Your AI tools launch directory. Ship smarter.
A startup directory and product launch platform for AI tools. Discover new launches, compare workflows, and submit your startup for free.
- Launches today
- 10
- Active directory
- 60
- Top categories
- 20
Daily launches
Curated drops land daily. Spot new AI products before the crowd.
Quality filters
Only practical, usable tools. No noise, no empty hype.
Community signals
Real upvotes drive trending. The strongest tools rise.
Launching today
Opposable is computer use for phones. It gives Claude Code, Codex, Cursor, any MCP client, or the agent built into the app the ability to use a real Android phone the way a person does: reading the screen, tapping, typing, swiping and opening apps in every app you are signed into. The Android app is out now as a 43 MB APK and needs Android 11 or later. It is built for people who already drive an agent such as Claude Code or Codex and want that agent to reach the parts of their life that only exist on a handset — messaging, banking, rides, delivery, shopping, calendars and the constant stream of two-factor codes. The product's purpose is stated plainly on its own site: give your AI thumbs. Most of your life runs through phone apps, and none of them have an API. Banking, rides, delivery, messaging, and the two-factor prompt sitting in the middle of every workflow all live behind app interfaces designed for human thumbs rather than for software. An agent can write code, search the web or summarise a document, but it cannot open a banking app, check an amount and stop before paying. Reval Labs describes Opposable as the layer that lets agents use those apps, on the phone you own and on phones the company runs for you. Computer use is coming to phones, and Opposable is building the hands. At the centre of Opposable is an agent that runs on the phone itself. Where most phone agents send your screen to a model in a data centre, Opposable's own agent runs on the device it operates, so it keeps working with the laptop closed or with no signal at all, and your screen never leaves the phone. It is small enough to download once over Wi-Fi, and it gets faster with every release. Three levels of intelligence are described on the site. With no model at all it handles about 40 everyday tasks — alarms, reminders, calendar, calls and texts, camera, settings, volume, maps and conversions — in 0 to 15 seconds, checking its own result on the screen. A 1.4 GB screen model looks at the screen and taps like you in any app, and picks from the screen's labels in under a second when it can. A 0.7 GB answer model replies to questions from web results. On recent Snapdragon phones the screen model's vision step runs on the phone's NPU; on a Galaxy S25 the company measured it at about a quarter of a second, roughly 16 times faster than on a laptop CPU. Opposable does not replace your agent; it gives it hands. Anything that speaks MCP can drive the phone. For Claude Code it is a single claude mcp add --transport http command, and Codex takes a few lines in its config file; Cursor works the same way through MCP. The app shows its address and a token, and the phone becomes a tool in your next session. There is also a Claude and ChatGPT connector: paste the URL https://getopposable.com/mcp into a custom connector in Claude's settings, or turn on Developer mode in ChatGPT and add it there with OAuth sign-in. Either way you land on Opposable's page, sign in, pick your phone and allow access. The connector is free for 14 days per phone and then part of Pro. Opposable is model-neutral: Claude, Codex, OpenAI-compatible endpoints and the company's own on-device agent all drive the same surface. Two capabilities make the phone usable as a tool. It sees: Opposable returns a screenshot plus the screen as a list of labelled elements with their positions — text views, switches and their coordinates — which is cheap enough to read on every step. It acts: taps, swipes, typing in any language, system keys, opening apps and links, and every call reports what it actually did. The action surface is small and explicit — tap_element, swipe, type_text, launch_app, press_key — so an agent can chain a handful of calls into a finished task. Tasks can also be handed over whole: a REST call to the phone's /api/do endpoint with a task string returns a status, a result and the number of seconds it took, so the phone does the work locally and only the result comes back. Connectivity is deliberately boring. The phone can be reached over USB, over the same Wi-Fi network, or from anywhere through Opposable's hosted relay; the phone keeps one outbound connection, so there is no port to forward. If you have no spare phone, you can rent a private virtual Android phone in the cloud, sign into your apps once through a browser viewer and connect your agent to its private HTTPS endpoint with one command. Cloud phones start at $19 a month. If you are on an iPhone, Opposable for Mac pairs with the iPhone as a Bluetooth keyboard and pointer and sees its screen over a cable or AirPlay, so the agent can tap and type in every app with no jailbreak and nothing installed on the phone; on Windows or Linux a small Opposable Stick does the Bluetooth part. The benefits are practical rather than abstract. Your agent stops at the edge of the phone and starts working inside it, in the apps you are already signed into, with the sessions, the accounts and the history you already have. Because the agent runs on the phone, tasks keep running when the laptop is closed or the signal drops, and the screen never leaves the device for a data centre. Common tasks are handled without any model at all, which makes them fast and free. Payments and purchases always stop and wait for your Approve tap on every plan: the agent does the twenty taps, you make the one that matters. And because a task Claude does once can be saved as a recipe, the phone can replay it on its own in seconds the next time. The site describes a set of concrete scenarios. Messages: Opposable reads a 2FA text the moment it lands and types the code where it is needed — its own example shows the code 482 913 being copied from Messages and used to sign in to a bank, before the same phone replies to a chat and books a ride. Bank: it opens your banking app, checks the amount and stops for your OK before paying. Chat: it replies in your chat apps in your voice, with the whole thread in mind. Rides: it books the ride, picks the pickup point and sends you the driver's ETA. Shop: it finds last week's grocery order and puts it back in the basket. Inbox: it archives, replies and moves invites into your calendar. Recorded runs on the site show an agent turning on dark mode and setting a five-minute timer in 50 seconds and 17 tool calls, and looking up Apollo 11's launch date and crew through Chrome in 118 seconds for $0.44. Opposable is free to use; you pay for what is annoying to host yourself. The Free tier includes the phone app, its MCP server and REST API, the model-free common tasks, unlimited tasks and recipe replays over USB or the same Wi-Fi, and iPhone support through Opposable for Mac in beta. Pro costs $8 a month ($79 a year, with founding members at $5 a month for life) and adds the hosted relay so Claude Code can reach your phone on mobile data or any Wi-Fi, scheduled tasks and webhooks while your laptop is closed, payment approvals from the phone's notification, an audit log, and recipes backed up and shared across up to three phones. Power is $29 a month for up to 10 phones. Cloud phones run from $19 a month for a sleeping starter phone, $49 for an always-on phone and $149 for three always-on phones. The audience is developers and power users already running Claude Code, Codex or another MCP agent who want those agents to reach phone-only apps, plus teams that need several phones for parallel agents or separate accounts. Opposable's pitch is short: give your AI thumbs. It takes the computer-use idea that has been applied to browsers and desktops and points it at the device that actually holds your accounts, using an on-device agent, an MCP server, a relay for remote reach and cloud phones when there is no handset to spare. The agent does the endless tapping; you keep the one tap that matters.
OpenCharm is an open-source body for the AI agent you already run. It gives that agent a face, a voice and one key, and it works with Claude Code, Codex, Hermes Agent, OpenClaw or any agent that speaks ACP, the Agent Client Protocol, as well as any server with an OpenAI-compatible API. One package: one agent at a time. Today it lives at the top of your Mac or Windows screen as the desktop charm — its eyes sit on either side of the notch on a Mac, or above a small black pill at the top centre on Windows — and next it is designed to run on a small ESP32-S3 board you build yourself. It exists for people who already trust an agent and want a glanceable, hands-free companion for it. The question the product asks is a simple one: why not just an app? The page acknowledges that a phone app could do most of this. The rest is the reason OpenCharm is a small thing that sits by your laptop or hangs from your keys. Your phone lies face-down and locked, so checking on an agent means picking it up and getting pulled into your inbox; the charm sits by your keyboard and a glance tells you whether your agent is busy, stuck or done. It does one job, then goes quiet. The page also positions OpenCharm against earlier AI gadgets: the Humane AI Pin and Rabbit R1 both promised to replace your phone, and both were slow, missed the basics and asked you to learn a new way of doing things. OpenCharm replaces nothing. Your agent keeps its memory, skills and model; the charm is the part it was missing — eyes, a voice, and a key you can find without looking. The charm's face is deliberately simple and readable. It is built from two characters for eyes and one for a mouth, which makes it readable from across the room, cheap to draw, and easy for anyone to write a new one and share it as text. There are 22 moods across 13 agent states, ranging from Neutral, Happy, Joy, Cute, Wink and Loved through Listening, Thinking, Focused, Curious, Confused, Surprised, Doubtful and Unamused to Strain, Sad, Oops, Dizzy, Sleepy, Learned, Money and Needs You. The face is never static: it breathes all the time and more slowly when asleep, blinks quickly, doubly or slowly, glances around and wanders up while it thinks, follows your finger on the screen and squashes when the key goes down, its eyes swell with your voice while you hold the key, it greets you after you unlock it and is pleased after it helps, and it falls asleep after about four minutes alone, with z's. A poke gets a different reaction each time, and three quick pokes make it dizzy. Beyond the idle animation, the charm turns your agent's events into faces so you can see what it is doing without asking. It shows Hello when you pick it up or sit down for the first touch of the day; Listening while you hold the key and talk; Thinking while the agent works on an answer; Working while a tool or a long task is running; Needs You for an approval request or a clarifying question, with an orange ring and one sound; Done when a turn completes or a cron job finishes, with one line before it returns to the face; Stuck when three tool errors pile up in a row; Failed when a run breaks, saying what in one line; Learned when a skill is created or updated; Noted on a memory write such as user.md or memory.md; Cost when spend passes a limit you set; Asleep when the charm is face-down or during quiet hours while the agent keeps running; and Idle when nothing is going on, with slow blinks and glances. Interaction is built around a single key with three moves, so there is nothing to learn: hold, press, tap. Holding the key is like a walkie-talkie — you talk to it, and the microphone is on only while you hold it. Pressing the key does everything else: wake it, stop it talking, dismiss, or say no. When the orange ring is showing because your agent has a question or wants an approval, holding means yes and pressing means no. Tapping its face is just for a reaction; you never need a swipe. On the desktop charm the key is Option + Space (Ctrl + Alt + Space on Windows) and works in any app; you can change it in Settings. Speech and decisions each get their own simple representation on screen. When the charm answers, the words type out under the eyes or in a panel below the notch — long answers scroll like captions and nothing runs off the screen. When your agent needs a decision, an orange ring appears around the screen or the panel and the key says what it will do. The design rules stated on the page are strict: one thing per screen, glyphs on true black, orange only when it needs you, and a target reaction time of under 100 ms. You can make the charm your own without touching code. Pick its colour — White, Cobalt, Lime, Lilac, Sun or Coal, or your own, which lights the glyphs but should not be orange or too dark — give it a name of up to 12 letters, digits and spaces, and choose one of the 22 faces. The same settings can be made in the desktop charm's Settings or in your workspace's opencharm.json, and the notch follows them, as will the board, along with its greeting, voice and how calm it moves. On the board you print the shell in one of the six colours or any colour you like. On a real charm, your agent's state picks the face, and your agent can try on a new look when you ask. Nothing you pick on the page is saved or sent. Underneath, OpenCharm is deliberately thin. The charm holds no API keys and runs no model; it is a small body for a brain you already have. charmd, a small daemon that runs on your machine next to your agent, carries the charm's voice to your agent and brings back speech, faces and questions. It handles pairing and the PIN, speech on your machine or with your own key, and the charm's own tools for your agent. It can run on your laptop, a Mac mini or a server, and the desktop charm brings its own. Your agent — Claude Code, Codex, Gemini CLI, goose, Hermes Agent or OpenClaw, one at a time — keeps its memory, skills and model, and the charm asks you before it acts. Anything risky turns the face orange and waits for your key. The desktop charm is the version you can use today, without hardware. It lives at the top of your screen and is the same OpenCharm OS the board will run; it uses about 2% of one core at rest and is a 4 MB app. By the notch on a Mac, its eyes sit on either side of the notch, breathing and blinking, and holding the talk key in any app opens a panel below. On Windows it is a small black pill at the top centre. In Settings you choose the agent's folder, the agent (Claude Code, Codex, Gemini CLI, goose, Hermes, OpenClaw, any ACP command or an OpenAI-compatible server) and the voice: local on a Mac, OpenAI with the key in your keychain, or none. It runs its own charmd and pairs by itself. It is available for macOS and Windows, downloaded from GitHub Releases, built by the repository's own CI from the same code with checksums and build provenance, or you can build it yourself. If you want the physical version, the build is short: one board, one evening. The hardware is a ready-made Waveshare ESP32-S3-Touch-AMOLED-2.16 board with a battery, which already has the screen, microphones, speaker amp, battery and a case: a 2.16-inch 480 x 480 AMOLED, ESP32-S3, two mics, in a 46 x 46 x 22.5 mm case for $31.99. You need a USB-C cable that carries data, and optionally a printed shell — about 14 cm3 of matte PLA in your colour with a little of a contrast colour for the key, for roughly $1 — and any thin phone-charm strap for about $2, bringing the total to $32-35. The charm already runs on your computer as the desktop charm; flashing the board comes with the device port, and Waveshare's factory firmware can always be restored. There are three levels of making it yours. On level one, no code is needed: who the charm is and what it knows are text files in its workspace, and you can ask your coding agent to change them — for example a skill file that makes it wrap up your day in three lines when you say "wrap up". On level two you give it tools by adding MCP servers to its workspace; it already has the charm's own tools: show_face, ask, notify, say and set_look. On level three you change the body by forking OpenCharm OS, one C++ core for the desktop charm and the board, developed and tested in an emulator on your computer. A C++ ESP-IDF snippet on the page shows how an Ask server kind triggers the decision view. Whatever your agent can do, the charm does — it adds a face, a voice and one key, while the skills and tools are your agent's. Described examples include talking to your agent by holding the key and hearing one clear answer; approving what your agent wants to do, holding for yes and pressing for no; walking away from a long task and knowing from the face when it is done; telling your agent something once so it remembers it; five-minute quizzes that adapt to you and get a reaction on every answer; a morning brief with the one thing that matters today; hands-free cooking with one step at a time and timers, readable with flour on your hands; controlling lights, heating and the door through Home Assistant MCP; travel days with gate changes, walking time and the right platform; and winding down when it gets sleepy. On safety and privacy, the product is explicit. The microphone opens only while you hold the key and closes when you let go; there is no wake word, and the rule lives in OpenCharm OS itself so your agent cannot open the microphone on its own. A PIN locks the charm on every power-on and five wrong tries block it; you can lock or revoke it from your machine. The charm keeps no API keys and never stores its PIN — charmd keeps only hashes. Everything runs with you: your agent runs on your own machine or server with its own memory and model, and what you say is understood on your computer. By default replies are spoken with Microsoft's free voices, which means the text of each spoken reply goes to Microsoft; you can keep everything local with the local voice instead, or use OpenAI with your own key. The software, the desktop charm included, is free and open source; the board is about $32 before shipping, there is no subscription, and the project sells nothing. OpenCharm is therefore not a new assistant and not a phone. It is an open-source body for the agent you already run: a face made of typed glyphs, a voice, and one key, on your Mac or Windows screen today and on a board you build next. It replaces nothing — your agent keeps its memory, skills and model — and if the company were to disappear, nothing would happen, because your agent and charmd run on your machine and the code is yours.
Busabase is an open-source (MIT) database and workspace for AI agents, described in its own words as the general system of record for AI agents. It gives people and AI agents one shared base where business records, docs, skills, and apps live in the same place, so the next task can build on whatever the previous one produced. Instead of letting agent output sit in a chat window, Busabase keeps it as data, docs, skills, and apps that a team can reuse. It is aimed at teams that already work with agents such as Claude Code, Codex, Cursor, Hermes, OpenClaw, WorkBuddy, and Buda AI, and it can be run on your own machine, self-hosted inside your network, or used through Busabase Cloud. The problem Busabase addresses is that agent work keeps evaporating. A team already uses AI and the work does get done, but it scatters across personal chat windows: one person drafts a quote in ChatGPT, another cleans up a customer list in Claude, a third finishes a data cleanup script in Cursor, and someone else records a pricing decision in Gemini. The site states the consequences plainly: results stay in a chat log nobody finds again, every session starts from zero, and when someone leaves the company, their work goes too. Busabase takes the opposite position: the work lands in one workspace and stays after people leave, so the next agent reads what the last one wrote and the work stays with the company. Busabase organizes that shared work into bases. The Data Base holds customers, projects, and inventory in tables with fixed columns, and because the columns are typed, every agent reads and writes the same fields rather than inventing its own shape for the data. The Knowledge Base is described as the team's shared memory: answers you can find, with a source, that someone checked. A record there carries its body, its sources, and its review history, so a fact can be traced back to where it came from and to whoever verified it. Together these two bases give agents a stable place to read from and write to, and give people a place to check the result. Three more bases extend the same idea. The Apps Base holds internal tools, called AirApps, built on the same data, so every screen shows the latest version — the site shows Busa CRM, a pipeline with deals and follow-ups that reads the same records. The Skills Base lets you save a workflow once as a skill, and any agent can run it next time. Playbooks are where a team writes down how it does things: agents check the playbook before every task and follow it instead of improvising. The site's summary of the workspace is Data, Knowledge, Apps, Skills, Playbooks, and External Agents, all in one place for people and agents. Agents connect to Busabase from wherever they already run. You can talk to a connected agent right inside Busabase, or connect 40+ external agents over Agent Skills, MCP, and more — Claude Code, Codex, and OpenClaw are named. Either way, those agents read and write the same workspace. The connection options listed are Agent Skills, MCP, OpenAPI, and the CLI, and the FAQ broadens this to any agent that can call a REST API, naming Claude Code, Codex, Gemini CLI, n8n, Zapier, LangChain, or your own agent; for that route the instruction is to paste the SKILL.md and go. Because the same structured data sits underneath, an agent does not have to be told the shape of the business each time it starts. The workflow Busabase describes has three steps. First, connect your agents: nothing to switch, your agents keep working the way they do today and simply write here. Second, every write is on the record: each change carries who made it, what changed, and a full history, and for the writes that matter you can hold the change for a person to review. Third, reuse it next time: the next agent, a teammate, or an AirApp reads the same data, so nobody starts from zero. Underneath, Busabase is open source under the MIT license, and the same engine runs on your laptop, on your own server, or in Busabase Cloud. Busabase Desktop keeps data in a folder on your computer with no usage tracking and keeps working offline; the Docker image is deployed inside your company network so data never has to leave it; Cloud needs nothing installed. The benefits the site claims follow from that structure. Work that would otherwise sit in personal chat windows lands in tables, docs, and apps you can open tomorrow, and it stays with the company after people leave. Knowledge comes with a source that someone checked, rather than as an unsourced answer. Every change keeps its history, so the record remains explainable later — approve, request changes, and reject decisions all stay attached, and rejected work never enters the canonical data. And because the same data feeds agents, people, and internal apps, a new session does not begin from nothing. For teams with a security review coming up, Busabase points to its self-hosting documentation about keeping data inside your network. The website lists eight kinds of work you can start keeping today. Customer support stores Q&A and product facts so agents draft the reply and a person approves it. Marketing keeps CRM contacts, campaign records, social posts, and creative assets in one place. Content moves briefs, drafts, and published pieces through a single pipeline. Team memory captures decisions, meeting notes, and context the next agent can read. Operations tracks projects, to-dos, and supplier details. Research collects market signals and monitored sources, verified and adding up over time. Product catalog holds SKUs, specs, pricing, and relations, searchable and managed in one place. Compliance covers access reviews, vendor checks, and a complete audit log. A demo on the site shows a content board where scheduled posts carry visual, platform, copy, scheduled status, and read-from relations, with the price pulled from the Products base. Busabase is built for teams and individuals who want agent output to accumulate somewhere shared. Named agent integrations are Claude Code, Codex, Cursor, Hermes, OpenClaw, WorkBuddy, and Buda AI, with n8n, Zapier, LangChain, and Gemini CLI mentioned in the FAQ, and connection surfaces including Agent Skills, MCP, OpenAPI, webhooks, a CLI, and REST APIs. Pricing has three tiers. Free costs $0 for one person keeping what their agents produce, with 1 space you own, 3 seats per space, 5,000 records per space, 1 GB of attachment storage, and 1 self-hosted connection online. Plus is $10 per seat per month, billed $120 per seat annually, with 3 spaces you own, 10 seats per space, 20 GB of attachment storage, and OpenAPI, webhooks, and MCP. Pro is $20 per seat per month, billed $240 per seat annually, with unlimited spaces you own, unlimited seats, 100 GB of attachment storage, and priority support over WhatsApp, WeChat, or email. The open source engine is free forever, and Cloud starts free and grows per seat. Taken together, Busabase's value proposition is simple: give your agents a workspace worth building in. The work they produce becomes typed data, sourced docs, saved skills, and internal apps that the next agent, the next teammate, or an AirApp can read; every change keeps its source and its full history; and sensitive work can stay on your machine, on your own server, or in Busabase Cloud. You can start local for free and add Cloud when your team is ready.
Refs is described as the video reference library for agents: a collection of 3,032 films that moved people, each measured cut by cut and turned into blueprints and prompt recipes an AI agent can build from. The site frames the product with a simple premise — Claude is only as good as the references you give it — and positions Refs as the way to hand Claude better refs. It is aimed at people who plan and produce launch films, motion pieces and explainers and who want their agent to work from real, published work rather than a loose collection of inspiration. The archive is free to browse, while the Pro plan opens up every plate of every blueprint, a runnable recipe for every film, formulas that compare films of one format, and the Refs MCP connection. The problem it addresses is reference quality. An agent can only plan what it has been shown, and the site notes that Refs is deliberately not a mood board: it publishes measured cuts, timed beats and a recipe for each film, so that Claude copies the method rather than the footage. The archive is built from films studied at Apple, Google, OpenAI, Anthropic, Framer, Notion, Cursor, ElevenLabs, Raycast, Arc, Vercel, Linear and Perplexity, among others, gathered into a single searchable place. By the numbers shown on the site, the library contains 3,032 films, 67,695 shots measured and 28 formulas. Refs does not host the videos: every film plays from its original post and stays its maker's, while Refs publishes its own measurements and analysis and credits and links every source. Every cut is measured. The site explains that shot boundaries are found frame by frame, and that clicking a shot jumps straight to it. Each film carries a cut map with figures such as cuts per minute and average shot length — the example shown on the homepage is 36 cuts per minute with an average shot of 1.5 seconds — so the pacing of a film becomes a number a planner or an agent can reason about rather than something you have to eyeball. Playback is built for scanning: walk the archive, scroll to move through it, hover a film to play it, move to scrub and click to open, with tap-to-play on a phone. Search runs across the whole archive, so a query pulls matching films out of the 3,032 on record. Each film is taken apart into a 15-plate blueprint covering hook, beats, shots, type, colour, sound and script. The plates are designed to be flipped through: Format states what the film is in one breath; Card gives length, pace, shots and sound at a glance; Hook breaks down the first two seconds frame by frame; and Make it yours carries the instruction to swap the story and keep the method. The public FAQ describes the blueprint as containing hook, beats, shots, type, colour, sound and script, plus a prompt recipe you can hand to Claude. Free users see the first plates of every blueprint; Pro opens all 15 plates of every blueprint. A runnable recipe sits at the end of each blueprint. The recipe is written to be pasted into Claude Code and made your own — the example on the site is a prompt recipe asking Remotion to create an original 15-second, 60 fps motion-design showreel for a product, with timed beats spelled out second by second, from a point growing into the mark inside faint circular guides to a full-screen shape wipe and a warm-ivory process chart. Alongside the per-film material, Refs publishes formulas: shared patterns across the strong films of one format, 28 of them in total, with counts of how many films sit behind each. Named examples include The Music-Led Motion Showreel, The Dark Staged Product Reveal, The Live-Drawn Paradox, The Fifteen-Second Service Rescue, The Sonified Chart Relay, The Capability Proof Montage and The Price of Regret. The core mechanism is the Refs MCP. One command adds Refs to Claude Code, Codex or Cursor — the site shows a claude mcp add command pointing at the Refs MCP endpoint with an authorization header carrying a Refs key — after which Claude can search the archive, pull blueprints and formulas, and plan your film from real references. The demo on the site shows the agent calling a Refs search tool with a query and returning matching entries, such as the Lumi founder launch and product walkthrough, the Warp 2.0 founder-led launch film and the Bolt v2 founder-led product launch. The result, as the site puts it, is the same Claude with better references: ask for a film and Claude studies films that already worked, then plans and builds yours. The Refs MCP is listed as part of the Pro plan with 1,500 credits a month. Because the references are measured rather than merely admired, the output an agent produces can follow an evidenced method: the hook, the beat timings, the shot lengths, the sound and the pacing of films that demonstrably moved people. Users get a way to brief an agent with cut maps, numbers and recipes instead of adjectives, and they keep the connection to the original work, since Refs links and credits every source and films play from their original posts. The library is also browsable on its own, so the same archive works as a study tool for a person and as a retrieval source for an agent. Use cases described on the site revolve around planning and producing video. A person planning a launch film can ask Claude for a film and have it study the films that already worked before it plans and builds theirs. Someone building a motion design piece can pull a recipe such as the Remotion prompt for an original 15-second, 60 fps showreel and adapt it to their product. Searches in the demo return matches under labels like founder launch, kinetic type, silent demo, three.js and terminal, with results such as a founder-led product launch or a product walkthrough, which suggests how a specific style or format can be retrieved and studied. Others can work from the formulas to understand what the strong films of one format share, or from the cut maps to match a pacing pattern. The archive itself can be walked as a study resource, with films such as A Miniature Garden Becomes Life-Size sitting alongside dozens of others drawn from YouTube and X posts. Refs is built for people who make and commission product and brand films — launch films, motion pieces and explainers — and for the developers and designers who drive AI coding agents such as Claude Code, Codex and Cursor. Browsing is free: every film playable from its source, cut maps, hover-scrub and the numbers, the first plates of every blueprint, and search across the whole archive. Pro costs $10 a month billed yearly or $16 monthly, and includes all 15 plates of every blueprint, a runnable recipe for every film, formulas across films of one format, and the Refs MCP for Claude Code, Codex and Cursor with 1,500 credits a month. A launch offer on the site notes that the code PRODUCTHUNT takes 50% off a year of Pro. Taken together, Refs is a reference library that treats video as data an agent can use: 3,032 films measured shot by shot, 67,695 shots and 28 formulas, packaged into 15-plate blueprints and recipes and delivered to Claude Code, Codex or Cursor through the Refs MCP. Its promise is narrow and specific — give Claude better references, so the film it plans copies the method of work that already moved people, never the footage.
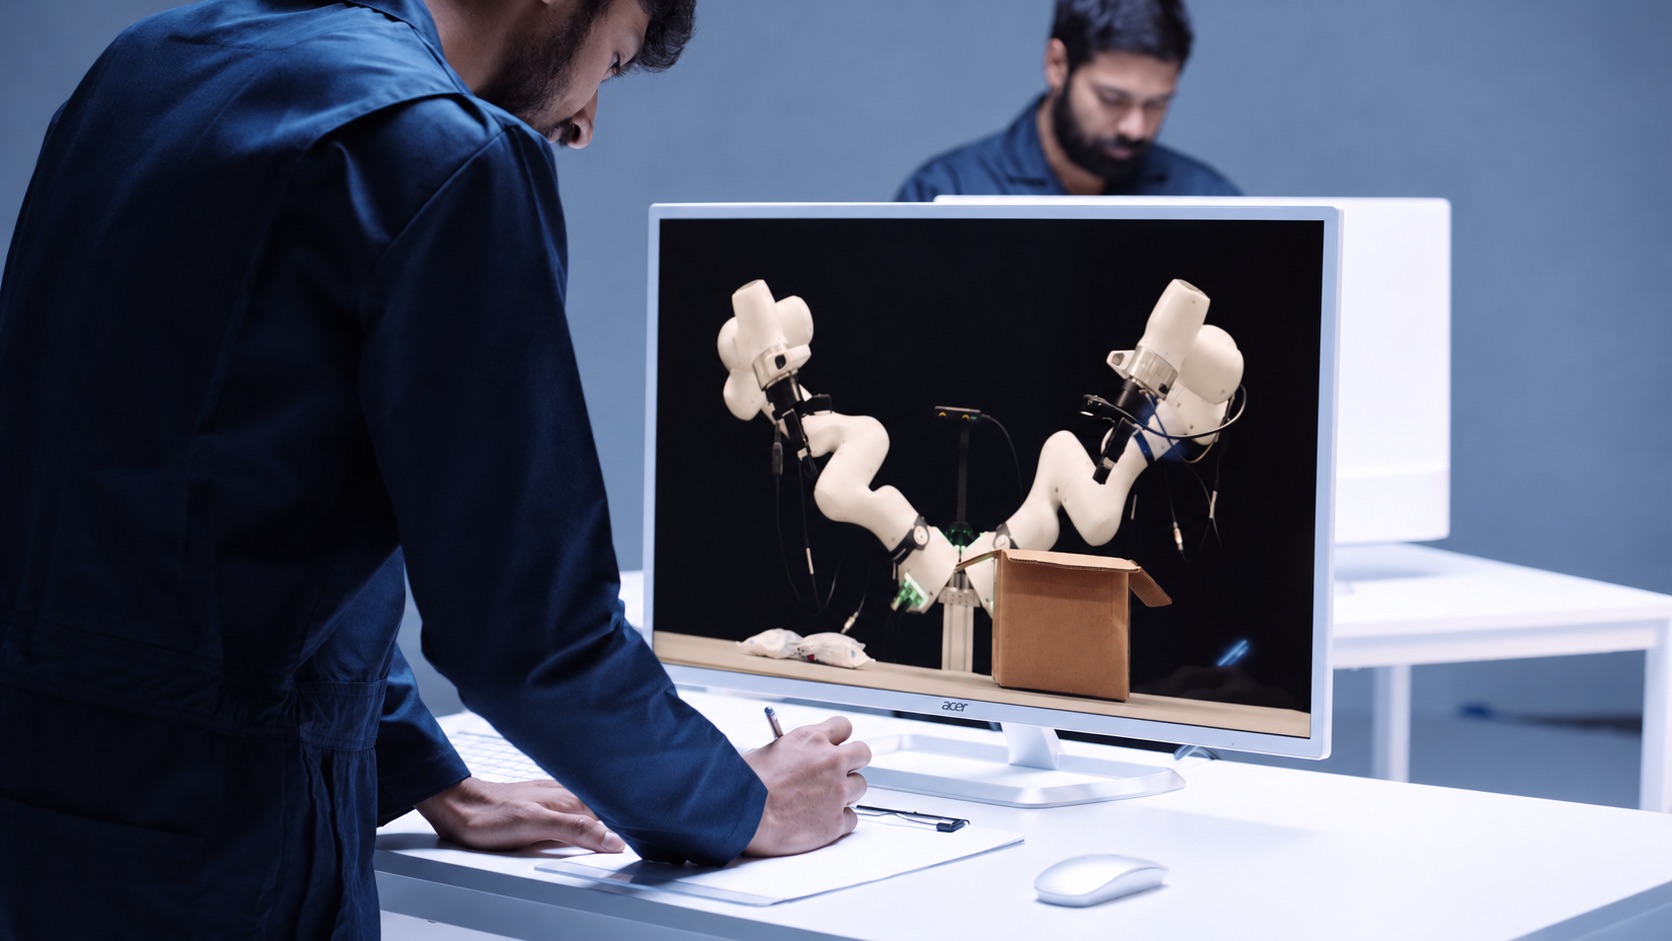
Odyssey-3 is Odyssey's most powerful foundation world model yet, described as a learned dynamical system implemented as an autoregressive diffusion transformer that predicts how objects move and interact through space and how situations evolve over time. It generates embodied environments from a prompt and predicts in real time how those environments change as a person or an agent takes actions or introduces events, using previous observations together with the latest inputs. The model is built for physical AI developers — teams building robots, humanoids, self-driving cars, drones, and other autonomous systems — who want to explore how foundation world models can accelerate their work. A research preview is available now, letting users prompt an environment, act within it, and observe how the world model responds, while developers interested in building with Odyssey-3 can get in touch for API access. The starting point for Odyssey-3 is a problem the founding team lived with for a decade. They spent that decade building driverless cars, where predicting the world was essential to determining what a car should do next. They founded Odyssey to pursue that idea far beyond the roads — to build a general-purpose technology that could bring learned world knowledge to all machines and tasks. With Odyssey-3, they believe this idea is now being realized. Physical accuracy is central to that goal, because a foundation model for physical intelligence must learn to predict how the world actually behaves rather than simply producing plausible-looking video. Odyssey-3 learns representations of physics, dynamics, and cause-and-effect from a broad dataset of visual observations, and developers use that knowledge both to simulate environments and to train policies for different physical systems. The first capability is real-time environment generation. Odyssey-3 generates embodied environments from a prompt and predicts in real time how they change as a person or an agent takes actions or introduces events, using previous observations and the latest inputs. You can move through the environment or introduce an event during generation and observe how the model responds. Today's preview provides first-person and third-person navigation alongside independent camera movement, giving you different ways to interact with and inspect the model's predictions. Physical accuracy is measured against public benchmarks. Odyssey-3 Pro sets a new state of the art on Physics-IQ Verified's video-to-video benchmark, achieving 66.1, the highest reported score. Physics-IQ tests physical behavior across fluid dynamics, optics, solid mechanics, magnetism, and thermodynamics, asking models to continue videos of real physical experiments and comparing their predictions with what actually happened. Odyssey-3 Pro also scores 54.7 in image-to-video, while Odyssey-3 improves the measured tradeoff between physical accuracy and generation cost, making it possible to generate more simulations within the same compute budget. On WorldMark, which measures control-following, visual quality, and world memory, Odyssey-3 ranks first in first-person stylized, third-person real, and third-person stylized environments, using the benchmark's own captions and the mean of its 13 reported metric scores. Odyssey-3 adapts to physical systems. Its learned world knowledge can be applied to different systems by training an action decoder or policy on paired observations and actions. These learned components translate that knowledge into the controls required by a particular machine, letting developers adapt the foundation to a new body or task. With only tens of hours of robot demonstrations, Odyssey-3 completed manipulation tasks and showed recovery behaviors absent from those demonstrations, including reorienting a gripper after a missed grasp and retrieving a dropped object in an unusual position. Flexion has built humanoid control policies on Odyssey-3 whose performance exceeded the tested VLA baselines under environmental changes and continued to perform tasks under lighting changes that caused those baselines to fail. Odyssey-3 was also adapted to drive a car on real roads in India, training a driving policy on just 20 hours of driving data while keeping the Odyssey-3 backbone frozen; the policy uses the model's visual representations to predict waypoints ahead of the car, allowing it to drive in closed loop. The model can additionally be adapted to generate observations for particular sensor arrangements — in an early experiment using the front three cameras of an autonomous-driving dataset, an Odyssey-3 training checkpoint produced driving sequences with three camera views generated together after just 100 training steps. Odyssey-3 can also help train agents. An agent is an AI system that pursues a goal by observing its surroundings, choosing actions, and using what happens to decide what to do next. A world model can provide the environment in which those decisions are made, giving a way to study how an agent responds to changing conditions and whether it can complete a task inside a world whose behavior is learned. In the task-completion demonstration, an agent receives a natural-language goal and pursues it inside Odyssey-3, observing the generated world as it works toward the task. How Odyssey-3 was built is described in the launch material. Its training data combines internet video with time-localized, schema-verified event annotations, gameplay recordings with time-aligned keyboard and mouse inputs, and simulated rigid-body interactions with captions and metadata. Together, these sources connect diverse observations with descriptions of what happens and, where available, the actions that produced it. The stated design goal was to enable dynamic, open-ended interactions with an environment that responds as the user acts. Odyssey-3 is built as a multi-step video diffusion transformer, using temporally resolved prompts and controls to guide how the world unfolds. It is then extended autoregressively through teacher forcing and causal masking, training it to continue from preceding observations and predict future states conditioned on action inputs. Finally, a post-training pipeline that combines distribution-matching and adversarial distillation produces a distilled variant of Odyssey-3 — a few-step model capable of real-time interaction. The measured results point to concrete benefits for users. Because physical accuracy and generation cost are traded off more efficiently, developers can generate more simulations within the same compute budget. Because the model can be adapted with small amounts of data — tens of hours of robot demonstrations, or 20 hours of driving data with a frozen backbone — developers can bring learned world knowledge to a new machine or task without training a world model from scratch. Because the distilled variant is a few-step model capable of real-time interaction, environments respond as the user acts rather than only after generation is complete. And because the model can provide the environment in which agents pursue natural-language goals, it offers a way to study agent behavior in worlds whose behavior is learned. Odyssey-3 appears in several concrete scenarios in the launch material. For robot arms, prompts such as "Pour the cereal into the bowl" and "Close the screwbox" were used with the model to perform manipulation. For humanoids, Flexion built control policies on Odyssey-3 and ran tasks such as "Open the blue container and take out the cardboard box" and "Move the plate to the center of the table and place the mug on top of it." For vehicles, prompts like "Take the first roundabout exit" and "Drive along the road" were used while the adapted policy drove autonomously on real roads in India. For multi-sensor data, Odyssey-3 generated driving sequences with three camera views produced together for an autonomous-driving dataset. For agents, an agent receives a natural-language goal and pursues it inside the generated world. And in the research preview, a user prompts an environment, navigates it in first or third person, and introduces events to see how the model responds. Odyssey-3 is aimed at physical AI developers — teams developing a robot, humanoid, self-driving car, drone, or any other autonomous system — as well as researchers studying world models and anyone who wants to try the research preview. Developers who want to build with Odyssey-3 are invited to get in touch for API access. The research preview, offered as "Try Odyssey-3 Flash," is available now through experience.odyssey.systems. Published evaluation details describe two model sizes: Odyssey-3 at 832×480 and Odyssey-3 Pro at 1280×720. The launch material presents Odyssey-3 as available today as a research preview, with API access offered on request; no pricing or plan details are published in the provided content. Taken together, Odyssey-3's primary value proposition is that it brings learned world knowledge to physical AI: a foundation world model that generates interactive environments from a prompt, predicts in real time how they evolve as someone acts, advances the reported state of the art in physical accuracy on Physics-IQ Verified, and can be adapted to control robot arms, humanoids, and vehicles or to serve as the environment in which agents learn and are evaluated.
OpenVids is an open-source, agent-first video editor for macOS and Windows. Its premise is simple: you direct, and agents edit. Instead of building an edit by hand, you describe the film you want, and AI agents build the chapters, cut the timeline, add motion and sound, and review the render. OpenVids is built for people who want to start from a description of the story rather than from an empty timeline, while keeping the result editable. Every change an agent makes lands on a timeline you can take over yourself at any point. The problem OpenVids was built around is that the timeline grows faster than the story. Every project starts with a story, but as footage accumulates the edit becomes a list of clips to manage rather than a story to tell. The creators of OpenVids describe losing the thread somewhere around clip two hundred. They wanted the story to stay visible the whole way through, so that the narrative — not the clip count — remains the organising principle of the project. That framing shapes the whole product: the editor is designed around chapters and a story structure rather than an undifferentiated sequence of clips. At the centre of OpenVids are its agents. You describe the film, and the agents work on your behalf: building the chapters, cutting the timeline, adding motion and sound, and reviewing the render. This is why OpenVids describes itself as an agent-first editor rather than an AI-assisted one — the agents are the primary way edits get made, and you direct them in plain language. The Product Hunt listing summarises the same idea as an open-source video editor you run by chatting with AI agents. The workflow is a conversation about the film rather than a series of manual trimming operations. OpenVids organises a project through named workspaces — Agents, Media, Story Graph, Edit, Motion, Sound, Render and Licenses — which the site presents as one continuous workflow rather than separate tools. The Story Graph is where the story structure lives: on the site's own demo project the chapters are listed as Cold open, The problem, Meet OpenVids, Feature tour, In the field and Outro, each with a timecode. The Media workspace tracks the assets in the project — the example shown lists 23 assets with 1 missing — so you can see what the edit depends on and what still needs to be supplied. The Edit, Motion and Sound workspaces cover the craft layers of the edit. The example project shows media assets such as an A-roll clip, B-roll footage and a motion asset, indicating that the editor works with different kinds of material — camera footage, supporting shots and motion pieces — inside the same project. Motion assets carry their own durations, and sound is handled as its own workspace, so an agent can add motion and sound to the cut as it builds. The Render workspace is where the finished edit is produced, and the agents also review the render, closing the loop between the description you gave and the video that comes out. The unique approach is the combination of agent-driven editing with a fully inspectable timeline. Agents do the work — cutting, adding motion and sound, and reviewing the render — but nothing is hidden: every change lands on a timeline you can take over. That means you can start with a description, let the agents assemble a first cut around a story structure of chapters, and then step in and edit directly when you want to. OpenVids is also free and open source, with the code available on GitHub and downloadable builds published as releases, so the editing engine is something you can inspect and run yourself. The payoff for users is that the story stays visible from the first line of your description to the final render. Rather than losing the thread in a growing pile of clips, you keep a chaptered structure that reflects what you are trying to say. Because agents handle the repetitive work of cutting the timeline and adding motion and sound, the first version of an edit arrives without a long manual pass. And because the result is a real timeline rather than a black box, you keep control: you can take over at any point instead of accepting whatever the agents produced. Concrete scenarios follow the demo project on the site. A creator describes a short film and the agents turn it into a chaptered edit with a cold open, a problem section, a product introduction, a feature tour, an in-the-field section and an outro. Editors working with mixed material can bring in A-roll and B-roll footage alongside motion assets such as a title reveal, and let the agents place motion and sound around them. Projects that depend on many assets benefit from the Media workspace view, which surfaces the full asset list and flags anything missing before render. Finally, anyone who wants to check the result can review the render with the agents, then open the timeline and make their own changes. OpenVids runs on macOS and Windows. The site offers a download for macOS on Apple Silicon and a download for Windows, both at version 0.5.4, and points to the source on GitHub. It is free and open source, and the site's own demo work references open movies from the Blender Foundation under CC BY, along with a Licenses workspace — so projects can track the provenance of the material they use. The Product Hunt entry categorises it under Design Tools, GitHub, YouTube and Video. It suits directors, editors and creators who work on macOS or Windows and want to direct an edit with agents while retaining a timeline they can take over. OpenVids' value proposition is straightforward: you direct, agents edit. By describing the film you want and letting agents build chapters, cut the timeline, add motion and sound, and review the render — all onto a timeline you can take over — OpenVids keeps the story, not the clip count, at the centre of the edit. It is free, open source, and available for macOS and Windows.
Pine Computer is a cloud computer built for AI to use. Rather than pointing an AI agent at an ordinary desktop, you hand Pine Computer a job — research, forms, spreadsheets, or portals that have no API — and the finished work comes back to your product. It exists so that software products can complete real work on the web rather than merely describe it. A single SDK lets you spin up a computer per customer, you can bring your own model or use Pine's, and a person can take over whenever a sign-in or approval is required. Pine Computer is invite-only while in beta. The starting point is that today's agents are usually run on computers built for humans. A human looking at a screen sees pixels; a human has to keep checking that screen for change; and a human works on one or two screens at a time. An AI agent driving that same machine inherits every one of those constraints, which makes long, real-world tasks across many apps slow and expensive. Pine Computer also targets a specific and widespread gap: the many portals, seller sites, city systems and insurer forms that have no API at all, so the only way to get work done on them is to actually use them. On the same long, real-world tasks across apps, Pine reports that its preliminary tests ran 2–5× faster than AI agents on ordinary computers, at 1/25 the model API cost. Two of Pine Computer's core ideas are reading structure and sensing change. Because humans see pixels but AI can read what each thing on a screen is and what it can do, Pine's AI works from the structure of an app rather than from images. In the examples shown on the site, that structure looks like a heading called Invoices, a field labelled Email that is empty, a field for PO number, a Submit button that can be clicked, a table with 12 rows and 3 columns, or a link that downloads a PDF. Working from that structure means the agent does not have to guess at coordinates or recognise pictures of buttons — it knows what a control is and what it can do with it. The second idea is sense: humans keep checking the screen, while Pine's AI is told what changed the moment it does. Notifications such as a completed download, or a window gaining focus, arrive as events rather than requiring the agent to poll and re-inspect the page. The third idea is seeing: humans work on one or two screens, but Pine's AI gets many screens, rendered in memory and only when it needs to look. That is what allows an agent to fill a basket at three shops at the same moment, or to renew permits on three different city portals at once, without needing physical displays to exist the whole time. The fourth idea is access: the computer is sealed off on its own and reached through your code, and your keys stay with you. Together these four ideas — read, sense, see, access — describe how Pine Computer differs from running an agent on a machine designed for a person. Pine Computer is designed to be embedded in your product. You spin up a computer per customer through one SDK, so each customer's work runs on its own machine rather than sharing a queue. You can bring your own model or use Pine's, which lets teams keep the model relationships, credentials and evaluation setups they already have. And a person can take over for sign-ins or approvals: where a portal asks for a login that only the account owner can provide, the human signs in on the live screen and hands the computer back to the AI. The site shows this in several examples — a property owner signing into a city portal for a permit, an analyst signing into a subscription research source, a shop owner signing into a marketplace, and a shopper approving a purchase before anything is spent. The developer experience starts with code. The Ruby example on the site creates a computer with a location and an ephemeral flag, opens a browser session on it, and then runs a job written in plain language: pull last month's invoices from the supplier portals into the ledger. From the outside, Pine Computer behaves like a machine your product can hand a job to: the product submits the task, the AI drives the apps it needs, and the finished work comes back. Because each computer is sealed off and reached through your code, the integration boundary stays inside your own system rather than in a shared browsing environment, and because each customer gets their own computer, work can run in parallel instead of one task waiting behind another. The stated benefits are speed and cost. In Pine's preliminary tests, on the same long, real-world tasks across apps, Pine Computer ran 2–5× faster than an ordinary computer driven by AI agents, and used 1/25 of the model API cost — model API cost only, with results varying by task. Beyond the headline numbers, the four design ideas produce practical outcomes: reading structure instead of pixels reduces the guessing that makes agents brittle; being told what changed removes the constant re-checking that burns time and tokens; virtual screens let one job fan out across several apps at once; and the sealed, code-reached design keeps access limited to you and your code. The site lists 26 use cases, grouped into sites with no API, research, documents, assistants, sales and marketing, and engineering. Six are shown in detail. Renew permits: a customer clicks Renew once, and every permit due this quarter is renewed on its own city's portal, with each city's receipt returning to its permit's row as a PDF. Research a market: an analyst names a market and gets a report in which every figure carries the number of its source, including both figures where two sources size the market differently. Fill PDF forms: each client's row on a broker's sheet becomes a filled copy of the insurer's current PDF form, read back field by field, and nothing goes to the insurer until the broker has read each copy. Compare and buy: an assistant checks three shops at once, fills a basket in each, stops before payment, returns a comparison with delivery included in every total, and only places the order once the person approves. Update marketplace listings: a spring range is updated on Larkspur Market, Harbour Lane and Ferrow in turn, with each change recorded once the live listing reads back right. Test a web app: users write test steps in plain English, and each run follows them in a real browser on a fresh computer and screenshots every step. Pine Computer is built for teams that are putting AI to work inside their own products — the examples describe property software, research software, broker software, an assistant, commerce software and a testing platform handing jobs to Pine. Access is currently invite-only while in beta; interested teams leave an email address, join the last step of an application, and request access. The site documents an SDK with a Ruby example, plus developer docs, and a create-computer call that takes a location such as country US and an ephemeral flag. There is no published pricing on the page, and no list of third-party integrations beyond the choice to bring your own model or use Pine's. The takeaway is that Pine Computer turns the hard, human-shaped parts of web work into something your product can delegate. Read structure, sense change, see many virtual screens, and stay sealed off behind your own code — you hand it a job, and the finished work comes back, 2–5× faster and at 1/25 the model cost in Pine's preliminary tests.

Phonable is a smarter voicemail app for iPhone that replaces your carrier's voicemail. When you cannot pick up a call, Phonable handles both sides of that missed call: your caller hears your greeting and then gets a short text back explaining why you could not answer, while you receive the voicemail as a recording, a full transcript and a one-line AI summary. It is designed for iPhone users who miss calls because they are in a meeting, on the road, at the gym or away for the weekend, and who want callers to know what happened without changing anything about their phone number. Phonable keeps your own number, your SIM and your phone, and only steps in for the calls you do not answer. Carrier voicemail has not changed in decades. You get a beep, a message you never quite get round to listening to, and a caller left wondering whether you received their call at all. As Phonable puts it, a missed call leaves both sides hanging. The caller does not know why you did not pick up or when you will get back to them, and you have to dial in, press 1 and sit through messages to find out what mattered. Phonable treats the missed call as a two-sided problem and fixes both ends of it: the person calling gets an immediate, polite explanation by text, and you get the substance of any voicemail delivered in seconds rather than minutes. The first half of the fix is the automatic text back. The moment you miss a call, Phonable sends a short text on your behalf, even if the caller hangs up without leaving a voicemail. That closes the loop for people who would otherwise never know their call landed. Phonable ships with templates for every moment — starting points such as "In a meeting", "Driving" or "Back on Monday" — and you can write your own wording if you prefer. Messages are considerate by default: each caller receives at most one text per hour, so someone who tries twice is not flooded with replies. Because each mode carries its own text, what callers read always matches where you are — driving, at the gym or away for the weekend. Texts use the SMS credits in your plan and are not sent to landlines or unsupported countries. The second half is visual voicemail with transcription and AI summarisation. Instead of dialling in and pressing 1, every voicemail appears in the app with the recording, a full transcript and a one-line AI summary, so you know what a message is about in seconds. The AI summary arrives as a notification, before you have even opened the app. From there you can read it or play it: skim the transcript quickly, or listen to the recording at whatever speed you like. If the message needs a response, you can reply in one tap, either calling back or sending a message straight from the voicemail screen. A voicemail stops being a chore you postpone and becomes something you can absorb at a glance. Greetings are the third piece. If you are not a fan of recording yourself, you can type what you would like to say, pick a voice and a tone, and Phonable speaks it naturally. The available voices are Sarah (soft and reassuring, American), George (warm and trustworthy, British), Laura (bright and upbeat, American), Lily (clear and polished, British), Brian (deep and composed, American) and Charlie (casual and friendly, Australian), and each can be delivered in a professional, friendly, calm or energetic tone. If you would rather sound like yourself, you can record your own greeting in seconds. Either way, callers hear something that fits the moment rather than a default carrier message. Modes, introduced in version 2.0, tie the greeting and the text reply together into a single switchable state. A mode pairs what callers hear with the text they get back, so you can move from Workday to Driving in one tap. Modes can be kept on for a while — an hour, three hours or until tomorrow morning — or set on a schedule by choosing the days and hours, after which Phonable switches automatically. The built-in examples show how specific they get. In Workday's "In a meeting" mode callers are told: "Sorry I missed your call. I'm in a meeting and will call you back within the hour." Driving's "On the road" mode says: "I'm driving right now and can't pick up. I'll get back to you as soon as I've parked." Gym's "Mid-workout" mode says: "Mid-workout, can't pick up! I'll call you back within the hour." And Weekend's "Away for the weekend" mode says: "Thanks for calling! I'm away until Monday. For anything urgent, send me an email." Phonable works through conditional call forwarding, a standard feature of mobile networks. After you sign up, the app shows you exactly what to dial and walks you through three quick steps to turn forwarding on with your carrier — a process that takes about a minute — and you can switch it back at any time, at which point missed calls return to your carrier's voicemail. Forwarding is conditional, so Phonable only takes over in the situations where you cannot answer: when a call rings out while you are busy, when you are already on a call or tap decline, or when you are unreachable because of flight mode, a flat battery or no signal. If you do pick up, nothing changes at all; the call connects as it always has and Phonable is not involved. Beyond the core loop, Phonable adds a set of thoughtful details. Every call and voicemail sits in one timeline organised by name, and if someone hung up without leaving a message you can still see that they received your text. Callers show up with the name from your contacts rather than a bare number. Privacy is handled deliberately: your contacts stay on your iPhone and are never uploaded, and the company states that it never sells your data. Pro subscribers can upgrade to a dedicated Phonable line that only handles their calls, rather than sharing a community line. The app also follows your iPhone's light and dark mode with a calm design. The overall benefit is simple: callers are never left guessing, and you never have to dial in and press 1 to find out what a voicemail said. The use cases follow the modes. If you are in a meeting, Workday mode tells callers you will call back within the hour instead of leaving them with silence. If you are driving, Driving mode explains that you cannot pick up and will respond once you have parked — without you touching the phone. If you are mid-workout, Gym mode does the same in a lighter tone. If you are away for the weekend, Weekend mode redirects urgent matters to email until Monday. Someone who simply misses a call while out of signal still benefits, because the caller gets a text and any message left is transcribed and summarised for later. Anyone who screens calls, works across time zones or is frequently in situations where answering is impossible can let a mode handle the explanation while they stay present. Phonable is an iPhone app available on the App Store, and it is aimed at anyone who misses calls regularly and wants callers treated well without switching numbers. Pricing starts free with Test Drive, which includes greetings, voicemail and text backs, a monthly allowance of voicemails and texts, up to two modes and a shared community line. Basic, billed monthly or yearly, adds more voicemails and texts every month, up to five modes and modes that switch on a schedule. Pro, also monthly or yearly, is described as everything Phonable does with room to spare: the most voicemails and texts, unlimited modes on a schedule, AI voice greetings and a dedicated line that is only yours. Prices are shown in the App Store in your local currency, yearly billing saves 20%, and you can cancel anytime in your App Store settings. Phonable's value proposition is that a missed call stops being a small failure on both sides. Callers get an immediate text explaining why you could not pick up and when to expect you back, and you get every voicemail transcribed and summarised by AI, delivered as a notification you can read in seconds. Nothing changes about your number, your SIM or your phone, forwarding takes about a minute to set up and can be turned off whenever you like, and you can start free before deciding whether Basic or Pro fits how many calls you miss. For iPhone users who cannot always answer, Phonable turns the calls you miss into handled, explained moments.
OpenPilot is an open-source desktop AI agent that runs locally and works with any large language model you choose. Instead of shipping a fixed, hosted model or forcing you through a vendor login, OpenPilot acts as a harness: you point it at any OpenAI-compatible API endpoint, add an API key, and the agent can then create files, scaffold projects, run real terminal commands, search the live web, and ship complete projects. It is built for people who want the agent itself—not the platform tax that usually comes with it—and who refuse to be locked into a single model provider. It is designed to be an agent that actually does the work, wiring filesystem tools, a live shell, web research, MCP, skills, and memory to the model you chose. The problem OpenPilot addresses is vendor lock-in. Most AI agents today tie you to one provider's account, one set of models, and one billing relationship, which means swapping models or moving to a local server requires rewriting your workflow. OpenPilot's answer is a harness, not a hosted model marketplace. There is no OpenPilot account and no vendor login required. You bring an OpenAI-compatible endpoint and API key—whether that is OpenAI, OpenRouter, a local server such as Ollama or LM Studio, or your own custom gateway—and your usage stays local to your keys. That makes the tool portable across the models you already pay for and keeps you in control of where your data and your spend go. The agent's filesystem tools are the foundation of its work. OpenPilot reads, writes, edits, greps, and globs across your workspace, so the agent can inspect a repository, understand its structure, and modify files in place. You can ask for a full project and watch the file tree fill in—for example package.json, src/index.ts, and src/routes/users.ts—and then refine the result with follow-up edits rather than starting over. Alongside file tools, the shell is a first-class capability. OpenPilot runs real terminal commands such as installing dependencies, starting servers, and running tests, streaming stdout back into the chat so you can see exactly what happened. This is not a pretend snippet; it is an actual shell connected to your machine, and you approve sensitive actions before they run. Because you explicitly open a workspace by pointing at a folder, the filesystem and shell access the agent receives is scoped to that workspace. When the answers you need live outside the repository, OpenPilot performs live web research. Using TinyFish, the agent searches and fetches pages in real time—for example looking up documentation, an API reference, or a specific error message—and then grounds its answer in what it actually read, returning a cited answer alongside the fix. The agent also supports skills and long-term memory. You can drop reusable playbooks into the workspace as skills, and persist preferences in a file such as AGENTS.md, including instructions like preferring TypeScript strict mode, using pnpm in a particular repository, or never committing .env files. OpenPilot loads these into context automatically and can update its memory when you ask, so preferences carry across sessions instead of being retyped every time you start working. For teams that need more than the built-in tools, OpenPilot connects to Model Context Protocol (MCP) servers, which can be flipped on per chat. MCP lets you extend the agent with the systems you already run—databases, browsers, or internal APIs—configured through an mcp.json file and enabled only when a conversation needs them. On the model side, configuration is deliberately simple: paste a base URL, an API key, and a model id, and you are connected. Each model can have its own custom base URL and key, so you can swap providers without rewriting your workflow. OpenPilot also shows session and lifetime token usage in-app, giving you visibility into consumption across the endpoints you use, both cloud APIs and local OpenAI-compatible servers. OpenPilot's overall approach is a three-step workflow. First, add a model by pasting your base URL, API key, and model id—no account with OpenPilot is required. Second, open a workspace by pointing the app at a folder; the agent then receives filesystem and shell access there. Third, describe the outcome you want: ask it to build, fix, research, or automate something, and then review the tool trail as it works. That tool trail is central to how OpenPilot operates. Rather than presenting an answer as a black box, the agent surfaces the sequence of tool calls it makes—file writes, edits, commands, searches—so you can follow along and intervene where needed. The benefits follow directly from that design. Because the agent runs locally as a desktop application and uses your own keys, there is no vendor login and no locked-in models; you keep usage local to your keys and stay portable across providers. Swapping models does not require rewriting your workflow, so the same working habits carry across a cloud API, a local server, or a custom gateway. Token tracking in-app makes spend visible at both the session and lifetime level. Skills and memory reduce repetition by carrying your preferences and playbooks into context automatically, and MCP support means the agent can reach the systems you already rely on. For developers who want an AI agent that works on real files and real terminals, OpenPilot delivers that capability without the platform tax. Concrete scenarios described in the content include scaffolding an entire project from a prompt and then iterating in place with follow-ups; installing dependencies, starting servers, and running a test suite such as npm test with the results streamed back into the chat; researching documentation, APIs, or errors that live outside the repo and receiving a cited answer plus a fix; and automating build, fix, or research tasks by simply describing the desired outcome. Users running local models through Ollama or LM Studio can keep everything on their own machine, while those using OpenAI, OpenRouter, or a custom gateway can move between cloud providers as needed. MCP connections extend these same workflows to databases, browsers, and internal APIs when extra tools are required. OpenPilot is aimed at developers and builders—people who want the agent rather than the platform tax and who refuse vendor lock-in. It ships as a local Electron desktop application under the MIT license, and pricing is free. Windows is available now with a 64-bit installer and a portable executable, requiring Windows 10 or later (x64); macOS builds for Apple silicon and Intel are releasing soon. The model layer is bring-your-own, using any OpenAI-compatible endpoint, including OpenAI, OpenRouter, local Ollama or LM Studio servers, or a custom base URL gateway. In short, OpenPilot is an open-source desktop AI agent that puts you in control of the model, the keys, and the machine. Own the harness, bring the model, and let the agent do the work—without vendor lock-in.
AgentSDR is an open-source, self-hosted AI SDR workspace for outbound sales teams. It runs email sequences, LinkedIn campaigns and WhatsApp calls from one place, and pairs them with an AI CRM that reads every reply, classifies it and drafts the answer. The product is described as the open-source AI SDR that replaces Clay, Smartlead, HubSpot and many more, and it is designed to run on your own server with your own model key. Its stated promise is to reach, reply and close from a single workspace: sequences on each channel, AI triage on every reply, and measurement of replies, meetings and customers in one view. It is built for teams that want to own their outbound stack instead of renting a hosted service. Outbound today is spread across a long list of separate tools. The AgentSDR landing page shows logos for Smartlead, Clay, Instantly, HubSpot, HeyReach, Attio, lemlist, Salesforce, Apollo.io, Pipedrive, Expandi, Close, Outreach, Lusha, Salesloft, Hunter, Waalaxy and folk, making the fragmentation of the modern sales stack visible. AgentSDR's answer is to collapse that stack into one self-hosted workspace where email, LinkedIn and WhatsApp run side by side and every reply lands in a single AI CRM. Because it is self-hosted, your leads, conversations and call recordings live in your own Postgres database and your own storage bucket, and there is no hosted AgentSDR service in the middle. Provider keys are encrypted at rest with AES-256-GCM, and the data and sending reputation stay yours. Email is the first channel. AgentSDR sends multi-step sequences from your own Google Workspace mailboxes, connected through a service account with domain-wide delegation. Any CSV or XLSX column can be used as a merge field, and the system supports {A|B} spin text. Each mailbox has its own daily cap — 30 by default — plus its own sending window and signature, and campaigns can share the same pool of mailboxes, which are assigned round-robin. The list tools include one-click unsubscribe and automatic bounce suppression. The email analytics view shows emails sent, leads contacted, replies, reply rate, bounced and unsubscribed, and it is explicit that opens and clicks are not recorded, so reply rate is the engagement metric to watch. A campaign table breaks those numbers down per campaign, and mailbox health is shown with near-limit warnings and connected versus failing accounts. LinkedIn campaigns run across several accounts through Unipile. A sequence consists of an invite, an accept message and three follow-ups. Safe pacing keeps the accounts inside LinkedIn's limits: 30 invites a day on premium accounts and 5 on free accounts, a randomised 30–60 second gap between invites, and sending only inside each account's working hours; an account that hits LinkedIn's own limit pauses for the day. Search batches can bring up to 400 leads a day per account into campaigns, and every LinkedIn reply appears in one thread view with an AI draft ready. WhatsApp adds calling and messaging. A Chrome extension, the AgentSDR Call Recorder, dials inside WhatsApp Web when you call a lead from AgentSDR, records both sides to your Cloudflare R2 bucket, and your chosen model writes the transcript; it relies on WhatsApp Web's English interface. Unanswered leads can be retried after 1, 2 and 4 days, and messages sync with a 24-hour warm-up for new numbers and a limit of 25 new chats a day per number. At the centre is the AI CRM and inbox. Every reply is classified as Interested, Customer, Not interested or Other, using your own stages. Grounded drafts are written from your knowledge base — pricing, FAQs, case studies and objections — and held for approval rather than sent automatically; reply sequences also have every follow-up step drafted for review. The analytics show how many drafts were sent, how many replies the AI classified, and the override rate for labels a person changed. In the sample data, 71% of sent drafts went out unedited (151 of 214). The inbox is keyboard-first: J and K move, Enter opens, and ⌘K jumps anywhere. An Action required queue centralises conversations waiting on you, follow-ups that are due, and drafts to review, alongside warnings such as failing mailboxes or disconnected LinkedIn accounts. Under every channel is one database of people and companies. You import CSV or XLSX, add your own columns of text, number, date or select, and duplicates match on email or LinkedIn. Enrichment tables let a column call an API, run a formula, ask your model or pull from Apollo, and a table can then become a campaign. The AI layer is bring-your-own-model: every AI call runs on your OpenRouter key, pinned to the provider you chose with fallbacks turned off, so your data only goes where you decided. Classification, reply drafts, transcription and AI table columns all run this way. Optional lead enrichment integrations for emails, phones and company data include Hunter, Lusha, RocketReach, Snov, FullEnrich, LeadMagic, Findymail, ZeroBounce and Apollo, plus six more. The overall method is expressed in three words: Reach, Triage and Measure. Reach covers sequences on email, LinkedIn and WhatsApp inside each channel's limits. Triage means every reply is classified by AI with the answer already drafted. Measure means replies, meetings and customers are tracked by channel in one view. Deployment follows the same self-hosted logic: clone the repository, copy the example environment file and set the database, auth and encryption secrets, then run docker compose up; the app is ready at localhost and each channel is connected from inside the interface. Guardrails apply everywhere: daily caps, sending windows, warm-up for new numbers, and Do Not Contact honoured on every channel. The AI proposes and a person approves — a confident classification can move a lead forward in the pipeline, but a backward move, a low-confidence call and every new Customer are held for a person. The benefit is ownership and control. You send from your own accounts, so sending reputation and data stay yours; you pay for your server and your own AI usage rather than seats, tiers or per-contact fees. Analytics turn conversations into a clear view of meetings and customers by channel. In the sample workspace, 512 replies produced 104 positive replies (27% of people who replied), 37 meetings and 6 customers, with a median first response of 38 minutes; channel reply rates were 4.1% for email, 9% for LinkedIn and 18% for WhatsApp. Because drafts wait for approval, the human stays in charge of what goes out, while low-confidence classifications are held for review. Concrete workflows run through the workspace daily. A team imports a list, builds an enrichment table, and creates a campaign from it. Email sequences pace themselves across a pool of Google Workspace mailboxes, respecting caps and windows. LinkedIn accounts send invites and follow-ups within their limits, and replies arrive in a thread with a draft ready. WhatsApp calls are dialled from AgentSDR, recorded, transcribed and retried if unanswered. Reps then work the triage queue: approving or editing AI drafts, clearing follow-ups that are due, and moving leads through stages such as Information Requested, Demo Requested, Meeting Requested, Meeting Done and Trial User. Analytics closes the loop by showing which channel brought the replies, meetings and customers, and a single deployment can hold several organisations with separate leads, inboxes and connected accounts. AgentSDR is built for sales teams, founders and agencies that run outbound and want a self-hosted alternative to a stack of subscriptions; the product explicitly supports whole teams, with owners, admins and members, and multiple organisations in one deployment. What you connect is your own accounts: Google Workspace mailboxes for email sequences, Unipile for LinkedIn and WhatsApp, OpenRouter for every AI step, and Cloudflare R2 for call recordings, with optional enrichment providers for table data. The stack is a TypeScript Next.js 16 application using React 19, Postgres, Drizzle, Tailwind 4, Bun and Docker, and it needs a machine that runs Docker plus PostgreSQL 16 or newer. Pricing is free: the project is open source, with no seats or per-contact fees, so the only costs are your server, your connected accounts and your AI usage. AgentSDR's core proposition is simple: one open-source, self-hosted workspace where email sequences, LinkedIn campaigns and WhatsApp calls sit beside an AI CRM that triages every reply and prepares the answer, with your data, your model key and your sending reputation kept on your own infrastructure. Teams reach, reply and close from a single place, with guardrails on every channel and a human approving the drafts.
The archive
Maisters TalentIQ™ is an AI-powered recruitment platform designed for government agencies and public-sector organizations that need to modernize hiring without sacrificing transparency, fairness, or compliance.The platform automates time-consuming recruitment activities including candidate screening, qualification checks, structured first-round interviews, candidate scoring, interview documentation, and compliance recordkeeping. AI-powered structured interviews give every candidate consistent questions and evaluate responses against agency-defined competencies and scoring rubrics.TalentIQ™ is designed with government hiring requirements in mind. It provides explainable candidate scoring, bias monitoring, veteran preference handling, compliance documentation, configurable records retention, and complete audit trails that help HR teams prepare for reviews, public-records requests, and internal oversight.Hiring managers receive ranked candidate shortlists supported by interview transcripts, scoring details, evaluation criteria, and decision evidence. Human staff retain final hiring authority throughout the process.The platform also provides workforce analytics for monitoring time-to-fill, candidate sources, hiring patterns, pipeline diversity, and recruitment performance. It can integrate with existing applicant tracking systems, HRIS platforms, background screening providers, credential verification services, identity providers, and agency-specific workflows through APIs.Maisters TalentIQ™ helps public-sector HR teams reduce administrative workload, accelerate recruitment, improve consistency in candidate evaluation, and maintain documented, audit-ready hiring processes.
Mega Jell-EEZ Peelable Mango is a fun and flavorful jelly candy made for mango lovers. Its peelable design adds an enjoyable way to eat the soft, chewy candy while delivering a sweet and fruity mango flavor in every bite. The playful texture and easy-to-peel format make it a fun choice for candy lovers, parties, sharing, and everyday snacking. Perfect for retailers and wholesale buyers looking to add an eye-catching mango treat to their candy selection. Visit us for more information!
Hark Pro is a personal AI built to take things off your plate rather than add another chatbot to your day. The company describes it as a new kind of system for getting things done: whatever you need, let Hark handle it. Hark remembers what matters, thinks ahead about what you might need, and uses its own cloud computer to get things done across the web, covering everything from managing calendars and email to shopping, travel, bills, and everyday errands. Hark Pro is available as an app on browser, iOS, and Android. The product is positioned against the usual pattern of AI tools, which the company frames as adding another chatbot to your day rather than removing work from it. The tasks Hark takes on are the ones that quietly pile up: remembering that you put off getting home insurance quotes, comparing equivalent coverage, ordering from your usual pizza place, sorting email, submitting expenses from receipts, or finding a spot for an annual physical. Each of these normally means opening a browser, logging in somewhere, comparing options, filling in forms, and often making a payment. Hark's premise is that you should be able to state the outcome you want and let the AI carry out the steps. The core of the everyday experience is a single chat thread. Chat with Hark in a single thread for whatever you need, whether that is booking a table for a birthday dinner, submitting expenses from email receipts, or doing quick research. Hark has persistent memory, so it tailors responses to actually be useful to you rather than treating every request as a fresh start. That memory is what allows it to act on personal specifics, such as your usual order or the coverage you already have. For larger efforts, Projects keep bigger undertakings organized; the company names job searches and trip planning as examples of the kind of work that benefits from being grouped rather than scattered across messages. Hark's computer use agent is called Handoff. It can use the internet just like you would, and it can build websites, do research, place orders, and make slides, among other things. Crucially, it does this from its own secure computer with a full browser that is individual to you, rather than simply returning text suggestions. That means tasks which require navigating real websites, clicking through flows, and completing transactions can be carried out from start to finish instead of being described back to you. Because Hark asks you to connect accounts, save logins, and make payments, the company treats security as a first-class part of the product under the name Secured by Hark. It uses end-to-end encryption so your data stays safe, and describes the arrangement as a vault that absolutely no person has access to. Hark also checks in with you before doing something that requires your approval. The company states that your sensitive credentials stay encrypted, that Hark never sells your data or shares it with advertisers, and that you can watch it work. Action Buttons are Hark's answer to the to-do list. Hark suggests and prioritizes these actions based on what it knows you have on your plate, so the list is generated for you rather than written by you. All you have to do is click on one, and Hark will perform that action from start to finish. This turns the assistant into something closer to a queue of delegated work than a conversation you have to keep driving. Panels are customizable views you create to stay on top of whatever you like. You describe what you want and Hark builds mini-apps completely tailored to you. You can also ask your Panels questions to dig deeper into their data, unlocking even more from services you already use; Strava, Spotify, and Venmo are the examples named on the site. Where Action Buttons handle discrete tasks, Panels are about ongoing visibility into the things you care about, built on the fly from your own description. Taken together, Hark's approach is to combine a conversational front end, persistent memory, a proactive task layer, and an agent that can actually operate the web. Rather than a chat window that only produces answers, Hark pairs the conversation with Handoff's own secure browser, with end-to-end encryption protecting the accounts and payment details you connect, and with approval checkpoints before sensitive actions. Meanwhile Action Buttons and Panels let the assistant surface what it thinks you should do and give you customized views of your own data. The result is a single system that spans talking to an assistant, delegating to it, and monitoring what it has done. The stated benefits are practical. Hark is designed to take things off your plate, remember what matters, and think ahead about what you might need. It can handle calendars and email, shopping, travel, bills, and everyday errands on your behalf, and you can watch it work. With persistent memory, responses are tailored rather than generic; with Handoff, work that would otherwise require your own browsing can be completed end to end; with Action Buttons, you get a prioritized to-do list you can clear with a click; and with Panels, you can dig deeper into data from services you already use. The site illustrates the scope with example requests. Hark can be asked to book a trip to Mexico City next weekend, find the cheapest flights, and locate a nice hotel in Polanco, or to find the cheapest flight from SFO to JFK this weekend and book it. It can order a Margherita from your usual pizza place, or find a nice dinner for two in your neighborhood this Friday. It can find competitive home insurance quotes with equivalent coverage, show a comparison, and make the switch, or audit what you are spending the most on and help you save money. It can find a dentist who takes your insurance and book a checkup, or find a spot for an annual physical. It can help manage and sort your email, submit expenses from email receipts, and do quick research. And through Handoff it can build websites, do research, place orders, and make slides. Hark Pro is aimed at people who want their everyday logistics handled without adopting another tool to manage. The examples span travel, dining, insurance, spending, health appointments, and email, the kind of personal admin that any busy individual faces. It is offered through the Hark Pro app on browser, iOS, and Android, and sign-up is through Google or Apple, or by continuing directly; by continuing you agree to the Terms of Service and acknowledge that your data will be processed in accordance with the Privacy Policy. The company frames the product around building the most personal, human-like intelligence in the world, and points to enterprise-level security as part of that promise. In short, Hark Pro sets out to be the personal AI that handles life before you have to. It combines a persistent-memory chat, Projects for bigger goals, Handoff's secure browser-based agent, approval-gated encryption, Action Buttons, and custom Panels into one system, built to take things off your plate rather than add another chatbot to your day.
Paw-Paw is a free desktop pet for macOS. A small illustrated animal sits on your screen — in the bottom-right corner next to the Dock, or the bottom-left in Mirror Mode — and reacts as you type and click anywhere on your Mac. It is made for anyone who wants a little companion while they code, write or study, and it deliberately stays out of the way. There are no ads, no subscription and no account needed. Paw-Paw runs on any MacBook, iMac or Mac mini with macOS 13 or later, and you download it directly rather than through the App Store. Click your Paw-Paw to hear a short cheering line, or type fast to set it On Fire. Most of the day on a Mac is quiet and solitary: typing, clicking, switching windows. Paw-Paw turns that ordinary activity into something a bit cozier. Instead of adding another dashboard or task list, it makes the typing and clicking you already do count for something — key presses and clicks build XP, and XP levels your Paw-Paw up. The pet is designed to stay out of the way, so it never becomes another thing to manage. Paw-Paw needs macOS Accessibility access to notice when you type and click, but it counts key presses and clicks only, never what you type, and it never logs or transmits typed text. It checks its CDN for updates, and it sends usage analytics or crash diagnostics only if you opt in. The core loop is reactions and XP. You start with Shiba or Sheep, and as you type and click each season grows on its own track. Get into a rhythm and your Paw-Paw catches fire, setting it On Fire and earning 2× XP while it burns. You can choose which season or collection earns XP, so your progress goes where you want it. Leveling up unlocks more Paw-Paws, and both seasons — Season 1, the original Paw-Paws, and Season 2, which starts with Sheep — are free to discover. Clicking your Paw-Paw also makes it talk, offering little cheers for the next small step in speech bubbles. Paw-Paw is also a collection game. Type, click and work to earn random item drops: more than 100 free items, from common sprouts to legendary frog princes, and every one of them fits every Paw-Paw. You try an item on by clicking it or dragging it onto your Paw-Paw in the corner; click or tap it again to take it off. Gifts arrive as one of three gift balls — pick one and you can wear what is inside straight from the reveal — and Open All lets you open a pile of gifts at once. The Library window brings every Paw-Paw, item and achievement together in one place, with a page for each season, a category filter, a search field, and badges showing which season each item came from. Season 2 added achievements to earn, along with secret Paw-Paw and item pairings to find in the app. Achievements appear as pop-ups, such as First Spark and New Look. You can also make the pet yours: choose a Small, Medium or Large size and turn on Mirror Mode in Settings, then right-click your Paw-Paw, or its Dock icon, to switch Paw-Paws and items or set its opacity. Your Paw-Paw sits next to the Dock but can be dragged anywhere, and Reset Position puts it back. Paw-Paw also has its own Dock icon, with a right-click menu that includes Open Library, Change Paw-Paw and Click-Through, among other options. Paw-Paw's approach is deliberately lightweight. It is a native macOS app rather than a browser toy, shipped as a universal binary that runs on Apple silicon and Intel Macs. You download it directly, with no App Store and no sign-up, and the download is signed with Apple Developer ID and notarized by Apple. Accounts are optional: sign in only if you want to buy a collection or keep your progress in sync, and signing in on a new Mac brings your progress along in one step. Updates download in the background, the Library now opens on Home, and a short tour shows you around after setup. Compared with most desktop extras, there is very little to configure and nothing to maintain. The outcome is small but real: a desk that feels less empty during long sessions. Because Paw-Paw reacts to what you are already doing, using it costs no extra effort — you do not open it, configure it or check it, and XP, item drops and achievements simply accumulate while you type. The pet naps when you pause and returns when you start again, so it stays out of the way until you want to interact with it. Clicking it gives a quick moment of encouragement; leveling up gives you new Paw-Paws and items to look forward to. Everything is free with no ads and no subscription, so the fun does not come with an ongoing cost or a recurring bill to track. Day to day, Paw-Paw fits the way people already work on a Mac. During a long coding session it keeps you company and quietly turns keystrokes into XP; while drafting or writing it levels up on the same typing you would do anyway. Students and solo workers get a tiny companion in the corner that cheers them on when they click it. Collectors work through two seasons of Paw-Paws and 100+ items, hunt achievements and secret pairings, and try endless item combinations on their pet. Anyone who uses more than one Mac can sign in and carry their progress along. And because the pet can be resized, mirrored, made more or less opaque and dragged anywhere, it also serves as a small piece of desktop decoration you can arrange around your own setup. Paw-Paw is aimed at macOS users who want a cute, low-effort companion on their desktop, and at collectors who enjoy unlocking things over time. It requires macOS 13 Ventura or later, including macOS 14 Sonoma, macOS 15 Sequoia, macOS 26 Tahoe and macOS 27, and runs on Apple silicon and Intel Macs, from a MacBook Air to an iMac or Mac Studio. It is macOS only for now; a Windows version is planned for later in 2026, alongside multiplayer, Season 3, a winter holiday special and Japanese, Korean and Chinese translations. Pricing is simple: Paw-Paw is free, with both seasons, all of their Paw-Paws and items, and no ads or subscription. The one optional extra is the Illustrain Collection — 5 Paw-Paws and 57 items on a level track of their own, illustrated by Illustrain, bought inside the app for a one-time USD 2.99. In short, Paw-Paw turns the ordinary typing and clicking you already do on a Mac into a small, free, ongoing source of companionship and collection. It asks nothing of you — no account, no subscription, no ads, no keystroke recording — and gives back reactions, cheers, XP, level-ups, items and achievements, all from a tiny friend sitting quietly in the corner of your screen.
Clippo is a visual orchestration canvas for Windows that turns software development into a command room where you act as the tech lead and your AI coding agents work together in parallel. Instead of wrestling with dozens of lost terminal tabs or repeatedly copy-pasting the same briefings, Clippo gives you an infinite canvas where you assemble your AI dev team, delegate tasks, and monitor code progress in real time, arranging your workspace however you like. It is built for developers who already use AI coding agents day to day and want a single screen to coordinate them, watch what they are doing, and keep every piece of project context in one place. The problem Clippo addresses is fragmentation. When you run several AI coding agents at once, each one typically lives in its own terminal tab, and the moment you switch between them you lose sight of which agent is still coding and which one has finished. Briefings get copied and pasted again and again, and context that was explained to one agent is not available to the next. Clippo replaces that scattered, tab-driven workflow with a spatial one: agents, notes, browsers, and editors are all placed on one canvas and connected to each other, so the state of your project is visible at a glance rather than buried in a list of windows. Clippo's core capability is running your AI dev team in parallel. You can assign agents to different fronts at the same time — one building the backend API, another writing test suites, and another refactoring the frontend — and see everyone working side by side on a single screen. Because the agents are laid out visually, you know instantly who is coding and who is done without switching windows. This parallel approach matters because development work naturally splits into independent tracks, and keeping those tracks visible next to each other makes it far easier to spot a stalled agent or an overlapping change before it becomes a problem. The Project binder keeps your agents aligned through a structured set of notes placed directly on the canvas. It has three parts. Project captures the overall architecture, stack guidelines, and team conventions. Plan holds a step-by-step implementation roadmap for you to review before execution begins. Walkthrough produces an executive delivery report with diff summaries and verification checklists. The binder is not just documentation — you connect a cable from any note to a terminal, and the agent absorbs that context immediately, with no re-prompting needed. That single mechanism means architecture decisions, conventions, and roadmaps are shared with every agent you link, keeping a multi-agent effort pointed in the same direction. ClipSurf is an embedded browser that lives on the canvas and serves as web browsing and eyes for any agent. It is available to both you and your agents, and it is particularly valuable for terminal agents and CLI models that do not have built-in web access. With ClipSurf those agents can browse documentation, research solutions online, and test the local web app they just built, live in front of you. Getting external information into an agent normally means copying links and pasted text; ClipSurf removes that step and lets the agent look things up directly, while you watch the same view it is working from. Persistent memory with local AI addresses one of the most costly parts of working with coding agents: losing context between sessions. Clippo keeps a local memory that learns your project over time, storing architectural decisions, solved pitfalls, and coding standards. A lightweight local model retrieves relevant memories on demand, which cuts token usage and keeps context across sessions. The practical effect is that an agent starting a new session does not begin from zero — the decisions you already made and the problems you already solved are available to it, and because retrieval is local, that recall does not come with a token cost for re-explaining the project each time. Clippo IDE is a visual code editor built into the canvas, designed for inspecting and polishing code before Git. You can browse project files, review agent-generated code with syntax highlighting, inspect Git diffs, and make quick edits before committing with a single keystroke. Because the IDE sits on the same canvas as the agents, reviewing their output does not mean leaving the orchestration view. The point is control: agent-generated code is checked, adjusted, and only then committed, so you stay in full control of your repository rather than trusting output blindly. Clippo is built to be lightweight, fast, and 100% private. There are no bloated web wrappers that eat up your RAM; Clippo opens fast, stays light, and leaves your CPU and memory free for compiling and development. Your files, notes, and prompts never leave your PC, with zero account creation, zero login, and zero tracking. For developers working on proprietary code, that on-device design removes the friction and risk of sending project material to a third-party service just to coordinate the tools building it. Overall, Clippo works as a visual orchestration layer that sits alongside the AI tools you already use rather than replacing them. It is compatible with Claude Code, OpenAI Codex, Gemini CLI, OpenCode, Aider, Copilot CLI, and local engines like Ollama and LM Studio, and WSL and Docker are supported out of the box. The methodology is node-based: you place terminals, notes, browsers, and editors on an infinite canvas and link them with cables, so context flows from a note into an agent, and agents run in parallel on separate fronts of the same project. Everything — unlimited terminals, notes, Clippo IDEs, ClipSurfs, and Spaces — lives inside the workspace you arrange yourself. The benefits Clippo claims follow from that structure. You stop drowning in terminal tabs and stop copy-pasting briefings, because one canvas shows every agent's progress at once. You save tokens, because on-device memory recalls project context instead of forcing you to restate it. You keep your CPU and memory for compiling and development, because the app stays light. And you retain full control of your repository, because nothing is committed before you review it in the built-in IDE. The outcome is a workflow where you step up as tech lead of your own AI engineering team rather than acting as a dispatcher between disconnected windows. Concrete scenarios include splitting a feature across agents — one on the backend API, one writing test suites, one refactoring the frontend — while you watch all three on one screen. Another is giving a CLI model without web access the ability to browse docs and research a solution through ClipSurf, then test the local web app it just built in the same embedded browser. A third is reviewing agent-generated code, inspecting Git diffs, and making a quick edit before committing. Persistent memory supports ongoing projects where sessions restart regularly, and the Clippo Pro add-on covers developers working across multiple projects at once using unlimited workspaces. Clippo is aimed at developers who use AI coding agents such as Claude Code, OpenAI Codex, Gemini CLI, OpenCode, Aider, or Copilot CLI, and at anyone running local engines like Ollama or LM Studio. It runs on Windows 11, version 22H2 or higher, on x64. The free plan includes a complete workspace with unlimited terminals, notes, Clippo IDEs, ClipSurfs, and Spaces inside it. To work across multiple projects at once, the Clippo Pro add-on unlocks unlimited workspaces through a one-time purchase from the Microsoft Store. The app offers in-app purchases and is developed by Thiago Grião. Clippo's primary value proposition is simple: it gives Windows developers a visual command room for AI agents, turning a scattered collection of terminal tabs into one infinite canvas where agents run in parallel, project context is shared through linked notes, memory persists locally to cut token usage, and code is inspected before it ever reaches Git.
tide is a simple, self-hostable video conference service that positions itself as an alternative to Jitsi, Zoom and Google Meet. Rather than renting conferencing from a hosted provider, an organisation can run tide on its own infrastructure and host meetings at an address such as meet.custom.domain. The product's own tagline describes it as "A Jitsi alternative that does a few things really well," and the site lists the core capabilities as link sharing, screen sharing and server-side recording. It is for anyone who wants to own the video meeting stack rather than depend on someone else's servers, and the site offers both a live demo and deployment documentation as starting points. Most video conferencing today happens on someone else's infrastructure. Zoom and Google Meet are hosted services: the meeting runs on the vendor's servers, under the vendor's terms, and the media travels through networks the customer does not control. Jitsi offers a self-hostable route, and tide explicitly frames itself as an alternative to it, naming Zoom and Google Meet alongside. The problem tide addresses is therefore one of ownership: whose server carries the audio and video, who holds the recordings, and who decides the sign-in rules. The website states its answer in two headline bullets — "Media stays on your server" and "Server-side recording" — arguing that a conferencing service can stay simple while still keeping the media and the resulting files inside the operator's own environment. For teams with data-residency expectations, internal security policies or a preference for self-reliance, that distinction weighs more heavily than a long feature list. Deployment is presented as one of tide's defining traits. The site lists "One Go binary" as its first bullet and calls tide a simple, self-hostable video conference service. Two links carry the practical next steps: a demo instance at demo.tide.convex.works and a Deploy link pointing to tide.convex.works/docs. The single-binary pitch means the whole service can be distributed and run as one artifact rather than as a suite of separate components the operator has to assemble and keep in sync. Go is the one technology named directly on the page, and the claim of one binary follows from that. For anyone evaluating self-hosted video, the effect is a smaller surface to install, fewer moving parts to update, and a documented entry point at the docs URL. On the meeting side, tide covers the core workflow of getting people into a call. Link sharing is named among the core features, and the interface shown on the site includes a "New room" form with fields for a Name, a Link, and a calendar shortcut. The illustrated example is a "Weekly sync" with the link meet.example.com/m/chw-pnih-sxi, and the form includes an "Add to calendar" action plus a Date block with Starts and Ends times — 10/05/2026, 07:30 PM to 08:00 PM in the example. Two actions are offered once the room is configured: "Create" and "Create & join," so an organiser can either prepare a room or start it immediately. Screen sharing is listed explicitly as a core feature, and recording is handled server-side rather than on a participant's machine — the site states "Server-side recording" both as a headline bullet and in the Product Hunt description alongside link sharing and screen sharing. Sign-in is delegated to OIDC, the fourth headline point. Using OIDC means authentication can be tied to an identity provider the organisation already operates, instead of tide maintaining its own account system, which fits the self-hosted positioning: the operator keeps control over who is allowed in. The meeting view shown on the site displays named participants — Daniel, Maya, Marcus and Nikos, marked as "You" — with a participant count of four, illustrating a small call. The overall approach tide takes is stated in its own tagline: "A Jitsi alternative that does a few things really well." Rather than competing on breadth, the product concentrates on a short, explicit list — one Go binary, media that stays on your server, server-side recording and OIDC sign-in — and repeats that framing in the Product Hunt description: "A few things, done well." The same description notes that tide lets you host your own "meet.custom.domain" for "a simple video conferencing environment with all core features you expect." The methodology, in other words, is to be a focused self-hosted service: install one binary, point a domain at it, and run meetings with link sharing, screen sharing and server-side recording under your own roof. The benefits that follow from the page's stated facts are straightforward. Because media stays on your server, meeting traffic terminates in infrastructure the operator controls. Because recording happens server-side, call recordings are produced by the service itself rather than depending on a participant capturing their own local stream. Because sign-in uses OIDC, access control can follow whatever identity system the organisation already runs instead of a separate set of credentials. Because the service is a single Go binary, deployment and maintenance are framed as simple rather than as an ongoing platform project. And because the scope is deliberately small — a few things done well — the operator does not have to weigh a long list of optional modules to get a working conferencing environment. Concrete scenarios appear on the page. The "New room" example is a recurring team meeting — a "Weekly sync" scheduled for a specific date and time with a fixed start and end — and the presence of an "Add to calendar" action indicates the intended flow of setting up a meeting and adding the appointment to a calendar. The generated link, meet.example.com/m/chw-pnih-sxi, shows the pattern of a short meeting URL that can be shared with attendees, which matches the link-sharing feature. The "Create" and "Create & join" buttons serve both the organiser who wants to prepare a room ahead of time and the one who wants to start straight away. The demo at demo.tide.convex.works provides a way to experience a call before committing to a deployment, and the site's framing of "meet.custom.domain" points to organisations that want their meetings hosted on a domain of their own. Server-side recording suits meetings that need to be captured for people who cannot attend, and OIDC sign-in suits invitations that must be restricted to members of an existing directory. The intended audience can be read from the page's own vocabulary: the three alternatives invoked — Jitsi, Zoom and Google Meet — describe both the self-hosting tradition tide belongs to and the mainstream services it is offered against. Anyone who wants to run their own "meet.custom.domain" is the stated target. In terms of stack, the site names exactly one technology, Go, in the bullet "One Go binary," and describes OIDC for sign-in. Deployment documentation is linked at tide.convex.works/docs. The page itself does not state a price, plan or licensing model, and it does not describe native mobile or desktop applications; it presents a self-hosted service with a room creation form and a shareable meeting link. Taken together, tide makes a single, deliberate claim: video conferencing that you host yourself, built around a few things done really well. One Go binary to deploy, media that stays on your server, server-side recording and OIDC sign-in, wrapped around the familiar flow of creating a room, sharing a link, sharing your screen and joining the call. For teams that want their meetings — and the recordings they produce — to remain on infrastructure they control, tide offers a focused alternative to Jitsi, Zoom and Google Meet.
Udon is a control deck for a home server built on an Apple Silicon Mac. It turns a Mac mini, Mac Studio, MacBook, or iMac into a home for your files, photos, media, and apps, and lets you manage all of it from your browser. Udon installs with a single terminal command, and the Mac keeps working as a normal Mac. Any Apple Silicon Mac (M1 or newer) running macOS 26 or later is supported; Intel Macs are not. A Mac mini is the usual pick for an always-on home server because it is small, quiet, and draws a few watts at idle. An optional AI sysadmin can help you install apps, check the server, and investigate problems. The product is built for people who want to own their digital life and keep their data on hardware they own. macOS has no dashboard for running self-hosted apps, and Udon exists to add one. Without a control panel, running services on a Mac means working manually over SSH with a container tool such as Portainer, which puts everyday management out of reach for many people. The established alternatives are Unraid, TrueNAS, or Proxmox on dedicated x86 hardware, a Synology NAS, or Umbrel, CasaOS, or OpenMediaVault on a Raspberry Pi or spare PC. Each of those routes asks for extra hardware, extra power draw, or extra maintenance. Meanwhile a Mac mini idles at a few watts, runs near silent, and still has power to spare for media, photos, and a dozen containers, so the hardware is often already sitting on the desk. Udon provides the missing software layer that makes that machine manageable as a server. The AI sysadmin is Udon's most distinctive component. It is optional and stays off until you turn it on. When enabled, you can ask it to install apps, check your server, or investigate a problem, rather than working through each screen of the dashboard yourself. You choose the AI provider: connect an Anthropic or OpenAI API key, a coding CLI such as Claude Code or Codex, or a local model running on the same Mac. By default the assistant asks before every change, and it records its actions in an audit log, so you keep control over what happens to your machine. If you connect a cloud model, it sees what you ask the assistant to work on, which the website states plainly. Containers and packages are managed in one place. Udon runs standard images from Docker Hub, GitHub Container Registry, or any other registry, on Apple Container, Apple's native runtime, or on OrbStack, which is Docker-compatible. On OrbStack you can also build compose stacks in the visual Composer. Alongside containers, Udon manages Homebrew packages, so the software your Mac runs is chosen and tracked from a single interface instead of a mix of command-line tools. This matters because container and package management is usually the part of self-hosting that people find hardest to keep organised. The built-in App Store makes the first steps easier. You can install self-hosted apps with settings pre-filled, so building a photo library, streaming your media, or organising documents at home does not require configuring every service by hand. If the catalogue does not cover what you need, Udon points you to more apps on Docker Hub and Homebrew, and the documentation includes a guide on how to deploy a container. Terminal and remote desktop access are built into the dashboard. You can work on your Mac from any browser, with its terminal and its desktop within reach, and terminal sessions stay open between visits, so a long-running task is still there when you come back. Storage and sharing are handled in the same place. Your files stay on your own drives, and Udon lets you browse and preview them, check drive health, and share folders across your home network as SMB shares. Remote access is handled through Tailscale. Your files and apps live on your Mac, and you stay in control of them; Udon connects over your own Tailscale network with trusted HTTPS for the dashboard, so you can manage the server from your phone's browser at home or away without exposing it publicly. The Activity view shows how your Mac is doing at a glance: CPU, memory, network, and power use live, plus which processes are running. Together these two areas cover both reaching the server and understanding what it is doing. Udon's overall approach is to take a machine you already own and give it a browser-based control deck. Installation is a single terminal command, and after that the dashboard is reached at an address such as mac-mini.local:4443. Everything the product manages — containers and compose stacks, apps from the App Store, files and SMB shares, drive health, live system stats, Homebrew packages, a terminal, and the Mac's screen through remote desktop — is available from any browser. The Mac keeps working as a normal Mac throughout. A companion app for iPhone and Android is coming soon, and until then the dashboard works from a phone's browser. The benefits follow directly from that design. Your files, photos, and media stay on your Mac rather than in a cloud service, and the dashboard is served over HTTPS with remote access over your own Tailscale network. Udon is a one-time purchase rather than a subscription, so there is nothing to renew. Trying it does not require a card, and if you do not buy a licence after the free days, nothing is charged: the dashboard locks, but containers keep running and your files and settings stay exactly as they are. In practice, people use Udon to run the self-hosted services that would otherwise need a NAS or a separate server. Streaming media with Jellyfin or Plex, backing up photos with Immich, syncing files with Nextcloud, keeping passwords in Vaultwarden, blocking ads for the whole network, archiving documents with Paperless, and automating workflows with n8n are all named as things you can self-host on a Mac. Udon can also host your dev environments and coding agents, which you reach from a laptop or an iPad anywhere. Udon is available for Apple Silicon Macs running macOS 26 or later, with the dashboard managed from a web browser. It runs Docker images on Apple Container or OrbStack, manages Homebrew packages, and uses Tailscale for remote access. Pricing is a free 5-day trial with no card required, followed by a one-time payment: early supporters pay $29, reduced from $49, for a lifetime licence that includes every feature and updates and is tied to the Mac's serial number with no accounts. Every purchase comes with a 14-day money-back guarantee. Udon's core proposition is simple: own your digital life, start with your Mac. It takes an Apple Silicon Mac you already have, adds the dashboard macOS is missing, and brings self-hosted apps, containers, storage, monitoring, and an optional AI sysadmin together in one browser-based control deck.
offstage is a free, open-source tool that gives a computer-use coding agent its own Mac desktop instead of your screen. It works with Claude Code, Codex and opencode, and it exists for one purpose: any command an agent runs that could open a window or take focus on your Mac is sent to a second, logged-in macOS account instead. Simulators, Xcode UI tests, osascript calls and the app your agent just built all open on that helper account's desktop, which sits behind yours. Your windows, keyboard and mouse stay yours the whole time. offstage ships as an MCP server and a CLI, is MIT licensed, and runs on Apple Silicon Macs with Node 20 or newer. The problem it addresses is the collision between coding agents and your own computer. Agents increasingly do GUI work: they launch simulators, run Xcode UI tests, drive browsers and open the apps they just compiled. On a normal Mac all of that lands on the one screen you are using, taking focus, moving the mouse and covering your windows. offstage's answer is not to hide the GUI work but to give it a different desktop. Because the helper account is a real macOS account with its own desktop, window server and input, the agent can screenshot, decide and click in a place that never overlaps with what you are doing. The site states plainly why that second macOS account is the whole point: it has its own desktop, window server and input, and that is why offstage exists. The core of the product is the helper account. One setup command creates an ordinary account called computeruse and builds a small Swift daemon for it. If the terminal has Full Disk Access, that daemon is granted Screen Recording and Accessibility automatically; if not, offstage tells you which two toggles to flip. It prints the entire root script before running it. After a single login through the menu bar user menu, the account stays logged in behind yours until the Mac restarts. offstage session status reports where things stand and exits 0 when the session is ready. Nothing here is a virtual machine: it is a second user account on the Mac you already have, with no guest OS and nothing to boot. The trade-off is that both accounts share the Mac's CPU, memory and disk. Storage is where the difference is stark, because the helper account takes about 3 GB of disk, where the macOS VM image the team measured was a 68.8 GB download. offstage also decides where each command should go. The site describes it as reading every command before it runs and sending it to the cheapest place that keeps it off your display, and it defines four lanes. Commands such as xcodebuild test, xcrun simctl, XCUITests, open -a, osascript and a built .app run in the second macOS account. Commands that force a real browser window, including --headed, headless: false, cypress open, WebGL and GPU flags, run in a Linux container with a virtual display if Docker is installed; it is a real display, just not yours. Headless work such as npm test, vitest, headless Playwright and Puppeteer runs right where it is, because those never open a window and wrapping them would only cost time. Finally, installers, .pkg, .dmg and hdiutil are refused outright: both accounts share one machine, so offstage will not run them and no flag overrides that. Agents connect through MCP. The site provides copy-paste configuration for Claude Code (claude mcp add offstage -- npx -y --package=@viraatdas/offstage@latest offstage-mcp), for Codex in ~/.codex/config.toml, and for opencode in opencode.json. Claude Code can also use offstage as a plugin. The MCP surface includes offstage_route, which tells the agent which lane a command gets, and offstage_run, which runs it there, alongside session tools: offstage_session_launch, which waits until the app registers and returns its pid, offstage_session_screenshot, offstage_session_input and offstage_session_quit. The documented GUI loop is launch, screenshot, decide, input, then screenshot again to confirm. Coordinates are points, not pixels, so a pixel coordinate has to be divided by the screenshot's scale. For anything that cannot use MCP, the CLI runs the same code path through offstage route -- and offstage run -- . The reason offstage can promise your screen stays yours is the daemon. It posts input to its own session only, never to the global input stream that feeds your screen, and if its session is ever the one on the console it refuses to send input at all. In testing, the window server's own log showed every synthetic event landing in the helper session and none reaching the console. The site is equally explicit about files: the helper account is an ordinary second user, so it cannot write to your files, and it can read only what macOS lets any other local account read. If a run fails because the helper account cannot read your repository, offstage session share grants read-only access to one folder at a time, and unshare takes it back. Each run writes its output to its own artifacts folder. To make the behaviour stick, you paste a block of instructions into your agent, or into your project's AGENTS.md or CLAUDE.md, and the agent connects offstage itself so GUI work stays off your screen from then on. Two things only the user can do, and the site's rules tell the agent to ask rather than work around them: sharing a repository folder with the helper account, and running offstage session setup --create, which needs sudo. The agent is also told to never re-run a skipped or refused command outside offstage to get past it, because that would put it back on your screen. The practical outcome is that you can keep using your Mac while an agent runs an entire GUI test suite somewhere else. Nothing boots, nothing is virtualised, and the agent's windows, cursor and focus live on a desktop that is not yours. A skipped status means nothing ran anywhere, and refused means the command will not run on any lane. Concrete scenarios appear throughout the site. In one real pair of captures taken on a single Mac on 2026-09-22, Claude Code checks that the helper account is logged in, off your screen, with Screen Recording and Accessibility granted; a second Claude Code session is then testing a messaging app called i2Message on the computeruse desktop, with a search for the word coffee typed in through offstage_session_input. None of it appears on the console user's screen, and the console user was watching a video in a browser the whole time. Other workflows are the lanes themselves: running Xcode UI tests and simulators off-screen, driving a headed browser in a Docker container with a virtual display, leaving npm test or headless Playwright in place because they never open a window, and refusing installers so they never land on either account. offstage is aimed at developers on Apple Silicon Macs who run coding agents and want their own machine left alone during GUI-heavy work: Xcode and simulator workflows, UI tests, browser automation, and any project where an agent builds an app that then needs to be clicked. The agents it supports explicitly are Claude Code, Codex and opencode, through MCP, with Claude Code also usable as a plugin; anything else that can run a shell command can use the offstage CLI, which runs the same code. Requirements are an Apple Silicon Mac and Node 20 or newer, with Docker optional for the container lane. Pricing is free: the project is MIT licensed and open source on GitHub. The takeaway is that offstage solves a very specific, very annoying problem, an agent that needs a screen taking over the one you are using, by giving that agent a second, logged-in macOS account with its own desktop, window server and input. It routes each command to the cheapest place that keeps it off your display, refuses the commands that could touch the whole machine, and costs nothing but a folder share and one sudo command. Your agent gets its Mac desktop; you keep yours.
Liquid Inference is an LLM router that runs an instant auction for every AI request. You send an ordinary chat request, and providers compete to answer it at the lowest price that meets the rules you set. Instead of committing to one vendor's rate card, you describe what the request needs — model, region, speed and minimum quality — and the cheapest provider that satisfies those requirements answers. The product is built for developers and teams already working with large language models through coding agents, SDKs or direct API calls, and who want access to hundreds of open- and closed-weight models without managing a separate account, key and billing relationship for each one. Choosing a model provider has usually meant accepting a published, fixed rate and paying it whether or not cheaper capacity exists somewhere else at that exact moment. Inference capacity fluctuates with supply and demand, so providers often hold spare capacity they would be willing to sell at a lower price, but buyers have had no practical way to discover and capture that price request by request. Liquid Inference turns every prompt into a small auction to close that gap. Providers publish a price per token for each model and can change it at any time, lowering it when they have spare capacity. The result is that a buyer pays the lowest marginal cost available for that request while still getting the model, region, speed and quality constraints they specified. The auction runs in three steps. First, providers set their prices: each provider sets a price per token for each model and may change it whenever they like, so the offers on the book move with supply and demand. Second, the cheapest match answers: you set the rules — model, region, speed and minimum quality — and the cheapest provider that meets them answers your request. Third, you pay for what you use: before the model starts, you know the most a request can cost, and you are billed only for the tokens it produces. Because the cap is fixed before the first token is generated, the price of a request is known up front rather than discovered later on the invoice. Control over routing is explicit. A price limit is placed on every request before the first token, so you know the maximum a request can cost and pay only for the tokens produced. Routing rules let you choose the model, region, speed and minimum quality, and only providers that meet those requirements compete for the work. To support trust in the marketplace, Liquid Inference tests every provider regularly with standard benchmarks and publishes the results, so the speed and measured quality of providers are visible and the same rules apply to everyone. Billing is itemized, showing what every request cost line by line, and public price history lets you download live and past prices for every model so you can send work when prices are low. Liquid Inference covers hundreds of open- and closed-weight models, spanning families such as GPT, Qwen, Gemini, GLM, Deepseek, Gemma, Kimi, Grok, Claude, Mistral, O, Nemotron, Ernie, Mimo, Llama, Phi, Nova, Command, Hermes, Granite, Sonar and many more. Model counts per family are listed on the site alongside the lowest current offer in USD per million output tokens, which ranged from $0.01 for Nemotron to $4.62 for O at the time of capture. Compatibility is deliberately simple: one key covers both OpenAI Chat Completions and Anthropic Messages on a single base URL, so existing code works unchanged, and getting started requires changing one URL. The product also supports full multi-modal requests. The overall approach is to treat inference as a live market rather than a static catalogue. Providers compete dynamically on price for every single prompt, offering the lowest marginal cost at the moment the request is made. You can create routing rule presets or use the Auto routing algorithms to decide how requests are matched, and the rules you set determine which offers are allowed to compete. Because providers can raise or lower prices at will and stop quoting when they are full, the offers on the book reflect current capacity. The buyer's side of the market is equally concrete: a single base URL, one API key, and code that already speaks the OpenAI or Anthropic API continues to work. Practically, this means a lower cost per request for equivalent work, because you are matched to the cheapest provider that meets your stated requirements rather than paying a fixed published rate. It means more predictable spend, since a price limit is fixed before the first token and you are billed only for produced tokens, with itemized billing showing what each request cost. It gives you leverage over supplier choice — model, region, speed and quality are yours to specify — while independent benchmark results keep providers comparable. And because prices move with supply and demand, public price history gives you the information needed to time workloads when prices are low. Concrete workflows follow from those capabilities. A developer using an agentic coding tool such as Claude Code, Codex, Cursor, OpenCode, Cline or Pi can point the tool at Liquid Inference by changing the base URL, keeping their existing client while gaining access to every listed model. A team planning spend can pick a model and a monthly output volume in the cost estimator and see the lowest offer now and the estimated cost per month. A workload that is price-sensitive rather than latency-sensitive can be scheduled using public price history when prices are low. A user who needs multi-modal support can send those requests through the same single key. And anyone already running inference on their own models can join as a provider, post a price and be paid for the tokens they serve. For buyers, sign-up is free with email and the first 500 users receive $20 of free inference; referring others earns 20% of referred fees as free inference, with 10% for second-level referrals. Access is through an API key and the base URL https://router.inference.ai.exchange/v1. The documented list of compatible clients and SDKs includes Claude Code, Codex, Pi, Oh My Pi, Cursor, OpenCode, Cline, Roo Code, Kilo Code, Goose, Open WebUI, Cherry Studio, n8n, the OpenAI SDK, the Anthropic SDK, the Claude Agent SDK, the OpenAI Agents SDK, the Vercel AI SDK, LiteLLM, LangChain and curl. On the supply side, anyone running models can create an account, register the deployment they want to serve, have an operator review and list it, then connect their agent and start quoting. Registration as a provider is free, and Liquid Inference charges its fee to the customer, not to the provider. In short, Liquid Inference replaces fixed inference pricing with a per-prompt auction in which providers compete to serve your request at the lowest price that still satisfies your rules. You keep the models and tools you already use, gain a price cap before the first token, itemized and predictable billing, benchmark-backed provider trust and public price history, while providers gain a live market for their spare capacity. The value proposition is straightforward: complete your AI requests and pay the lowest offer that meets your requirements.
BotBus is an app for keeping tabs on the AI coding agents running on your computer from your phone and Apple Watch. On the computer it lives in the menu bar and automatically discovers local agents such as Codex and Claude Code; on your phone and watch you can follow task progress, approve, follow up, interrupt, and start new tasks. Tasks from all of your computers are gathered in one place, sorted by agent and project, so developers who run agents locally can stay in control without sitting at their desk. What you can do depends on the connector, the task's state and whether the computer is online. Coding agents do not only write code; they pause. An agent may want to run a command such as a test suite, edit files, or ask a question before continuing, and it waits until someone answers. When that someone is away from the keyboard, the work stops, and a task that could have been finished in an hour sits idle until the developer returns. BotBus is built around that gap. Its promise is that you can step away from your computer and the work keeps moving: approvals, follow-ups and new instructions arrive on the device that is already in your pocket or on your wrist. The desktop app quietly discovers the agents already installed on the machine rather than asking you to configure them, and the phone app turns those agents into something you can supervise from anywhere. Every computer at a glance. BotBus collects tasks from all of your paired computers and sorts them by agent and project, including the tasks you started at your desk. A device list shows online status and pending counts for each machine, and opening a single computer reveals its pending and running tasks alongside recent projects, so you can tell at a glance where attention is needed. New tasks, on the go. From your phone you pick a computer, a project and an agent, say one sentence, and the task starts. You can choose the model, or run the task in its own git worktree so parallel work stays isolated from your main checkout. Approvals and questions in one tap. When an agent wants to run a command, edit files or ask you something, BotBus nudges you, and you answer with a tap on your phone or your watch. Auto-approve can be turned on for a project when you would rather not be asked. Beyond approvals, BotBus also supports following up and interrupting a running task, voice input for instructions or replies, sending photos from your phone, reviewing uncommitted changes, and switching the model and reasoning effort for a task. Watch sync means that once your watch has synced pairing from your phone it connects on its own, so common actions do not require pulling out your phone at all; the watch can show all devices, recent projects, approval requests and a task awaiting your reply with voice reply. Control your computer's screen. On supported setups you can see your computer's screen live on your phone and tap, swipe or type on it. Input starts locked, and both the picture and your input are end-to-end encrypted. Screen control currently supports Mac. Results, straight to your phone. Screenshots, files and videos come back together with the task, and images and PDFs mentioned in the chat open with a tap, so you can inspect what an agent produced without transferring anything by hand. Preview web pages on your phone. When an agent starts a dev server, BotBus lets you preview the page it built on your phone, without going back to your computer. BotBus works through a small desktop app plus a pairing flow. You install BotBus on your computer, where it lives in the menu bar, runs in the background and automatically discovers local agents. Choosing 'Pair a Phone' shows a QR code; scanning it pairs the phone, and the key never goes through the server, staying in each device's keychain instead. Content is encrypted with AES-256 on your device before it is sent, so the server only relays and briefly holds ciphertext and cannot decrypt your chats, commands or images. Pairings that idle for 30 days are cleared, and removing any single computer or phone disconnects it at once. The server still sees the little it needs to relay data: device IDs, online status, update times and data sizes. Developer previews, which share a web page from your computer to your phone, are proxied through the server and are not end-to-end encrypted. Viewing already-synced tasks does not require the computer to be online, but approving, following up, starting new tasks and interrupting do require the target computer to be online and supported by the connector. The benefit is continuity. Instead of returning to the desk to unblock an agent, you answer the approval from your phone in a tap, or reply by voice from your watch. Instead of wondering whether a long job finished, you glance at a device list that shows pending counts across all your machines. Instead of waiting to see what an agent produced, the screenshots, files, videos, PDFs and dev-server previews arrive with the task. BotBus does not change how your agents work; it changes where you have to be while they work, so a commute, a meeting or an evening away does not mean downtime for your machine. Typical scenarios follow the way developers actually work. A test suite fails and the agent asks to run a command; you are away from your desk, so you approve it from your phone and the run continues. You think of a small fix while commuting, so you pick the project and agent, say one sentence, and the task starts on the computer at home. You run several machines and want a single view of pending and running work, sorted by agent and project. You want to see the landing page an agent built before you get back, so you preview the dev server on your phone. You are traveling and need to take control of your Mac's screen directly. Or you are in a meeting, an approval arrives, and one tap on your watch, or a spoken reply, keeps the agent moving. BotBus runs a desktop app on macOS, Linux and Windows and a mobile app for iOS and Android. The Mac app requires macOS 26 or later and is universal for Apple Silicon (arm64) and Intel (x86_64); the current download is BotBus for Mac 1.0.6 (build 33), 24.3 MB, released 2026-10-08, with a published SHA-256 for verification. Linux is a command-line version for servers and dev machines, covering mainstream x86_64 and aarch64 distros with or without systemd and installing without sudo; you scan a QR code in the terminal to pair. Windows 10 and 11 is ready to install, runs in the background after you sign in with a tray icon, needs no administrator rights, and requires Windows 11 on ARM PCs. On mobile, the iPhone and Apple Watch app requires iOS 26 / watchOS 26 or later and comes bundled with the watch app; Android 8.0 or later is available on Google Play or as a direct APK download. Built-in agent support covers Codex, Claude Code, Hermes, Pi, OpenClaw and DeepSeek Harness, and other agents that implement ACP (Agent Client Protocol), such as OpenCode, can connect as well. BotBus turns the computer that runs your coding agents into something you can supervise from your pocket. By discovering local agents automatically, delivering approvals and questions to your phone or watch, and encrypting content end to end, it keeps the work moving while you are away from your desk.
Markdoc is a shared Markdown editor that places the raw source and an editable rendered preview side by side in the same document, live for everyone who has it open. You can type in either surface — the Markdown source or the rich preview — and the other follows instantly, cursors included. The Product Hunt listing describes it as "a shared Markdown editor for people and their agents," which captures its two audiences: people who write and review Markdown, and the AI agents they bring into the document. Its stated purpose is straightforward: write Markdown together in real time, review with comments and suggestions, keep every version, and publish straight to a gist or a repository file. Access is free while the product is in preview, and a GitHub account is required to get started. Markdown has become a common format for documentation, notes, READMEs and repository files, but the act of writing it has largely stayed a solitary, file-based job. Files typically live in gists and repositories, and review tends to happen after the writing is done, through commits and whatever commentary travels alongside them. Markdoc's framing — "Markdown, together" — positions the editor as the place where those activities converge instead of being scattered. Rather than writing in one tool, previewing in another, discussing changes in a third and publishing from a fourth, the product brings authoring, review, versioning and publishing into a single shared document on the web. The tagline "A shared Markdown editor for people and their agents" also signals a newer kind of collaborator: software agents can take part in the same document through MCP, so human and machine editing can happen against the same live text. The first capability Markdoc highlights is its dual-surface editing model: "Two surfaces, one document." A code editor and a rich preview sit side by side, and you can type into either one. Type in the source and the rendered page updates; type in the rendered page and the source follows. The update is described as instant and includes cursors, so both surfaces stay visually in step. Because both views are driven by the same document, there is no need to switch tools to check how your Markdown will render — you see it as you write it. Real-time collaboration is layered on top: presence, live carets and selections, and conflict-free merging on both surfaces. That means multiple people can be in the same document at once, each seeing where the others are working, with concurrent edits merged rather than clobbering each other. The editor also works offline and catches up when you reconnect, so a dropped connection or a flight does not stop the writing. Review in Markdoc happens inside the document. Comments are designed to stick: threads are anchored to text, and they follow the words as the document changes, so a comment stays attached to its subject even after paragraphs move or are rewritten. Threads can be replied to, resolved, and reopened, which supports a back-and-forth review that continues over time rather than a one-off note. Alongside comments, Suggesting mode lets a collaborator propose edits as tracked changes instead of editing the text directly. Owners — the people responsible for the document — can accept or reject each proposed change individually, or accept or reject all of them at once. Together these two features cover the familiar review loop: leave a note where something needs discussion, or make a concrete proposal that someone else decides on, without either side overwriting the other's work. Version history gives the document a memory. Markdoc takes automatic snapshots while you work, so recent states are captured without anyone having to remember to save a copy. When a particular state matters, you can create a named version. Comparing versions is done with word-level diffs, and restoring is a one-click action. For storage, Markdoc is GitHub-native: you can open any Markdown file from a gist or a repository, and publishing creates a real commit on the branch you choose. In other words, the document's home remains the place the file already lives — a gist or a repo — and publishing is not a copy-paste export but a commit. The Product Hunt description adds one more route in and out of the document: you can bring your own agent over MCP, letting an assistant work with the same Markdown file alongside the people in it. The distinctive approach is that everything happens in one place, on one document, in real time. Editing, previewing, discussing and versioning are not separate stages handed off between tools; they are concurrent activities on the same live text. The two-surface design makes the source and its rendered output equal, editable views of that text, and the collaboration layer — presence, carets, conflict-free merging and offline catch-up — keeps every participant, including ones who were disconnected, on the same state. Comments anchored to text and tracked suggestions keep feedback attached to the exact words it concerns. Version snapshots and named versions record how the document evolved, while GitHub-native storage and publishing tie the working copy back to a gist or a repository through real commits. Agents participate through MCP, so they are not a separate chat window but another participant in the document. The benefits follow from that consolidation. Because the preview is always beside the source and updates as you write, you can see how your Markdown renders without leaving the editor or opening a separate preview window. Because collaboration is real time with presence and conflict-free merging, several people can work on one file at once instead of taking turns or merging changes later by hand. Because comments anchor to text and suggestions are tracked, review feedback stays attached to what it refers to and nothing is silently overwritten. Because snapshots are automatic and restore is one click, experiments are less costly and earlier states are recoverable. And because publishing is a real commit to a gist or repository, the file you wrote stays in the place your team already looks for it. Concrete workflows the content describes include writing Markdown alongside other people in the same document, with everyone's cursors and selections visible as they work. A reviewer can comment on a specific passage and hold a discussion in the thread, resolving and reopening it as needed, or switch to suggesting mode and propose edits as tracked changes that the document owner accepts or rejects. Teams can start from an existing Markdown file by opening it from a gist or a repository, work on it together in Markdoc, then publish back — creating a real commit on a chosen branch — when the document is ready. Someone can draft offline and let the editor catch up on reconnection. And a team that uses an agent can bring it into the document over MCP so it works on the same Markdown file as the people. Markdoc is aimed at anyone who writes Markdown collaboratively — the Product Hunt topics list Productivity, Writing and Developer Tools, which matches a product that appeals both to writers who care about the rendered result and to developers who treat Markdown files as part of their repositories. The stated integrations are GitHub-specific: opening files from gists and repositories, publishing as commits to a branch, and the requirement of a GitHub account to get started. Agents integrate over MCP. Pricing is free while the product is in preview. No other technology stack details are stated in the provided content. Markdoc's core promise is simple to state: Markdown, together. It puts source and preview side by side in one live document, lets people edit either surface at the same time, anchors comments and tracked suggestions to the text they concern, keeps automatic and named versions with word-level diffs and one-click restore, and publishes to a gist or repository as a real commit on the branch you choose. Agents can join over MCP. Free while in preview and requiring only a GitHub account, it offers a single shared place for writing, reviewing, versioning and shipping Markdown.
OpenSwarm is a free AI desktop for Mac where many agents work at once. Rather than giving you one assistant in one chat window, it puts a desktop in front of you on which a swarm of agents runs in parallel, each agent with its own browser, apps and tools. The stated goal is straightforward: anything you do on your computer, a swarm can do for you. You tell OpenSwarm what you want, the agents work with you at the helm, and you can watch the whole swarm on one canvas, step in when you want, and pick up the finished work. Most AI tools still give you one agent in one chat. It works on a single task while you wait, and anything bigger than that ends up back on your plate. That limitation is the problem OpenSwarm sets out to remove. When a job involves dozens of small steps - searching many pages, checking several sources, drafting a message for every name on a list - a single conversational agent cannot keep up, so the human becomes the bottleneck and the coordination work lands back on them. OpenSwarm reframes the work as orchestration instead of execution: you describe the outcome, and a swarm of agents carries out the parallel steps while you stay in control of the direction. One of the clearest demonstrations of the swarm model is parallel browsing. A single ask - the site's own example is "Best food in Berkeley" - opens six browsers at once, and each agent reads its own set of pages. Instead of one agent walking through search results one after another while you wait, six lines of research run simultaneously and their findings come back together. Agents also use your browser, your apps and connected tools, which means they can carry a task through to the end rather than stopping at advice. The site frames this as unlimited capability: whatever you would normally do on your computer, the swarm can do it for you, and it finishes the whole task instead of telling you how to do it. OpenSwarm also builds software on request. In the example shown on the site, you type "Make me an app for my daily brief" and an agent builds the tool for you; it then sits in your launcher next to the rest of your apps. That behaviour matters because it removes the gap between having an idea for a small utility and actually having it. You do not need to know how the app is put together or where it lives - you describe the tool you want in plain language, and it appears as a finished app in the same place as everything else you use. This is the sense in which the product describes apps creating themselves: the desktop grows to fit the work you ask for. On top of the desktop itself, OpenSwarm offers an agent marketplace - a set of apps that your agents use inside OpenSwarm to find leads, validate problems and more. Lead Finder is described as an app for finding your next customers with five agents. Problem Validator takes a description of a problem and sends agents to search Reddit, X, Hacker News and review sites for real people who have it, using six agents. Post Harvester asks you to paste a profile, after which three agents harvest the posts and turn them into a knowledge base you can talk to. Social Footprint Finder takes a name or a handle, and six agents find public profiles across the web. More apps are listed as coming soon: Text Agents, Call Agents and Verbal Hotkeys. The pattern behind all of these apps is the same: a big job is split so that every source or every unit of work gets its own agent. Problem Validator is the clearest illustration - it gives every source its own agent so that Reddit, X and Hacker News are searched at the same time rather than one after another. You then supervise the swarm on a single canvas, watch what each agent is doing, intervene where your judgement is needed, and collect the results when the work is finished. OpenSwarm describes itself as an AI-first operating system where agents run the whole machine - apps create themselves, browsers control themselves, and swarms of agents work together - turning your operating system into an infinite canvas and your work from doing one task at a time into orchestrating dozens in parallel. The benefits follow directly from that structure. Work that used to be serial becomes parallel, so waiting time shrinks and more of a task can be handed over instead of just the easy part. Because the agents use your browser, apps and connected tools, they can finish the whole job rather than leaving you to complete it. At the same time, you are never out of the loop: the swarm is visible on one canvas, you can step in when you want, and you pick up the finished work when it is ready. OpenSwarm summarises the outcome as being at the helm - you are no longer the person doing one task at a time, but the person orchestrating dozens. The site positions OpenSwarm as one desktop for every team and lists sales and outreach, operations, recruiting and research as the areas it is built for. The sales example is spelled out in detail: a user can ask OpenSwarm to find 50 Series A fintech startups in New York and draft a first email to each founder. The swarm finds the right people, learns what they care about, and has a first email ready for each one, with progress shown against a running total of leads. Research workflows appear in the same way - the Berkeley food question, or validating a problem across many sources at once - while recruiting and operations teams are named as the other functions that can hand repetitive, multi-step work to a swarm. OpenSwarm is a free AI desktop for Mac. The site describes it as a 100% free AI desktop, and access is being handled through a waitlist: at the time of writing the page showed 10,672 people on the waitlist, and joining requires only an email address, with early-access updates sent by email and unsubscribe available at any time. The workflows shown reference LinkedIn, Crunchbase, HubSpot and Gmail as the tools involved in the outreach example, alongside the apps agents use inside OpenSwarm. The page carries a "Backed by" link to joinef.com. Beyond the Mac desktop itself, the marketplace apps - Lead Finder, Problem Validator, Post Harvester and Social Footprint Finder - each come with a stated number of agents, and Text Agents, Call Agents and Verbal Hotkeys are marked as coming soon. OpenSwarm's proposition is easy to state and hard to do: instead of an assistant that answers in a chat while the real work stays with you, it offers a desktop where a swarm of agents works at once, each with its own browser and tools, all visible on one canvas. You keep the helm; the swarm keeps the pace. Whether you are researching a market, validating an idea, harvesting posts, finding leads or drafting outreach, the product turns a queue of small tasks into parallel work that can be finished and handed back to you - and it is free for Mac users who join the waitlist.
DevAlly is an AI-powered accessibility compliance platform built for product teams who ship quickly. Its purpose is to make a digital product accessibility conformant fast, so that teams can build products for everyone rather than treating accessibility as a one-off audit. The platform covers the accessibility lifecycle end to end — scan, identify, remediate, prove and scale — and combines automated auditing with AI that generates exact code-level fixes. DevAlly AI Agent, the product's launch on Product Hunt, extends this by letting a user describe a user journey in plain English; the agent then navigates the application and records that journey, saving hours of engineering work. DevAlly then audits each stage of the recorded journey against the WCAG criterion and suggests fixes for every issue it finds. The company positions the product for teams that need accessibility compliance without slowing down their roadmap. The context behind DevAlly is a regulatory and legal landscape that is tightening. According to figures presented on the website, a large share of websites fail basic accessibility requirements, and thousands of ADA lawsuits are filed in the United States annually. The site notes that ADA Title III exposes private businesses to civil lawsuits, with demand letters, class actions and settlements rising every year, and that settlements often exceed $50,000. At the same time, the US, the EU and the UK have each set their own accessibility requirements, and the direction is described as mandatory, enforceable and increasingly expected by the enterprise customers teams are selling to. For US federal procurement, VPATs are required, and they are increasingly expected by enterprise buyers more broadly. Because products change constantly, accessibility requires consistent monitoring rather than a single audit — which is exactly the gap the DevAlly Agent is designed to close. DevAlly organises accessibility work into five stages. The first is Scan: you sign up and run your first automated audit in under ten minutes, with no configuration required. The website states that no credit card and no accessibility expertise are needed to begin, so a team can enter its product URL and get started straight away. The second stage is Identify, where issues found by an audit are prioritised by severity and by compliance standard. The point of that prioritisation is to surface the necessary fixes first rather than the nice-to-haves, so a team working through a long list of findings knows which items actually block conformance and which can wait. Together, Scan and Identify turn an open-ended question — is our product accessible? — into a ranked, standard-based list of things to fix. The third stage, Remediate, is where DevAlly's AI generates exact code-level fixes rather than generic advice. Those fixes are integrated directly into GitHub and into a CI/CD pipeline, which means accessibility issues can be caught before they ship instead of being discovered after release. This matters because it moves accessibility into the same workflow engineering already uses for other quality checks: remediation happens where the code lives, and the pipeline becomes a gate rather than a report. The website also notes that the DevAlly MCP brings accessibility compliance into your editor, so you can ask what is failing WCAG and get the fix without leaving your workflow. The company describes this combination as accessibility that stays built in, not bolted on. The fourth stage is Prove. When procurement, legal or a customer asks about accessibility, DevAlly is designed to have the documentation ready: VPATs, compliance dashboards and accessibility statements on demand. Because VPATs are required for US federal procurement and are increasingly expected by enterprise buyers, being able to produce them quickly is a commercial concern as well as a compliance one. The fifth stage is Scale: as a product grows, DevAlly grows with it, and continuous monitoring catches regressions before users do. Continuous monitoring is the direct answer to the problem of constant change — a product that passed an audit last quarter may fail today's WCAG criteria after a release, and DevAlly's approach is to keep checking rather than to re-audit from scratch. Taken together, the platform's methodology is an end-to-end, AI-driven loop rather than a point-in-time audit. A team enters its product URL or signs up, runs an automated audit, and receives findings prioritised by severity and compliance standard. For each issue, AI generates code-level fixes that flow into GitHub and the CI/CD pipeline. Documentation for compliance and procurement is produced from the same system, and monitoring continues so that regressions are caught as the product evolves. The DevAlly AI Agent adds a natural-language layer on top of this: instead of scripting a test path, you describe a user journey in plain English, the agent navigates the app and records the journey, and the platform audits each stage of that journey against the WCAG criterion and suggests fixes for every issue it finds. The website frames the overall promise simply — DevAlly handles the auditing, the prioritisation and the documentation, and the team handles the building. The intended outcomes are that teams become accessibility conformant quickly, without needing in-house accessibility expertise and without slowing down the roadmap. Practically, that means less engineering time spent recording and replaying user journeys by hand, a short path from sign-up to first audit, and a prioritised list of fixes instead of an undifferentiated backlog of violations. It also means documentation that is ready when it is requested by procurement, legal or customers, and monitoring that keeps a product conformant as it changes. The website summarises the goal as building products for everyone, not just running audits. Concrete scenarios described in the content include a product team that wants to run a first automated audit with no configuration simply by entering its product URL; engineering teams that need AI-generated, code-level fixes wired into GitHub and their CI/CD pipeline so issues are caught before they ship; teams asked for a VPAT or an accessibility statement by procurement or a customer, who need compliance dashboards and documentation on demand; and growing products that need continuous monitoring to catch regressions introduced by new releases. The DevAlly AI Agent supports the case where a team wants to verify a full user journey — described in plain English — and have each stage of it audited against WCAG automatically. DevAlly is aimed at product teams who ship fast, and specifically at teams selling into markets where accessibility is mandatory or expected — the US, the EU and the UK — as well as organisations for which federal procurement and enterprise buyers require VPATs. The site emphasises that no accessibility expertise is needed, which suggests it is intended to be usable by teams without a dedicated accessibility specialist. Mentioned integrations and touchpoints include GitHub, CI/CD pipelines, an MCP integration for the editor, and a Chrome extension called Wendy described in the company's blog. On pricing, the website offers a free way to get started, with no credit card required, alongside a Request a Demo path for teams that want a walkthrough. The product is described as being live on Product Hunt as DevAlly AI Agent. The core value proposition is straightforward: DevAlly makes accessibility compliance something a fast-moving product team can actually keep up with. By combining automated scanning, severity-based prioritisation, AI-generated code-level fixes, on-demand compliance documentation and continuous monitoring into one end-to-end platform — and by letting a user journey be captured in natural language — it turns accessibility from a periodic, expensive audit into an ongoing part of shipping software.
Knuff is a family check-in app that makes it easy to see how the people around you are doing, even when life gets busy. It is made for families and friend groups of all ages — grandparents, parents, children, partners, neighbours, colleagues, football teams, roommates and school friends. With Knuff you create a bubble with your most important people and share quick check-ins so that everyone stays connected, wherever life takes you. The app is available for iPhone and iPad with iOS 16 or later, as well as Android smartphones. Knuff was developed to bring people closer together and give them a good feeling in everyday life, whether between grandparents, children, parents, partners or friends. Ordinarily, staying in touch means sending messages, making calls or starting a conversation, which is not always practical when schedules differ or when someone simply wants to signal that everything is fine without saying much. Knuff complements existing messengers rather than replacing them: it is not necessarily a substitute for WhatsApp or iMessage. The focus is on knowing how the people in your bubble are doing and informing you if someone has been inactive for a long time. That way, everyone stays up to date and can react if someone does not check in as usual. The heart of the app is the check-in itself, which the site describes as effortless — just tap. Inside your Bubble or in the Knuff Chat you tap the hand button, select a Knuffling, indicate how you feel and check in. No more messages and no more calls are required; once you check in, your Bubble knows you are okay. Check-ins can optionally be expanded with a range of personal touches: you can indicate whether you feel good or bad, add a personal message, upload a photo or video, take a picture directly via the camera, record a voice message, create a poll for your group, or share your current location. This keeps checking in flexible and personal, depending on how much you want to share. Knuff organises people into Bubbles, which are separate groups for family, close friends, neighbours or colleagues. Everyone in a bubble can see each other's check-in status — private, simple and reassuring. The Bubble map shows at a glance how current the check-ins of your friends are: whoever has just checked in remains outside in the green area, while a friend whose last check-in was a long time ago moves further towards the centre, towards the red area. Because each Bubble is its own separate group, your Knuff Check-Ins are shared only with the members of the Bubble where they are created, and are never shared across Bubbles. Other Bubbles do not have access to your Check-Ins, so you control who receives which check-ins by choosing the Bubble you post them in. Beyond check-ins, Knuff also includes lighter communication and customisation features. You can discuss, share pictures and upload videos, and simply stay in good contact with your loved ones, with reactions available on check-ins and member details you can open. Bubbles can be personalised with different Bubble themes, such as the "Sardegna" theme shown on the website. Knufflings are the little figures that make the check-in process more personal: you select one to accompany your check-in and make it more individual, and Knufflings can be purchased individually or given as gifts. In the Bubble Store you can specifically expand your Bubble with surveys, appointment scheduling, sharing locations or longer video clips; these functions apply to each Bubble in which they are activated and are activated for the entire Bubble, so all members can use them. Knuff takes an unusual approach to privacy and ownership, which the site presents as a key part of the product. It is built in Munich, Germany, by a small, independent team rather than a big corporation, and data stays entirely in Germany — the company does not use AWS, Google, Microsoft or other US cloud providers, storing data in its own German data centre. Knuff describes itself as a European product and, with great attention to detail, as a very good complement to US mainstream apps rather than a replacement for them. The app is also international: users can choose their favourite language from a long list that includes English, Arabic, Catalan, Czech, Danish, German, Greek, Spanish, Finnish, French, Swiss German, Hebrew, Hindi, Croatian, Hungarian, Indonesian, Italian, Japanese, Korean, Malay, Dutch, Polish, Portuguese, Romanian, Russian, Slovak, Slovenian, Swedish, Thai, Turkish, Ukrainian, Vietnamese, Simplified Chinese and Traditional Chinese. Inviting people into a Bubble is deliberately simple. Inside your Bubble you tap the plus symbol; people who are with you can simply scan the avocado to join, or you can invite other people by email, WhatsApp and similar channels. Bubbles manage themselves in a lightweight way too: a bubble is automatically deleted when the last member leaves it, and you can delete your own account by tapping the head icon in the top right of the app and then your name at the very top of the list. When a check-in is missed, the other members of the bubble are notified, which is what turns a simple tap into genuine reassurance. The benefits Knuff promises are straightforward. Busy people no longer need to send a message to let someone know they are fine, and the people who worry about them get a clear, current signal instead of silence. Family members living far away can feel closer, parents can feel reassured when a child arrives somewhere on their own, and partners who are apart can share a small glimpse of their day without needing to start a conversation. Everybody in a bubble sees the same status, so nobody is left guessing. The website illustrates concrete scenarios through a cast of example users. Margaret, 68, lives alone and is recovering from hip surgery; she values her independence and loves being able to stay connected to family life through small updates from her family. Thomas, 72, and Janet, 69, live abroad and love staying in touch with their grandchildren from afar through photos and video clips. Sophie, 45, is a busy mum of three who works from home; Knuff helps her know her children are okay and stay connected with colleagues throughout the day. Daniel, 48, is a pilot and often far from home; a quick check-in on Knuff shows his partner where he is and gives her a little glimpse into his day, without needing to send a message or start a conversation, and he can also use a dedicated bubble to let his football friends know when he is ready for a match. Olivia, 19, has just moved to a new city for university and keeps in touch with her family and roommates. Noah, 15, checks in quickly and easily when he is out with friends in the evening, with or without sharing his location. Grace, 11, has recently started going to her new school on her own, and her parents feel reassured when she quickly checks in after she arrives. Knuff is free to use: all core features are available free of charge. If you like, you can purchase additional Knufflings, Bubble designs or features in the Knuff Shop. Knuff does not offer subscriptions; instead, features are available through Passes with a fixed validity period, so there are no automatic renewals and no recurring charges. A Pass expires automatically, and you are only charged for another Pass when you explicitly confirm the purchase. You can extend a Pass at any time, even before it expires, and the additional time is added in full to your current Pass. Purchases in the Bubble Store are also one-time purchases for a certain period rather than subscriptions; they add up, so you can purchase a period multiple times and the end date adjusts accordingly. A Bubble Store Pack is activated for the entire Bubble, so once a pack is unlocked all members can use the included features, and each Bubble member can unlock a feature that benefits everyone. Packs apply only to the Bubble in which they were purchased or unlocked, although it is possible to sponsor Bubble packs in all bubbles via a separate purchase. Knuff is built for people who care. Whether the goal is letting a grandparent know you are thinking of them, reassuring a parent that a child arrived safely, or simply keeping a group of friends in light, low-effort contact, the product reduces staying in touch to a single tap. Its combination of a Bubble map, personalised check-ins, private group bubbles and a European, subscription-free pricing model makes it a reassuring companion rather than another noisy messenger.
Velozity is the Multiplayer AI Office, a workspace where your team and your AI agents work together in one place. Instead of your team chatting in one app, meeting in another, and every AI working alone, Velozity brings it all into a single window. You can walk into a cabin in Workspace or talk to your agents in AI Space, using chat, audio and video calls with transcripts, tasks, calendar and files alongside AI agents such as Claude and Codex running on the subscriptions you already pay for. It is designed for startups, teams in development, product, sales and operations, and solo users juggling several AIs. Modern teams suffer from tool fragmentation. As the Product Hunt listing describes it, your team chats in one app, meets in another, and every AI works alone, forcing people to constantly switch between tools and re-explain context. Velozity's answer is to bring communication, meetings, tasks, calendar and files into one place, and to give every agent the same shared context so work moves between people and agents without having to re-explain. User stories on the site reinforce this: one describes replacing a whole suite of tools like Slack, Zoom, Notion, Calendly and even physical office setups, and another reports 97% less tool switching. The premise is that context is expensive, and keeping people and agents on the same page saves both time and money, with no second AI bill. Velozity is organized as a virtual office rather than a flat chat app. You walk into a cabin inside Workspace, and you can drag to walk around the floor to see who and which agents are working where. Each cabin and space shows live presence, so you can see that Arjun is using VS Code, Meera is using Figma, or that agents like Atlas, Tabby and Nova are working. From any cabin you can Drop In, chat, or invite someone over. Shared rooms such as a Town Hall and a Focus Room let people join a room for meetings, and the whole experience is designed so your team works there while your agents already know what happened. Velozity bundles the communication tools a team normally pays for separately. It supports chat with reactions, reply, quote reply, forward, copy text and copy link, plus at-a-glance context indicators such as the number of Context items and Routines in a space. It also includes audio and video calls with transcription and recording: the site shows a video call with a recording timer and a live transcript capturing who said what. Presence is continuous, so you can see who is online and what they are doing, and the meeting conversation flows directly into the office's shared context rather than being trapped in a separate app. Beyond communication, Velozity includes the operational tools teams juggle every day. There is a task system with a Smart and Fast AI task mode: Smart checks your existing tasks first and can update one, mark it done or flag a duplicate while picking the assignee and project, while Fast always creates a new task and never looks at existing ones. Tasks can be typed or spoken, with a voice recorder that opens in a small window, and they support due dates and priority. A booking calendar shows a week view of standups, demo calls, design sessions and one-to-ones, and tasks appear in grouped states such as in progress, open and completed. Files and docs live inside spaces, and Guest Pass Management lets you create and manage external guest access with validity options of 7 days, 30 days, unlimited or one-time use, with a Reception where the guest waits until you let them in. Velozity's defining capability is its agents. You use the AI subscription you already pay for, with Claude Code, Codex and Grok shown, to create your agents, and your whole team can tag their own agents in the same conversation. The site demonstrates named agents such as Jack (designs interfaces), Hulky (builds and ships code), Snoop (digs up research), Kai (prototypes screens) and Monkey (writes product copy) all working inside one space. You can spawn a department and watch it run: Engineering triages bugs, opens the fix, gets it reviewed and writes the release note; Marketing plans a campaign, writes it, designs it and reports what it brought in; Sales finds leads, writes the first email and books the demo in your diary; Customer Support answers tickets, escalates real bugs and keeps the customer posted; Finance reads invoices, matches them to orders and lines up the payment run; and HR & People screens CVs, books interviews and has the offer ready. Each department runs with four agents. Crucially, nothing is sent, paid or signed without you. Agents can run on this device or on a cloud computer. A cloud computer keeps agents working 24/7: the example shows Aria answering and following up support tickets overnight while your laptop is asleep, and capturing and qualifying unlimited leads all day. Velozity also ships Speed, its built-in agent that is on your team from day one and needs no Claude Code or Codex subscription. Speed reads your sources such as email, transcripts and files; creates tasks with a priority and due date; captures tasks from transcripts and email; performs deep research that answers questions from your own data; and delivers a morning brief every day at 8 covering what is due, who is waiting and what is on your calendar. Velozity connects to 100+ integrations and pairs them with a cloud computer for legacy apps. Documented integrations include Gmail (reads and sends email), Jira (captures and tracks issues), GitHub (tracks pull requests), Google Sheets (reads and writes rows), Google Drive (finds the right document), Outlook (reads and sends email) and Google Calendar (finds a slot and books it). Where there is no integration, for example Tally, your agent simply uses the app on a cloud computer. The shared context, sometimes framed as a Company Brain, means agents can answer questions such as where the team landed on a customer's pricing by checking calls and docs. The site illustrates an end-to-end flow: a customer email arrives at 09:12, a bug is captured in Jira at 09:13, a refund is posted in Tally at 09:20 with no integration needed, a fix is merged on GitHub at 11:48 and the customer gets a reply at 11:50. The benefits described on the site are practical and measurable from user stories. Consolidating work tools is said to save $214 per user per month, deliver 97% less tool switching, produce 85% less friction in day-to-day collaboration, make team coordination 4X quicker and enable 10X smarter collaboration powered by AI. Because Velozity uses the AI subscriptions you already pay for, there is no second AI bill, and because everything happening in the office is shared context, you do not waste time switching between apps and meeting notes are ready without anyone writing them manually. Founders get complete visibility and accountability without micromanaging, and remote-first teams get a virtual office that makes distributed work feel like working side by side. Velozity suits startups and teams working in development, product, sales and operations, as well as solo users juggling several AIs. Concrete scenarios shown on the site include a support agent resolving tickets around the clock on a cloud computer, a sales agent capturing and qualifying leads throughout the day, an engineering department triaging bugs and shipping fixes and release notes, a finance agent reconciling September invoices against payouts, a hiring agent screening curator portfolios, and a social and content studio pulling the last 30 days of X and LinkedIn performance. It is free to start with no card needed, and guests can be given time-limited or unlimited passes. Ultimately, Velozity positions itself as one office for your people and your agents: calls, presence, tasks and transcripts in the same window, every agent sharing the same context, and the ability to bring your own AI subscription. For teams tired of tool fatigue and of re-explaining context to isolated AIs, the Multiplayer AI Office aims to make remote work feel like working together, side by side.
Proofsource is an AI intelligence platform that shows whether ChatGPT, Perplexity, Claude and Google AI Overviews name your brand when buyers ask category questions, who those engines name instead, which sources they cite, and what to fix. It is built for the teams that own the shortlist: growth and brand leaders, writers and search teams, agencies running many brands, and founders or small businesses. Its stated purpose is simple and direct — be the brand AI recommends. Rather than measuring blue links or ranking positions on a search results page, Proofsource measures the answer itself: whether your brand appears inside it, where it appears, and which other brands appear alongside it. Buyers now ask AI for a shortlist. An answer engine names three to five brands and moves on. If your brand is not one of them, there is no second page to rank on and no click to measure, so the loss is invisible in conventional reporting. Proofsource says most brands never see this shortlist. Its own measurement illustrates how contested the space is: across 947 citations, four engines and a scan dated 4 October 2026, 43.5% of the sources AI cited for category questions were comparison pages — listicles, alternatives and versus pages. In the same research, 387 different websites were cited across just 80 answers, meaning a brand's own site is one voice among hundreds. A separate finding reported on the site states that only 1 of 4 engines described a brand-new company correctly, with the other three answering from what they already believed. New research highlighted on the homepage notes that 0.8% of AI citations point to the brand's own website. The first feature group is visibility measurement. Proofsource asks each engine the questions your buyers ask and records whether you are named, in what position, and next to whom. It reports mention rate, share of voice and average position per engine, and every number carries a 95% confidence range, described in the product as a 95% Wilson interval, so a bad day never looks like a trend. Answers are kept in full, both as text and as a screenshot, so the evidence behind a number can be revisited. In the Tesla example shown on the site, 53 of 100 answers named Tesla overall, split as 16 of 25 on ChatGPT, 16 of 25 on Google AI Overviews, 11 of 25 on Claude and 10 of 25 on Perplexity. Second, Proofsource shows who AI names instead of you. Every brand the engines name for your questions lands on one leaderboard, ranked by answers per engine, including brands you never thought of as competitors. You can add any of them to tracking with one click, and the platform highlights the questions where each competitor beats you. The Tesla example lists Rivian at 13 answers, SunPower at 13, Ford at 10 and Enphase Energy at 9, alongside Tesla at 53. This matters because a shortlist loss is usually a competitive loss, and the leaderboard makes the set of rivals that answer engines actually consider — not the set you assume — explicit and trackable. Third, Proofsource shows the pages AI trusts in your category. Because answers are built from sources, the platform lists every page the engines cite for your questions, which of those pages mention you, and which are open to a pitch, a listing or a correction. It surfaces cited domains alongside the exact pages, the listicles that leave you out, and the pages on your own site that engines read versus the ones they skip. In the Tesla example, youtube.com was cited in 29 answers, en.wikipedia.org in 24, reddit.com in 20 and tesla.com in 17, with the platform noting whether each source names the brand, partly names it, or is the brand's own site. Fourth, Proofsource catches what AI gets wrong about you. Engines answer from what they already believe, so the platform asks about your brand by name, reads the answers, and flags wrong prices, old features and mixed-up identities, along with the source behind each claim. It reports wrong claims together with the page that caused them, runs profile checks on the sites engines lean on, and checks crawler access — whether GPTBot, ClaudeBot and PerplexityBot can read you at all. One illustrative claim check on the site shows an engine stating that plans start at a price the brand retired last year and that the free tier includes unlimited seats, flagging it as wrong on both counts, pointing to a 2024 review page as the likely source, and suggesting an update to the pricing page plus a request for the reviewer to refresh. Fifth, and central to the product, Proofsource does not stop at a score. It keeps going through a loop it describes as Know, Act, Prove, Repeat: what the engines say, why they say it, what to change, and whether the change worked. It ranks the gaps behind each lost answer by likely lift against effort, names the page or source to change, and drafts the fix from your own content for you to approve. After approval, its agents publish the change, verify that the answers have changed, and learn from every change. The workflow starts from your website and reaches first answers in minutes. You tell Proofsource your site; it reads it, works out your category and your competitors, and drafts the buyer questions worth tracking, with you approving every one. It then asks 25 questions on ChatGPT, Perplexity, Claude and Google AI Overviews, and keeps every answer with its sources and a screenshot. You receive the shortlist and the fixes: where you are named, who is named instead, which sources decided it, and the gaps worth closing first. On paid plans answers are checked every day, because AI answers shift from day to day and a weekly snapshot can miss the day a competitor enters your shortlist. The free trial runs two scans, today and tomorrow. The site links to a published methodology page describing how it measures AI answers. Proofsource is positioned for every team that owns the shortlist. Growth and brand leaders get one number for AI visibility they can defend in a board meeting, with the questions, engines and confidence range behind it. Writers and search teams get the questions they lose, the pages the engines cite instead, and drafts grounded in their own site — the site frames the shift as "search taught you to rank; this shows you how to be quoted." Agencies running many brands get unlimited brands on one account, a weekly report per client, and a roll-up of who is winning and losing across their book. Founders and small businesses use the free trial to see in minutes whether ChatGPT recommends them and then fix the one page that matters most. Engines tracked on every plan are ChatGPT, Perplexity, Claude and Google AI Overviews; the site also displays Google AI Mode, Gemini, Microsoft Copilot, Grok, DeepSeek and Meta AI logos, and the FAQ states that Grok and DeepSeek are available as add-ons on Custom plans. Pricing is free to start: 200 answers, 25 questions on every engine, top AI engines, two days, no card. After that, you choose how many questions each brand tracks, and custom plans start at $64 per brand per month, with the final price discussed on a demo call. Proofsource also publishes side-by-side comparison pages against Profound, Otterly.AI, Peec AI, Semrush, Ahrefs, Scrunch, SE Ranking, Rankscale and AthenaHQ, covering engines covered, sampling cadence, statistics, fixes and price, with sources for every claim about another product. The FAQ clarifies that Proofsource is not ProveSource, the social-proof popup tool, and explains how it differs from SEO rank tracking: rank trackers measure blue links, while answer engines write one answer and name a few brands. The takeaway Proofsource reinforces throughout its site is that the shortlist is being written right now — answer engines are deciding, question by question, which brands get named. By measuring those answers across the major engines, showing who is named instead and which sources decided it, and then drafting, publishing and verifying the fixes, Proofsource turns AI visibility from an invisible loss into a measurable, actionable loop.
Ownfeed is a tool that builds a daily social feed of posts from people who appear to need your product. You paste your product's URL, and Ownfeed reads that page to learn what the product does and who it is for. From there, it searches public posts across Reddit, X, Bluesky and Hacker News and uses AI to keep only the posts where your product helps. The result is a personal timeline of relevant posts, refreshed every day, that you scroll for about five minutes and reply to yourself. It is built for indie makers. The problem Ownfeed addresses is stated plainly on its own site: you built it, you shipped it, nobody came. Launch posts get removed by moderators. Searching for people to talk to eats your whole day. A good product exists, but no one who needs it can see it. The site shows real examples of the frustration: a maker asking how to find the first 10 users without spamming, another spending three hours on Reddit looking for people who might need their app, and another wishing for a tool that tells them when someone asks for something like their product because they keep finding those threads a week too late. Ownfeed's core observation is that the people who need your product are writing about their problem today, you just cannot see them. The product exists to close that visibility gap without keyword setup, alert inboxes or automation. Setup is deliberately minimal. You paste your product's URL, and that is the whole setup. Ownfeed reads your page to learn what the product does and who it is for, then writes about 30 search terms to find your people. Your first feed is ready in a few minutes, with posts from the last 24 hours. The site's own working view shows the process for a sample product: reading the product page and generating 30 search terms, then searching four sources at once. Discovery across sources is the second core capability. Ownfeed searches Reddit, X, Bluesky and Hacker News, and the sample feed shows example result counts per source — 9 posts from Hacker News, 11 from Bluesky, 42 from Reddit and 18 from X in that illustration. AI then picks the posts that matter, keeping only the ones where your product helps. The feed can be filtered between 'Today' and 'All relevant.' The example posts shown include freelancers asking how to chase unpaid invoices, a solo designer looking for a dead-simple invoicing app, a Bluesky post about third reminder emails, an Ask HN thread about late payments, a mention of a specific invoicing tool, and a Reddit request for an invoicing app that sends polite reminders automatically. These illustrate the kinds of posts Ownfeed surfaces and are labeled as pain points, tool requests and mentions. Reading and replying is the third step, and it is intentionally manual. You spend five minutes in your feed each morning and reply to the people you want to talk to. Ownfeed states there is no alert inbox and no keywords to set up, and that you write the replies, not an AI — which is why they land. The FAQ reinforces this: Ownfeed never posts or replies automatically, and it never touches your social accounts. You reply in your own words, as usual. Ownfeed's approach differs from keyword alerts and monitoring inboxes in a few ways the site makes explicit. Instead of you defining keywords, Ownfeed derives roughly 30 search terms automatically from your product page. Instead of delivering an inbox of alerts to triage, it delivers a daily timeline you scroll. Instead of automating outreach, it deliberately leaves the writing to you, on the stated reasoning that human-written replies are the ones that land. The whole workflow is framed as three steps — add your product, AI finds your people, scroll and reply — and as a five-minute-a-day habit. For users, the stated outcome is time saved and better-targeted conversations. Instead of spending hours hunting Reddit for people who might need your app, you get a ready feed of posts where your product helps, drawn from the last 24 hours. Instead of finding relevant threads a week too late, you see people writing about their problem the day they write it. And because you write the replies yourself, there is no automated spam risk to your account and the replies are more likely to land. The concrete use cases shown on the site are indie makers shipping a product and looking for the first users, freelancers and solo operators searching for tools, and makers replying to pain-point threads, tool recommendation requests and mentions of their product. In the sample feed, the product being monitored is an invoicing tool, and the relevant posts are freelancers with late invoices, solo designers wanting a simple invoicing app, an Etsy seller needing automatic polite reminders, and a Bluesky user mentioning they switched invoicing to that tool for automatic reminders. In general terms, Ownfeed suits anyone who wants to find and reply to public conversations where their product is the answer. Pricing starts with a $1 one-day trial that shows a day of your feed before you decide; $1 today, then $39/month starting the next day unless you cancel before then. The monthly plan is $39/month, renewing monthly and cancellable anytime from Billing in Settings. The 3-month plan is $89 every 3 months. Every plan includes one product and a daily timeline, and the 3-month plan additionally includes beta sources: LinkedIn, Threads, TikTok, Instagram, YouTube and Product Hunt, delivered in small daily amounts with no guarantees while in beta. Every option renews automatically until cancelled; prices are in USD and tax may be added at checkout. The trial, monthly and 3-month options all include Reddit, X, Bluesky and Hacker News. Ownfeed is a web product accessed through the browser. In short, Ownfeed's value proposition is visibility without automation: paste your product URL, get a daily feed of posts from people who need what you built, and spend five minutes replying in your own words.

Wabi describes itself as a new kind of messenger that gets things done. According to its website, it is a messenger that makes apps and gets things done for you and your friends, so that a conversation becomes the place where plans actually happen. The company frames the product as "the OS for the agentic era — software that adapts to your life, gets things done, and makes more room for the people and things that matter." Its messaging is aimed at groups: friends organizing a trip, people who share bills and subscriptions, students, book clubs, pet owners, dinner planners and concert-goers. The promise on the site is simple and repeated in its call to action, "Let Wabi handle your next group trip," followed by "More of what you want to do. Less of what you have to." The problem Wabi addresses is visible in the way group chats usually end up: a lot of talking, and then a lot of loose ends. The website's use-case list reads like a catalog of exactly those loose ends — group trips that still need to be organized, bills and subscriptions that quietly grow, school items, group pets, games, book clubs, dinner plans and live music. One of the example conversations on the site makes the problem concrete: Wabi tells a user that their Comcast bill went up $41 a month and asks, "Want me to try to renegotiate it?" The point is not that people need another place to type messages; it is that the things discussed in a chat typically require separate apps, separate reminders and separate effort to finish. Wabi positions itself as the layer that closes that gap between talking about something and actually doing it. The most distinctive claim in the content is that Wabi not only carries a conversation but also builds the small apps that the conversation needs. The Product Hunt description states that Wabi is "a new kind of messenger that makes apps and gets things done for you and your friends." The website illustrates this with a set of use-case tiles that recur throughout the page: Group trip, Bills & subs, School, Group pet, Games, Book club, Dinner plan and Live music. Each of these is presented together with its own icon and the label of the app or scenario it represents, suggesting that these are the kinds of lightweight, purpose-built spaces Wabi can create around a group's activity. In other words, instead of asking users to leave the chat for a dedicated planning tool, Wabi brings the tool into the conversation, where the context — who is involved, what was decided, when it happens — already exists. A second, equally prominent theme in the content is proactivity. In the "Wabi conversation" example screens shown on the site, Wabi is not waiting to be asked questions; it is reporting things it has noticed. In one thread, Wabi says: "Your flight confirmation email just landed. San Francisco (SFO) → Mexico City (MEX). Sep 30 – Oct 5." The same thread displays a flight card with departure 09:55 and arrival 14:20, a destination label reading "CDMX," a trip countdown reading "DEPARTURE ✈ 14 DAYS 08 HRS 32 MIN," and a widget labelled "Mexico City · Local recs." In another conversation, Wabi says "I've put all your upcoming live shows into one app," above a list of concerts (Turnstile Sep 25, sombr Oct 4, Disclosure Nov 12). A third example shows a Subscriptions app with a monthly total of $327.60 and Wabi's offer to renegotiate a bill. Each example follows the same pattern: an inbound piece of information is detected, organized and surfaced inside the chat with a suggested action attached to it. Wabi's shared, group-oriented side is expressed through its use-case categories. The page names Group trip, Bills & subs, School, Group pet, Games, Book club, Dinner plan and Live music, and the site's headline call to action is "Let Wabi handle your next group trip." Those labels cover both logistics — a trip with flights, a countdown and local recommendations — and recurring group life, such as dividing bills and subscriptions, coordinating school matters, tracking a shared pet, running games, choosing a book, planning a dinner, or keeping track of live music everyone wants to attend. Because these appear as reusable tiles rather than one-off screens, the implication of the content is that a group can spin up a working space for whatever activity it currently cares about, inside the same messenger the group already uses for conversation. The overall approach, as described, is to treat the messenger as an operating layer rather than a chat window. Wabi calls this "building the OS for the agentic era," and defines that software as something that "adapts to your life, gets things done, and makes more room for the people and things that matter." The examples support that framing: information arrives from the outside world — an emailed flight confirmation, a set of upcoming shows, an increase in a monthly bill — Wabi turns it into an organized in-chat object such as a trip card with a countdown, a consolidated shows app, or a subscriptions view with a monthly total, and then offers the next step, such as trying to renegotiate that bill. The "+Message" control visible in each mock conversation indicates that Wabi sits inside the normal flow of messaging, so users keep responding with plain messages rather than switching tools or learning a new interface. The benefits stated or directly shown in the content follow from that structure. The site's closing line, "More of what you want to do. Less of what you have to," summarizes the value proposition: less administrative overhead and more time for the actual point of the group, whether that is a trip, a book, a show or a dinner. Practical benefits visible in the examples include being told about a flight confirmation without hunting for it, seeing a countdown to departure, having upcoming live shows gathered in a single app, seeing subscription spending in one monthly figure, and being offered help when a bill increases. The underlying promise is that nothing important said in the chat gets lost, and that the follow-through happens alongside the conversation rather than somewhere else entirely. The content describes a wide spread of concrete situations. A group trip is the flagship example: the site explicitly invites users to "Let Wabi handle your next group trip," and the conversation mock-up walks through a San Francisco to Mexico City itinerary with flight times, a countdown to departure and local recommendations for CDMX. Bills & subs is another: a Subscriptions app showing a $327.60 monthly total, plus the example of Wabi flagging a Comcast increase of $41 a month and offering to try to renegotiate it. Live music is shown as a consolidation task, with several upcoming concerts collected into one app. The remaining named scenarios — School, Group pet, Games, Book club and Dinner plan — appear as use-case tiles describing other kinds of everyday group activities that Wabi is presented as supporting. The audience implied by the content is people who organize life in groups: friends and travel companions, households and bill-splitters, students, club and hobby organizers, pet owners and concert-goers. The meta keywords on the site list "Wabi, messenger, group chats, trip planning, everyday tasks," which matches that framing. On availability, the site provides a "Get Wabi" call to action, and its page metadata includes an apple-itunes-app identifier (app-id 6747768928), indicating a mobile app presence, alongside the web page at wabi.ai. No pricing, plan tiers, technology stack or integration details are stated in the provided content, so those specifics cannot be confirmed here. In summary, Wabi is a messenger that aims to get things done rather than just carry messages. It positions itself as an operating system for the agentic era, making apps and handling everyday tasks for you and your friends, and illustrates that idea with group trips, bills and subscriptions, live music, school, book clubs, dinner plans, group pets and games. Its stated value is straightforward: more of what you want to do, and less of what you have to.
Redlamp is a native, open-source RAW photo editor for the Mac, built from scratch in Swift and Metal for Apple Silicon. It is currently at pre-alpha version 0.2.6 and requires macOS 26. Redlamp keeps the panels, sliders and keyboard shortcuts that photographers already know from Lightroom — including panel order, slider names, ranges, defaults and single-key shortcuts — and rebuilds everything underneath as a native, GPU-first application. It is an editor rather than a catalog: it opens folders of photos and keeps edits in small sidecar files right next to the originals. It is aimed at photographers who edit on a Mac and want Lightroom's familiar workflow without a subscription and without a cloud. The application is licensed under MPL-2.0, is free with no subscription, and runs its AI features on device. Lightroom defined how millions of photographers edit, but it is a cross-platform application that does not feel at home on a Mac, and it is tied to a subscription and a cloud. Redlamp was created to keep the workflow photographers already know and rebuild everything underneath as a native, open-source application. The name comes from the darkroom safelight: a red lamp is the one light you can work by without fogging the paper. The stated idea behind the product is that you can see and shape your photo freely, and the original is never harmed. Redlamp is Mac-first: one platform-neutral engine powers the application, with the Mac editor coming first and iPad and iPhone stated to follow from the same engine. Redlamp's Develop module covers the core of a RAW editing workflow: Basic, Tone Curve, Color Mixer, Color Grading, Detail and Effects. It carries over Lightroom Classic's shortcuts as 83 actions on 87 key bindings, and adjustments can be found by name or by the words people use. The command palette, opened with ⌘K, searches every action, every Develop slider and every picker — including white balance, treatment, Base Looks, recipes, Before/After, snapshots and history — with each action's shortcut shown beside it. Choosing a slider or picker does not close the palette; it turns into that control over the photo. Pressing Return shrinks the palette to a slider bar, where the arrow keys step the value, Shift moves ten times as far, Option adjusts more finely, and typing a name and value such as 'exposure 0.7' or 'temp 5600k' sets the slider directly. Moving through a picker previews each choice on the photo before it is applied. Masking is part of the architecture rather than an afterthought. Every edit is a layer: its own adjustments plus a mask built from components that add, subtract and intersect, as in Lightroom. Linear and radial gradients are drawn and adjusted directly on the photo, with 15 local adjustments including Texture, Clarity and Dehaze, a red mask overlay and a full mask list. Masks are evaluated per pixel inside the same GPU kernel, so 16 of them cost well under a millisecond. On the colour side, the pipeline is linear and scene-referred with a proper camera white-balance model. Temperature and Tint use Robertson's method with the camera's matrix. The Color Mixer works in OKLCh so hues move the way the eye expects, colour grading offers 3-way and individual wheels with Blending and Balance, and the tone curve is available in parametric and point modes. Some looks are measured against cameras' own renderings — Standard v3 sits within ΔE 3.26 of the camera's Provia. The Detail panel handles noise and sharpening with awareness of each photo's own noise, read from the DNG or measured from the raw data when the file opens. Luminance and Color noise reduction use Lightroom's controls, sharpening is noise-aware so the photo's grain passes through untouched, and Texture, Clarity and Dehaze are available globally and inside masks. Highlight reconstruction rebuilds clipped photosites. Recipes bring presets, profiles and LUTs into one open format: 39 bundled recipes in eight groups, the ability to type in a Fujifilm-style camera recipe card exactly as it is written, camera controls such as Dynamic Range, Color Chrome and white-balance shift, and import and export of .redrecipe, .cube and HaldCLUT files. A separate Stack workspace offers one-click focus stacking: Redlamp spots a focus bracket in a folder and offers to merge it, and frames are stacked as demosaiced camera RGB before any edit, so every Develop slider still works on the result. Auto, Smooth and Detail strategies are available, along with a depth map and retouching from any frame. Redlamp's own RAW pipeline treats LibRaw purely as an unpacker. Black levels, white balance, demosaicing and colour all happen inside Redlamp, on the GPU. Bayer sensors use the Menon demosaic by directional filtering with a posteriori decision, X-Trans is supported, hot pixels are repaired before demosaicing, and row and column banding is measured in the sensor's masked optical-black margins and subtracted with the black level. DNG gain maps are applied before demosaicing, and photosites that clipped are rebuilt from their bright unclipped neighbours. The demosaiced image is cached as a full mip pyramid so every zoom level samples the right resolution. A single fused Metal kernel applies every per-pixel adjustment, frames are delivered as IOSurfaces without a copy, and rendering never waits on the main thread. Latest-wins scheduling collapses a burst of slider events to the newest one. Responsiveness is a central design goal. Interactive renders at Fit take 0.6 to 3 milliseconds on Apple Silicon, a full 26 MP frame at 1:1 renders in about 13 milliseconds, a full-resolution export render takes 45 milliseconds, and opening a raw file takes 70 to 250 milliseconds; these figures were measured on an Apple M1 Ultra with a Release build. Because rendering and the UI are strictly separated, the interface never waits on the engine, the disk or the GPU. Exports rest between tiles when the Mac runs hot, and previews take priority over exports. AI features run on device, so photos are never uploaded. Edits are saved to small sidecar files next to each photo and the original stays exactly as it was shot, which protects a photographer's archive. Photos are supported in Sony ARW, Canon CR3, Nikon NEF, Fujifilm RAF, Apple ProRAW and Pixel DNG, plus JPEG, HEIC, TIFF and PNG. Concrete workflows follow Lightroom's habits. A photographer can add folders with the plus button, ⌘O or by dropping them on the window; folders are remembered by bookmark, so a folder that is renamed or moved is followed. The filmstrip follows the disk by itself, so photos copied in, deleted, renamed or rewritten appear, leave or update in place. Focus stacks are looked for one folder at a time in the background and remembered. Before and after comparison is available in three layouts and is cached so edits never re-render it, and the histogram can be dragged across to adjust Blacks, Shadows, Exposure, Highlights or Whites. Photographers can apply a recipe, hover to preview it, then adjust its Amount, save the current edit as a recipe with a settings checklist, and import Lightroom develop presets with a report of what came across exactly, approximately or not at all. On-device AI masks include Subject, Background, People and Sky, using Apple Vision's built-in models with nothing to download, plus Objects, Depth Range, and Landscape categories such as water, vegetation, mountains, architecture, ground and snow. Models are listed in Settings with their size and licence, are removed from there too, and photos are never uploaded. Redlamp is free with no subscription, supports development through Ko-fi, and is licensed MPL-2.0, compatible with the App Store, with algorithms implemented clean-room from papers. It is built with Swift and Metal, runs on macOS 26 on Apple Silicon, and is currently a pre-alpha release, with iPad and iPhone to follow from the same engine. It is a single macOS desktop application, not a web service. Redlamp's promise is simple: Lightroom's workflow, native to your Mac, open source. It gives photographers the panels, sliders and shortcuts they already know, renders every change within a frame, keeps edits in sidecar files beside the originals and never touches the raw files themselves, and does all of it without a subscription or a cloud. For Mac photographers who want a fast, native RAW editor built in Swift and Metal, with serious colour science, GPU-first masking, one-click focus stacking and on-device AI masks, Redlamp offers an open, free alternative at the pre-alpha stage of its development.
Ana by Vertice is an autonomous negotiation agent built specifically for software purchases. Ana runs software negotiations on your behalf: it reads your requirements, builds the strategy, drafts every email and tracks every round, updating the plan the moment a vendor responds. It is built for procurement buyers and sourcing teams who want negotiation expertise applied to every purchase rather than only to the largest or most strategic deals. Ana is trained on what Vertice describes as the world's largest procurement intelligence dataset and has negotiated $500 million in spend over more than 4,000 negotiations. Ana is built by Vertice. Most teams overpay on SaaS renewals because they go into the negotiation without knowing what a competitive price actually looks like. The negotiation itself is also a chore: rounds of back-and-forth email, spreadsheets and vendor pressure that consume hours of skilled procurement time and rarely leave a clear record of why a deal was struck. As one customer quoted on the page puts it, Ana "replaces chore, not core - it's scalable, takes away the non-value-add back and forth, and frees up time to tap into commercial value you wouldn't otherwise have had time for." The product is built to deliver negotiations at scale and specializes in long tail spend, giving hours back on every renewal. Ana's core advantage is data. It is trained on the world's largest software pricing dataset, built from thousands of comparable live negotiations, with 32,000+ vendors benchmarked across every category, 2M+ vendor price points powering every negotiation, and $75bn+ of real vendor spend analysed and applied. Because it has been trained on thousands of comparable live negotiations, Ana knows how vendors price, when they concede, and what it takes to secure the best terms. Every insight Ana produces is backed by data rather than instinct. That intelligence is what allows a buyer without deep negotiating experience to benchmark a deal accurately and to know which requests are realistic. Working from that intelligence, Ana starts by analysing your deal and benchmarking it against thousands of comparable contracts across 32,000+ vendors and 2M+ price points. It then builds a negotiation strategy specific to your vendor and your requirements, drafts the outbound emails with the reasoning explained, and adapts its approach as your vendor responds. In practice this means you always know what to ask for and how to ask for it, rather than guessing. Users comment on the quality of the writing: one Global IT Sourcing Manager at a global security services company said the AI wording is very natural, and that it looks professional but also like a human wrote it. Control sits with the buyer. Ana is explicitly designed as a co-pilot, not an autopilot: it drafts every email, includes the reasoning behind it, and waits for your approval before anything is sent, and tone settings and constraints are configured upfront so Ana operates within boundaries you define. You can review, edit or ignore any recommendation before it goes anywhere, and tone, timing and escalation decisions always remain yours. Ana also tracks every round and updates the plan the moment a vendor responds. Its deal overview and analysis lets you go back and see the evidence for why a purchase was approved, which one customer described as important from an audit trail perspective. Ana's overall approach combines an aggregate procurement dataset with a human-in-the-loop workflow. It handles the data-heavy parts of negotiation - analysing the deal, benchmarking it, building the strategy and drafting the emails - while leaving judgement calls to the procurement team. Vertice states that Ana is trained on its aggregate dataset, built from years of vendor negotiations across thousands of contracts, and that your individual contract data is not shared with other customers or used to train against your interests. One customer highlighted that everything lives on the same page, rather than a tab for Gmail, another for an AI assistant and another for an Excel comparison. The reported outcomes are concrete. Procurement buyers using Ana achieve 18% savings on average, and 15 days cut from renewal cycles. Beyond headline savings, the product gives procurement teams hours back on every renewal by removing repetitive vendor back-and-forth and replacing it with a structured, evidence-backed process. Because every recommendation arrives with its reasoning attached and every step is approved by your team, those savings are achieved without giving up control of vendor relationships or the audit trail that procurement functions are expected to maintain. Ana is used wherever software is bought or renewed. Typical scenarios include negotiating a SaaS renewal where the team does not know what a competitive price looks like; benchmarking a contract against comparable deals across 32,000+ vendors and 2M+ price points before going back to a vendor; handling long tail spend, the many smaller agreements that would otherwise receive little or no negotiation attention; running multi-round negotiations in which the vendor responds and the strategy must adapt; and keeping a record of the analysis and evidence behind an approved purchase for audit purposes. Ana is aimed at procurement buyers, sourcing teams and procurement experts responsible for vendor negotiations. Named users quoted on the site include a Procurement Lead at Baringa, the APAC & EMEA Head of Strategic Sourcing at Bloomberg, a Procurement Expert at Lenqi and a Global IT Sourcing Manager at a global security services company; customer logos displayed on the page include Santander, BlackBerry, ARM, ClearScore and Factorial. The page does not publish pricing or plan details - the primary calls to action are to book a demo or get started with Ana. Ana is accessed through Vertice's website at vertice.one, where the product is described as the #1 AI agent for vendor negotiations. Ana by Vertice brings negotiation expertise to every software purchase by combining the world's largest procurement intelligence dataset with a co-pilot workflow that keeps procurement teams firmly in control. It analyses and benchmarks your deal, builds and adapts the strategy, drafts and tracks every email, and leaves approval and escalation decisions with you - delivering 18% average savings, 15 days cut from renewal cycles and hours back on every renewal.
Alkera is an agentic data platform that brings data engineering, analysis, and science into collaborative multiplayer workspaces for humans and agents. Its open-source offering, Databench by Alkera, is described as the multiplayer workspace for data science, analytics, and engineering, where teammates and agents collaborate live inside notebooks and chats. The platform is built so that users can run any cell or agent on their laptop, another computer, or a GPU node, and can launch many agents in parallel to explore ideas. Every result traces back to the data and code behind it, so the people working in a workspace can follow a number straight to its source. Alkera is aimed at data teams that want one agentic platform to cover their entire data stack, rather than moving between disconnected tools. The context Alkera addresses is a data stack where engineering, analysis, and science are the daily work of the same team, and where agents are increasingly part of that work. Alkera's positioning is to bring those disciplines together in one place: the site promises "One agentic platform. Your entire data stack." and describes data engineering, analysis, and science happening in collaborative multiplayer workspaces for humans and agents. The promotional copy for the platform frames the outcome as "bringing confidence and speed to your agentic data stack." That combination — confidence and speed — is reflected in two of the platform's stated properties: results that trace back to the data and code behind them, and the ability to run many agents in parallel rather than one at a time. Alkera also emphasizes that it works with the applications and tools teams already use, so the platform is intended to sit alongside an existing stack instead of replacing it. Collaboration is the core of the workspace. Alkera supports multiplayer notebooks and chats in which humans and agents work side by side in the same session. The company's demo shows this directly: a user named Priya asks a signals agent to chart monthly revenue by segment for the year; the agent uses notebook tools, runs the notebook file q3-revenue.alknb.py across three cells, reports that enterprise is growing fastest at roughly 5% a month and drives most of the year's growth, and the run is marked finished. Marcus then joins the same conversation and asks to split the chart by region as well. The dbt agent responds by adding a region facet to the trend chart and editing a single cell in the same q3-revenue.alknb.py notebook. Because everyone is in the same workspace, these exchanges happen live: questions, agent actions, notebook edits, and results all appear in the same thread. Notebooks and dashboards are documented as first-class features, with a feature page dedicated to them. Agents in Alkera are not limited to a single machine or a single thread of work. The Product Hunt description states that users can run any cell or agent on their laptop, on another computer, or on a GPU node, and can launch many agents in parallel to explore ideas. That flexibility matters because different pieces of data work need very different compute: a quick chart can run locally, while a large model training run needs accelerators. The website illustrates this with a pretraining example that shows an FSDP-wrapped Llama model on 8x NVIDIA B200 hardware, with a loss curve charting training progress against tokens. In the interface, agents are presented with a model and behavior configuration: the demo shows Claude Opus selected, alongside settings labeled "High" and "Ask first," with the agent's activity counted as it uses tools (for example, "Used 2 notebook tools"). Agents also work with a charting API: the demo code calls alkera.chart(revenue).line with parameters for the x axis, the summed y value, a color split by segment, a title, a tooltip, and a facet, producing a monthly revenue by segment chart with Enterprise, Mid-market, and SMB series. Traceability is a stated property of the platform: every result traces back to the data and code behind it. Alkera extends this idea in several documented ways. Column-level lineage is shown across warehouse, transformation, and analysis layers, so a field can be followed from where it is stored, through the transformation that shapes it, to the analysis that consumes it. The platform also includes a knowledge base in which each knowledge entry shows its sources and whether it is human-verified — a visible signal of provenance for the information agents and people rely on. For changes, Alkera provides sandbox environments so modifications can be tested safely before they touch production, illustrated by a self-healing pipeline demo with a page for reviewing occurrences. Together these features give the workspace a record of where numbers come from, what depends on what, and what has been checked by a person. Alkera is organized as one platform that connects to the rest of a data stack through plugins and connections. The site states that Alkera works with the applications and tools you already use, and lists connectors spanning orchestration (Airflow), transformation (dbt), analytics databases (ClickHouse, DuckDB), lakehouse (Databricks), data warehouses (Snowflake, BigQuery, Redshift), query engines (Trino), databases (PostgreSQL, MySQL, SQLite, and generic SQL), object storage (AWS S3), data ingestion (Fivetran), business intelligence (Tableau, Looker, Sigma), data analysis (Hex), observability (Datadog), code and CI/CD (GitHub), communication (Slack), issue tracking (Linear), and knowledge sources (Google Docs, Confluence, Notion). A dedicated documentation page covers available plugins. On top of those connections, the workspace supplies notebooks, dashboards, chats, agents, knowledge entries, lineage, and sandboxes. Databench, the open-source workspace, can also be hosted by the user rather than used as a hosted service. The benefits Alkera claims are confidence and speed in an agentic data stack. Confidence comes from traceability and verification: results link back to the data and code that produced them, lineage runs down to the column level, and knowledge entries indicate their sources and whether a human has verified them. Speed comes from working with agents inside the same workspace where people already collaborate: an agent can run notebook cells, produce a chart, or edit a single cell in response to a teammate's follow-up question, and a user can fan out many agents in parallel instead of waiting on one. Running cells and agents on a laptop, another computer, or a GPU node lets teams match compute to the job, and sandbox environments let them test changes safely before they go live. All of this happens in a single workspace shared by humans and agents, so the work itself stays in one place. Several concrete scenarios appear in the material. In an analytics workflow, a user asks an agent to chart monthly revenue by segment for the year; the agent runs a .alknb.py notebook, returns the chart and a short read on growth, and a second teammate asks for a regional breakdown, which the agent adds as a facet to the same chart. In a data engineering workflow, changes are tested safely in sandbox environments before being applied, and column-level lineage shows how a field moves through warehouse, transformation, and analysis, which supports understanding impact. In an engineering and research workflow, a pretraining run is executed on 8x NVIDIA B200 GPUs with a loss curve tracking progress against tokens, using code and a run display that appear alongside the rest of the workspace. In a knowledge workflow, entries capture information with their sources and human verification status. Across all of them, the same thread of notebooks, chats, and agent actions carries the work forward. Alkera is built for data teams: data scientists, analysts, and data engineers, plus the agents that work alongside them. Its connector list indicates the surrounding stack such teams already use, from Airflow and dbt to Snowflake, BigQuery, Databricks, Tableau, Looker, and Slack. The public materials mention a generous free tier and a "Start for free" call to action, along with the option to book a demo with the founders. Databench, the open-source workspace, is available on GitHub for self-hosting. Alkera also publishes documentation for its foundations and plugins, provides security, privacy policy, and terms of service pages, and can be contacted at contact@alkera.ai. Because the open-source workspace and the hosted platform are described together, teams can choose to adopt the hosted experience or run the workspace themselves. Alkera's primary value proposition is a single agentic platform for the whole data stack: data engineering, analysis, and science performed in collaborative multiplayer workspaces where humans and agents work together. It combines parallel agent execution, flexible compute from laptop to GPU node, full traceability from result back to data and code, column-level lineage, verified knowledge entries, and safe sandbox testing, while connecting to the tools teams already use. For data teams that want to move quickly with agents without losing confidence in what those agents produce, Alkera is designed to keep the work — and the evidence behind it — in one shared place.
Supademo's AI Demo Agent is an always-on agent that runs product demos for prospective buyers. According to Supademo, you deploy self-improving AI agents that run discovery, answer questions, handle objections, and showcase interactive content to drive warmer leads from day one. Rather than filling out a demo form and waiting for a sales representative, a buyer meets the agent, is asked about their role, goals, pain points, and what brought them there, and then receives a tailored experience assembled from the vendor's own interactive demos, videos, decks, pricing, case studies, and documentation. The agent is aimed at revenue teams — sales and SDR teams, solutions engineers and presales, and PLG and growth teams — that need to qualify and educate buyers at scale. It runs 24/7 across time zones and supports voice and text in more than fifty languages, so buyers can interact however they prefer, whenever they arrive. Supademo frames the problem bluntly: your demo process is losing you deals. Buyers want to see the product before they talk to sales, but today they have to fill out a form, wait for a rep, and hope the timing works — and most don't bother. A prospect who lands at 11pm sees a "Book a demo" button, and by morning has shortlisted a competitor that let them explore instantly. Meanwhile, reps repeat the same pricing, integration, and security questions every week instead of spending that time closing. Static assets such as decks, one-pagers, and case studies get skimmed and, without guided context, even great content fails to prove value. And demos are limited by capacity: the team has limited hours, but buyers have questions 24/7 across every time zone, meaning prospects slip through the cracks. Supademo positions the AI Demo Agent as the replacement for dead-end demo forms — an always-on experience that answers questions, shows the product, and guides each buyer to the next step based on what matters most to them. The experience begins with smart discovery. Supademo states that every demo starts by understanding who is on the other side: the agent asks about the buyer's role, goals, pain points, and what brought them there, then uses that context to shape the entire experience. From there, personalization happens in real time. Based on what each buyer shares, agents surface the most relevant demos, videos, decks, content, and use cases for that specific person. Supademo explicitly contrasts this with generic walkthroughs, noting that no two demo sessions are exactly the same. Crucially, the buyer is not passively watching a screen: they click through real interactive demos hands-on, take any path, jump back, skip ahead, or have the agent guide them step by step. The agent listens, answers the actual question asked, and surfaces the right proof — by voice or by text — rather than continuing a scripted monologue. Agents then score, summarize, and route buyers to the right next step. Supademo says agents identify high-intent visitors, recommend next steps, and give the sales team a full session summary with key takeaways and action items. The example summary shown on the site includes the topics discussed (team size and structure, SOC 2 and GDPR compliance needs, integration with an existing CRM, pricing for a 50-seat team, and implementation timeline), key takeaways (the buyer is evaluating two other vendors, security and compliance is the top concern, and CRM integration is needed before trial), the assets viewed (a security demo, an SOC 2 case study, a pricing page, and a CRM integration guide), and the outcome, such as a meeting booked and sent to a rep. Instead of a rep starting cold with a name and email from a form, the handoff carries a conversation summary, topics discussed, a fit score, and the assets the buyer actually viewed. Control and grounding are central to how the agent behaves. Guardrails govern how the agent handles pricing, competitors, escalation, and sensitive topics. In the configuration example on the site, Supademo shows three guardrail types: off-limits topics as a hard rule (for example, competitor pricing and internal roadmap), escalation triggers as a hard rule (enterprise security and custom contracts), and approved responses as a soft rule (pricing tiers, integrations, and compliance). The agent is trained on approved sources you choose — interactive demos, decks, pricing, case studies, and docs — and stays grounded in that content with no hallucination and no off-brand answers, evolving automatically as you add or update sources. Interaction happens through both voice and text: voice mode handles natural back-and-forth including clarifying questions, follow-ups, and objections while still surfacing interactive demos and visual proof in real time, and both modes use the same approved sources and guardrails so the experience stays consistent. The agent can also generate tailored proof experiences and lightweight visuals based on buyer context, and it can route a buyer who says they would rather talk to a human to a team member. Getting live is deliberately lightweight. Supademo describes a four-step setup: add interactive demos, decks, pricing, and case studies; guide buyers with conversation, interactive demos, and approved assets; qualify and route buyers to the right actions around the clock; and learn from every conversation automatically. The site states most teams go live in days, not weeks, and that the agent improves from real conversations rather than manual retraining. Every buyer interaction generates signal — which demos resonate, what questions come up most, where buyers drop off, and what content drives conversion — and the agent uses these patterns to surface better answers and assets over time. Supademo calls this self-improving expertise and compounding value: every interaction sharpens qualification, surfaces better proof, and improves conversion without adding headcount. A sample agent performance dashboard tracks conversations, demos surfaced, CTA conversion, and top topics such as pricing and plans, security and compliance, and integration support. The outcomes Supademo claims for buyers and sellers follow directly from that workflow. Buyers get answers and see the product instantly instead of waiting for a callback. Interactive demos are surfaced based on what the buyer actually asks, rather than being gated behind a scheduled call or a generic recording. Availability is no longer limited to rep working hours: the agent runs 24/7 across every timezone in 50+ languages. Qualification happens in real time, before the call, instead of being done manually on a 30-minute call. Content delivery is personalized — the agent surfaces the most relevant asset for that buyer's use case rather than a generic PDF or a follow-up email. On the rep side, handoff stops being a cold start: sellers receive a conversation summary, topics discussed, fit score, and assets viewed, plus a concise summary instead of a blank form fill. And intelligence is no longer trapped in individual rep notes: every conversation generates structured data covering top questions, feature interest, and conversion patterns. Supademo presents the ROI for teams that need to qualify and educate at scale in terms of fewer unqualified sales calls, a short average setup time to go live, and more buyers arriving at the "aha" moment. Concrete use cases map to three stated audiences. Sales and SDR teams use the agent to qualify inbound buyers faster and move the right accounts to a meeting or next step without waiting on rep availability. Solutions engineers and presales use it to offload repetitive technical walkthroughs while keeping the live demo focused on high-value discussion. PLG and growth teams use it to give high-intent prospects a self-serve path to understand fit and experience the product before they talk to sales. In session, the agent can run structured discovery around role, use case, and urgency; pull up the most relevant Supademos, docs, pricing, or case studies in real time; let buyers explore multiple demos in a learn-by-doing way or guide them step by step; answer pricing, integration, and security questions; and hand qualified buyers to a rep with full context attached. Supademo is explicit that the agent does not replace the sales team — it replaces the dead space before and after the sales conversation. AI SDRs chase and schedule meetings, while the AI Demo Agent qualifies and educates buyers through real product experiences, so reps spend less time on basics like pricing and integrations and more time on deal strategy and relationships. On target users and commercial details, Supademo says the product is trusted by 200,000+ top operators and 3,000+ paying organizations across companies such as Beehiiv, Lightspeed, Khan Academy, Jotform, Bullhorn, Typeform, NetApp, Turo, Siemens, and others, with quoted users in sales enablement, presales, product enablement, customer education, and instructional design roles. AI Demo Agents are a usage-based add-on available on all paid plans (Scale and up); Enterprise customers enable it through their account team. Every workspace starts with 1,500 free credits (roughly 75 demo calls) and credits never expire. On security, agents run within Supademo's SOC 2 Type II framework with AES-256 encryption at rest and TLS in transit; customer data is never used to train AI models, and third-party AI providers the agent calls don't retain or train on your data either. The Enterprise plan adds workspace governance, role-based access control, audit logs of every conversation, and approved-source grounding. The takeaway Supademo reinforces is simple: stop losing deals to slow follow-ups and gated demos. The AI Demo Agent lets buyers experience your product and self-qualify on their own terms, 24/7 and in 50+ languages, with guardrails your team controls and every conversation feeding back into a demo experience that compounds in value the longer it runs.
Rool is a full private cloud machine that brings your files, software and AI into a single workspace. Instead of being only a chat window, Rool gives you a complete machine in the cloud that holds your documents, runs software, and keeps the work and memory produced between tasks. The machine is hosted in the EU, and the AI models that run on it are self-hosted by Rool in the EU as well. Rool is built for privacy-conscious individuals, teams and creators who want to work with AI without giving up control of their content. Your workspace stays private to you and to the people you choose to invite, and you can start on a free machine without a credit card. Most mainstream AI tools ask you to trade your data for convenience. Content you upload may be used to train models, advertising may be part of the deal, and your data may sit in jurisdictions far from where you or your customers are. Rool takes a different position. The company states that it sells Rool, not your data: there are no ads, no data sales, and your files and conversations are never used to train AI models. Your data is stored in Finland, under EU law, and your Rool Machine is hosted in the EU. For individuals and teams who care about where their information lives and who can reach it, that difference is the whole point rather than a footnote. Chat is just the surface in Rool. Behind every conversation sits a full machine that holds your files, runs software and keeps your work and memory between tasks. That means a chat is not a dead end: you can start with a conversation and then build from there. The machine keeps the results of what you do and the context around them, so the next task does not begin from zero. Files, software and memory are the three pillars Rool highlights. Writing a document, working with your files, or running software all happen on the same machine, and the outputs stay there, ready for whatever you do next, rather than being scattered across separate tools that forget what happened before. Rool runs AI models on infrastructure it manages in the EU. Those self-hosted models are what you use to work on the documents, files and tasks inside your Rool Machine. Frontier AI models are included in every plan, so the free Standard tier is not limited to a cut-down model. Usage is measured in AI credits: Standard includes 240 AI credits per day, Plus includes 1,200 per day, and Pro includes 4,800 per day, with the balance refilling hourly up to a plan-specific ceiling of 1,000, 2,000 or 5,000. Keeping the models in the EU, on infrastructure Rool manages, means your workspace and the AI infrastructure that serves it sit closer together rather than across jurisdictions. Your existing tools can be connected to your Rool Machine. Rool provides built-in connectors and support for custom MCP servers, which bring external services into the workspace so you do not have to abandon the tools you already use. Connectors and MCP are listed as features of the Plus and Pro plans, and they appear alongside the custom subdomain option. Practically, this means the machine is not a sealed box: it can reach out to the services around your work and pull their capabilities into the same place where your files and memory already live. Rool describes this as bringing the tools you already use into your Rool workspace, keeping one environment instead of many disconnected ones. Privacy is not a setting in Rool; it is the shape of the product. Your machine is private to you and the people you invite, and you choose who gets access. Your files, conversations and memory stay in your own workspace. Rool states plainly that there are no ads and no data sales, and that your files and conversations are never used to train AI models. The European hosting story reinforces the same point: your Rool Machine is hosted in the EU, and the models are self-hosted in the EU too. For anyone whose work involves sensitive material, such as client documents, internal notes or personal writing, having a workspace that is not mined for advertising or model training removes a recurring source of hesitation. The overall approach is to give one person or a team a single persistent machine rather than a collection of disconnected chat sessions. You start with a chat, and the chat is how you get going, but everything it touches lands on the machine: the documents you write, the files you work with, the software you run, and the memory that carries context forward. Rool calls the memory system Object Memory, and full Object Memory is included in the free Standard plan. Because the machine keeps working state between tasks, you do not have to re-establish context every time you come back. Because the models run on Rool's own EU infrastructure, the AI is part of the same environment as your files instead of a separate service consuming them. The benefit is continuity with control. Work you do in Rool does not evaporate when a conversation ends; the results and the context stay on your machine, ready for the next task. You keep your files, conversations and memory in your own workspace and decide who else can see them. There are no ads and no data sales to work around, and your content is not used to train AI models, so you can bring real work into the tool rather than sanitised versions of it. EU hosting and EU self-hosted models give you a clearer answer when someone asks where the data lives. And because every machine starts free, with no credit card and no trial clock, the cost of trying that approach is zero. Rool fits workflows where a person or a small team needs to work across files and tasks with AI in the loop. Writing a document, working with existing files, or running software are the activities Rool names directly, with the machine keeping the results and context ready for what comes next. Teams can invite the people they work with and control who has access to the workspace. Creators get a place to keep ideas, files and AI work together instead of spread across unrelated apps. Anyone who needs to connect external services can do so through connectors or a custom MCP server and then work with those tools from inside the same machine. The pattern in every case is the same: start a chat, do the work, and let the machine hold onto it. Rool is available on the web and as mobile apps for iOS and Android, with download badges for the App Store and Google Play. Pricing is freemium. Standard is free forever: 240 AI credits per day, 2 Rool Machines, 1 GB of storage per Machine, a balance that refills hourly up to 1,000, full Object Memory and frontier AI models included. Plus costs €9 per month and multiplies the daily credits five times to 1,200, with 2 GB of storage per Machine, a refill ceiling of 2,000, faster hourly refills, a custom subdomain, and connectors/MCP. Pro costs €25 per month, twenty times the Standard credits at 4,800 per day, 5 Rool Machines, 10 GB of storage per Machine, a refill ceiling of 5,000, priority support from the Rool team, plus everything in Plus. Rool's proposition is simple to state: a full private AI machine with files, software and persistent memory, hosted in the EU, running models that Rool self-hosts in the EU, under a policy of no ads, no data sales and no training on your content. It takes the convenience of chatting with AI and attaches it to something that lasts, a machine that keeps your work and its context between tasks. For privacy-conscious individuals, teams and creators who want AI they can trust with real work, Rool offers a workspace you control, on your terms, and free to start.
ruOS is a private cloud desktop with an AI team built in. It is designed for people who want an agentic workspace where AI does the work for them — research, writing, and code — without installing anything. You sign up, ruOS sets up your own private desktop, and you open it from any web browser on a Mac, iPad, Chromebook, or Linux laptop. A free option, ruOS Lite, runs a real Chrome browser drawn as your ruOS desktop right in your web page, and opens in about a second with no sign-up required. Most AI tools today live in a single chat window. You ask a question, you get an answer, and then you copy that answer somewhere else to actually finish the work. Your context, your files, and whatever the AI learned are scattered across tabs, apps, and devices. ruOS starts from a different premise: instead of a chat box you visit, you get a desktop that runs itself, with AI helpers already installed, signed in, and working side by side. Nothing has to be configured, and nothing has to be synced, because the desktop and everything on it live in one place that you reach from any browser. Everything is ready the moment you sign in. ruOS ships with smart AI helpers built in that write and run code, research on the web, remember your projects, and understand what is on your screen — all working together from day one. Claude Code is ready to write and run code for you. ruflo is a team of AI helpers. ruvector remembers your work, giving your agents long-term, self-learning memory. ruview understands your screen. Codex is available as extra coding help, and VS Code is the code editor. Because the helpers are preinstalled and signed in, the AI stack is ready as soon as your desktop starts — you do not have to wire up models or connections yourself. ruOS opens in any web browser, so there is nothing to install. The same session reshapes to any screen: sharp on a big monitor and comfortable on a tablet, with no fiddling with zoom. You can start on a laptop and keep going on an iPad, because your whole desktop goes with you. ruOS Lite goes further in simplicity — it draws a real Chrome browser as your ruOS desktop inside your web page, with tabs and windows, a dock of apps, and the ruOS app first. It opens in about a second, and it picks up where you left off: sign-ins, site data, and open tabs are saved and encrypted. Persistence is built in. Your files and everything the AI has learned are saved automatically, so you can come back tomorrow and pick up right where you left off — even from a different device. The desktop is yours and private: your files, your work, and your AI are kept separate and private from everyone else's. In ruOS Lite, VS Code and extensions are available too — vscode.dev sits in the dock, along with 1Password, Bitwarden, Claude, and uBlock Origin Lite when you turn them on. Your AI can drive it: ChatGPT and Claude see and click the desktop through the ruOS connector, never your extensions, and payments wait for you. The workflow is four simple steps. First you sign up: enter your email and ruOS sets up your own private agentic desktop, bound to your account, with no setup and nothing to configure — it is ready in minutes. Second, your desktop turns on: a private desktop starts up in seconds with the whole AI stack preinstalled and signed in, including Claude Code, a team of helpers, and self-learning memory. Third, the AI gets to work: ask for something and it is done, with a whole team of AI helpers researching, writing, and coding side by side while you watch — or step away and come back to finished work. Fourth, you open it anywhere: your desktop streams to any web browser and reshapes to the screen, the same session on your Mac, iPad, or laptop, with nothing to install and nothing to sync. Once you are in, the things you can ask for are simple. It writes and runs code: tell it what you want changed, and it edits the files, runs the tests, and tells you when it is done. It works as a team: it splits a big job across several AI helpers that work side by side. It remembers: it keeps track of what you are working on, so you never explain twice. It researches: ask a question and it browses the web, reads the sources, and brings back the answer. And it goes with you: your whole desktop travels with you, so you can start on your laptop and keep going on your iPad. Hand ruOS a task and it picks the right tool and gets to work. The outcome for users is fewer hand-offs and less copying between tools. Because the AI helpers run on the same desktop where your files live, research, writing, and code happen in one place rather than across scattered apps. Because memory persists, you do not repeat yourself or rebuild context each session. Because the desktop is private and per-account, your files, work, and AI stay separate from everyone else's. And because everything opens in a browser, switching devices does not mean setting anything up again. For developers and power users, ruOS is also a build platform. Under the hood it is a real Linux box with the full ruvnet stack and programmatic control, and everything is already installed on your desktop. ruOS runs an MCP server — ruos-computeruse-mcp — so an AI client like Claude can drive the desktop for real: see the screen, move the mouse and type, run shell commands, trigger system actions, and change the resolution on the fly. The exposed tools include screenshot, mouse_move / left_click, type_text / key (xdotool), run_shell, system_action, and desktop_resolution. You can point an MCP client at your desktop using stdio over SSH, and after launch you can resize with desktop_resolution presets of 720p, 1080p, 1440p, or qxga, or a custom width × height, applied server-side via xrandr. A hosted MCP endpoint is on the roadmap. The ruvnet stack is one command away, all preinstalled. Open a terminal on your desktop and use the same commands the AI helpers run for you: npx ruflo@latest init wizard to set up agent-swarm orchestration, npx ruflo@latest swarm init --topology hierarchical to spin up a team of AI agents, npx ruvector to give your agents long-term, self-learning memory, and npx ruflo to run the ruflo agent runtime. For quick start, ruOS provides an MCP address at https://ruos.cognitum.one/mcp. In ChatGPT you go to Settings → Apps & Connectors → Create, paste the address, and sign in. In Claude you go to Settings → Connectors → Add custom connector, paste the address, and sign in. In Claude Code you run claude mcp add --transport http ruos https://ruos.cognitum.one/mcp. ruOS in ChatGPT uses only the desktops and metered entitlements already assigned to your account. The ChatGPT app and its linked review surfaces do not present pricing, checkout, subscriptions, upgrades, or credit purchases. Getting started is straightforward: you can try ruOS Lite free in seconds with no sign-up, or get early access by signing up, after which your desktop is ready a few minutes later. ruOS takes the idea of an AI assistant and turns it into a place you work. It is a browser-reachable, private, agentic desktop where a team of AI helpers — Claude Code, ruflo, ruvector, ruview, and Codex — researches, writes, and codes alongside you, remembers your projects, and follows you from device to device. Nothing to install, nothing to sync, and nothing to configure: sign up once and the desktop does the rest.

Scumble is a free, open-source desktop editor built specifically for AI inpainting. Rather than assembling a mask in one tool, running a generation workflow in another and then pulling the result back into an image editor, Scumble keeps the whole loop in a single application: you select part of a picture, say what belongs there, and the result lands as its own colour-matched layer. The original image is never touched, so the edit stays non-destructive. Scumble is aimed at people who inpaint regularly — swapping an object out, removing something unwanted, or adding something new to an existing picture — and who prefer to run the generation step themselves, either through their own ComfyUI installation or through their own provider API keys. It is an editor, not a service. The product began as a weekend project, and the maker's own reason for building it is the problem it solves. Doing a lot of inpainting meant repeating the same routine over and over: build a mask here, run a workflow there, pull everything back into an image editor, fix the edges, and repeat. Each hop between tools costs time and breaks concentration, and the final edge-fixing step is the part that decides whether an edit looks believable. Scumble was built to remove those hops by putting selection, generation and layer-based compositing in one place, so the edit you describe is the edit you get, already sitting on its own layer next to the original picture. Scumble gives you three ways to define what should change: you can select by painting a mask, by pointing at an object, or by typing what it is. Whichever route you take, every result comes back as its own layer that is colour-matched to its surroundings. That colour matching is deliberate: it means a new object, a removed sign or a replaced detail blends into the existing image instead of sitting on top of it with a visible seam. Because the result is a layer, the original stays untouched underneath and you can adjust or discard the edit without redoing the whole image. Community reaction to this approach noted that the layer-based style makes AI edits feel more like normal photo editing rather than a full regeneration of the picture. Scumble does not ship its own image model. Instead it runs on your own ComfyUI — local, remote or Comfy Cloud — or on your own API keys for services including FLUX 3, FLUX.2, GPT Image, Nano Banana, Seedream, Qwen and Ideogram, with the promise of more. That means the choice of model and the cost of generation stay with you: you pay the providers directly and Scumble takes no cut. The project is honest about its maturity on this front — it is at version 0.1.x and moving fast, and not every API provider has been tested live yet, so support for a given provider may still be rough. The API path is built with privacy in mind. Through an API, only the area around your selection leaves your machine, and the answer comes back at full resolution. Your original image is not uploaded wholesale, and what comes back is not a downscaled preview that you then have to upscale yourself. Scumble also keeps no account, sends no telemetry, and stores your API keys in the system's credential store rather than inside the app. Combined with the fact that you supply your own keys and pay providers directly, the result is an editing tool that does not sit in the middle of your data or your billing. Two prompt-level features give you more control over what the model produces. With boxes in the prompt you can draw where things go and describe each box — for example placing an object in a specific part of the frame and describing it there — a capability listed as working with FLUX 3 Image and Ideogram 4. Reference images can also be named inside a prompt, so a request such as "put their cup from @img1 on the sill" pulls a specific existing image into the edit. Together these let you direct an edit spatially and keep particular objects consistent between generations instead of describing everything from scratch in words. Scumble also exposes an MCP server with 105 tools, which means Claude Code or any other MCP client can drive the editor directly. For people who work with AI agents, that turns Scumble into something that can be operated programmatically: an assistant can select an area, request an inpaint and receive the result as a layer without a human dragging a mask each time. It is the same inpainting engine, exposed to the tooling that agents already speak, rather than a separate product bolted on the side. For finishing work, Scumble includes 46 film looks that apply as layers, a set of retouch tools, and export to PSD, ORA and TIFF. It handles pictures of 15,000 pixels and more. The export formats matter because they let an AI edit be finished elsewhere: as one commenter put it, if an AI edit is almost right it is useful to be able to complete it in another editor instead of generating again. Film looks as layers and retouch tools mean the generated result can be graded and cleaned up inside Scumble, keeping the last step of the workflow in the same place as the first. Scumble is free and open source under GPL-3.0. Windows comes first: it is available in the Microsoft Store, signed by Microsoft, and there is also a GitHub installer and a portable zip. Linux builds come out of CI, though the maker notes he has not run them himself yet, and a Mac version is planned. The project is at version 0.1.x and changing quickly, so features and provider support are still moving. Tutorials are published under the title "two sceptics, one editor" at denrakeiw.com/scumble/videos. One workflow question that comes up is how Scumble copes with larger selections or edits where the surrounding lighting and shadows need to change along with the new object. The maker's answer is candid: the AI only sees the area being edited and does not really understand what the surrounding area looks like. The new FLUX 3 model can edit areas up to 4K, which already makes the selection pretty large, and the suggested workflow is to first inpaint a larger area with FLUX 3 and then refine the details. That ordering — broad pass first, detail pass second — is a practical way to work within how inpainting models actually see an image. In short, Scumble takes the repetitive, multi-tool inpainting routine and collapses it into one free desktop editor: select by painting, pointing or typing, describe what belongs there, and receive a colour-matched layer while your original stays untouched. It runs on your own ComfyUI or your own API keys, keeps only the area around your selection away from your machine when using an API, stores keys in the system credential store and charges nothing on top of what providers charge you. With an MCP server, box prompts, named reference images, film looks and PSD/ORA/TIFF export, it is an open-source option for people who want control of the model and the data.
Doco is an expressive companion for focus, music and everyday moments, available as an Android app with an optional Windows desktop client that lets Doco visit your computer. Described by its makers as "a little company for your day", Doco is not a conventional productivity timer or a bare music player: it is a small animated character that keeps you company while you work, listen or step away. It arrives fully animated with zero setup, so there is nothing to configure before it starts sitting beside your day. Doco switches between a playful, warm Everyday mode and a calmer Focus mode, and its music plays through a Spotify connection so that the soundtrack fits the moment rather than fighting it. The context for Doco is the texture of ordinary days: endless scrolling, tasks that compete for attention, slow mornings that need an easier start, and long stretches where a little company goes a long way. The website presents these moments directly, pairing scenarios such as "One task. A little less scrolling." with "A little company goes a long way." Focus mode is framed as the setting that cuts the noise, bringing "a little less distraction—and a little more friendly sarcasm", while Everyday mode stays playful and warm. Instead of another dashboard of metrics to check, Doco responds with tone, expression and music, which is what makes it a companion rather than a tracker. It is built for people who want something friendly in the room while they get on with their day, not another system demanding input. The heart of the product is its two modes. Everyday mode is the lighter, warmer register: Doco is playful, animated and companionable, offering small prompts and expressions that feel like a friendly presence nearby. Focus mode is deliberately quieter — less distraction, fewer interruptions, and a slightly sharper, friendly sarcasm that acknowledges the seriousness of getting something done. The layout supports both portrait and landscape, and the interface is built around character animation, including a thought cloud and small interactive moments such as the "Make a leap" prompt and the line "My thoughts found a window seat." A rotating quote appears as part of the experience — the site shows one from Epicurus about friendship — reinforcing the idea that Doco is there for company as much as for utility. Music is the second pillar. You connect Spotify to play music inside Doco, and song selection "stays close to your listening history, with room for something new." That balance matters: the app leans on the taste it already knows you have, but deliberately leaves space for discovery rather than looping the same familiar tracks forever. The player is presented as part of the companion experience rather than a separate utility, showing cover art, track and artist (the site's example is "God's Plan" by Drake), a progress bar with elapsed and remaining time, and straightforward skip back, play and skip forward controls. The "Music time" scenario sums the intent up: "Familiar favourites. Something new." Doco describes itself as a BYOK — bring your own key — powered companion, and that is because its more advanced expressive behaviours are optional and opt-in. The FAQ is explicit: you do not need a Gemini key, because "Doco has expressions and prompts without one." Adding your own Gemini API key unlocks two additional capabilities: camera-based reactions and AI captions. Because the key is your own, the generative layer is something you choose to switch on rather than a mandatory part of the experience, and the base companion works fully without it. This keeps the core product simple for people who just want the animated companion, while giving people who want more expressive, generative behaviour a way to enable it on their own terms. Doco can also travel. An optional Windows desktop client lets the companion visit your computer. The setup described is simple and account-based: install the Windows client, sign in with the same Google account, and enable visits on both devices. Once that is done, the companion can appear on your desktop as well as your phone, so the same character and the same company follow you between the places you spend your day. The desktop client is framed as a "visitor" rather than a replacement for the mobile experience, which fits the product's overall tone of lightweight, voluntary presence. Taken together, Doco's approach is to keep everything in one small, animated presence. There is no lengthy onboarding — the app is "fully animated right out of the box with zero setup" — and no requirement to configure AI or music before using it. You pick a mode that matches your moment, optionally connect Spotify so the music matches your taste, optionally add a Gemini key if you want camera-based reactions and AI captions, and optionally let Doco visit your Windows machine. Doco is pre-launch; the site currently offers an email waitlist, and joining means agreeing to receive Doco launch updates. A short FAQ on the site answers the practical questions about what Doco is, whether a Gemini key is needed, what changes in Focus mode, how the music works and whether Doco can visit your computer. The promised benefits are deliberately modest and human. Focus mode gives you fewer distractions and a little more room to concentrate on one task. Everyday mode gives you warmth — something friendly sitting with you rather than another notification. The Spotify connection means your soundtrack adapts to the moment instead of being an unrelated background app, and the selection logic keeps familiar favourites close while leaving room for something new. The desktop visit extends that company to the computer where many people do their longest stretches of work. And the BYOK design keeps the AI layer optional, so nobody has to hand over a key to get the core experience. The site names five situations Doco is made for. Deep work is framed as "One task. A little less scrolling." Slow mornings are about easing in and finding your rhythm. Music time is for familiar favourites and something new. Long days are the moments where "a little company goes a long way." Screen breaks are the prompt to "Stretch. Sip. Come back." Together these describe a single companion used across the whole shape of a day rather than a tool you open for one narrow task. In terms of audience and setup, Doco is aimed at people who want a light, expressive presence during focus sessions, music listening and everyday moments, and who prefer something animated and friendly over a clinical productivity dashboard. The explicitly stated integrations are Spotify for music, an optional Gemini API key for camera-based reactions and AI captions, and Google account sign-in for connecting the Android app with the Windows desktop client. The product runs as an Android companion with an optional Windows desktop visitor. No pricing details are published; Doco is pre-launch and access is currently through the email waitlist on the website. Doco's takeaway is simple: it is a companion first. It blends two moods — playful Everyday and focused calm — with Spotify-powered music that fits, optional Gemini-powered reactions and captions, and cross-device visits, all delivered as a fully animated character with zero setup. For anyone who wants a little company during deep work, slow mornings, long days or screen breaks, Doco's promise is that good company and music that fits can make an ordinary day feel less solitary.
AUDR (Agent Usage Detail Record) is an open standard for recording who initiated your agent runs and how much each cost, across every system a run passes through. It defines a common JSON schema that any harness, router, or billing system can emit and ingest. The goal is to help businesses make sense of the economics at the run level, giving every team building or monetizing agents a reliable record of what an agent run consumed and who or what it was associated with. It was drafted at Chargebee and is being improved with collaboration across the ecosystem, stewarded by Chargebee under the Apache 2.0 license. The problem AUDR addresses is that a run can be fully observable at every individual layer and still leave you without a single end-to-end record of who ran it and what it cost. A single agent run touches multiple systems: the application knows the customer and the feature, the router knows the tokens and the cost, and the tools know what they executed. Without a shared way to join these, usage data is orphaned from the business context that gives it meaning. The telecom industry solved a similar problem with the Call Detail Record, an open standard carriers converged on so a call's attributes could be captured and exchanged in a common format, independent of any single carrier's systems. AUDR is built on the same principle: a common record for agent runs that any harness, router, or billing system can emit and ingest. AUDR adds three core rules that let reports from different layers come together into one record. The first is a shared run ID, minted by the harness, passed to the router in request metadata, and echoed back, so every system that touches the run carries the same ID. The second is clear authority per field: the harness owns attribution such as customer, environment, and initiator, while the router owns usage such as tokens and provider. Each fact has exactly one source. This ensures that a record can carry raw counts that drive cost—tokens, tool calls, seconds of compute—alongside the business context that says whose cost it is. The record structure includes a run block with run ID and span ID, an attribution block sourced from the harness, a usage block sourced from the router, and an emitter block that identifies the component that produced the record. The third rule is strict merge rules. The sink assembles records sharing a run and span ID, and no component rewrites another's block. Conflicts are rejected, and a correction is a new record, never a mutation. This makes the record durable and reliable, and ensures that retries remain idempotent. The example in the spec shows a run with a run ID minted by the harness, attribution sourced from the harness, usage sourced from the router, and the emitter identified as the router. Because each field has exactly one authoritative source, the merged record is consistent and auditable, and any correction is preserved as a new record rather than silently overwriting history. AUDR provides adapters for runtimes you already use, so you can register an adapter and get a usage record for every model and tool call, including the customer it belongs to. Available adapters include NVIDIA NeMo Relay, LiteLLM, Merge Gateway, Vercel AI SDK, and Mastra. The core SDK builds, validates, and delivers records straight from your own code, with Python and TypeScript packages. Sinks deliver records to destinations you already use: Chargebee and Lago for usage-based billing. Adapters read identifiers, usage, and timings, never prompts or outputs. Every package is Apache 2.0 and published to PyPI or npm. The architecture is runtime → adapter → core client → sink → destination. Support for OpenRouter is in development. You can write records to a local file to start, with no account, hosted backend, or pricing configuration needed. AUDR is designed to sit on top of OpenTelemetry, not compete with it. OTel's GenAI semantic conventions provide the foundation for describing model calls and usage, and AUDR reuses them. An AUDR record can be emitted as an OTel span, and the OTel collector is a first-class sink. What OTel does not define is the set of rules needed when usage becomes a durable record: which attributes are required, how attribution is handled when it's missing, how retries remain idempotent, or how corrections are made. Observability can tolerate a dropped span, but a usage record cannot. AUDR adds those requirements and delivery semantics on top of OTel. It also complements standards like FOCUS, which standardizes billing data received from providers; AUDR standardizes the usage emitted when an agent run happens, before that usage is priced. The benefits are practical. With AUDR, you can answer questions like: How much does this agentic feature cost? What does this customer's agent usage look like, and how much does it cost? What are the unit economics and margins per customer for my agentic features? Which workflows or models are driving our costs? Which power users are driving our costs? Because records are emitted asynchronously and out of band, recording usage adds no synchronous work to inference in the normal request path. The only exception is optional pre-flight budget gating, which makes a single check before a run starts. You can store records locally, send them to a warehouse, feed them into an observability system, or use them for internal cost analysis or future projections. Use cases include usage-based billing, where records are delivered to a Chargebee site's usage-ingest batch endpoint or Lago's batch event endpoint. Teams can also use AUDR for internal cost analysis, to understand unit economics and margins, to identify which workflows or models drive costs, and to track power users. It supports cost governance by providing a common record that any system can emit and ingest. You can write records to a local file to start, with no account, hosted backend, or pricing configuration needed. For observability, the OTel collector acts as a first-class sink, and records can be used for future projections. AUDR is aimed at teams building or monetizing agents, developers, platform engineers, and billing teams. It does not assume what you do with the data after it is emitted; a billing system is just one possible consumer. It carries no prices or rating logic, and the SDK has no concept of plans, invoices, or how a customer should be charged. It records what happened and who it happened for. You can point the records at Chargebee, a competing rating engine, your own, or a warehouse for analytics. The spec is Apache 2.0, stewarded by Chargebee, and the goal is to move cost governance to an independent foundation as adoption grows. Contact is audr@chargebee.com. The three core rules are stable and will not change without a major version, while the field set will continue to grow as providers introduce new things to measure. In summary, AUDR is an open standard that provides a common language for recording agent run usage and cost across every system a run passes through. By combining a shared run ID, clear field ownership, and strict merge rules, it turns orphaned usage data into a durable, end-to-end record that supports cost analysis, usage-based billing, and agent unit economics. It is open, neutral, and community-owned, with packages published under Apache 2.0.
Incredible is an AI that does tasks on your computer. It is a desktop app for macOS and Windows that clicks and types in your browser, in files, and in apps, exactly like you do, so the busywork gets done while you do something else. You give Incredible a task, and Incredible does the work on your computer, in the same places you would. The company describes the product as "vibe computing" and as an AI you control with your voice, built for anyone who spends their day inside a browser, a set of business apps, and a folder of files. The problem Incredible addresses is simple to state and hard to solve. A chatbot writes the answer, but you still have to put it into each app yourself; Incredible puts it there for you. The repetitive parts of knowledge work — clicking through pages, reading reviews, copying numbers between a PDF and a spreadsheet, filling in forms, drafting and sending the same email again and again — still land on a person. Incredible is built to get that repetitive work done faster. The site illustrates the difference with a comparison across repetitive workflows: 1x on your own, 2x with a chatbot, and 14x with Incredible, measured on select repetitive workflows across multiple domains, with results varying by task. Product Hunt lists the product under Productivity, Artificial Intelligence and Menu Bar Apps. Incredible is driven by voice and by what is on your screen. Hold the activation key and say what you need in your own words; you can also type the task instead. When you activate Incredible, Incredible can see the page or document in front of you, so you can say "reply to this" without explaining which email you mean. That awareness is paired with the material already sitting on your machine: Incredible works from what is already on your computer, using your files and the page in front of you as context, so you can give a task without explaining everything first. The app lives up in the menu bar — "Hey! I'm Incredible. I live up here" — with a small set of keyboard commands shown in the interface: fn to talk, Alt+C to add files, Alt+X to capture text, a screenshot command, up and down arrows for history, esc to close, and Enter to send. Apps, browser and files are where the actual work happens. Incredible opens the apps you already use and moves information between them, so you no longer copy and paste from one app to the next. It sends the emails and fills in the forms for you, then tells you when the task is done. In the browser, Incredible uses websites the way you do, clicking through pages and filling in forms on sites you are already signed in to. In your files, Incredible can read and update the spreadsheets and documents on your computer, so you stop copying numbers between them by hand. The site's example shows a proposal PDF, a model spreadsheet with a total updated, a brief document and a deck with slides added, alongside counters such as 12 calls logged and 12 follow-ups booked. More than 3,000 apps connect to Incredible directly, and any other app you can open in your browser works too. Apps named on the site include Gmail, Slack, Notion, LinkedIn, Google Drive, Google Sheets, Google Calendar, HubSpot, Zoom, Microsoft Teams, Salesforce, GitHub, Figma, WhatsApp, Outlook, Excel, Google Docs, Discord, Telegram, Shopify, Trello, Chrome, Jira, Dropbox, iMessage, Airtable, PayPal, X, Google Meet, Zendesk, Confluence, Snowflake, Sentry, QuickBooks, Xero, Zoho, Sage, Odoo, Linear, Vercel, SharePoint and PostgreSQL. Three further controls round out the experience. Reminders let you tell Incredible what needs your attention and when; Incredible reminds you at that time, with the details you gave attached to the reminder. Control means Incredible asks you before anything is sent — you can approve the step or change it first, and you can stop Incredible at any time. Privacy is explicit: Incredible only looks at your screen after you activate Incredible, and the rest of the time your screen stays private. Together these settings keep a person in the loop over anything that leaves the machine. The overall approach is to work inside the tools rather than beside them. Incredible does work for you directly inside your apps, in the same places you would work, rather than producing an answer in a separate chat window that you then have to move into each system yourself. Because it acts on the page, the document and the application in front of it, it can carry a task through several steps and several apps — reading something in one place, clicking or typing in another, filing the result somewhere else, and reporting back when the task is finished. That is why the same assistant can handle a spreadsheet update, a form submission and a reminder without the user rebuilding the workflow by hand each time. The stated outcome is leverage rather than replacement. CellMark, a customer that uses Incredible in its offices in Sweden, France and the United States, describes the effect this way: "It's not about taking the work away from me. It's about boosting me. We are seeing higher accuracy and better results across the board," says Håkan Enhager, VP Global IT & Digital at CellMark. The site frames the benefit as handing over routine work, so the person keeps the judgment while the busywork gets done. The result is fewer manual handoffs between apps, less copying and pasting, and work that continues while you turn your attention elsewhere. Concrete workflows are laid out by role. For sales, Incredible finds and reaches out to prospects — the example task is finding 50 VP of Product at fintech SMEs with personal intros, reading profiles, adding contacts and sending personalized emails — while researching prospects and keeping the CRM up to date work the same way. For marketers, it reads 100 G2 reviews of a competitor, pulls out what users complain about, tags the complaints and writes the summary, and the site notes it can also research competitors and turn the findings into content. For recruiters, it screens a folder of 200 resumes against the role being hired for, scores candidates, builds a ranked shortlist with reasons, and drafts replies to the people picked. For operations, it finds every receipt in an inbox for the month, renames and organizes the files and logs the amounts, and it files invoices the same way every month. For founders, it finds the speakers at a conference, sends requests and dinner invitations, and follows up with everyone met at an event. For everyone, it turns a long email thread into a meeting with all attendees included — reading the emails, finding a slot for all six, and posting the invite in Slack. Incredible is aimed at people and teams who work across a browser, standard business apps and local files, and who have routine tasks they repeat. The company markets a downloadable desktop app for Mac and Windows — "Download for Mac", "Download for Windows", "Try for free", "Get started" and "Book a demo" — and Product Hunt lists it as a Menu Bar App. Security and privacy documentation is published in a Trust Center: SOC 2 Type 2 audited by Sensiba, GDPR compliant, data encrypted at rest and in transit, and no training on your data. The site also lists protection against malicious code, confidentiality agreements with staff and partners, feedback on every response, and a dashboard of your team's usage, plus support from a dedicated success team, priority support with an SLA, guidance on setting up your first tasks, and onboarding for your whole team. Incredible announced a $2.7M pre-seed round. Incredible's proposition is narrow and practical: it is an AI that does tasks on your computer, clicking and typing in the browser, apps and files you already use. You speak or type a task, it works in the same places you would, it asks before anything is sent, and it tells you when the task is done — so the routine gets handled while you do something else.
CodeCrab is a native desktop application that reviews pull requests in seconds by orchestrating the local command-line AI tools already installed on your machine. It is built for software engineers who want fast, deep reviews of both their teammates' pull requests and their own work, and it is designed around a simple promise: your code never leaves your laptop. CodeCrab learns your codebase, combines your existing skills with its own specialized CodeCrab review skills, and maps AI observations directly onto the changed lines so reviewers can catch bugs, risky patterns, and regressions before they approve. The product is currently available as a free public beta that runs 100% on your machine. Modern engineering teams are writing code faster than they can review it. As AI tooling generates code at unprecedented speeds, the primary bottleneck has shifted from writing code to reviewing pull requests efficiently. In practice, that means senior engineers spend hours walking through diffs, and reviewers often lack the full context of the repository behind a change. At the same time, many teams work on sensitive or regulated codebases where uploading source code to a third-party cloud review service is simply not an option. CodeCrab was built by Edy, a software engineer with more than 14 years of experience, including years building systems at Google and Pinterest, initially as a personal tool to perform deep, Staff-level code reviews quickly without uploading sensitive private code to third-party servers. The first core workflow is pull request code review. You open any pull request from your colleagues, and CodeCrab walks through the diff with you. It maps AI observations directly onto the changed lines, so you can spot bugs, risky patterns, and regressions fast, before you hit "Approve". Crucially, CodeCrab reviews against your entire local repository rather than only the diff: it uses full codebase context, including your types and your test suite. That means observations are grounded in how the change actually fits into the project, not just in the isolated lines that changed. The whole process is 100% local-first, so CodeCrab can catch logic bugs and regressions without uploading a single line to the cloud. The live review interface combines a file tree, a diff viewer, and inline AI observations in one native desktop window. The second workflow covers your own pull requests. When a teammate leaves an observation on your PR, CodeCrab runs a deep investigation for you. It digs through the code around every comment, connects that code with your project's context, and helps you understand as precisely as possible what the observation really means and what the correct solution looks like. The investigation of every reviewer observation on the diff is deep and read-only, so nothing is modified while CodeCrab is reasoning about the feedback. Once you understand the finding, CodeCrab supports an assisted fix on your local branch, verified against your own test suite. A third, closely related workflow happens before the pull request even exists: pre-push code review of local changes. While you are still working locally, CodeCrab reviews your in-progress changes in read-only mode before anyone sees the diff, detects errors early, investigates each finding as deeply as needed, and helps you apply the right fix while the context is still fresh. CodeCrab is built to plug into the workflow you already have rather than replace it. You connect any repository, and CodeCrab learns its rules and patterns, building a per-repository review profile that powers specialized review agents and custom skills. Those profiles make reviews tuned to your codebase instead of generic best practices. Your own skills and CodeCrab's agents work together: you can reuse your existing local skills, combine them with CodeCrab's, and extend as far as you need. The app integrates with your local skills, Claude Code, and Jira, and it works with GitHub and GitLab today, with Bitbucket, Cursor, and Codex listed as coming soon. Repositories, skills, models, and language are all configurable, so experienced engineers can enforce their own standards without abandoning their existing setup. Privacy is the foundation of the product. CodeCrab uses a 100% on-device architecture with zero code uploads: your source code never leaves your laptop or passes through external cloud databases, which makes it suitable for strict corporate environments where no code may be sent to third-party AI clouds. Control is equally deliberate. CodeCrab is read-only by default and never commits, pushes, or posts public GitHub comments without your explicit permission. When you do want to apply a change, CodeCrab generates verified code patches as 1-click local fixes, and it runs your native test suite (cargo test, pytest, npm test) before applying them, so the patch is checked against the project's own tests rather than trusted blindly. Instead of requiring org-wide OAuth admin permissions, CodeCrab uses your own CLI login (gh). The distinctive approach is tool orchestration on the client side. Rather than locking you into a vendor's fixed model wrapper, CodeCrab orchestrates your local command-line tools, so it can use your local Claude Code and Cursor setups. It connects directly to the AI subscriptions you already pay for, giving you full model and cost control: you choose which AI models to run and control exactly how much you spend on code reviews, with zero server markups or hidden fees. Execution is transparent through a live execution console that shows real-time stdout and stderr, in contrast to an opaque cloud pipeline. The difference from cloud review bots is not the model, it is where your source code ends up: with CodeCrab everything stays client-side and runs as an instant local native application, while cloud SaaS bots upload and process code on vendor servers and run queued background jobs. The headline benefit is speed without loss of depth. CodeCrab is described as instant and lightweight, with blazing-fast native desktop performance, minimal RAM consumption, and instant startup, so reviews happen in seconds instead of waiting on a queue. Engineers get early bug detection for logic flaws, security risks, and regressions directly on the diff, plus 1-click local fixes that produce verified code patches ready to apply to a local branch. Precision diff navigation with clear changed-file tracking, inline observation badges, and clean multi-file diff inspection keeps large changes manageable. Together these outcomes shorten the loop between noticing a problem and having a reviewed, verified fix, and they let teams ship cleaner, higher-quality code while keeping full control over cost and data. Concrete workflows include reviewing a teammate's pull request before approving it, where CodeCrab walks the diff and places observations on the changed lines so you can catch risky patterns and regressions with full repository context. Another is turning feedback on your own PR into a solution: CodeCrab investigates each reviewer observation deeply, explains what it means, and assists with a local fix verified against your test suite. A third is pre-push review, where you analyze in-progress local changes and apply fixes before the pull request is ever created, so the PR you open ships cleaner code. Teams working in regulated or security-sensitive environments use CodeCrab because reviews happen entirely on-device with no code uploads. Engineers who already pay for tools such as Claude Code or Cursor can reuse those subscriptions for reviews rather than paying for an additional cloud service. The bundled ready-to-test demo project lets anyone install, open, and see CodeCrab in action without connecting their own code. CodeCrab is aimed at software engineers and engineering teams who review code daily, particularly those who want deep, Staff-level reviews quickly and cannot or will not upload sensitive private code to third-party servers. It complements existing setups instead of replacing them: it integrates with GitHub, Claude Code, Jira, and GitLab, with Bitbucket, Cursor, and Codex listed as coming soon, and it plugs into local custom skills. Reviews run against your local repository and your own test suites, with example commands including cargo test, pytest, and npm test. GitHub access uses your own gh CLI login rather than org-wide OAuth permissions. The app ships as a native desktop application, currently downloadable for Linux as Beta v0.1.7, and CodeCrab is in free public beta with no code leaving your laptop. CodeCrab's promise is straightforward: faster, deeper pull request reviews with total privacy. By learning your codebase, orchestrating the local AI tools and subscriptions you already own, and keeping every line of code on your machine, it turns review from a bottleneck into a fast, controlled, read-only step in your engineering workflow.
Rill is a free browser for the Mac where your Claude Code and Codex agents work beside you. It runs on the Claude Code or Codex plan you already have, and its purpose is simple: let you ask for work from the exact page you are already looking at, instead of leaving the browser to describe it somewhere else. Rill is for people who browse the web and build things at the same time — developers, researchers, writers, designers and teachers — and it keeps your browsing and your agents in one window. You can search, enter an address, or send a task from the same field, then carry on reading while the work happens. Rill starts from a specific frustration: an idea used to mean switching to the terminal. You found something on a page, then had to leave the page, open a terminal, find the right project, and restate the context you were just looking at. Rill's answer is that you now say it where you found it. The same problem shows up in browsing itself. Tabs pile up with no structure, and history becomes a flat list of timestamps that tells you nothing about what you were doing or what got finished. Rill is built to close both gaps: it carries the page you are on into the project that should handle it, and it turns your browsing into something you can read back later — where you went, what you asked for, and what got done. The core gesture is ⌘E. Press it on any page and a note opens over the page, holding what you were looking at — the page itself, or a paragraph or row you pointed at with a click — plus whatever you type. You describe the task in plain words, and Rill decides which project it belongs to. It finds your projects in your Claude Code and Codex history, so there is nothing to set up: no configuration, no mapping of folders. In the product's own examples, a task to 'Try this method on my data' routes to a project called longitudinal-study; 'Try this on one lesson' routes to lessons; 'Chart this against last year' routes to newsroom-charts; and 'Make my project pages like this' routes to portfolio. The project field shows Choosing a project, then the choice, then Sent. Not every request is code. When a task isn't meant for a project — finding a nonstop flight from San Francisco to New York, for instance — the destination reads On the web, and your agent goes looking in a tab behind yours. You keep reading. Agents tell you when they need something instead of waiting for you to check on them: in one example, Claude Code raises a bubble over the essay you are reading with the question 'Nonstop from SF to NYC. Needs your answer. Morning or afternoon departure?', offers Morning and Afternoon buttons, and carries on in the same tab after you answer. When a result lands, it lands where you were: one demonstration shows a chart titled 'July surface water temperature: one step, not a slope' appearing while you browsed the page, from the longitudinal-study project, marked Done · 2 files changed. Rill also organises the browsing itself. Tabs are sorted by AI into groups by what you were doing, each group carrying a one-line summary — in the sample start page, Music videos, Land and climate, Art collection and Space imagery. Task tabs sit among them, and a task tab on the web shows a thin red-orange line at its edge to mark work in progress. History becomes a journal rather than a log: a day is broken into stretches, each summarised in a sentence — for example, 64 pages in six stretches on Sunday, September 27, with 'Morning news and weather', 'Changepoint methods paper' (a task sent to lake-temps, done) and 'CPI chart for the newsroom' (a task sent to newsroom-charts, done) — plus a ribbon of the day and the individual pages with timestamps. After a few weeks, every project your agents have touched appears on one map: 38 projects in 6 areas named by AI, including Research and data, Writing and publishing, Design, Teaching, Home and life, and Tools and code, with finished work lit as Done. How Rill works overall is deliberately light. The AI features run the Claude Code or Codex installation on your Mac, under your own account, so Rill adds no model of its own and no API keys. Setup is three steps: download Rill and drag it to Applications; sign in to Claude Code or Codex — use either, or both, and Rill walks you through it; then press ⌘E on any page, and Rill finds your projects for you. Agents read pages as untrusted text, new tasks are read-only until you allow edits, and in git repositories each edit can be undone. A task on the web is told to stop before the step that pays, places an order, sends, posts or deletes unless you plainly told it to go through with it, and it cannot type into password, card or one-time-code fields. In a project, an agent browses in tabs of its own, without your logins, and clicks or types only when you allow it. The outcome is that context switching largely disappears. You no longer stop what you are doing to explain it somewhere else: the page, the highlighted paragraph or the pointed-at table row travels with the request, and the agent starts with the context you already had. Because projects are found for you from history, the cost of starting a task is a keystroke and a sentence. Because agents ask their questions inline and report when they are done, you are not polling them in another window — you answer or keep scrolling. And because tab groups, day summaries and the project map are generated from what you actually did, the record of your work stays legible: you can see which stretches of the day produced something and which projects your agents have touched. Concrete scenarios appear throughout the product's own material. A row of a consumer-price table, pointed at with a click, becomes 'Chart this against last year' in a newsroom-charts project, and the chart is waiting when you look. A release note for Polars 2.0 becomes 'Try this on one lesson' in a lessons project. A type foundry's page, with a paragraph pointed at, becomes 'Make my project pages like this' in a portfolio project. A city article becomes 'Find a nonstop from SF to NYC, Nov 12 to 16' — a task on the web. Beyond agent tasks, Rill works as a browser on its own: ask about a page and the answer opens beside it from the agent you already use; compare up to six tabs and get a table that quotes each page; let agents in a project read the web in tabs of their own. And with the beta talking feature, hold Fn and say the task out loud. Rill is currently free and in beta, for Macs with Apple silicon running macOS 14 or later. There is no new subscription and no API keys; the AI features run on the Claude Code or Codex plan you already have, and browsing works without them. Privacy is local by design: your history and passwords live on your Mac. History is kept as files on your Mac, for as long as you choose; passwords are saved in the Mac Keychain and unlocked with Touch ID; AI features run under your own account; and tab sorting and day summaries can be turned off in Settings. The browser's basics are covered too — passwords in the Keychain, private windows, and sign-ins brought over from Chrome, Arc or Safari. Rill lets you know when a new version is out. Rill's proposition is compact: your browsing, your agents, one window. It is a browser first — search, tabs, private windows, imported sign-ins, a Keychain for passwords — with an agent layer that uses the Claude Code or Codex setup you already run. Press ⌘E on the page in front of you, Rill finds the right project and passes the context along, and the work happens while you keep reading. Tabs sort themselves, history reads like a journal, and every project your agents have touched gathers on one map. Free, in beta, on Apple silicon Macs, and built on the plan you already have.

Pheebs is an open-source AI telemetry tool created by Eversynced that measures how engineers and teams actually work with AI coding agents. It sits quietly inside Claude Code, Cursor, and Codex via hooks, capturing lightweight interaction signals: the shape of the session, not its contents. The people it is built for are the ones who need an honest proficiency read rather than a guess — engineering leaders, platform teams, and the developers themselves. Its purpose is measurement: turning the ordinary activity of agent sessions into signals about model choice, verification habits, context management, orchestration, and the dollars that model choices are costing. The problem Pheebs addresses is a visibility gap that opens up precisely when a team starts moving fast. AI coding agents arrive, adoption climbs, and nobody can say what changed. Six observations illustrate the questions the tool was built to answer: model spend that buys nothing, such as a bigger model than the work needed; where AI code ships unchallenged; whether AI output gets verified at all; rework hiding inside the speedup, where follow-up prompts are fixing something the AI broke; and whether the enablement investment landed — for example, a review skill used weekly by 78% of engineers while a migration skill never caught on. The final observation frames the stakes: nobody on the team runs tests inside the agent loop, which is a missing harness rather than a skills gap. Distinguishing a structural gap from a coaching gap is the core problem Pheebs exists to solve. Pheebs captures data by hooking into the agents themselves. It works with three coding agents — Claude Code, Cursor, and Codex — and records seventeen event types that run from session_started through to artifact_found. Hooks fire on session starts and ends, prompt submissions, skill and slash-command expansions, sub-agent spawns, tool calls and failures, compaction, and background tasks. Typical recorded fields are deliberately small: a session_started event carries a codebase such as acme/checkout and a model such as opus; a prompt_submitted event carries a character count and, when the prompt intent classifier is enabled, an intent label such as task or debug; a tool_use_completed event carries the tool name and its duration, with recognized commands summarized as a tool_intent such as test_run. Claude Code and Codex additionally export native OpenTelemetry metrics and logs through the Pheebs proxy, while Cursor is covered by hooks alone. The design constraint behind all of this is that Pheebs captures interaction patterns, not content. It never records source code or file contents. It never records file paths or directory structures — a repo is reduced to org/repo from the git remote. It never records prompt text; a prompt becomes a character count. It never records raw command strings, since a command like npm test is read in process and recorded as tool_intent: test_run. It never stores your name or your email: the developer is the id behind your Pheebs token, stamped by the backend, or a truncated hash of your git email when no token is set, and your GitHub handle is never looked up. The only route in the backend contract that receives raw text at all is POST /classify-prompt, which takes one prompt in and returns one label out. The backend contract also includes POST /ingest for one event envelope per request, POST /validate-token to resolve a token to an identity and its consent flags, POST /otel/v1/{signal} as an OTLP passthrough so no observability credential ever ships in the client, and an optional GET /insights for what one developer can see about their own work. On top of those signals sits a documented proficiency model. It assesses six competencies: Models, covering model choice, effort settings, plan mode, and autonomy modes; Artifacts, the reusable configuration that shapes the agent, such as skills, sub-agents, slash commands, and context files; MCP, live connections to external systems like tickets, databases, browsers, and documentation; Evals, verification wired into the agent loop through tests, typecheck, lint, build, and review passes; Context management, deliberate use of the context window including compaction and the save, resume, clear lifecycle; and Orchestration, running more than one agent at a time via sub-agents, parallel work, worktrees, hooks, and plugins. Each practice is classified as Unobserved, Adopted, or Recurring — Recurring meaning it showed up in at least 3 of the last 4 active weeks — and the coverage index summarizes, per engineer, the share of applicable practices at Recurring. Five judgement signals sit alongside the competency model. On the output side, verification coverage measures the share of AI edits followed by a verification action such as a test run, typecheck, lint, build, or a check against a spec; pushback rate measures how often the engineer challenges AI output instead of accepting it; the refinement-to-repair ratio separates follow-up prompts that refine intent from those that repair breakage; and wholesale-accept rate captures sessions with no pushback, no repair, and no verification, weighted by lines changed — described as the composite red flag of polished output with no questions asked. On the input side, model-fit rate measures the share of sessions whose model class matched the size of the work. Pheebs follows three stated principles here: tasks are sized, so every task prompt gets a scope from a one-file change to open-ended design and a session is judged on its hardest prompt; misses count both ways, because an over-provisioned session burns budget silently while an under-powered one shows up as repair prompts; and Pheebs is an audit, not a router — it never intercepts a prompt or switches a model on anyone's behalf, it reads the gap and prices it, and the decision stays yours. The overall pipeline has five steps. A hook fires. Lightweight fields are extracted — event type, durations, counts, models, trigger types — with prompt text reduced to a character count and an optional intent label. Identity and repo are resolved from the Pheebs token or a truncated git email hash, and from org/repo on the git remote. Every event is logged locally in a JSONL log, and with a token set it is also sent to the backend. OpenTelemetry rides along for Claude Code and Codex. Sending requires both settings to be present: pheebs config set base-url and pheebs config set token. Both need to be set or nothing is posted, and unsetting either one stops sending — the local JSONL stays the durable copy either way. Pheebs also states there are four routes to any backend: self-hosted, or managed by Eversynced. Two deployment shapes are described. In the self-hosted model you run the backend and hold the data: telemetry goes from developers' machines to your infrastructure and Eversynced never sees it. That option includes the full client for all three agents under Apache-2.0, a documented contract and a reference backend in the repo, raw JSONL you can query with whatever you already use, and no account, no key, and no requests. In the managed model, the same open-source client points at a backend Eversynced operates, with the proficiency model rendered as reports and dashboards — the AI Enablement Assessment, a 30-day telemetry sprint ending in an executive debrief and a plan for the gaps. The benefits the content states are visibility rather than surveillance: knowing which models are in play, whether AI output gets verified, whether enablement investments landed, and what the model-fit gap costs. The reporting built on top includes a practice adoption funnel, with one bar per competency split by how many engineers have not acted on it, acted on it once, or acted on it week after week; a practice heatmap putting every engineer against every competency, where a cold column means the team is missing the setup and practice for it and a cold row calls for coaching; a per-engineer view showing how much of each competency has become habit; and a signals table showing the five judgement signals per engineer against a team median. The dollar view prices the gap: in the illustrative example, a savings opportunity of $9,960 against $32,400 of list-price spend, described as 31% and an API list-price equivalent estimated upper bound, with models used and work as sized split across Frontier, Large, Medium, and Small classes. Decisions and figures come from complete sessions only, with coverage reported as complete, incomplete, no telemetry, and unpriced. The quickstart is three commands: npm install -g pheebs, pheebs init for interactive setup across all three agents, and pheebs doctor to check the wiring. Eversynced states that every Eversynced engineer is instrumented with Pheebs; it powers the measurement layer of their AI delivery framework, and the reporting built on top of it ships with the AI Enablement Assessment run for client teams. The product is therefore aimed at teams adopting AI coding agents who want evidence about how those agents are actually being used in their codebase. In short, Pheebs turns the day-to-day shape of AI coding sessions — model choices, prompts reduced to counts, tool calls, verification, compaction, and orchestration — into an honest, legible read on proficiency, adoption, and cost, while keeping the code, the prompts, and the identity of the developer out of the dataset.
Ghostifier is a privacy tool that finds every company holding your personal information and asks each one in writing to stop selling or sharing your data and to delete it. Instead of filling out one removal form per company, it starts from your Gmail inbox: you connect Gmail once, and the first scan looks back about two years to build a list of every company that has your details. It is built for anyone who wants their personal information removed from marketing lists, company databases and data brokers without chasing down dozens of privacy pages by hand. The problem Ghostifier addresses is laid out plainly on its website. Companies hold your name and address, handed over with every account you open and every order you place. They hold what you buy, kept in a profile with your name on it. They hold how you browse, habits and interests gathered to target ads at you. They hold where you go, location details collected by apps and sometimes sold. On top of that, data brokers collect and sell information about people who never heard from them at all. Because each company handles privacy differently, asking for removal one company at a time is slow and easy to abandon. Ghostifier's starting point is your inbox, because that is where the evidence of who holds your data already sits. It unsubscribes you and opts you out of sale and sharing on day one, waits out return windows, then sends deletion requests and tracks every reply. The first thing Ghostifier does is find the companies. You sign in with Google, and, in the words of the site, one sign-in starts the scan right away. Ghostifier uses your inbox to identify the companies that email you, and the scope of what it can see is deliberately narrow. It sees the sender, the subject line, the date and any unsubscribe link in the header. It cannot see message bodies or attachments, and it never opens your emails. The company states that Gmail access is headers only, so it never reads your email bodies, and that there is no AI: every decision follows fixed rules. From that metadata it builds a list of every company that has your information, along with what kind of company it is, and the free scan shows you the result — for example, a count of how many companies have your data, how many relate to marketing mail, and which ones Ghostifier will not delete. Nothing is sent at this stage. You see every company and the plan before anything goes out. You stay in control of what happens next. After the first scan, you can see every company and the plan for it, and nothing goes out until you say go; you also have the option to approve each company yourself. Ghostifier groups companies by relationship type in a control center, with settings for unsubscribe, opt-out and deletion that can be set to automatic, ask me or leave alone. Under the Balanced preset, marketing-only companies get automatic unsubscribe, automatic opt-out and automatic deletion held for 48 hours first; account and updates companies are set to ask me for unsubscribe and opt-out and to be left alone for deletion; purchase companies are likewise ask-me for unsubscribe and opt-out and left alone for deletion. You can change these settings at any time, for each kind of company, and pick how much Ghostifier does on its own. There is also a set of companies Ghostifier never deletes, whatever you pick: banks, insurers, doctors, schools and employers; password managers, email and storage, domains and crypto; anything you used in the last year; and household names like Google and Spotify. Those companies can still be asked to stop selling your data, according to your settings. When you give the go-ahead, Ghostifier does the work in stages. It unsubscribes you from every list that supports one-click unsubscribe, free on every plan. It opts you out of sales, telling each company in writing not to sell or share your data. Once any waiting period has passed, such as the return window on an order, it asks the company to delete your data. If a company misses its deadline, Ghostifier follows up once. Every step is tracked to the legal deadline where one applies. The deletion request itself is sent as an authorized agent request; the sample letter on the site is made out under the California Consumer Privacy Act, as amended by the California Privacy Rights Act, which the letter states requires a response within 45 days and allows a request to be made through an authorized agent holding signed written permission. Ghostifier contacts companies from its own address on your behalf, and you give it written permission once, when you pick a plan. Receipts are kept for every request: the letter, when it went out, and what each company said back. The activity page shows the status of each request — queued, waiting on them, replied, done or problems — alongside the request type, whether unsubscribe, opt-out or deletion. Data brokers are handled separately. Ghostifier asks 220 registered data brokers to delete your details, even if they never emailed you — a group that by definition collects and sells information about people who have never heard from them. This is included with the Cleanup and Autopilot plans. The dashboard tracks how many brokers were asked, how many replied and how many are done, meaning deleted or with none on file. A separate sample letter shows the broker request, which notes that the broker is registered in California, that you may have no relationship with it, and that the request covers records gathered from other sources; it also asks the broker to instruct service providers and third parties to delete as well, and to say so if it holds no records. Overall, Ghostifier works from a single connection rather than repeated manual requests. You connect Gmail, the first scan builds the list, you review it and say go, and Ghostifier handles unsubscribes, opt-outs and deletion requests. On the Autopilot plan, this becomes ongoing: a daily check of your inbox deals with new companies as they appear, companies still emailing after you unsubscribe are followed up, and you get a weekly summary email. Because companies often write directly to you to verify a deletion request, Ghostifier surfaces those messages in a Needs you area — it can see that the email arrived but cannot read your email or answer from your address, so you open it, do what it says and mark it done. The benefits are the ones the site states directly: fewer companies hold your data, and each request is tracked rather than lost. You get proof in the companies' own words — for example a confirmation reading "Your data has been deleted from our systems," kept as a receipt. You do not have to hunt for contact addresses, write letters or remember follow-ups. Nothing is sent without your approval, nothing is sold, and you can leave at any time. And because Gmail access is limited to headers and the system runs on fixed rules rather than AI, the tool gathers what it needs to identify companies without reading the contents of your inbox. Concrete scenarios follow the company's own examples. Someone who has been online for years signs in, sees a scan result such as 412 companies holding their data, and reviews the list before approving anything. A shopper's purchase data sits in a retailer's profile; Ghostifier waits out the return window before requesting deletion, so an order in progress is not disturbed. A person who keeps receiving mail from companies they never heard of can have broker deletion requests sent to the 220 registered brokers, including firms that never emailed them. Someone who wants to keep a Google or Spotify account can still unsubscribe from marketing and ask those companies to stop selling their data, while the accounts themselves are never deleted. A user who receives a verification email from a company can find it flagged in Needs you, complete the step and mark it done. Ghostifier is aimed at people who want their personal information removed from company databases and data broker files without doing the paperwork themselves. It works with Gmail and is a web application. Seeing who has your data is free forever, and the free plan includes the ability to see every company that has your data and to unsubscribe from every list that supports one-click unsubscribe. Cleanup costs $29 once and adds opt-out and deletion requests to every company found so far, deletion requests to 220 registered data brokers, deadline tracking with a follow-up, and a receipt for every request; it counts toward Autopilot if you upgrade within 60 days. Autopilot is $59 a year — about $5 a month, billed yearly, or $8 monthly — and adds companies found later, a daily inbox check, follow-ups on companies still emailing after you unsubscribe, and a weekly summary email. Upgrading to Autopilot within 60 days means the $29 Cleanup counts toward the first year. Payments go through Stripe, and Ghostifier never sees your card. On data storage, the site states that Ghostifier keeps a list of the companies it found and a few dates, such as when they last emailed you; once requests go out it also keeps each letter and the replies companies send back, encrypted so only you can read them, until 30 days after a request finishes. You can delete them sooner, it does not store your emails, everything it holds is visible in Settings, and you can delete it all in one step. In short, Ghostifier's primary value is turning data removal from an endless series of individual forms into one connected workflow: scan your inbox to find who has your data, decide what should happen, and let Ghostifier unsubscribe, opt out and request deletion while keeping a receipt for every request. Seeing who has your data is free; asking them to delete it is where the paid plans come in.

Coddy is an interactive platform that teaches people how to code through short, gamified lessons available in more than 20 programming languages and technologies. According to the site, it covers Python, JavaScript, TypeScript, React, Next.js, HTML, CSS, Java, C++, SQL, C, C#, PHP, Dart, Golang, R, Rust, Lua, Luau, Ruby, Swift, SwiftUI, Verilog, Solidity, Kotlin, Assembly, AI Prompts, Terminal, Excel, Git, Docker and Kubernetes, among others. The product is aimed at anyone who wants to learn to code — from complete beginners writing their first line to learners building a finished project — and it is designed around the idea that learning to code should feel like a game you want to return to every day rather than a textbook you dread. Coddy runs on the web, iOS and Android, and the company states it is free to start with no setup required. Coddy's founders — Barak, Nati and Kevin — state that they built the product because learning to code should feel like a game you want to come back to every day, not a textbook you dread. That framing drives the whole product: lessons are deliberately short, interactive and designed to be finished, rather than long passive courses that learners abandon. Traditional coding education often requires environment setup, downloads and configuration before a single line runs, which is a common reason beginners stop early. Coddy removes that barrier by letting people write and run real code directly in the browser with no setup required, and by turning daily practice into a habit through streaks, leagues and rewards. The result, according to the site, is a platform where over 5.5 million codders have joined and where the mobile apps hold 4.9-star ratings on iOS and Android. Coddy's catalog spans more than 20 languages and technologies. The site lists Python, JavaScript, TypeScript, React, Next.js, HTML, CSS, Java, C++, SQL, C, C#, PHP, Dart, Golang, R, Rust, Lua, Luau, Ruby, Swift, SwiftUI, Verilog, Solidity, Kotlin, Assembly and AI Prompts, along with Terminal, Excel, Git, Docker and Kubernetes. Each language has its own landing page, and many include reference documentation and a browser playground where you can write and run code without installing anything. There are also Spaces beyond programming: a Coding space to write and run real code from your first line to a finished project, a Chess space to learn the rules, tactics and openings one interactive board at a time, and a Math space in Beta where you solve equations move by move and draw graphs by hand with every step checked on an interactive board. Tutorials, guides and stories are published on the Coddy blog. At the heart of Coddy is a real code editor that runs in the browser. Lessons let you write actual code, hit Run Code, and check your work against built-in test cases that report pass or fail along with the expected input and output. The interface shows a console alongside the editor, so you can see what your program returns and compare it with what the test expects. Bugsy, the AI tutor, sits right next to the editor with an Ask AI button: it reads your code and your error, explains what is happening and offers hints — but, as the site emphasises, never the answer. Separate Playground pages exist for individual languages such as Python and JavaScript, described as a place to write and run code in the browser with no setup required. Coddy also offers an Embed Editor that lets you add a free, runnable code editor to your own site with a single iframe. Coddy builds daily habit through a gamification layer. A streak counter tracks consecutive days of activity, with a calendar view and a reminder to return tomorrow to keep the streak alive; Streak Freeze items let you protect a streak on days you miss, and a Double or Nothing challenge runs over multiple days. Learners also carry a score and an energy meter, and their progress is mapped on a Journey board of hexagonal lesson nodes — completed, active and locked — connected by paths, where each node is a lesson such as a theory or challenge step. Beyond the journey, Coddy includes Goals and daily challenges, a Leaderboard, and a Profile. The leaderboard is organised into leagues: the Challenger League shown on the site advances the top 7, with a promotion zone and ranked positions displaying streak length and score. Social features encourage learners to invite friends and earn rewards. Coddy deliberately offers every way to learn within a single lesson. The site describes four complementary modes: Audio, which narrates the explanation (for example, an introduction to variables read aloud with playback controls and speed adjustment); Quiz, to test yourself; Ask AI, to question the tutor; and References, to look up anything you have already covered. Around the courses sit a set of free resources: Docs with reference documentation for every supported language, Cheat Sheets with quick-reference tables, a Glossary of plain programming definitions each with a runnable example, a page of Git Commands with syntax, flags and examples, Visualizations that show algorithms and data structures running step by step, and Tools offering free developer utilities such as formatters and converters. Courses are also paired with Certifications, so learners can earn shareable certificates by completing them. Coddy's approach is to make each lesson small enough to finish and interactive enough to require doing rather than watching. A learner follows the Journey, opens the next unlocked hexagonal node, reads or listens to the theory, then completes a challenge by writing real code in the editor, running it, and passing the test cases. If they get stuck, Bugsy reads their code and error and hints at the direction without handing over the solution, while Ask AI and References let them dig into concepts they have already covered. Daily play is reinforced by the streak system, energy, score and weekly leagues, and progress is visible on the profile. Because everything runs in the browser, the same account works across web, iOS and Android, so a session can continue on a phone during a commute. At the end of a course, the platform issues a certificate that can be added to LinkedIn. The stated benefits centre on consistency and completion. Because lessons are short and gamified, learners are encouraged to show up every day — the site notes that a streak can be protected with freeze days and that rewards are earned for showing up daily. Because the editor and test cases give immediate feedback, learners can tell whether their code works rather than guessing. Because the AI tutor hints instead of answering, learners are pushed to reason through problems instead of copying solutions. Certificates give a tangible outcome: every completed course produces a certificate that can be added to a LinkedIn profile or resume to showcase coding expertise to employers, and the certified example shown is Python Fundamentals. Ratings of 4.9 stars on iOS and Android, and a community of more than 5.5 million learners, are presented as evidence that the format works. Coddy supports several concrete scenarios. A complete beginner can start the Coding space and write their first line of code straight in the browser, using Python or JavaScript lessons and the built-in editor with test cases. Someone who wants exposure to many technologies can move between the 20+ language tracks, from Python and SQL to React, SwiftUI, Solidity or Verilog. Learners preparing for interviews or coursework can drill with quizzes, cheat sheets, a glossary and step-by-step visualizations of algorithms and data structures. Teachers have a dedicated offering: Coddy for teachers lets them assign lessons, track progress and grade automatically. Developers can add a free, runnable code editor to their own site with the one-iframe Embed Editor, and people who want to go further can use Coddy Build to build full-stack apps with AI by chatting, previewing and publishing. Outside programming, the Chess and Math spaces offer interactive practice. Coddy is built for anyone learning to code — beginners writing their first program, self-taught developers picking up new languages, students, and teachers who want to assign and track lessons. It is available on the web, plus iOS and Android apps, so learning is described as taking your coding journey on the go with no setup and no downloads. Pricing is freemium: the Product Hunt listing states that everything is free with a daily limit, and that paid plans are available — Product Hunt visitors get 50% off any plan for 72 hours, applied automatically, and the landing page shows the discount saved and applied at checkout. Coddy also runs an Affiliate programme through which supporters can promote Coddy and earn commissions on referrals. Coddy's core proposition is simple: make learning to code something you actually finish and want to return to. It combines a catalog of 20+ languages with a real browser editor and test cases, an AI tutor that hints rather than answers, and a gamified habit loop of streaks, energy, score and weekly leagues — all wrapped in short, interactive lessons available on web, iOS and Android. Free to start with a daily limit, with certificates for completed courses and a range of supporting resources from docs and cheat sheets to visualizations and a code playground, Coddy positions itself as a practical, playful path into programming for millions of learners.
EasyCut is a free video editor that runs entirely in your browser and is built around a single, specific job: finishing motion videos that Claude has made. Claude designs the video, animates it and scores it — its own motion, music and sound effects — and EasyCut then opens every part of that video as its own track inside one project. Instead of ending up with a flat file, you get a timeline where the video, the titles, the music and each individual sound effect are lined up, labelled and ready to edit. That means you can trim a scene, mute a whoosh, drop in your own track or move the titles, and you can still select one clip and ask Claude to change just that part without rebuilding the whole video. It is free, requires no sign-up, adds no watermark and never uploads your files. The problem EasyCut addresses is a familiar one for anyone making videos with AI: generation tools are good at producing something complete, but they hand back a finished artefact. Once a video has been rendered, the layers are gone. A title is baked into the frame, the music is welded to the picture, and a single sound effect that lands in the wrong place forces you to regenerate everything or start over in a conventional editor that was never designed around AI output. EasyCut's answer is to keep the structure of the AI-generated video intact. By opening each element on its own track, it preserves the ability to make targeted changes at the point where they matter, which is what finishing a video actually means in practice. EasyCut's core editing toolset covers the essentials of assembling a timeline. You can cut, trim and split clips by dragging edges, splitting at the playhead and reordering by dragging, and transitions can be added with one click. The editor is described as a real editor, with a magnetic timeline, frame-exact cuts, J/K/L keyboard controls, markers and undo for everything, so the fundamental mechanics of cutting work the way an experienced editor expects. Two features attack the most tedious part of editing. Remove pauses takes the silences out of a recording in one go, and you can also cut words by crossing them out directly in the transcript — a far more direct way of tightening a talking-head section than hunting through waveforms. Auto captions writes word-by-word captions on your computer and can save them as SRT or VTT files, which makes the output useful outside EasyCut as well. The music tools are built around fitting a track to the edit rather than the other way around: you can fit any song to the video's length and cut on the beat with its real ending, music ducks automatically under voices, and there are free music and effects libraries to draw on. EasyCut can also record directly onto the timeline — your screen, your camera, or both together with your voice — so you can capture a demo, an introduction or a reaction and drop it straight into the project without reaching for a separate app. A visual toolkit covers colour looks, green screen, split screen, blur boxes, shapes and stickers. A set of AI features — voice clean-up, background removal and an AI voice — runs on your device without uploading a thing; the only downloads are the AI models themselves, fetched once the first time you use a feature. Speed ramps let you slow one moment down or speed it up, easing smoothly in and out of the change. Layers groups every clip of a Claude video into one list, so you can find all the whooshes and mute or delete them at once. Your brand keeps your logo, colours and fonts in one place for every video, and Claude can use them too. The most distinctive part of EasyCut's approach is the hand-off from Claude to the timeline. To set it up you connect Claude once, which takes about a minute. On Claude Desktop you download the EasyCut extension — EasyCut.mcpb, 170 KB, for macOS and Windows — and open it, and Claude asks to install it: you press Install. Claude already has everything it needs to run it. On Claude Code you run a single terminal command, claude mcp add easycut -- npx -y easycut-connector@latest, which requires Node.js 18 or newer. From then on, Claude can open the videos it makes straight in EasyCut, every part on its own track. If you are using claude.ai in the browser instead, you ask for the parts as downloads and then open them from EasyCut's Claude panel. The outcome for users is speed: a change to one title or one sound effect no longer means regenerating a whole video, because the structure is still there to edit. Because everything happens locally, footage stays private — your files never leave your computer. Projects save in your browser automatically as you work, and can be moved between machines as a single .easycut file, so the work travels with you. The editor is designed to be calm: big buttons, plain words and tips everywhere mean there is nothing to learn first. Concrete uses follow directly from that workflow. A founder asks Claude for a dynamic launch video for an app, then opens it in EasyCut to trim a scene, swap in their own logo, fit a track to the edit and export wide, tall and square versions for different platforms. A creator cuts the pauses out of a screen-recorded walkthrough, adds word-by-word captions and exports the SRT alongside the MP4. A marketer takes a Claude-made promo, swaps the music for something on brand, and creates a smooth slow-motion speed ramp for a key moment. EasyCut is not limited to Claude output either: it is a full editor, so you can add your own videos, photos and music, or record your screen and camera, and cut, caption, colour and export them the same way. EasyCut is aimed at people who make motion videos with Claude and want to finish them properly — AI-first creators, indie founders, marketers and anyone producing motion content without a professional editing suite. It runs in the browser on computers; on a phone the screen is too small for a timeline, so it is explicitly a computer tool. Google Chrome and Microsoft Edge do everything, including export, while Safari 16.4+ and Firefox 130+ can edit too. Export options include MP4 up to 4K and 60 fps in wide, tall and square formats in one go, a GIF, or just the sound. Pricing is straightforward: EasyCut is free, with no trial, no watermark and no account. The through-line is a simple idea: Claude makes it, you finish it. EasyCut takes the completeness of an AI-generated motion video and restores the editability that normally disappears the moment it renders, keeping every title, scene, image, sound and element on its own track. Free, in your browser, with nothing uploaded and nothing to learn first, it is the finishing editor for AI video.
Chunk is a time-blocking app for Mac that puts your tasks and your calendar on one surface you slide between. Tasks live on the left — smart lists, custom lists, Apple Reminders, recurring tasks and template lists — and your full calendar lives on the right as a day, week or month. Its purpose is simple: let you decide where your day goes. You drag a task onto your day and it becomes a block, and a live countdown shows how long is left on it. Chunk is built for people who plan their days deliberately and want their plan and their real calendar to stay in step, rather than living in two separate apps. Most people keep their to-do list in one tool and their calendar in another. The two rarely agree, and the day tends to be shaped by whatever meetings land in the calendar first, with the actual work squeezed around the edges. Time blocking is the practice of giving tasks real space on the calendar, but doing it by hand across multiple apps is tedious and easy to abandon. Chunk closes that gap by making tasks and calendar one continuous surface: block out the day, drop tasks straight from your list, and see the plan and the calendar update together. Because Chunk syncs both ways with the calendars you already use, adopting time blocking does not mean abandoning your existing setup. At the heart of Chunk is the timeline. You drag on the timeline to create blocks, drop tasks straight from your list, or apply a recurring template to fill the day in seconds. The layout slides from the task column to the calendar, so the same plan can be worked as a timeline, a week grid, or a month view. Chunk can compress quiet hours and export a PDF or CSV when you need a copy of your plan. A live countdown stays visible in the system tray, and a fullscreen alert fires as each block ends, letting you mark the block complete or reschedule it in a click. Tasks and their lists live in a single column alongside the calendar. Chunk groups them into Inbox, Today, Upcoming, Overdue and Completed, and supports smart lists, custom lists such as Work, Launch, Personal, Home, Reading, Groceries and Errands, plus Apple Reminders and recurring template lists. Tasks can carry detail: a task like "Write launch post" can hold subtasks, notes, an attached file such as Pricing model.pdf, and a deadline. Schedule the work once and it appears everywhere it should, so a task you place on the timeline is still visible in your list views. Chunk integrates with the calendars people already use. It offers full two-way sync with Apple Calendar, Google Calendar and Outlook, keeping work and personal calendars in one unified view. Because the sync runs both ways, you can drag to move or resize an external event straight from Chunk and the change is written back to the source calendar. A lock toggle lets you freeze external events as read-only whenever you would rather avoid accidental edits. Apple Reminders lists appear inside Chunk's task column too, so you can drag a Reminders item straight onto the timeline to schedule it. Chunk also ships a local MCP (Model Context Protocol) server that connects to Claude Desktop in one click from Settings → AI Integrations, letting you plan your day in natural language. Once connected, Claude can read your schedule, create, edit or delete events, manage task lists, work with recurring templates and view external calendars. The MCP server is a local process: Chunk reads and writes directly to your on-device database, and nothing is sent to any server beyond what Claude itself processes during your prompt. You can disconnect at any time. Chunk is designed to stay one keystroke away. First, open Chunk from the menu bar: click the tray icon or hit ⌘+/ from anywhere, even over fullscreen apps, and Chunk slides in ready to use. Second, block out your day by dragging on the timeline, dropping tasks from your list, or applying a recurring template. Third, stay in flow: the tray countdown and the fullscreen alert at the end of each block keep you moving through the day without breaking focus. The Chunk panel floats above every other window, including fullscreen apps, so you never have to break your flow just to check your schedule. The result is a plan you can actually follow. Because tasks become blocks, you see exactly where your time is going rather than guessing. Because the countdown and the end-of-block alert sit in the tray, you do not have to open a separate window to know what you should be doing. Because external calendars sync both ways, your plan never drifts out of date. And because templates let you reuse a good day — daily, weekly, monthly or yearly — the planning work you do once keeps paying off. Concrete scenarios show how this plays out. Someone planning a focused workday drags "Deep work" onto the timeline for 9:00 to 10:30, adds a standup and lunch around it, and lets the countdown track the block. Someone with a repeating routine builds a "Morning routine" or "Deep work day" template with a daily or weekly rule and applies it in seconds. A user who keeps errands and groceries in Apple Reminders drags those items from the Reminders list straight onto the timeline. Someone who wants their week planned out asks Claude in natural language. And anyone with several Macs installs Chunk on each and switches on syncing so the plan follows them. Chunk is a native macOS app for both Apple Silicon and Intel Macs running macOS 12 Monterey or later. There is no Windows, Linux or Android version, and a separate Chunk for iPhone app is coming soon to the App Store as a one-time purchase with a free 7-day trial that syncs with your Mac through your own iCloud; Apple Family Sharing is supported at no extra cost. Chunk integrates with Apple Calendar, Google Calendar, Outlook and Apple Reminders, and its optional AI planning runs through a local MCP server. You can try Chunk free for 7 days with no credit card required, after which it is a one-time purchase of $29.99 for lifetime access — no subscription. Your data stays on your Mac and, if you switch on cross-device sync, travels through your own iCloud rather than Chunk's servers. Chunk's value proposition is straightforward: one surface for tasks and calendar, real blocks on your day, a countdown that keeps you in flow, and two-way sync with the calendars you already use — all for a single one-time payment. It is time blocking without bloat, fuss or a subscription.
NoteWorthy is a notes app for iPhone, iPad and Mac that finishes the note after you have written it. You jot anything down — a messy line, a quick capture, a scraped list — and NoteWorthy writes a title, summarizes what you wrote, cleans up the formatting and files the note into the right place. Its purpose is captured in its own headline: You write the note. It does the rest. The app is built for people who capture quickly and organize slowly, and it is designed from the ground up to run entirely on the device it is installed on, without an account, without a subscription and without any note leaving the machine it was written on. The app aims at a familiar problem. Note-taking tools are easy to start and hard to keep. Notes arrive without titles, without structure and without a home, and the fixing-up work — naming, tidying, filing — is exactly the work people skip. At the same time, most modern notes apps ask for an account, hold content on remote servers and charge a subscription for the privilege. NoteWorthy's answer is to put the clerical part of note-taking on the device itself, so that titling, summarizing, formatting and filing happen automatically and privately, with nothing to trust beyond the hardware in your hand. Writing in NoteWorthy is rich text with real Markdown underneath. Checkboxes, headings, bold and italic, tables and images all work the way you would expect, and the note is stored as Markdown you can take anywhere. Six paper colors let you separate the look of different notes, you can scan text straight out of a photo, and any note can be exported as Markdown that opens in any other editor. The Markdown foundation matters because it makes the library portable by default: if you ever want to leave, you take your notes with you rather than leaving them behind inside a proprietary format. Two on-device writing tools do the tidying. AI Format turns a scrappy line into headings, bullets and checkboxes without changing your wording — it restructures, it does not rewrite. AI Summarize pulls a page of thinking down to a single sentence. In both cases you see the result before it touches the note, and you can then copy it, insert it, or replace the original with it. Both run on the device with no network in either direction, and on older hardware they fall back to fast built-in heuristics so the feature still works. AI Organize handles placement. Every note gets a title and files itself into Tasks, Ideas, Info or Personal, and you can make your own labels with your own icon and color and pin the ones you use most to the tab bar. A single tap on AI Organize tidies the whole library. The filing is deliberately deterministic: run it twice and nothing moves, because filing reads what is already stored on the note rather than asking a model to guess a second time. That detail is what makes automatic filing safe to rely on — the library does not reshuffle itself every time you press the button. Capture and retrieval extend the app beyond its own window. You can select something in Safari, share it, and it becomes a note; Siri and Shortcuts do the rest. There are five Shortcuts actions, and Summarize and Format work on text from any app. Widgets come in four sizes and include checkboxes you can tick without opening anything. Search works both inside the app and from the Home Screen: keyword search with highlighted matches that can be filtered by color, and every note indexed with Spotlight so the system search finds it without opening NoteWorthy, with Spotlight results opening the note directly. Indexing happens on device, like everything else. Notes also know what they contain: a date becomes a calendar event, a name links to your contacts, an address opens in Maps, and writing "remind me before Friday" prompts the note to offer to set a reminder. All of that detection happens on device and is never uploaded, nothing happens until you tap it, and reminders arrive as a local notification. Privacy here is presented as a property of the build rather than a promise. There is no server to trust because the app makes no network requests at all. There is no account to create and no connection required, so airplane mode changes nothing. The app can be locked with Face ID, notes are written to disk with file protection on iPhone and iPad and stay inside the app's sandbox on a Mac, and nothing is collected and nothing is tracked — no analytics, no advertising and no crash reporter of the developer's own. You can verify the claim rather than believe it: on a Mac the app is sandboxed without the network entitlement, so macOS itself would refuse any connection, and the entitlement list can be printed with a codesign command. On iPhone and iPad you can turn on App Privacy Report, and NoteWorthy never shows up under network activity. Underneath, two models run on the device. Apple's Foundation Models, part of Apple Intelligence running on the Neural Engine, write the words: note titles, summaries and the Markdown rewrite. Google's EmbeddingGemma 300M — a 300-million-parameter embedding model, quantized to 4-bit, bundled inside the app and run through MLX — decides where things go. Because it is an embedding model, it matches a note to a label by meaning rather than by keyword, and it can also conclude that none of the labels fit. It is loaded lazily and never downloads; the weights ship inside the app. As the site puts it, one writes and the other decides where things go, and neither can reach the internet because the app cannot. NoteWorthy is universal for iPhone, iPad and Mac and is a single Universal Purchase covering all three. It needs iOS or iPadOS 26 or later, or a Mac with Apple silicon running macOS 26 or later. Apple Intelligence is required only for the writing features — AI Format, AI Summarize and generated titles — and the app falls back to built-in heuristics without it, with writing, filing and search still working. Everything the app does today is free, with no ads and no subscription. iCloud Sync and Shared Notes are announced but not shipped; when they arrive they will go through your own iCloud account rather than a server of the developer's, and they will be a single one-time unlock. Until sync ships, each device keeps its own notes and you can move one across by exporting it as Markdown. The Mac version is in review for the Mac App Store; until it clears, it can be installed from a DMG or with a Homebrew cask. The intended audience is people who already live on Apple devices and want the convenience of AI assistance without handing their writing to a server. That includes anyone who captures thoughts in a hurry and never gets around to filing them, and anyone for whom privacy is a requirement rather than a preference. Because the app works offline and asks for no account, it also suits people taking notes in places where a connection is unavailable or unwanted, and people who simply do not want another subscription. The outcome for a user is a library that stays organized without a filing session. Notes arrive titled, structured and classified, which means search and Spotlight can find them later and the labels remain meaningful instead of becoming a junk drawer. Because there is no network path at all, notes carry no exposure: nothing to leak, nothing synced to a third party, nothing collected. And because the format is Markdown, the library is not a commitment — it is a set of plain text notes you can carry elsewhere. That plays out in ordinary workflows. You are reading something in Safari and a paragraph is worth keeping, so you select it, share it to NoteWorthy and it becomes a note; later a single tap on AI Organize titles it and puts it under Ideas. You dictate a messy list of errands; AI Format turns it into checkboxes without touching the wording, and the items can be ticked from a widget without opening the app. You have written a long page of thinking about a decision and want the gist, so AI Summarize offers a sentence you can insert while keeping the original underneath. You write "remind me before Friday" in a note about a signed statement of work, and the note offers to set a reminder that arrives as a local notification. The website's own sample notes show exactly this shape of use: a follow-up about a reply, a market list with items already ticked, a dentist and insurance note, a packing list for Lisbon and a sourdough starter idea, each one titled and filed under its own label. NoteWorthy's core proposition is narrow and firm: the AI help in a notes app does not have to travel. Titles, summaries, Markdown cleanup and semantic filing all happen on the iPhone, iPad or Mac you are already holding, the library is stored as Markdown you can export, and every feature the app ships today is free. For anyone who wants smart notes without a smart server, that combination — automatic organization plus an app that makes no network requests at all — is the whole point.
OpenBot is a free desktop application that runs AI agents as a team on your own computer. Instead of a single chat window, OpenBot gives you persistent AI teammates: each agent has its own name, its own instructions and its own workspace, and agents can message each other, hand off tasks and share files. OpenBot is built for people who already pay for an AI plan and want to turn it into a working team rather than a single assistant. It connects to Codex, Claude Code, Gemini, Grok, OpenCode, Cursor and Cline, to any OpenAI-compatible endpoint, or to local models running in Ollama or LM Studio. Most people who use AI every day are juggling several assistants at once. They may have a ChatGPT plan for one job, a Claude plan for another, and a Gemini or Grok subscription for something else, but each of those assistants works alone, in its own silo, and none of them can hand work to the others. OpenBot brings those providers into a single workspace where agents are given clear roles and can delegate to one another. Because the app runs on your own computer, workspaces, conversations, files and browser data stay on the machine that runs OpenBot rather than on a vendor's servers, and you keep paying only for the AI provider plan or API key you already have. It is also open source, so the code can be read, changed and run for noncommercial purposes. The core of OpenBot is the idea that agents work as a team. Each agent has its own name, its own instructions and its own workspace, so a Research agent and a Builder agent can hold different briefs and different context. Agents send each other messages, hand off tasks and share files. In the product's own walkthrough, a planner asks Research to verify the evidence and Builder to check the rollout path, then references @Research and @Builder by name to turn the work into a final launch brief with the source files attached. Because the handoffs are explicit, you can see who did what and keep every decision traceable. OpenBot does not ship its own model subscription. It runs on the AI plan you already pay for: Codex signs in with your ChatGPT plan, Claude Code with your Claude plan, and Gemini works with a Google AI Pro or Ultra plan. OpenCode offers free models that need no account at all. You can also connect any OpenAI-compatible endpoint, or run local models in Ollama or LM Studio. The providers listed on the site are Codex, Claude Code, Gemini, Grok, OpenCode, Cursor and Cline, and the same names appear in the app's agent picker. The result is that your existing spend on AI is turned into a team of agents instead of a single assistant. Three design choices define how OpenBot behaves in practice. First, everything is stored on your computer: workspaces, conversations, files and browser data stay on the machine that runs OpenBot, not on OpenBot's servers, although the AI provider you choose does receive the prompts your agents send to it, and pages an agent opens use the network. Second, you can change the provider and keep the agent: an agent keeps its workspace and conversation when you restart the app or move it to a different provider, so a long-running piece of work can continue under Claude Code after starting under Codex. Third, OpenBot includes a built-in browser, and agents can open, read and control pages in it, which is how an agent can load a local sign-in page such as localhost:3000/sign-in while doing QA work. OpenBot also lets you work at your own pace and with other people. You can queue the next task: send more work while an agent is busy, and messages wait in a queue that you can pause, resume or cancel. The app is multiplayer, too, so you can invite your team to collaborate live with the same agents, and colleagues can follow work in a shared channel and watch an agent hand a task from one teammate to another. Signing in is optional; the app works without an account, and you need one only to invite other people to your team. Getting started is deliberately short: download OpenBot, connect a provider, then describe the agent you want in one prompt, check its instructions and save it. The methodology behind OpenBot is straightforward. Instead of building one more chat interface, it gives agents roles, a workspace that persists, and the ability to talk to each other. A role is defined by the prompt you write when you create the agent: you describe the agent you want, check its instructions and save it. From then on that agent keeps its name, its instructions and its workspace, and it can be moved between providers without losing its place. Work is passed around by messages and attached files rather than by copy-pasting between tools, and a queue holds new requests until the agent is free. Everything runs on the computer that runs OpenBot, with a browser built in for the pages agents need to read or control. The practical benefit is that you pay nothing extra for the app itself. OpenBot costs $0, with no hidden fees and no locked features; the only cost is whatever you already pay your AI provider, through a plan or an API key. Because agents can hand work to each other, a single request can turn into a chain of checks, an evidence review, a rollout check, a test and a rollback step, without you shuffling between apps. Because the provider can be changed without losing the agent, you are not locked into one vendor's model for the life of a task. And because workspaces, conversations, files and browser data stay on your computer, the material you produce stays with you rather than living only in a hosted service. The scenarios described on the site are concrete. In a launch planning workflow, a planner agent prepares the launch plan, tags it Research and keeps every decision traceable, while a Research agent verifies the evidence and a Builder agent checks the rollout path, producing a launch brief and metrics files. In a coding workflow, an agent reads billing code, reports that six tables use it, moves the billing tables to their own schema, changes four files and writes the migration, then hands the test work to a provider that continues the migration. In a team channel, one teammate reports a failing sign-in test on Safari, passes it to another, who fixes it in session.ts and asks a third to review and merge it. Agents can also load a local sign-in page in the built-in browser, steer a request such as summarizing the support inbox or drafting the release notes, and queue extra work, like checking new sign-ups, while the agent is still busy. OpenBot is aimed at people and small teams who already use coding and chat agents and want those agents to work together: developers, technical teams, and anyone coordinating research, releases or QA with AI. It runs on macOS 13 or newer on Apple silicon or Intel, Windows 10 or newer on x64, and Linux on x64 or arm64 as an AppImage. The app is free at $0, with no account required unless you invite other people to your team. The source code is public on GitHub under the PolyForm Noncommercial License 1.0.0, so you can read, change and run it for any noncommercial purpose; commercial use needs a separate license. Users should note that OpenBot is a development preview: agents can read and change files, run commands, use the network and control the built-in browser without asking each time, so it should be given only tasks you trust, with backups kept. OpenBot's value proposition is simple: a free, local, open-source workspace that turns the AI plans you already pay for into a persistent team of agents that share work, files and conversations on your own computer, and lets your colleagues join them live.
CamCue is a desktop AI interview and meeting assistant for Mac and Windows. It drafts answers to spoken questions and tasks on your screen using your CV, job description, and documents. Use it for interview practice, coding questions, client conversations, and team calls.Listen recognizes complete questions from your computer's audio and drafts answers as the conversation unfolds. Capture analyzes your entire screen, while Select focuses on the area you choose. You can ask about a question, a paragraph, a coding problem, or another task without copying it into a separate app.Add your CV, the role you're applying for, or project documents to give the assistant useful background. Choose Interview, Coding Interview, Quiz/Test, or Call mode, then set the response language and length. Save context presets for different conversations.Focus Mode puts answers in a compact, movable window with adjustable transparency. Global shortcuts control Listen, Capture, Select, and the window. Try the built-in Listen demo before a call and revisit questions and answers in local session history.Speech recognition runs on your computer. Raw Listen audio is not saved or uploaded; recognized text and relevant screen or document context are sent for AI processing. CamCue requires an internet connection and an account. Stealth requests screen-capture exclusion where supported; compatibility depends on your operating system and capture app.Start with the Free plan's limited AI credits. PRO includes unlimited AI credits for Listen, Capture, and Select at US$9 every 3 days, US$19 per week, or US$69 per month. Subscriptions renew until canceled; technical rate and session limits apply. Mac requires Apple Silicon and macOS 14.2 or later. Windows requires x64 and Windows 10 version 2004 or later, or Windows 11.Website: https://camcue.app/Contact: support@camcue.app
Marv is a Windows desktop companion built around your cursor. The website introduces it as your cursor's new plus-one — a little companion that helps you get things done. Marv sees your screen, answers out loud and shows you the next step. Rather than leaving the program you are working in to hunt for an answer, you hold a hotkey and ask about whatever is currently on your screen. Marv replies by voice while drawing directly on top of what you are looking at, circling buttons, drawing arrows and writing notes so you can follow along in place. The page frames the whole experience as a conversation, on your desktop, and the product is positioned for people who want to finish a task inside the app they are already using instead of breaking away from it. The problem Marv addresses is the friction of getting stuck inside software. When you cannot remember a spreadsheet formula, cannot find the right control in a video editor, or cannot work out why a piece of code is misbehaving, the usual path is to stop what you are doing and go looking for help elsewhere — another window, another tab, documentation, or a forum — then translate whatever you find back into the interface in front of you. That gap between knowing the answer and knowing where to click is exactly what Marv targets. Its stated promise is one task, all the way through: the site gives the example of Marv taking a spreadsheet question from the formula to the next app. Marv is also designed to be helpful when you need it and quiet when you don't, with screen access that can be paused, so the companion stays out of the way until it is called on. It is currently in early access for Windows, with a waitlist. The first of Marv's three stated steps is ask out loud. You hold your hotkey to talk, and the page displays Ctrl + Alt as the shortcut. Instead of typing a query into a search box, you speak your question while looking at the thing you are confused about, and Marv listens. Because the trigger is a held hotkey rather than an always-on microphone, the interaction is deliberate: you decide when the conversation starts. This matters because the question you want to ask is usually about something visible on screen, and describing it in words is faster than copying it out. The illustration of Marv listening accompanies this step, reinforcing the idea that Marv is attending to both your voice and your screen at the same time. The second step is get a clear answer. Marv speaks, so you can keep moving. Voice output is the core of the design: your eyes stay on your work while Marv explains, rather than being pulled to a separate chat window or a wall of text. For tasks where you are mid-flow — tracing a bug, adjusting a formula, hunting for a menu item — spoken guidance means you do not have to break your attention to read. The page pairs this step with a smiling Marv, underlining that the response is conversational rather than a document to be studied. The third step is follow Marv's lead, where the cursor-centric part of the product comes in. Circles, arrows and highlights show the way, and Marv also writes notes directly on your screen. This is the feature that distinguishes Marv from an ordinary assistant: the answer is not just described, it is pointed at. When Marv circles a button or draws an arrow to a control, you are being shown the next step on the actual interface you are using, in the actual application, without a second monitor or a side panel. The site's imagery for this step shows Marv pointing with an arrow, and the Product Hunt description confirms the same behaviour — Marv draws arrows, circles buttons and writes notes directly on your screen to walk you through it. Taken together, Marv's approach is to combine screen awareness, voice input and voice output with on-screen annotation on the Windows desktop. The product sees your screen, you speak a question through a held hotkey, Marv answers out loud, and it then marks up the interface to show where to go next. A visible screen access control — shown on the page in a paused state — gives you a way to stop Marv from seeing the screen, matching the promise that Marv is helpful when you need it and quiet when you don't. Everything happens over the top of the application you are already in, which is the stated benefit: you can debug some code, work out a spreadsheet formula, or find the right control in your video editor, all without leaving the app you are using. The benefits follow from that design. Because Marv answers out loud and annotates in place, the loop between asking a question and acting on the answer is short: you do not switch windows, you do not lose the context of what you were doing, and you do not have to translate written instructions into clicks. The guidance lands on the real controls of the real interface rather than on a screenshot in a help article. And because you can pause screen access and Marv stays quiet until summoned by the hotkey, the companion does not demand attention when there is nothing to solve. The page's framing of Marv as a plus-one to your cursor captures this: it is a companion that accompanies the work rather than a destination you travel to. Concrete scenarios are described throughout the site. Marv can help you debug some code, working alongside you in your development environment. It can help you work out a spreadsheet formula, and the site explicitly describes Marv taking a spreadsheet question from the formula all the way through to the next app, so a single task can span more than one program. It can help you find the right control in your video editor, a classic case of an unfamiliar or deeply nested interface where hunting through menus wastes time. More broadly, the page illustrates Marv sitting alongside an ordinary desktop window — a Notepad file holding a weekend plan — with the cursor pointing at a line item, showing the everyday, non-technical context in which the companion operates. The common thread in every scenario is that the question arises while you are already inside an app, and the answer is delivered there too. Marv is currently offered as early access for Windows, and the site's call to action is to save a spot for Marv by joining the waitlist with an email address. Joining the waitlist means agreeing to the Terms and Privacy Policy. No pricing or paid plans are stated on the page, and no integrations, technology stack or mobile or web application are mentioned — the product is presented as a desktop companion for Windows. The primary audience is therefore Windows users who want in-context help while they work: developers debugging code, people wrangling spreadsheets, video editors looking for a control, and anyone else who would rather be shown the next step on screen than read about it somewhere else. In summary, Marv's value proposition is simple and specific: it is a little companion that sees your screen, listens when you hold a hotkey, answers out loud, and then draws circles, arrows, highlights and notes directly onto your screen to show you what to click. By keeping the entire exchange inside the app you are already using, Marv turns a stuck moment into a guided next step — one task, all the way through.
DailyHelm is an agentic AI business reviewer that monitors your analytics, ads, SEO, and store data overnight and then tells you what to fix today, ranked by revenue impact. Its promise is simple: your business, reviewed by AI, every morning. Rather than leaving you to interpret charts or open dashboard after dashboard, DailyHelm produces a daily brief that works as a prioritized punch list of the issues and opportunities worth acting on. It is built for founders, operators, and growth teams who run the whole business themselves — people who wear the marketing hat, the engineering hat, and the finance hat — and who need a clear answer to the question of what to do next. The problem DailyHelm addresses is the gap between data and action. Traditional dashboards show you charts and leave you to interpret them, which means hours of tab-switching and a lingering sense that you are still guessing. Real problems hide in that gap: conversion tracking silently breaks, ad spend keeps optimizing against zero conversion data, a top product disappears from the sitemap, a lead form stops firing, or failed payments quietly churn subscribers. DailyHelm was built to catch those issues and turn them into a ranked, evidence-backed list of things to fix, so days of wasted spend and lost orders do not go unnoticed. The review is produced by six specialists led by Aria. Each agent owns a domain. Iris covers analytics and growth — funnels, pipeline health, and churn signals. Pitch covers ads — spend, keywords, search terms, and CPA. Echo covers SEO — rankings, indexation, and on-page signals. Ada covers code, investigating your repository when business data smells off. Penny covers cost — cloud spend by SKU, cost forecasts, and egress leaks. Sage covers site UX — crawl-driven performance and conversion blockers. Aria correlates their findings, ranks them by expected impact, and writes the morning brief. Together they handle AI for business operations, monitoring ads, SEO, analytics, and code while you sleep. Each finding is delivered with the detail needed to act on it. Every finding cites its evidence and a recommended next step, along with an impact score, a confidence level, and an effort rating. In the product's example, Iris flags a conversion tracking blackout with 96% confidence, showing that GA4 recorded zero conversions while Stripe recorded 47 purchases in the same window, and pointing to the commit that removed the tracking include. The finding carries a recommended action, and you can accept it, snooze it, dismiss it, or chat with Aria to dig deeper into what broke and how to fix it. That structure means the digest does not just surface a symptom — it explains the cause and proposes the fix. Setup is designed to be fast and non-technical. DailyHelm handles the OAuth; you click approve. First you tell the system about your business — what you sell, who buys it, and what success looks like — which anchors every recommendation. Then you connect your platforms one click at a time: GA4, Google Ads, Search Console, Shopify, GitHub, GCP billing, and your site. DailyHelm opens the approval page and you confirm. From there you get a daily AI business review, a prioritized punch list every morning, with the option to chat with Aria any time. The company states average setup time is under five minutes and that findings start arriving within the hour, with first findings reachable within 24 hours. DailyHelm's overall approach is overnight monitoring plus correlation, delivered as a morning brief. It pulls a daily snapshot from each connected platform and stores nothing it does not need. The agents work in parallel across their domains, and Aria cross-references their individual findings to produce one ranked list. Because the system is built to be read-only on every connector, it never writes back to your accounts. OAuth scopes are read-only across GA4, Search Console, Ads, GitHub, and your store, so DailyHelm cannot write, post, or modify anything. Integrations use each platform's own consent screen rather than API keys, and onboarding happens through those approval flows. Users describe the outcome in terms of time saved and money recovered. One founder reported that Aria caught a $340 per day wasted-spend issue on day one, with a Shopping campaign running against 47 zero-conversion search terms for nine days; negatives were added before lunch and the bleed stopped the same morning. Another reported that a Friday deploy broke the GA4 purchase event, leading to $2,200 spent over a weekend with no conversion data to optimize against, and said that kind of thing will not happen again after setting up DailyHelm. A solo founder described replacing 90 minutes every morning across five dashboards with an eight-minute brief and one clear priority. DailyHelm reports early user ratings of 4.9 out of 5 and describes itself as a part-time COO that reads every dashboard so you do not have to, answering questions about your business in plain English. The product documents concrete categories of findings for different business types. For DTC and e-commerce, Pitch surfaces wasted ad spend — specific keywords or search terms burning budget with zero conversions — plus negative-keyword and bid recommendations to cap the bleed. For SaaS and app businesses, Iris and Ada detect a conversion tracking blackout where Stripe charges fire but GA4 shows zero, identifying the deploy that broke the tag and the line of code to restore. For local and service businesses, Echo surfaces a local-search ranking collapse in which "near me" and city-name queries fall out of the local pack. For dropshippers, Echo and Ada catch a top product disappearing from the sitemap or returning a 404 after a deploy. For B2B and lead gen, Iris, Ada, and Sage cross-reference a lead form that silently regressed after a deploy broke validation or the success-event fire. For subscription businesses, Penny flags a failed payment surge, including the dunning gap and recoverable MRR. DailyHelm is aimed at operators who run the whole business: DTC and Shopify founders, dropshippers, B2B SaaS operators, solo founders, agencies, and anyone short on time. It connects to Google Analytics 4, Google Ads, Google Search Console, Shopify, GitHub, Stripe, a Site Crawler, and Meta Ads, with GCP billing referenced during setup. The company offers a seven-day free trial, requires no credit card, and says setup takes about five minutes. On security, it states that all traffic to DailyHelm is TLS 1.2+ encrypted, data is encrypted at rest, and OAuth refresh tokens and webhook secrets are encrypted at the field level. It states that AI never trains on your data, that processing happens through providers contractually prohibited from training on it, and that the service is GDPR and CCPA compliant with rights to access, correct, export, and delete data. One click deletes your account, revoking every connected token and purging findings within 30 days. DailyHelm's value proposition is straightforward: stop opening eight dashboards every morning, get the punch list, pick the top three, and move on with your day — with every recommendation anchored to evidence from your own connected tools. It turns overnight data into a prioritized set of revenue-oriented fixes so founders and growth teams always know what to fix today.
Oogwai Beacon is Oogwai's answer engine optimization audit. It puts 20 real buyer questions about your category to the AI assistants your buyers use — none of them naming you — and records how often each engine names your brand, who it names instead, and which sources it relied on to decide. The free check covers ChatGPT and Gemini, while the paid audit adds Claude, and Perplexity is covered on the managed programme. Beacon measures the two things that determine whether you get recommended: whether AI crawlers can read your site at all, and whether the engines actually cite you when they answer. The first result lands on the page in seconds; the second arrives as a report in your inbox, with a ranked list of the sources worth being on next. Buyers have stopped searching in the old sense. A buyer evaluating your category used to type a query, scan a page of results and form their own shortlist. Now they ask an assistant, and the assistant hands back a shortlist that is already formed: three names, a sentence each, and a follow-up question. Whoever is not in those three names is not in the evaluation at all. Answer engines do not rank pages the way a search engine does. They assemble a reply from three things — what the model absorbed during training, what it retrieves live from the web at the moment of asking, and which of those sources it trusts enough to lean on. Your own website influences the first two weakly and the third barely at all, because when a buyer asks who the best vendor is, an engine will not settle the question by quoting the vendor. That is the gap answer engine optimisation works in: not keywords and rankings, but presence, corroboration and machine legibility, measured by whether you get named. Most AEO tools score your HTML and call it AI visibility; Beacon actually asks the engines. AEO has two halves, and only one of them is a technical problem. Most tools sell you a single number, and a single number hides the distinction that matters, so Beacon reports the two halves separately. Half one is readability: can a crawler read you at all? This check is pure HTTP with no engine calls, which is why it lands in seconds, and it answers whether GPTBot, ClaudeBot, PerplexityBot and Google-Extended can reach your pages and find anything on them. It examines robots.txt rules for each named AI crawler, whether pages are server-rendered HTML rather than an empty shell filled in by JavaScript, Organisation, Product and FAQ structured data, llms.txt and a machine-readable summary of what you sell, heading structure, canonical URLs and clean sitemaps, and consistent entity facts — one name, one description. The readability check is free, runs in seconds and requires no sign-up. Half two is citation: do the engines actually name you? Beacon puts buyer questions about your category to the engines in your tier — ChatGPT and Gemini on the free check, with Claude added on the paid audit — and none of them mention your brand, because a question that names you proves nothing. The report records how often each engine names your brand unprompted, which competitors it names instead and how consistently, the sources each engine cited to get there, what the engines believe you do (correct or not), the question types where you are strong and where you vanish, and a ranked list of the sources worth being on next. The free citation report, showing who ChatGPT and Gemini name instead of you, needs a free business-email account. The full citation report is usually in your inbox within a few minutes, and always within one business day. Which engines run depends on your tier. The free check queries ChatGPT and Gemini. The paid audit adds Claude, and Perplexity is covered on the managed programme, where Oogwai also tests regional variations and buyer personas. Claude grades markedly harder than the other two, so a two-engine result reads higher than a three-engine result — which is why the AEO score is reported only on the paid audit, where it is measured against the full set. The readability check and the two-engine visibility check are free with no credit card required, while the three-engine audit and the media and content programme sit behind the paid tier. Beacon's approach is deliberately different from tools that inspect markup and infer visibility. Because it asks the engines themselves, the audit produces two separate answers that can be read independently: can AI crawlers read your site, and do the engines recommend you? Every gap comes with the fix, and technical readability issues are usually a short engineering fix — Oogwai hands over the exact changes whether or not you work with them. A perfect readability score with zero citations is common, and it is the most useful result the audit produces, because it tells you the problem is not on your website. Being readable is not the same as being recommended. Fixing robots.txt takes an afternoon; getting named takes presence on the pages an engine reaches for when it is asked to compare vendors — roundups, review platforms, comparison pages, community threads, editorial coverage and transcripts. Almost never the vendor's own homepage. That is what the Oogwai media and content team works on, and the audit is the brief: every run records the exact domains each engine cited for your category, so the target list is evidence from your own market rather than a generic media plan. Source mapping starts from the citations in your report — which twenty domains ChatGPT, Claude and Gemini actually pull from when someone asks about your category, and which of them already mention your competitors — and that list becomes the workplan, re-derived every quarter because the sources move. Editorial placement covers contributed articles, expert commentary and product inclusion in the trade publications and roundups that keep appearing in those citations, written to the publication's standard and pitched on a real angle, with no syndicated filler. Review platforms include G2, Capterra, Product Hunt, Clutch, TrustRadius and category directories, with profiles completed properly, categories chosen deliberately and a steady review cadence, because engines lean on these surfaces for being structured, current and third-party. Comparison coverage targets "X vs Y" and "alternatives to X" questions, the highest-intent questions in any category, through honest comparison and alternatives pages on your site and third-party ones that already exist. Community answers cover Reddit, Quora, Stack Overflow, industry Slack and Discord recaps, disclosed as coming from you. Video and audio work turns YouTube descriptions, chapters, transcripts and podcast transcripts into retrievable, indexed text. Quotable owned content — original data, plain definitions, question-shaped headings, clear attribution and schema markup — is written so a model can lift one sentence and credit you for it, and it is the only part of the programme that lives on your domain. Entity consistency keeps one company name, one description and one set of founding and product facts across every profile, directory and press mention, because inconsistency splits you into two half-known entities. Measurement re-runs the same 20 questions monthly against all three engines, showing share of answers over time, which competitors gained or lost ground, and which specific placements moved the number — so the programme is judged on citations, not impressions. The engagement runs in four stages. Audit: 20 category questions across three engines, plus the readability pass, so you get the baseline before anything is promised — including the possibility that you are already being named and need less work than you thought. Map: the cited domains are turned into a ranked target list, weighted by how often each source is quoted, how hard it is to appear on, and whether your competitors are already there. Place: editorial, review, comparison, community and video work runs in parallel against that list, alongside the technical fixes the readability half surfaced. Measure: monthly re-runs of the identical question set, with share of answers as the metric, and any channel that does not move a number is retired rather than defended. The outcome Beacon aims at is a measured share of answers in the assistants your buyers actually use. Because retrieval-based mentions can shift within weeks of a placement going live — the engine reads the source at question time — while what the model itself has absorbed moves on the far slower training cycle, Oogwai reports both separately rather than blending them into one flattering number. That separation is what makes the audit actionable: a readability gap is fixed by engineering, a citation gap is fixed by presence on the pages engines trust. The audit is also a baseline you own, and the ranked source list is derived from your own market's citations rather than a generic media plan. Typical use cases follow the two halves. A marketing lead runs the free readability check with no sign-up to find out in seconds whether GPTBot, ClaudeBot, PerplexityBot and Google-Extended can reach their pages and find anything on them. A founder requests the free citation report to see which competitors ChatGPT and Gemini name instead when buyers ask about their category. An SEO or content team uses the ranked source list to decide where to pitch next. A product marketer builds comparison and alternatives pages for the highest-intent "X vs Y" questions. A brand with a perfect readability score and zero citations learns that the problem is off-site and starts a media and content programme. And a team under pressure to prove ROI re-runs the same 20 questions monthly to track share of answers. Beacon is built for the teams whose buyers now ask assistants instead of searching: marketing and SEO teams, founders, product marketers and content teams at companies that sell into a category where buyers compare vendors before they talk to sales. The free tier covers the ChatGPT and Gemini visibility check and the instant readability check, with no credit card required, though the free citation report needs a business-email account. The paid audit adds Claude and carries the AEO score measured against the full engine set; Perplexity, Copilot, regional variations and buyer personas are covered on the managed programme. Oogwai Beacon's value proposition is narrow and testable: instead of scoring your HTML and calling it AI visibility, it asks the answer engines what they say when your buyers ask about your category, shows how often you are named, who is named instead and which sources decided it, and pairs every gap with the fix.
devpit is a native desktop application for controlling the coding agents you run. Everything a session needs sits in one window: a chat pane, a terminal for each project, a board that holds the work, a running record of what every agent call cost, and an orchestrator that can see across every project you have linked. Today it drives Claude Code through the claude CLI you already have installed, while support for Codex, Cursor, Gemini CLI and opencode is described as coming. devpit runs on Linux, macOS and Windows, is free and open source, and is aimed at developers who run more than one agent at a time and want a single place to watch them all. Coding agents are powerful, but they are also noisy. Each one lives in its own terminal, and the moment you run more than one at once — a task in one repository, a review in another — you are switching between windows, losing track of which process is still alive, and guessing at what any given run has cost you. There is no shared place where the work being done is visible, and no natural place for an agent to stop and ask you a question. devpit exists to put all of that in one window, with panes side by side rather than tabs spread across six applications. Its guiding rule is that nothing advances on its own: an agent writes down what it did, and moving the work forward remains your call. The most basic pane is the terminal. It is a real pty behind tmux, which means you can split it, close the window, and find the same process still running when you come back. Beside it sits a chat that proceeds one turn at a time and shows what each turn cost, so a conversation with an agent is also a running account of what it is spending. Per project, devpit also offers capabilities — extra tools that open as panes next to the work; Notes and Excalidraw are the ones available today. Files, diffs and a browser are available in the same window, so you can review what an agent changed and look at the page it serves without leaving devpit. Because each terminal is held by tmux rather than by the visible window, and because each project has one target terminal, switching between pieces of work simply re-attaches the view to whatever you are looking at, while the previous session keeps running in the background. The board is where work is organised. It uses your columns in your order, and moving a card is what starts the work: the card is not a passive note, it is the trigger for a step. A step does not advance on its own. It writes down its output, its exit code and its real cost, and then it stops. Deciding to move on is yours, unless you have deliberately set a lane to move by itself, in which case the board shows that. Cost is tied directly to the board too: a spending cap on every call is set by the column the work sits in, and the card records the real cost of what ran. In other words, the column defines the ceiling for that stage of work, and the card reports what was actually spent. Above the individual project sits the orchestrator: a chat that reads every board you have linked, across projects. You can hand it a card and it starts a session for that card, then reports back to you. Alongside it, the Sessions panel lists every session on your account, with the ones waiting on you first, and you can answer them in place, as yourself. The island — a capsule that floats above your windows — shows what each agent is doing and lets you allow or deny from there. Agent state is expressed in words as well as visuals: thinking (started, before its first step), working, asking, waiting, done, failed and sleeping. There are also reminders that only remind: telling devpit to remind you at three to review a pull request means it will tell you then, and start nothing. The orchestrator has explicit limits: it never moves a card into a lane that runs a step, it never acts on a timer, and it never approves anything in another session. Any reply it drafts goes out only when you send it. Underneath, devpit is local-first. Everything it creates — the board, the panes, the terminal and the costs — lives in a workspace per project under ~/.devpit, so nothing lands in your repository: there is nothing to gitignore and nothing appears in the diff. A teammate can work alongside you without ever hearing of devpit. When a step needs a checkout, devpit makes a worktree for that line of work, and it never removes a worktree while it still holds uncommitted work. Sessions are designed to outlive the window: close devpit, reopen it, and what was running still is, because tmux holds the processes. Windows is supported through a per-user installer that brings psmux, the tmux of Windows, and the Linux build also runs in WSL 2. devpit is written in Rust and Tauri rather than being another Electron app, and each terminal is a real pty behind tmux, or psmux on Windows. The outcome for a developer is a single place to watch several agents at once, without losing any of them. Costs are visible per call and capped per column, so agent work does not become an unbounded bill. Sessions that wait on you are surfaced first, so time is not wasted hunting for the agent that has stopped and needs an answer. Because the workspace is separate from the repository, using devpit does not change your code base or your team's workflow. And because state is preserved — tmux holds the processes and the workspace persists per project — you can come back days later and find the board, panes, terminal and costs where you left them. Concretely, this plays out in several ways. When you are running agents on more than one project, each board gets its own workspace and you watch them all through one window. When an agent finishes a change, you review its files, its diffs, and the page it serves without leaving the app. When you want work kicked off, you hand the orchestrator a card and it starts a session and reports back. When an agent stops and asks a question, you answer it in place as yourself, with the sessions waiting on you listed first. When you are away from the machine, you can check on running work from your phone over Tailscale. And when you want a nudge rather than action, you set a reminder that tells you at the time and starts nothing. devpit is aimed at developers who use coding agents, and specifically at those who run Claude Code and find themselves managing several sessions or several projects. The agent it drives today is Claude Code, through the claude CLI you already have; other agents can report their status with the devpit-agent hook, and Gemini CLI does so with nothing to set up. Codex, Cursor, Gemini CLI and opencode are all listed as coming behind the same interface, and your own agents are markdown files. The tech stack is Rust and Tauri, with tmux as the process holder and psmux on Windows; optional remote checking is done over Tailscale by pairing a device with a one-time code and choosing what it may do, with nothing listening beyond your tailnet. devpit is free and open source under Apache 2.0, uses your existing Claude Code plan with no new API keys, and requires no account — an account today only signs you in, and sync, when it comes, will keep the workspace around your work rather than the work itself. devpit's value proposition is control: one native window for the coding agents you already run, a board that makes the state of the work visible, a cost on every call and a cap on every column, and an orchestrator that sees every project while never acting on its own. Free, open source, local-first, and out of the way of your repository.

Dots UI is a React animation library for morphable particle interfaces. It renders swarms of dots that can take on almost any form, and it treats a shape as a prop: the same particles morph into the next shape when a value changes. The library ships 171 particle shapes across assistant, productivity, media, commerce, and navigation, along with real UI components built from what the site calls "one living material." Developers can use ready-made components, customize their appearance and behavior, or create their own shapes in Studio. Dots UI is built for interactive interfaces, animated states, loaders, controls, visual effects, and UI that can transform from one form into another. The project is framed around the idea that interfaces should feel alive rather than static. The homepage opens with "A LITTLE LIFE. IN EVERY PIXEL" and the line "Every interface begins with small things. A letter, a shape, a moment of motion." The stated goal is to make products feel animated from the inside out: "Make the next thing feel alive." Instead of layering motion onto static components after the fact, Dots UI makes the particles themselves the interface — dots become the button, the slider, the switch. The site summarizes this as "A small API. A whole new surface," and describes the library as handling "real UI, and playful interactions" so that even the smallest visual elements carry character and movement. The foundation of the library is its shape system. Dots UI provides 171 particle shapes for React, and the core mechanic is that a shape is a prop. Changing a single prop causes the same dots to morph into the next shape, for example switching a swarm to a "wire-sphere" shape with a specified color, particle count, and height. Because the dots themselves animate between forms, smooth transitions come from the same particle field rather than separate animated assets. The library is positioned around that shift: "Every state. A little more alive." Beyond standalone shapes, Dots UI turns particles into working interface primitives. The site presents Button, Dropdown, Slider, Checkbox, and Switch as components that are built from the particle material, so interactive controls literally assemble themselves out of dots. The primitives are described as composable parts with Radix behavior and your own styles, meaning developers keep familiar component behavior and styling while the visual layer becomes particle-based. The page invites users to "Pick a primitive. Watch it come together" and shows an example with a SwarmButton inside a SwarmUI scene, where clicking a particle button triggers an ordinary click handler. Dots UI also extends the system into customization, texture, sequencing, and character. Studio is where users set color and speed, pause playback, or start from ready-made recipes such as an Assistant loop with a cloud shape, a Productivity calendar for planning the day, and a Commerce shopping bag for checkout. Textures let one shape take on different feelings — Chrome, Ink, Neon, and Glass — with chrome described as flowing silver reflections steered by pointer movement, and an on-screen note stating that this texture needs WebGL. Sequences let developers choreograph a run of shapes; the sample code builds a DotsSequence from cloud, microphone, thought-bubble, and neural-network shapes, each with a duration, and plays it through a sequence player using pro shapes. A separate set of particle actions drives reactive moments, illustrated by a dot avatar that responds when you interact with it, with the site promising "Give it a reaction" and "A thousand dots. One personality." Even words can wander: pressing a button gives a paragraph of text a new particle shape, so the same words become "a different kind of sentence." Under the hood, Dots UI is a React and TypeScript library distributed as the dots-swarm package, with UI extracted from dots-swarm/ui, styles from dots-swarm/ui.css, and pro shapes from @dots-swarm/pro. Its API is deliberately small: components such as DotSwarm, SwarmSurface, SwarmUI, SwarmButton, DotsSequence, and DotsSequencePlayer, plus handles and hooks like SwarmSurfaceHandle and swarmActions that let developers control particles from their own components. The site describes a pipeline of particles going through physics into a real button, which is why a single prop change can produce an entirely different silhouette. WebGL support is called out for richer surfaces, and the docs link to API pages for actions, usage, UI primitives, and sequences. For users, the benefit is motion that feels native to the interface instead of decorative. States become visibly different from one another, loaders and transitions carry personality, and controls stop looking like static rectangles. Because shapes are props, developers can change behavior and appearance incrementally — one prop, one new form — and because primitives are composable with Radix behavior, they can adopt the particle look without rebuilding their component logic. The site summarizes this as a small API that unlocks a whole new surface. Use cases follow directly from the examples shown on the site. Teams can use the dots for animated interface states that shift as an app changes mode, for loaders and transitions, and for controls such as buttons, dropdowns, sliders, checkboxes, and switches. Shapes can be used for visual effects, including textured surfaces like chrome, ink, neon, and glass. Sequences suit onboarding or assistant flows that move between a cloud, a microphone, a thought bubble, and a neural network. Playful interactions — a dot avatar that reacts, particles embedded in text, or a paragraph that reshapes itself on click — cover moments where a product wants to feel responsive and characterful. Dots UI targets React and TypeScript developers building interactive interfaces who want animated, particle-based visuals without assembling them from scratch. The entry points are the docs, the shape browser, the showcase pages for objects and textures, and Studio. Product Hunt lists it under Design Tools, Developer Tools, and Tech. Stack details visible in the content are React, TypeScript, Radix behavior for primitives, and WebGL for richer textures. Pricing is presented as "Free to start. More to play with," alongside a Get Pro option and pro shapes, indicating a free starting tier with a paid upgrade. In short, Dots UI turns particles into usable interface material for React. By making a shape a prop and rebuilding controls out of the same dots, it lets developers morph between 171 shapes, compose real UI primitives, design their own in Studio, and add texture, sequence, and character — so the next thing they build feels alive from the first pixel.
Jarq is a Mac app that acts on text right where your cursor already is, inside whatever application you happen to be using. Instead of copying text into a separate translator tab or assistant window, you select a passage, point at the dot that appears beside it, and choose an action: translate, shorten, fix, or rewrite. The result lands where you wrote it, replacing the selection in place. Jarq also dictates: you press a hotkey, speak, and finished text with punctuation and capitals appears at the cursor. It is built for people who write, read and answer messages all day on a Mac — in email, chat, documents or code — and who lose momentum every time they have to leave the app they are working in. Jarq exists because of a specific, repeated annoyance: every trip to a translator tab drops your train of thought. The website lays out the old way in seven steps — select the text and copy it, switch to a translator tab, paste and wait for the answer, copy the result, switch back, paste again, and then ask yourself where you were. That is seven steps and two app switches. Jarq reduces the same job to two steps and zero app switches: select the text, click a language button. There is a second, unplanned benefit the team highlights: because translations appear next to the original text in its real context, rather than in an isolated tab, words tend to stick, and phrases you translate today eventually stop needing a translator at all. The core interaction is minimal. Select text anywhere on your Mac and a small set of buttons appears right beside the selection — the product calls this the dot. From there you can translate, shorten or fix any text in the app you are in, and the answer lands where you wrote it. Where an application blocks text selection, Jarq has a fallback: the ⌥T hotkey grabs the text anyway, which the site says makes it work in places others cannot, naming Figma and terminals. Actions can be applied as a replacement in place, or copied for pasting elsewhere. Jarq runs from the menu bar and answers its keys wherever you are already typing. Translation is available for any selection across thirteen languages, including English, Russian, Spanish, Portuguese, French and German. You can translate between any two of them, or speak one language and get clean text in another — say it in Russian and English lands in the input. The site draws an explicit contrast between word-for-word translation and the way you would actually say it: Jarq aims for natural wording while keeping your tone intact rather than producing a literal rendering. Language buttons such as EN and RU sit beside the selection, and the site lists English, Russian, Spanish, French, German, Portuguese, Italian, Turkish, Kazakh, Arabic, Chinese and Japanese among its language options. Dictation follows the same in-place philosophy. You press ⌥ ` (Option plus backtick), talk, and press it again; polished text — punctuation and capitals included — appears right at the cursor of any app, whether that is Slack, Mail or your IDE. Dictation can also translate as you speak, so a spoken sentence in one language can land as written text in another. The site positions this against Apple's built-in dictation by noting that Jarq drops finished text into any app, can translate while you speak, and keeps working in the apps macOS dictation trips over. The microphone opens with the hotkey and closes when you stop, and the recording is not kept once it has become text. Beyond the built-in actions, Jarq lets you build your own buttons. You write an instruction in your own words — shorten this, fix the grammar, make it formal — and it becomes a button beside the language buttons, one tap away, listed alongside EN, RU, Shorten and a plus control for adding more. A notable design detail: selected text is never read as a command, only as material, so an instruction you have written is treated as the instruction and your selection is treated as the thing to be acted on. This keeps behaviour predictable when you are rewriting someone else's words, or text that itself looks like an instruction. Jarq is designed to stay out of the way and stay under your control. Every hotkey can be remapped, and your history stays on your Mac. The app installs as one file dragged into Applications, sits in the menu bar, and answers a key wherever you are already typing. The download page lists version 1.0 (84) at 15.1 MB, and the product is described as needing macOS 13 or later on Apple Silicon. Privacy is addressed directly on the site because, as the page puts it, an app that hears you and types for you owes you a straight answer about both. Two paths are described. On your Mac, history is a file on your own disk, and with on-device recognition your voice never leaves the Mac. In the cloud, a recording or a selection becomes text in memory and comes straight back — stored nowhere, trained on never. Jarq itself does not keep your text on its servers, and the microphone only opens with the hotkey and closes when you stop. A full privacy policy is linked from the site. Dictation through the optional on-device model is free and unlimited on every plan precisely because it never reaches Jarq's servers, so there is nothing to charge for. The outcome Jarq promises is continuity. Your flow stays intact: instead of a long chain of small context switches a day, there is one selection and one click. Writing speeds up too — you write the draft fast, then tap a sentence to make it shorter, cleaner or more formal, so a rushed first pass can leave the app already polished. Because translations appear in context, the site argues that words stick and repeated phrases gradually stop needing translation. And because actions are applied where the text already lives, there is no round trip through a browser tab or a separate assistant window: the same edits happen in place, in whatever app you are already working in. Four scenarios anchor the product on its website. The first is bilingual work: reading a message in one language and replying in another — the example is a Telegram conversation where a Russian message is read in your language and a reply goes out in theirs. The second is email: long drafts, typos and the wrong tone, handled by tapping a sentence in a Mail draft to shorten, clean or formalise it. The third is talking instead of typing — pressing the hotkey and speaking into Slack, Mail or an IDE and having clean text land in the field. The fourth is custom buttons: writing an instruction once and running it with a tap on whatever sentence is in front of you. A fifth case is any app that resists selection, where ⌥T reaches the text anyway, from Figma to a terminal to a PDF. Jarq is aimed at Mac users who work across languages and live in text: people who read in one language and answer in another, people whose email eats their day, and people who would rather talk than type. It is a native macOS app — the download requires macOS 13 Ventura or later on Apple Silicon (M1 or later). Pricing has three tiers. Free keeps working after the trial with 5 dictations or translations a day, unlimited on-device dictation, no account and no expiry. Pro is $4.99 a month or $39 a year for unlimited dictation and translation on up to 2 Macs, cancellable any time. A lifetime option at a $179 launch price (from $200) includes everything in Pro plus every future version, up to 2 Macs. Every install begins with 14 days of Pro at no cost, without a card or an account, prices are in USD with tax included, payment can be by card, PayPal or Apple Pay, and there are 30 days to change your mind. Jarq's value proposition fits in a sentence: translate, shorten, fix or rewrite any text right where your cursor is, in any app on your Mac — and dictate there too, without tabs and without copy-paste. Select, hit a hotkey, and the answer replaces the selection in place. Fourteen days of Pro are free, the free plan keeps working afterwards, and dictation can stay entirely on your machine.
iLand is a macOS menu-bar app that turns the empty space around your Mac's notch into a living hub for everyday tools. Instead of leaving that strip of screen unused, iLand fills it with the things you check all day: music, AirPods battery, weather, calendar and a drag-and-drop file tray. It is built for Mac users who want quick, glanceable access to everyday information without opening separate apps or breaking their focus. The app comes from CodeM Labs, described as an independent group of developers crafting lightweight, privacy-first apps for Apple platforms. Most of the information people check constantly on a Mac is scattered across multiple apps and menu-bar icons. Album art, accessory battery levels, the next meeting, local weather, a file you need to send to a nearby device, a quick screenshot — each of these normally requires its own app, window or menu. iLand's premise is that these small, frequent tasks should live in one calm place. Its own framing is "one quiet hub for the things you check all day," positioned against the clutter of jumping between windows and menu items. The notch, an area of the screen that currently does nothing on many Macs, becomes the natural home for that hub, and the site's closing line sums the idea up simply: give your notch a job. Music control is handled directly inside the notch. Users can control playback, scrub and skip right from the notch area, and album art spills into view the moment a track starts, so the currently playing song is visible without switching to a music app. Weather shows local conditions, including highs and lows, and updates quietly in the corner of the screen rather than demanding attention. Live Translation is built for quick language checks: you type on one side, read the result on the other, and swap the direction with a tap — aimed at the everyday situation where you know a word, but only in the wrong language. The battery widget keeps track of every device at a glance, showing real-time battery levels for your AirPods and accessories, so you can see what needs charging before you head out. The file tray is a shelf built into the notch: you drop files in, AirDrop them to nearby devices, convert formats on the fly, and then drag them anywhere. A built-in media converter is listed as part of both paid plans, which means format conversion happens inside iLand rather than through a separate utility. The AirDrop integration makes the tray practical for moving a file to another Apple device without hunting through Finder windows. Calendar and events keep your next meeting one hover away, with a join button that appears when it is time to connect. Widgets can be switched between, covering your calendar, weather, timers and more, so the notch can be shaped around what you actually check. iLand also includes a built-in screenshot and recorder tool for capturing screenshots and recording your screen, and both the monthly and lifetime plans list these features explicitly. Together, these widgets replace a set of small utilities that would otherwise each need their own slot in the menu bar and their own set of interruptions. iLand's approach is deliberately unobtrusive. It is hover-aware: the app stays out of the way until your cursor approaches, at which point it unfolds and reveals its widgets. That means the hub is available the moment you reach for it and invisible when you do not need it. Under the hood it is described as a tiny, signed menu-bar app built natively — no Electron, no bloat and negligible battery impact. Users can shape it themselves by reordering widgets, picking what shows, and choosing a liquid glass or dark appearance. The layout is described as customizable so everything stays within reach, and widgets can be switched with gesture controls. The stated benefit is speed and calm: instead of opening apps and windows, you hover, glance, and get back to work — the site's own formula is "Hover to expand. Glance to know. Get back to work." Because the data shown is glanceable rather than buried inside a workflow, iLand is positioned as a low-friction way to stay informed during the day. The native, lightweight build also means the utility itself does not become another resource drain on the machine, which matters for a tool that is meant to be always available. Everything is one glance away, and that is the core promise of the product. Concrete scenarios follow from its widgets. While working in a full-screen app, you hover the notch to see what is playing and skip a track without breaking focus. You glance at the weather widget to check today's local conditions and highs and lows before heading out. You drop a file into the tray to AirDrop it to a nearby device, or convert its format on the fly before dragging it wherever it is needed. You check real-time battery levels for AirPods and accessories. When a meeting is about to start, the calendar widget shows the next event on hover with a join button ready to use. You use the built-in screenshot and recorder to capture your screen, and Live Translation to look up a word in another language by typing it into one side and reading the result on the other. iLand is aimed at Mac users — the Product Hunt topics list Mac, Productivity and Menu Bar Apps — and the site targets macOS 13 and later, on both Apple Silicon and Intel Macs, with a download of approximately 30 MB. Pricing is simple and has no surprises: a free 7-day trial, then either a monthly plan at $1.99 per month offering full access, all iLand features, all future updates, the built-in media converter and the built-in screenshot and recorder, with a 1 device license; or a one-time lifetime purchase at $14.99 once, which keeps the app yours forever and raises the license to up to 3 devices. A FAQ section covers questions including whether a MacBook with a notch is required, which macOS versions are supported, whether it will slow a Mac down, how the free trial works, and whether data is private. iLand's value proposition is straightforward: give the notch a job. It gathers the small, frequently checked pieces of daily Mac use — music, weather, batteries, calendar, files, screenshots, translation and timers — into a single hover-aware hub that stays hidden until you need it, built natively so it remains fast, light and out of the way.
Opengeni is open-source AI infrastructure for putting agents directly inside your own product. It gives developers the pieces an agent needs to run reliably in production — durable sessions, isolated sandboxes, credentials, tools and MCP, memory, multi-tenancy and ready-made React components — and lets you either use the managed Opengeni cloud or run the same stack in your own environment. The purpose is stated plainly on the site: agents in your product, infrastructure out of the box. You focus on your agents, Opengeni handles the infrastructure, and the promise of the launch is shipping agents to production in hours rather than spending that time building plumbing. The project is released under Apache-2.0, its source lives on GitHub, and the site notes it is built from running agents in production, with Hydro, Havila and Posten shown as brands already working with it. Getting an agent demo running is easy; running agents for real customers is not. A single dropped connection can end a run. Agent code cannot safely execute next to your secrets. Every user needs their own OAuth tokens, and every API has to be wired before an agent can call it. Agents forget everything between sessions, and in a multi-tenant product every query has to know who is asking. Opengeni frames this as a list of things you do not have to build, and the site walks through each one in turn: durable sessions, sandboxes, credentials, tools and MCP, memory, multi-tenancy and model choice. Each of those is presented as a problem that would otherwise land on your team before the first real user ever touches the agent. Durable sessions are the first building block. Opengeni keeps a run alive when a worker restarts or a tab is closed: the run keeps going and resumes at the event where it left off, with the site's example showing a run resuming at event 128. Agent code then runs in an isolated sandbox, so it cannot run next to your secrets. In the example, the sandbox executes a Python script that detects a duplicate charge, and the credentials it uses are described as scoped and short-lived. That combination matters because agent work is often long-running and unpredictable: durable sessions turn a failure into a pause instead of a lost run, and sandboxes let you hand an agent real code execution without exposing production secrets to it. Credentials and tools cover the other half of the integration problem. Every user of your product needs their own OAuth tokens, and Opengeni handles that: the site shows Stripe, GitHub and Google Drive accounts connected per user, with tokens refreshed automatically over time. On top of credentials, Opengeni lets you plug tools in from an existing API definition — an OpenAPI file such as billing.openapi.yaml yields callable operations like invoices.list, refunds.create and customers.get, and the site presents adding three tools as a single step. Tools and MCP are both supported, which means an agent can act on the systems your customers already rely on rather than only talking about them. Memory, multi-tenancy and model choice complete the core. Memory is built in, so agents learn from past sessions instead of forgetting everything between them; the examples separate workspace-level memory (refunds go to the original card), user-level memory (sends invoices by email) and entries flagged to review first (bills in EUR from April). Multi-tenancy keeps customers apart, with distinct workspaces such as Acme, Globex and Initech and row-level security so that every query knows who is asking. Model choice stays open: OpenAI, Azure OpenAI, OpenRouter or your own OpenAI-compatible endpoint are all listed, and Opengeni states that you can swap models freely as better ones ship, without being locked in. Opengeni's overall approach is that the same session can appear on any surface, because every surface is a client of the same API. The site shows three of them. First, the Opengeni app at app.opengeni.ai, where a session can be started and tracked, including a completed example run that lists each step the agent took. Second, your product, shown as a billing assistant embedded in a customer's billing page, where the same session runs under your own brand. Third, the code, where a React component such as BillingAssistant.tsx is assembled from the @opengeni/sdk and @opengeni/react packages, using OpenGeniClient, OpenGeniProvider and SessionConversation. The client talks to your backend, and the documentation notes that your backend holds the API key and proxies the session routes so the key never reaches the browser. The React components are designed to be restyled quickly. The site lists a five-step customization flow: one variable recolors every surface through your accent, corners can be sharp, soft or round, you can use the font you already ship, and a single attribute flips between light and dark themes. The sample CSS shows custom properties for accent color, radius and font family, and an interactive control panel lets you try accent, corner, font and theme options directly. Because these are the same packages the Opengeni app is built on, the streaming responses, tool steps and composer come with the component rather than having to be rebuilt, which shortens the work between having a working agent and having it appear inside your product. The outcomes Opengeni emphasizes follow directly from those pieces. Sessions that recover from failures mean a run is not lost to a restart. Sandboxes mean agent code does not run beside your secrets. Handled credentials mean each user's own OAuth tokens are managed and refreshed. Tools and MCP mean APIs are wired from an existing definition instead of by hand. Memory means agents carry learning across sessions. Multi-tenancy and row-level security mean customer data stays separated. Model freedom means a better model can be adopted without a rewrite. The launch description also highlights 100+ integrations, human approvals and visibility into every step and dollar spent, so teams can see what an agent did and what it cost. The concrete workflows on the site are customer-support and billing shaped. A customer asks why they were charged twice in March; the agent lists invoices, runs a duplicate-detection step, confirms the duplicate and issues a refund, then explains that two $49 charges landed on March 12 and the duplicate is going back to the card. The same exchange is shown inside a branded billing assistant, with a confirmation that $49 was refunded to a card ending in 4242. Other listed session examples include a weekly churn summary, updating a refund policy document and triaging failed webhooks — all presented as work an agent can carry out inside the same environment, with the steps visible as they happen. Opengeni is aimed at developers and product teams who want agents inside their own product rather than in a separate tool. The integrations shown are Stripe, GitHub and Google Drive, alongside the broader mention of 100+ integrations and support for tools and MCP. The stack is open source under Apache-2.0 and can be self-hosted with a Helm chart on any Kubernetes, with Terraform for AWS, Azure and GCP; the repository is cloned from GitHub. Two deployment paths are offered: the managed Opengeni cloud, where you pay model cost plus 5%, or your own cloud running the same Opengeni API, workers and web app. Self-hosting is free, and a launch promotion gives the first 100 users $100 in cloud credit with the promo code PRODUCTHUNT100. The takeaway is straightforward: Opengeni is infrastructure for agents that actually finish the job. It packages the parts that are tedious and risky to build — durable sessions, sandboxes, credentials, tools, memory, multi-tenancy and model swapping — behind an open-source stack with React components you can restyle in seconds. You can start in the Opengeni cloud or keep everything in your own Kubernetes, and the same session can run in the Opengeni app, inside your product, or straight from your code, all on one API.
FastRouter.ai is a unified AI gateway and control plane for developers and enterprise teams building with large language models. It routes every request to the right model across more than 200 LLMs through a single OpenAI-compatible API, optimizing for cost, latency, quality, and reliability. The product gives organizations one consistent way to reach leading models including Claude Fable 5, Gemini 3.1 Pro, GPT-5.5, Grok 4.3, Veo 3.1, Nano Banana, and Claude 4.8 Opus, without integrating with each provider separately. Teams point their existing OpenAI SDK at FastRouter's base URL and immediately gain intelligent routing, automatic failover, built-in governance, and observability from a single high-performance gateway. It is positioned as the fastest gateway for every model, covering text, image, video, embeddings, and speech, and it lets teams add or swap models without code changes. Building with LLMs has become a multi-provider problem. New models arrive every few weeks, and benchmark results rarely tell the full story for a specific application, so the best model for a given task changes frequently. Teams that hard-code a single provider run into vendor lock-in, unpredictable spend, and outages they cannot control. One FastRouter user, Dr. Rishabh Bhandari of Medisha, explains that with new LLMs coming out every few weeks and benchmarks not giving the full picture, they rely on FastRouter.ai to optimize the cost-versus-quality balance. Another user, Sainath Gupta of Knit Finance, highlights that reliable access to models across providers removes the worry about outages or vendor lock-in. FastRouter addresses this by sitting between applications and model providers, giving teams a single point of access where they can compare models, control spend, and keep applications running when a provider degrades. The stated goal is to let teams scale AI apps without vendor lock-in or code changes. The foundation of the product is unified access. FastRouter provides an OpenAI-compatible API across different providers, so existing OpenAI SDK code keeps working while gaining access to many models. The gateway covers text, image, video, embeddings, and speech workloads, and it allows teams to add or swap models without code changes. Enterprises get access to top models such as Claude Fable 5, Gemini 3.1 Pro, GPT-5.5, Grok 4.3, Veo 3.1, Nano Banana, and Claude 4.8 Opus from a single API. This matters because it removes the need to maintain separate integrations, keys, and code paths for each provider, and it means a model change is a configuration change rather than an engineering project. Smart routing is the mechanism that keeps quality high while controlling spend. FastRouter routes every request to the best LLM based on cost, latency, and output quality with no manual tuning required. Its Auto Router chooses models that deliver the highest accuracy and relevance for the request under a cost-optimized policy. A low-latency policy selects the quickest model available to keep experiences smooth and responsive, while a high-throughput policy prioritizes models that handle high request volumes at scale. Intelligent cost optimization adds smart routing to cost-efficient models, prevention of unnecessary premium model usage, and batch processing for high-volume workloads. Together these capabilities help teams reduce AI spend while still matching each request to an appropriate model. Reliability and governance are built in. FastRouter provides automatic retries across providers, fallback models when failures occur, and virtual model lists for seamless failover. Instant failover automatically reroutes requests to other healthy providers for the chosen models, fallback lists let teams define prioritized fallback models so requests continue seamlessly, and aggregated capacity across providers supports higher rate limits. On the governance side, the platform offers project and API key limits, member roles and access controls, and protections designed to prevent spend shocks and bill spikes. Consolidated dashboards and alerts give complete visibility across every model, provider, and project, with powerful filters for cost, latency, and errors, plus alerts for usage and spikes. Observability and model comparison round out the platform. FastRouter tracks usage, latency, errors, and costs across all models with real-time metrics and detailed logs. Unified metrics monitor performance, latency, and error rates across models and providers; an activity log gives clear visibility into usage and performance for each request; and ongoing evaluations monitor model outputs to ensure consistent quality and performance. The Model Council and Playground let teams compare latency, output quality, and cost across models in interactive playgrounds, combine multiple models to cross-check outputs and reduce errors for stronger reasoning, and use the strengths of each model to deliver consistently better results. Insights adds a weekly read-only pass over the traffic you already route, producing a ranked list of changes, each with the sampled requests, the savings math, and the exact screen where you make the change. FastRouter's overall approach is one API for every model, production ready. Developers point the OpenAI SDK or a direct API call at the FastRouter base URL, https://api.fastrouter.ai/api/v1, supply a FastRouter API key, and select a model ID, so the integration looks like a standard OpenAI chat completions call in Python or TypeScript. Virtual model lists let teams mix providers and models into a unified model alias with policy-driven selection. Beyond routing, the platform covers evaluations, guardrails, alerts, and virtual model lists. For organizations with stricter requirements, FastRouter can be self-hosted in your own cloud so that prompts, responses, logs, and provider keys never leave your network, available on the Enterprise plan with the team helping on deployment and upgrades. The benefits follow directly from that architecture. Teams reduce AI spend through intelligent routing, batching, and model controls; they protect against spend shocks and bill spikes with limits and access controls; and they keep AI applications running with automatic failover, multi-provider redundancy, and intelligent traffic routing. Because the API is OpenAI-compatible, developers get drop-in integration with fast routing and built-in failover, while engineering leaders control costs without compromising reliability or scale. Product teams gain actionable insights to power faster, smarter AI product development. Crucially, users report that reliable access to models across providers removes the worry about outages or vendor lock-in, which is the central promise of the platform. Concrete use cases appear throughout the product. A team unsure which LLM suits its use case can play with models in the playground, compare them against each other, and then call normal OpenAI-compatible APIs to use the chosen model. A high-volume workload can be routed to cost-efficient models and batch processed to lower spend. An application that depends on a model which becomes slow or unavailable can rely on instant failover and fallback lists to keep serving requests. An engineering leader can set project and API key limits plus member roles and access controls to prevent spend shocks across teams. Teams can run evaluations and guardrails to validate and monitor inputs and outputs for safety, compliance, and consistency. Finally, an organization with strict data requirements can self-host the gateway so prompts, responses, logs, and provider keys never leave its network. FastRouter is aimed at developers, engineering leaders, and product teams inside organizations that build with LLMs. Developers get drop-in OpenAI-compatible APIs with fast routing and built-in failover; engineering leaders get cost control without compromising reliability or scale; product teams get actionable insights for faster, smarter AI product development. The site states that FastRouter is trusted by teams at Media.net, Amazon, Optum, GlobalFoundries, Verticurl, and Supaboard, and describes it as forged from the insights of high-performance engineering organizations. Getting started requires no set-up fees, no monthly minimums, and no credit card: new users receive millions of tokens in free credits to build, test, and explore the unified API, and a self-hosted deployment is available on the Enterprise plan. In summary, FastRouter.ai turns the messy reality of many model providers into one coherent gateway. It combines a single OpenAI-compatible API across 200+ models with smart routing for cost, latency, quality, and throughput; automatic failover and fallback lists for uptime; governance controls for spend; and dashboards, logs, evaluations, and weekly Insights for visibility. The primary value proposition is straightforward: route faster, scale smarter, and build better AI apps by sending every request to the right model without vendor lock-in or code changes.
Pilot5 Legal is an adversarial intelligence platform for legal teams. It takes a legal question and has five independent frontier AI models analyse it separately, challenge one another's reasoning, and converge on a structured recommendation — while the strongest opposing view stays on the record. The product covers five legal workflows: reviewing separation agreements against statutory requirements, understanding unfamiliar contracts clause by clause, pressure-testing settlement positions, retrieving enacted statutory text, and applying a firm's approved playbook to future reviews. It is built for lawyers who need answers that can survive challenge, not merely fluent answers, and every result carries its sources, its dissent, and the reasoning behind the conclusion. Every review is scoped to United States law. The product's own framing of the problem is direct: a fluent answer is easy to produce, but a defensible one needs the source, the opposing view, and a record of how the conclusion was reached. Single-answer AI tools typically deliver a confident paragraph and leave out the challenge, the authority behind the claim, and the uncertainty attached to it. For legal work that will be reviewed, negotiated, or tested, that omission matters. Pilot5 Legal is positioned as 'a different standard of answer', designed for work that will be challenged. Its designers state that Pilot5 adds primary-source research, citation verification, contract analysis, and transparent reasoning designed to help lawyers inspect, challenge, and verify AI output. The tool's premise is that the lawyer remains the decision-maker and the reviewer of record, and that the record itself is part of the product. The defining difference is that Pilot5's models do not merely answer — they answer one another. Five models first form positions without seeing one another (blind first analysis). They then engage in anonymous cross-critique, where they challenge assumptions and answer objections, followed by reasoned revision under pressure, and finally synthesis plus a minority report. The final view follows that argument rather than being an average of five first drafts. In the completed Chapter 7 preference dispute shown on the site, the panel moves from a question — litigate the $1.2M preference claim or settle? — through rounds of cross-examination. The Engineer's initial position recommends building and litigating only after a six-week forensic payment audit, otherwise settling at 35 to 45 cents; the Contrarian challenges the legal premise by arguing not to assume the affirmative defences; the Counsel challenges both positions and reframes the dispute around what the payment record can prove; the Architect revises to make payment timing, new-value offsets, and defence cost the settlement gates rather than a fixed dollar anchor. The sharpest remaining disagreement is sent to a separate tie-breaker round. The five perspectives are deliberately distinct. The Architect supplies structure, benchmarks, and operational logic. The Counsel brings evidence, nuance, and legal clarity. The Strategist weighs long-range value and trade-offs. The Engineer tests feasibility and failure conditions. The Contrarian is mandated to present the strongest case against consensus — the model required to argue against you before the panel converges. The site presents an interactive product walkthrough of a completed deliberation in four stages: Analyze, where five models form independent positions on the same question; Challenge, where each model tests the reasoning and assumptions of the others; Resolve, where a tie-breaker addresses the panel's sharpest disagreement; and Synthesise, where the final view preserves sources, limits, and dissent. Users can open every round of a completed Chapter 7 preference dispute, from independent analysis to final synthesis, and expand the walkthrough to full screen. Five legal workflows are offered, each a focused tool for a specific task. Statutory review checks a separation agreement against selected statutory requirements and shows the provision behind each finding, delivering an annotated agreement in Word so the lawyer can see exactly which requirement supports each flag. Contract understanding helps a lawyer get oriented in an unfamiliar contract by producing a clause-by-clause map, quoting the source wording verbatim, and identifying skipped material — so nothing is silently dropped from the analysis. Both workflows keep the underlying text intact rather than paraphrasing it, which supports the product's claim that every claim should have a path back to the text. Settlement range pressure-tests both sides' positions and exposes a settlement range that costs each side something. It produces five independent positions, checks statutory claims, and preserves dissent, so the lawyer can see what each side must give up rather than only what their own client wants. Statutory authority lookup retrieves the enacted text: a lawyer pastes a citation and gets the publisher's own words without a generative model involved, with up to 25 citations handled, the official source and retrieval date attached, no generated text, and unresolved citations left unresolved. Firm playbook makes a firm's position repeatable by adding approved firm positions to the statutory baseline used in future reviews; human approval is required, the statutory baseline remains, and approved positions are reused in future reviews. Three principles govern the quality of every answer. First, source: primary law is fetched from the publisher's text and analytical inference is marked separately, so confidence never masquerades as authority. Second, challenge: five independent perspectives analyse the question before they can influence one another, and the strongest dissent stays visible. Third, record: every source, finding, challenge, and limitation travels with the outcome, and the lawyer remains the decision-maker and the reviewer of record. The site summarises the principle as 'the record is the product'. Claims keep their sources, with authority and inference visibly separate; silence never means clearance, so unresolved and unexamined issues remain explicit; dissent remains visible, with the strongest opposing view travelling with the result; and human decisions remain on record, so accepted, rejected, and overridden findings carry into the review output. Security is treated as a requirement for client work. Client matters are never a training asset: no cross-account use and no model training. Data is encrypted with AES-256 at rest across tables, WAL, and backups, and encryption cannot be disabled. There is a right to erasure with hard delete across all tables, and retention is published per data class. Data flows through zero-retention routing, where frontier models run on no-retention endpoints and models without one are excluded; pseudonymization happens before inference, with identifiers tokenized and then re-identified in the response; and transport uses TLS 1.3, AES-256-GCM, and forward secrecy. Firms can require a Zero Data Retention mode with ephemeral processing and no outcome logging, disclosure of every sub-processor with role, region, and transfer basis, in-region deployment with BYOK and sovereign hosting on demand, and a DPA (Art. 28) under NDA. Every review is scoped to United States law, no other jurisdiction is consulted, and that disclosure travels with every deliberation record. The stated benefit is an answer a lawyer can defend. Rather than a single confident draft, a team gets a structured recommendation with a preserved opposing view, checkable citations that link to publisher text, visible limits, and an inspectable record of how the panel arrived at its conclusion. The adverse case is argued as part of the work, so weaknesses surface before the matter is committed to. The authority can be checked, and anything unresolved stays unresolved rather than being smoothed over. The limits remain visible: sources, inference, dissent, and scope all remain available for review. Because accepted, rejected, and overridden findings carry into the review output, the product supports a review trail rather than replacing reviewer judgement. The workflows map to concrete matters. Reviewing a separation agreement for what it omits, against selected statutory requirements, with the provision behind each finding. Getting oriented in an unfamiliar contract through a clause-by-clause map that keeps the source wording verbatim, and spotting material that was skipped. Deciding whether to litigate or settle a claim — the site's example is a Chapter 7 trustee demanding $1.2M from a supplier client under 11 U.S.C. §547(b) — by pressure-testing both positions and exposing a settlement range. Retrieving the enacted text of a statute from a citation without a generative model. And making a firm's approved positions repeatable across future statutory reviews. The site's own framing of cost puts a statutory review at roughly fifty cents and pressure-testing a settlement position at about four dollars in credits. Pilot5 Legal is aimed at lawyers, legal teams, and firms with client matters and confidentiality duties, from occasional individual matters through busy practitioners to small legal teams and firms or legal departments. Deliberations can be run from MCP setup inside tools including Claude, ChatGPT, Cursor, Perplexity, Mistral · Le Chat, and Microsoft Copilot Studio, and data can be brought in from sources such as Slack, GitHub, Notion, Google Drive, Jira, Confluence, Linear, GitLab, Stripe, Zendesk, Sentry, PostgreSQL, Zotero, Finnhub, EODHD, Twelve Data, Indian Kanoon, OpenCorporates, Docket Alarm, UniCourt, Clio, SharePoint, and NetDocuments. Every plan includes all five legal workflows; authority lookup and firm playbook are free, while contract understanding is 0.2 credits, statutory review 0.5 credits, and settlement range about 4 credits. Paid plans run from Starter at $29/month for 30 credits up to Business at $999/month for 1,750 credits, with unused credits rolling over for 12 months. Pilot5 shows the credit estimate before a paid run and refunds any unused reserve when it completes, with no daily caps or feature-gated plans. Pilot5 Legal's primary value proposition is adversarial rigour applied to legal questions: five independent models that argue with each other, one mandated to argue against you, the strongest dissent preserved, sources separated from inference, and a recommendation that arrives with its reasoning attached. For work that will be challenged, it offers a defensible answer rather than a fluent one.
Reviu is a native desktop application built for reviewing the code that coding agents write. Instead of treating an agent's output as a disposable chat log, Reviu turns each task into a durable session with its own conversation, branch, terminal, checkpoints, file edits, and review queue. Developers start an agent such as Claude Code or Codex, watch the session, inspect every diff, send line comments back to the agent, and then stage, rebase, commit, and push with real Git underneath. The app is aimed at developers who already drive agent CLIs on their own machines and want a structured review layer between the agent's work and the branch that eventually lands in their repository. Agentic coding changes where the bottleneck sits. The agent can produce a large diff quickly, but someone still has to read it, question it, and decide what belongs in the branch. That review step is usually spread across terminal windows, a chat transcript, a separate Git client, and a browser tab full of pull request threads. Reviu was rebuilt from a Git client with an agent panel into a review workspace for coding agents, so the review of agent output happens in one place before the work becomes history. The core local agent review loop stays free, while GitHub pull requests, reviews, checks, merge, and notifications are the Pro layer. Each task in Reviu becomes a durable session rather than a disposable chat. A session keeps its own conversation, branch, terminal, checkpoints, file edits, and review queue, and you can switch between sessions without stopping running agents. Parallel worktrees keep multiple agent tasks out of your main checkout, so one task cannot dirty another. Attention states show at a glance which sessions are running, waiting, failed, or ready for review, and readable agent activity groups commands, reads, edits, permissions, and failures as reviewable events. Running several agents at once therefore stays organised instead of turning into a pile of interchangeable terminal tabs. Diff review is the centre of the app. You inspect the diff produced by the agent, with file, line, and side context, and leave line comments that are sent back to the agent. Comments can be batched rather than sent one by one, so a review queue such as three selected comments on a file becomes a single message to the agent. The agent can then address them, for example fixing a discount order, adding a rounding test, or renaming an unclear helper. Because the comments carry the exact file, line, and side context, the fixes are anchored to the code being discussed instead of being described in prose. Reviu keeps real Git nearby so that review decisions become commits. You can stage the hunks you trust, unstage another pass, and restore the rest. Branches can be cleaned before a pull request exists by squashing, fixup, dropping, and reordering commits. Messy states are recoverable: resolve conflicts, continue rebases, stash work, cherry-pick, and undo mistakes. Every surface follows the checkout, so changes, history, terminal, and review all reflect the same branch, and Git actions such as commit, amend, push, force push with lease, interactive rebase, and pop stash are available from the same keyboard-first command palette as the rest of the app. Reviu Pro adds GitHub without losing local context. A pull request dock shows your branch's pull request alongside the agent session, working tree, and review threads, and Reviu finds the pull request for a checked-out branch or helps create one from the header. GitHub diffs can be opened in the editor, commented on inline, replied to in threads, and submitted as a full review. Merging follows GitHub conventions with squash, merge, or rebase using GitHub's generated title, message, bullets, and trailers, and checks and review status are visible before you act. An inbox surfaces notifications such as requested changes, finished CI, and replies, and a browser extension adds Open in Reviu to GitHub pull requests in Firefox and Chrome so a pull request can be opened as a local checkout ready for diff review, files, and terminal. Underneath, Reviu is a fully native desktop app built with Rust and GPUI, a Rust-based GPU-accelerated UI framework, with no Electron and no webview. It does not run agents in the cloud: Reviu launches the agent CLI you already installed and signed into, so the agent runs as a local process on your machine and your code stays local. Agents come from the official Agent Client Protocol registry, which includes Claude Code, Codex, Gemini, Copilot, Cline, and about twenty others. Because Reviu drives the CLI you already have, agents run with your existing subscription, there is no API key to paste, and there is no agent meter. The practical benefit is that agent work stops being a raw dump of changes and becomes a branch you own. Review happens before the work lands, comments travel back to the agent with precise context, and the final steps of staging, rebasing, committing, and pushing happen in the same window instead of a chain of separate tools. Cleaner history means the commit that reaches a pull request reflects decisions you actually made. If you already have Git tooling you like, Reviu is designed to sit alongside it as the missing agent review layer rather than replace it. A typical workflow starts with an agent session for a feature such as checkout discounts: the agent works in its own worktree, and you review the resulting diff line by line. Selected comments are batched and sent back to the agent, which makes the fixes, after which you stage the hunks you trust and clean the branch with an interactive rebase before pushing. Running several sessions in parallel covers tasks like adding percentage discounts, fixing tax rounding, and writing cart property tests at the same time without one task dirtying another checkout. For developers working through GitHub, you can open a pull request from the inbox, review its diffs locally, submit the review, and merge with a squash, merge, or rebase commit. The browser extension covers the reverse entry point: spotting a pull request on GitHub that needs local review and opening the branch in Reviu. Reviu is for developers who already use coding agent CLIs and want to review their output before it becomes a commit. Local agent review is free and includes agent sessions with ACP registry agents, parallel worktrees and durable session state, diff review with comments sent back to the agent, and local Git covering stage, rebase, conflicts, and terminal. Pro costs $9 per month or $79 per year, saving 27%, with a 14-day free trial and cancel anytime, and adds the pull request dock with checks and merge, GitHub review comments and submit review, inbox notifications, and the browser extension. Reviu runs on macOS for Apple Silicon and Intel, Windows for ARM64 and x64, and Linux through a terminal install command. No account is needed for local sessions; signing in is only required for the GitHub integration in Pro. Mobile access and remote over SSH to servers and VPS are listed as planned. In short, Reviu gives developers a review workspace for the code their agents write: run the CLI you already use, inspect and comment on every diff, send fixes back to the agent, and finish the branch with real Git, while Pro connects that local flow to GitHub pull requests, checks, merge, and notifications.
Siteprint is a Safari extension for Mac that measures the design of any website and turns those measurements into one exact prompt for a coding agent. Open a site in Safari, click Siteprint, and it measures the page's colours together with their roles, the type scale, the spacing, the corners and the layout. Inspect shows the palette, the typography and a blueprint of every section. Generate copies one prompt containing the exact values, so an AI coding agent can build a new page from it. The product is made for people who think in references — designers and developers who see a design they love and want to hand it to their AI rather than describing it from memory. Design inspiration is easy to find and hard to use. You can look at a site and admire it, but the thing you actually need in order to rebuild it — the exact colours and their roles, the precise type scale, the spacing rhythm, the corner radii, the layout structure — is buried in a browser you cannot easily measure. That gap is what Siteprint fills, and its position is explicit: real values, not vibes. Rather than asking an AI to imitate a look from a vague description, you give the agent measured numbers. This matters because coding agents such as Claude Code, Cursor and Codex produce more usable output when the instructions are concrete, and design values are exactly the kind of detail that gets lost when a person tries to describe a page in prose. The free tier is built around Inspect, which measures a page rather than guessing at it. Clicking the extension reads the page's colours and shows each one with its role, so you see not just a swatch but what that colour is for. It measures the type scale, the spacing and the corners, and produces a blueprint of every section on the page so the layout structure is visible at a glance. Alongside this, the free tier includes an eyedropper and a grid overlay for checking values on screen, token export so measurements leave the extension in a usable form, and Your Library, where scans are kept. The measured palette and typography can be reviewed inside the extension itself — the product's own screenshots show a palette with roles, font families and a page blueprint. Pro unlocks Generate, the step that turns measurements into something an AI agent can act on. Generate copies one prompt containing the exact values measured from the page, so the agent receives the design in a form it can build from rather than a description it has to interpret. Pro also produces DESIGN.md and themes. A DESIGN.md is a plain-text design specification: the example export published by the product lays out a design direction under headings such as Colour — with named values like Canvas, Surface, Text and Muted — Type, with display and body sizes and weights, and Shape, listing radii. That structure turns a website's visual language into a written document an agent can read before it writes any code. Compose is the other Pro capability, and it is where measurement becomes authorship. Compose mixes two saved sites into a new style. Siteprint's own illustration of this shows Stripe's colours being combined with Linear's type and layout, so the result is neither of the originals but a distinct combination built from measured ingredients. Because both source sites have been measured rather than eyeballed, the mixture still resolves to real values — you get a palette, a type scale and a layout that came from somewhere specific, not a mood. For anyone building a brand or a product surface, this offers a way to derive a new style from references you already trust. Pro also lets your AI read your scans directly. In the extension you open Generate, then Coding agents, and follow the setup for Claude Code, Cursor or Codex, after which those tools can read a Siteprint scan instead of waiting for a pasted prompt. Siteprint states that it works with Claude Code, Codex, Cursor, Lovable and, more broadly, any AI. Separately, on Macs that have Apple Intelligence, the extension adds Ask the design anything: it reviews each scan and answers your questions about the design, for example how to match a particular look. Apple Intelligence is not required — the product states that everything works without it. The workflow is deliberately short: three clicks. You open any site in Safari, click the crow — Siteprint's mascot, used as the extension's button — and paste into your AI. The paste step is shown as a prompt beginning "Build this in my style", which is the handoff point between measurement and construction. Getting to that point takes about a minute: install Siteprint from the Mac App Store, turn it on in Safari Settings, and click the crow on any site. Siteprint is clear about where its responsibility ends: it does not build the site for you. It measures the design, and your coding agent builds from the prompt. The benefits follow from measurement. You get real values rather than approximations, which means the prompt you hand to an agent contains the same numbers the original site uses — the colours and their roles, the type scale, the spacing, the corners, the layout. Because Compose works on saved scans, you can produce a style that borrows deliberately rather than accidentally. And because the extension runs on your Mac, there is no account, no tracking and no uploads: your scans stay local. Pricing reinforces the same idea — a free tier for inspection and a single $9.99 Pro purchase, described by the product as pay once, keep it, rather than a subscription. Concrete uses follow the workflow. A developer who admires a site's interface can inspect it, take the prompt and have an agent rebuild an equivalent page in their own product's style. A team that needs a pricing page can hand a Siteprint scan to an agent and let it build from measured values — one of the product's screenshots shows exactly that, a coding agent reading a Siteprint design and building a pricing page. Someone defining a new visual direction can use Compose to blend two references, for instance one site's colours with another's typography and layout. And a designer who wants to know how a look is achieved can ask the design directly on a Mac with Apple Intelligence. Siteprint is a Safari extension for Mac, so its audience is Mac-based designers and developers — particularly those already working with AI coding agents. It requires macOS 14 or later. The product states plainly that there is no Chrome version and no iPhone version yet. Pricing has two parts: a free tier covering colours, type and layout, the eyedropper and grid overlay, token export and Your Library, and a Pro tier at $9.99 once that adds the one exact prompt, DESIGN.md and themes, the ability to mix two sites, and agent access so your AI can read your scans. Support is by email and a published setup guide. Siteprint's value proposition is narrow and complete: it measures a design instead of describing it, then hands the numbers to your AI. Free to inspect, $9.99 once for the prompt, the DESIGN.md, Compose and agent access, running locally on your Mac with no account and no uploads.