Category Focus/categories/developer-tools
Developer Tools AI Tools
Discover and compare the best developer tools AI tools and software. Browse 567+ curated tools with reviews and rankings.
Projects tracked
567
Sort mode
RECENT
Page
1
Discover and compare the best developer tools AI tools and software. Browse 567+ curated tools with reviews and rankings.
Projects tracked
567
Sort mode
RECENT
Page
1
Clippo is a visual orchestration canvas for Windows that turns software development into a command room where you act as the tech lead and your AI coding agents work together in parallel. Instead of wrestling with dozens of lost terminal tabs or repeatedly copy-pasting the same briefings, Clippo gives you an infinite canvas where you assemble your AI dev team, delegate tasks, and monitor code progress in real time, arranging your workspace however you like. It is built for developers who already use AI coding agents day to day and want a single screen to coordinate them, watch what they are doing, and keep every piece of project context in one place. The problem Clippo addresses is fragmentation. When you run several AI coding agents at once, each one typically lives in its own terminal tab, and the moment you switch between them you lose sight of which agent is still coding and which one has finished. Briefings get copied and pasted again and again, and context that was explained to one agent is not available to the next. Clippo replaces that scattered, tab-driven workflow with a spatial one: agents, notes, browsers, and editors are all placed on one canvas and connected to each other, so the state of your project is visible at a glance rather than buried in a list of windows. Clippo's core capability is running your AI dev team in parallel. You can assign agents to different fronts at the same time — one building the backend API, another writing test suites, and another refactoring the frontend — and see everyone working side by side on a single screen. Because the agents are laid out visually, you know instantly who is coding and who is done without switching windows. This parallel approach matters because development work naturally splits into independent tracks, and keeping those tracks visible next to each other makes it far easier to spot a stalled agent or an overlapping change before it becomes a problem. The Project binder keeps your agents aligned through a structured set of notes placed directly on the canvas. It has three parts. Project captures the overall architecture, stack guidelines, and team conventions. Plan holds a step-by-step implementation roadmap for you to review before execution begins. Walkthrough produces an executive delivery report with diff summaries and verification checklists. The binder is not just documentation — you connect a cable from any note to a terminal, and the agent absorbs that context immediately, with no re-prompting needed. That single mechanism means architecture decisions, conventions, and roadmaps are shared with every agent you link, keeping a multi-agent effort pointed in the same direction. ClipSurf is an embedded browser that lives on the canvas and serves as web browsing and eyes for any agent. It is available to both you and your agents, and it is particularly valuable for terminal agents and CLI models that do not have built-in web access. With ClipSurf those agents can browse documentation, research solutions online, and test the local web app they just built, live in front of you. Getting external information into an agent normally means copying links and pasted text; ClipSurf removes that step and lets the agent look things up directly, while you watch the same view it is working from. Persistent memory with local AI addresses one of the most costly parts of working with coding agents: losing context between sessions. Clippo keeps a local memory that learns your project over time, storing architectural decisions, solved pitfalls, and coding standards. A lightweight local model retrieves relevant memories on demand, which cuts token usage and keeps context across sessions. The practical effect is that an agent starting a new session does not begin from zero — the decisions you already made and the problems you already solved are available to it, and because retrieval is local, that recall does not come with a token cost for re-explaining the project each time. Clippo IDE is a visual code editor built into the canvas, designed for inspecting and polishing code before Git. You can browse project files, review agent-generated code with syntax highlighting, inspect Git diffs, and make quick edits before committing with a single keystroke. Because the IDE sits on the same canvas as the agents, reviewing their output does not mean leaving the orchestration view. The point is control: agent-generated code is checked, adjusted, and only then committed, so you stay in full control of your repository rather than trusting output blindly. Clippo is built to be lightweight, fast, and 100% private. There are no bloated web wrappers that eat up your RAM; Clippo opens fast, stays light, and leaves your CPU and memory free for compiling and development. Your files, notes, and prompts never leave your PC, with zero account creation, zero login, and zero tracking. For developers working on proprietary code, that on-device design removes the friction and risk of sending project material to a third-party service just to coordinate the tools building it. Overall, Clippo works as a visual orchestration layer that sits alongside the AI tools you already use rather than replacing them. It is compatible with Claude Code, OpenAI Codex, Gemini CLI, OpenCode, Aider, Copilot CLI, and local engines like Ollama and LM Studio, and WSL and Docker are supported out of the box. The methodology is node-based: you place terminals, notes, browsers, and editors on an infinite canvas and link them with cables, so context flows from a note into an agent, and agents run in parallel on separate fronts of the same project. Everything — unlimited terminals, notes, Clippo IDEs, ClipSurfs, and Spaces — lives inside the workspace you arrange yourself. The benefits Clippo claims follow from that structure. You stop drowning in terminal tabs and stop copy-pasting briefings, because one canvas shows every agent's progress at once. You save tokens, because on-device memory recalls project context instead of forcing you to restate it. You keep your CPU and memory for compiling and development, because the app stays light. And you retain full control of your repository, because nothing is committed before you review it in the built-in IDE. The outcome is a workflow where you step up as tech lead of your own AI engineering team rather than acting as a dispatcher between disconnected windows. Concrete scenarios include splitting a feature across agents — one on the backend API, one writing test suites, one refactoring the frontend — while you watch all three on one screen. Another is giving a CLI model without web access the ability to browse docs and research a solution through ClipSurf, then test the local web app it just built in the same embedded browser. A third is reviewing agent-generated code, inspecting Git diffs, and making a quick edit before committing. Persistent memory supports ongoing projects where sessions restart regularly, and the Clippo Pro add-on covers developers working across multiple projects at once using unlimited workspaces. Clippo is aimed at developers who use AI coding agents such as Claude Code, OpenAI Codex, Gemini CLI, OpenCode, Aider, or Copilot CLI, and at anyone running local engines like Ollama or LM Studio. It runs on Windows 11, version 22H2 or higher, on x64. The free plan includes a complete workspace with unlimited terminals, notes, Clippo IDEs, ClipSurfs, and Spaces inside it. To work across multiple projects at once, the Clippo Pro add-on unlocks unlimited workspaces through a one-time purchase from the Microsoft Store. The app offers in-app purchases and is developed by Thiago Grião. Clippo's primary value proposition is simple: it gives Windows developers a visual command room for AI agents, turning a scattered collection of terminal tabs into one infinite canvas where agents run in parallel, project context is shared through linked notes, memory persists locally to cut token usage, and code is inspected before it ever reaches Git.
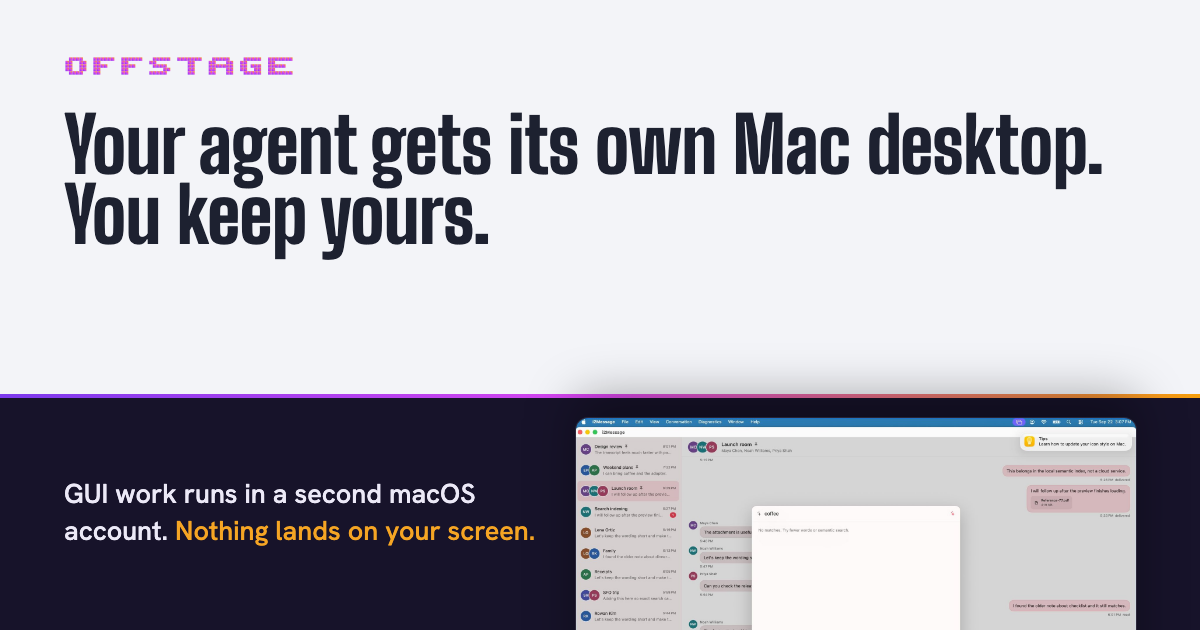
offstage is a free, open-source tool that gives a computer-use coding agent its own Mac desktop instead of your screen. It works with Claude Code, Codex and opencode, and it exists for one purpose: any command an agent runs that could open a window or take focus on your Mac is sent to a second, logged-in macOS account instead. Simulators, Xcode UI tests, osascript calls and the app your agent just built all open on that helper account's desktop, which sits behind yours. Your windows, keyboard and mouse stay yours the whole time. offstage ships as an MCP server and a CLI, is MIT licensed, and runs on Apple Silicon Macs with Node 20 or newer. The problem it addresses is the collision between coding agents and your own computer. Agents increasingly do GUI work: they launch simulators, run Xcode UI tests, drive browsers and open the apps they just compiled. On a normal Mac all of that lands on the one screen you are using, taking focus, moving the mouse and covering your windows. offstage's answer is not to hide the GUI work but to give it a different desktop. Because the helper account is a real macOS account with its own desktop, window server and input, the agent can screenshot, decide and click in a place that never overlaps with what you are doing. The site states plainly why that second macOS account is the whole point: it has its own desktop, window server and input, and that is why offstage exists. The core of the product is the helper account. One setup command creates an ordinary account called computeruse and builds a small Swift daemon for it. If the terminal has Full Disk Access, that daemon is granted Screen Recording and Accessibility automatically; if not, offstage tells you which two toggles to flip. It prints the entire root script before running it. After a single login through the menu bar user menu, the account stays logged in behind yours until the Mac restarts. offstage session status reports where things stand and exits 0 when the session is ready. Nothing here is a virtual machine: it is a second user account on the Mac you already have, with no guest OS and nothing to boot. The trade-off is that both accounts share the Mac's CPU, memory and disk. Storage is where the difference is stark, because the helper account takes about 3 GB of disk, where the macOS VM image the team measured was a 68.8 GB download. offstage also decides where each command should go. The site describes it as reading every command before it runs and sending it to the cheapest place that keeps it off your display, and it defines four lanes. Commands such as xcodebuild test, xcrun simctl, XCUITests, open -a, osascript and a built .app run in the second macOS account. Commands that force a real browser window, including --headed, headless: false, cypress open, WebGL and GPU flags, run in a Linux container with a virtual display if Docker is installed; it is a real display, just not yours. Headless work such as npm test, vitest, headless Playwright and Puppeteer runs right where it is, because those never open a window and wrapping them would only cost time. Finally, installers, .pkg, .dmg and hdiutil are refused outright: both accounts share one machine, so offstage will not run them and no flag overrides that. Agents connect through MCP. The site provides copy-paste configuration for Claude Code (claude mcp add offstage -- npx -y --package=@viraatdas/offstage@latest offstage-mcp), for Codex in ~/.codex/config.toml, and for opencode in opencode.json. Claude Code can also use offstage as a plugin. The MCP surface includes offstage_route, which tells the agent which lane a command gets, and offstage_run, which runs it there, alongside session tools: offstage_session_launch, which waits until the app registers and returns its pid, offstage_session_screenshot, offstage_session_input and offstage_session_quit. The documented GUI loop is launch, screenshot, decide, input, then screenshot again to confirm. Coordinates are points, not pixels, so a pixel coordinate has to be divided by the screenshot's scale. For anything that cannot use MCP, the CLI runs the same code path through offstage route -- and offstage run -- . The reason offstage can promise your screen stays yours is the daemon. It posts input to its own session only, never to the global input stream that feeds your screen, and if its session is ever the one on the console it refuses to send input at all. In testing, the window server's own log showed every synthetic event landing in the helper session and none reaching the console. The site is equally explicit about files: the helper account is an ordinary second user, so it cannot write to your files, and it can read only what macOS lets any other local account read. If a run fails because the helper account cannot read your repository, offstage session share grants read-only access to one folder at a time, and unshare takes it back. Each run writes its output to its own artifacts folder. To make the behaviour stick, you paste a block of instructions into your agent, or into your project's AGENTS.md or CLAUDE.md, and the agent connects offstage itself so GUI work stays off your screen from then on. Two things only the user can do, and the site's rules tell the agent to ask rather than work around them: sharing a repository folder with the helper account, and running offstage session setup --create, which needs sudo. The agent is also told to never re-run a skipped or refused command outside offstage to get past it, because that would put it back on your screen. The practical outcome is that you can keep using your Mac while an agent runs an entire GUI test suite somewhere else. Nothing boots, nothing is virtualised, and the agent's windows, cursor and focus live on a desktop that is not yours. A skipped status means nothing ran anywhere, and refused means the command will not run on any lane. Concrete scenarios appear throughout the site. In one real pair of captures taken on a single Mac on 2026-09-22, Claude Code checks that the helper account is logged in, off your screen, with Screen Recording and Accessibility granted; a second Claude Code session is then testing a messaging app called i2Message on the computeruse desktop, with a search for the word coffee typed in through offstage_session_input. None of it appears on the console user's screen, and the console user was watching a video in a browser the whole time. Other workflows are the lanes themselves: running Xcode UI tests and simulators off-screen, driving a headed browser in a Docker container with a virtual display, leaving npm test or headless Playwright in place because they never open a window, and refusing installers so they never land on either account. offstage is aimed at developers on Apple Silicon Macs who run coding agents and want their own machine left alone during GUI-heavy work: Xcode and simulator workflows, UI tests, browser automation, and any project where an agent builds an app that then needs to be clicked. The agents it supports explicitly are Claude Code, Codex and opencode, through MCP, with Claude Code also usable as a plugin; anything else that can run a shell command can use the offstage CLI, which runs the same code. Requirements are an Apple Silicon Mac and Node 20 or newer, with Docker optional for the container lane. Pricing is free: the project is MIT licensed and open source on GitHub. The takeaway is that offstage solves a very specific, very annoying problem, an agent that needs a screen taking over the one you are using, by giving that agent a second, logged-in macOS account with its own desktop, window server and input. It routes each command to the cheapest place that keeps it off your display, refuses the commands that could touch the whole machine, and costs nothing but a folder share and one sudo command. Your agent gets its Mac desktop; you keep yours.
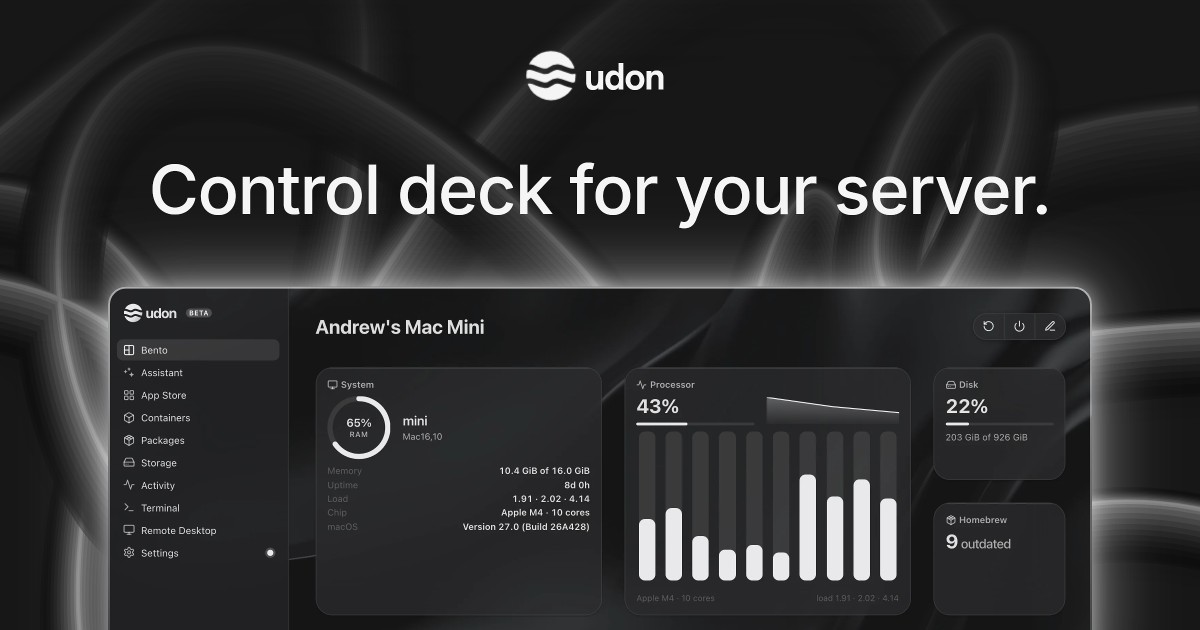
Udon is a control deck for a home server built on an Apple Silicon Mac. It turns a Mac mini, Mac Studio, MacBook, or iMac into a home for your files, photos, media, and apps, and lets you manage all of it from your browser. Udon installs with a single terminal command, and the Mac keeps working as a normal Mac. Any Apple Silicon Mac (M1 or newer) running macOS 26 or later is supported; Intel Macs are not. A Mac mini is the usual pick for an always-on home server because it is small, quiet, and draws a few watts at idle. An optional AI sysadmin can help you install apps, check the server, and investigate problems. The product is built for people who want to own their digital life and keep their data on hardware they own. macOS has no dashboard for running self-hosted apps, and Udon exists to add one. Without a control panel, running services on a Mac means working manually over SSH with a container tool such as Portainer, which puts everyday management out of reach for many people. The established alternatives are Unraid, TrueNAS, or Proxmox on dedicated x86 hardware, a Synology NAS, or Umbrel, CasaOS, or OpenMediaVault on a Raspberry Pi or spare PC. Each of those routes asks for extra hardware, extra power draw, or extra maintenance. Meanwhile a Mac mini idles at a few watts, runs near silent, and still has power to spare for media, photos, and a dozen containers, so the hardware is often already sitting on the desk. Udon provides the missing software layer that makes that machine manageable as a server. The AI sysadmin is Udon's most distinctive component. It is optional and stays off until you turn it on. When enabled, you can ask it to install apps, check your server, or investigate a problem, rather than working through each screen of the dashboard yourself. You choose the AI provider: connect an Anthropic or OpenAI API key, a coding CLI such as Claude Code or Codex, or a local model running on the same Mac. By default the assistant asks before every change, and it records its actions in an audit log, so you keep control over what happens to your machine. If you connect a cloud model, it sees what you ask the assistant to work on, which the website states plainly. Containers and packages are managed in one place. Udon runs standard images from Docker Hub, GitHub Container Registry, or any other registry, on Apple Container, Apple's native runtime, or on OrbStack, which is Docker-compatible. On OrbStack you can also build compose stacks in the visual Composer. Alongside containers, Udon manages Homebrew packages, so the software your Mac runs is chosen and tracked from a single interface instead of a mix of command-line tools. This matters because container and package management is usually the part of self-hosting that people find hardest to keep organised. The built-in App Store makes the first steps easier. You can install self-hosted apps with settings pre-filled, so building a photo library, streaming your media, or organising documents at home does not require configuring every service by hand. If the catalogue does not cover what you need, Udon points you to more apps on Docker Hub and Homebrew, and the documentation includes a guide on how to deploy a container. Terminal and remote desktop access are built into the dashboard. You can work on your Mac from any browser, with its terminal and its desktop within reach, and terminal sessions stay open between visits, so a long-running task is still there when you come back. Storage and sharing are handled in the same place. Your files stay on your own drives, and Udon lets you browse and preview them, check drive health, and share folders across your home network as SMB shares. Remote access is handled through Tailscale. Your files and apps live on your Mac, and you stay in control of them; Udon connects over your own Tailscale network with trusted HTTPS for the dashboard, so you can manage the server from your phone's browser at home or away without exposing it publicly. The Activity view shows how your Mac is doing at a glance: CPU, memory, network, and power use live, plus which processes are running. Together these two areas cover both reaching the server and understanding what it is doing. Udon's overall approach is to take a machine you already own and give it a browser-based control deck. Installation is a single terminal command, and after that the dashboard is reached at an address such as mac-mini.local:4443. Everything the product manages — containers and compose stacks, apps from the App Store, files and SMB shares, drive health, live system stats, Homebrew packages, a terminal, and the Mac's screen through remote desktop — is available from any browser. The Mac keeps working as a normal Mac throughout. A companion app for iPhone and Android is coming soon, and until then the dashboard works from a phone's browser. The benefits follow directly from that design. Your files, photos, and media stay on your Mac rather than in a cloud service, and the dashboard is served over HTTPS with remote access over your own Tailscale network. Udon is a one-time purchase rather than a subscription, so there is nothing to renew. Trying it does not require a card, and if you do not buy a licence after the free days, nothing is charged: the dashboard locks, but containers keep running and your files and settings stay exactly as they are. In practice, people use Udon to run the self-hosted services that would otherwise need a NAS or a separate server. Streaming media with Jellyfin or Plex, backing up photos with Immich, syncing files with Nextcloud, keeping passwords in Vaultwarden, blocking ads for the whole network, archiving documents with Paperless, and automating workflows with n8n are all named as things you can self-host on a Mac. Udon can also host your dev environments and coding agents, which you reach from a laptop or an iPad anywhere. Udon is available for Apple Silicon Macs running macOS 26 or later, with the dashboard managed from a web browser. It runs Docker images on Apple Container or OrbStack, manages Homebrew packages, and uses Tailscale for remote access. Pricing is a free 5-day trial with no card required, followed by a one-time payment: early supporters pay $29, reduced from $49, for a lifetime licence that includes every feature and updates and is tied to the Mac's serial number with no accounts. Every purchase comes with a 14-day money-back guarantee. Udon's core proposition is simple: own your digital life, start with your Mac. It takes an Apple Silicon Mac you already have, adds the dashboard macOS is missing, and brings self-hosted apps, containers, storage, monitoring, and an optional AI sysadmin together in one browser-based control deck.
BotBus is an app for keeping tabs on the AI coding agents running on your computer from your phone and Apple Watch. On the computer it lives in the menu bar and automatically discovers local agents such as Codex and Claude Code; on your phone and watch you can follow task progress, approve, follow up, interrupt, and start new tasks. Tasks from all of your computers are gathered in one place, sorted by agent and project, so developers who run agents locally can stay in control without sitting at their desk. What you can do depends on the connector, the task's state and whether the computer is online. Coding agents do not only write code; they pause. An agent may want to run a command such as a test suite, edit files, or ask a question before continuing, and it waits until someone answers. When that someone is away from the keyboard, the work stops, and a task that could have been finished in an hour sits idle until the developer returns. BotBus is built around that gap. Its promise is that you can step away from your computer and the work keeps moving: approvals, follow-ups and new instructions arrive on the device that is already in your pocket or on your wrist. The desktop app quietly discovers the agents already installed on the machine rather than asking you to configure them, and the phone app turns those agents into something you can supervise from anywhere. Every computer at a glance. BotBus collects tasks from all of your paired computers and sorts them by agent and project, including the tasks you started at your desk. A device list shows online status and pending counts for each machine, and opening a single computer reveals its pending and running tasks alongside recent projects, so you can tell at a glance where attention is needed. New tasks, on the go. From your phone you pick a computer, a project and an agent, say one sentence, and the task starts. You can choose the model, or run the task in its own git worktree so parallel work stays isolated from your main checkout. Approvals and questions in one tap. When an agent wants to run a command, edit files or ask you something, BotBus nudges you, and you answer with a tap on your phone or your watch. Auto-approve can be turned on for a project when you would rather not be asked. Beyond approvals, BotBus also supports following up and interrupting a running task, voice input for instructions or replies, sending photos from your phone, reviewing uncommitted changes, and switching the model and reasoning effort for a task. Watch sync means that once your watch has synced pairing from your phone it connects on its own, so common actions do not require pulling out your phone at all; the watch can show all devices, recent projects, approval requests and a task awaiting your reply with voice reply. Control your computer's screen. On supported setups you can see your computer's screen live on your phone and tap, swipe or type on it. Input starts locked, and both the picture and your input are end-to-end encrypted. Screen control currently supports Mac. Results, straight to your phone. Screenshots, files and videos come back together with the task, and images and PDFs mentioned in the chat open with a tap, so you can inspect what an agent produced without transferring anything by hand. Preview web pages on your phone. When an agent starts a dev server, BotBus lets you preview the page it built on your phone, without going back to your computer. BotBus works through a small desktop app plus a pairing flow. You install BotBus on your computer, where it lives in the menu bar, runs in the background and automatically discovers local agents. Choosing 'Pair a Phone' shows a QR code; scanning it pairs the phone, and the key never goes through the server, staying in each device's keychain instead. Content is encrypted with AES-256 on your device before it is sent, so the server only relays and briefly holds ciphertext and cannot decrypt your chats, commands or images. Pairings that idle for 30 days are cleared, and removing any single computer or phone disconnects it at once. The server still sees the little it needs to relay data: device IDs, online status, update times and data sizes. Developer previews, which share a web page from your computer to your phone, are proxied through the server and are not end-to-end encrypted. Viewing already-synced tasks does not require the computer to be online, but approving, following up, starting new tasks and interrupting do require the target computer to be online and supported by the connector. The benefit is continuity. Instead of returning to the desk to unblock an agent, you answer the approval from your phone in a tap, or reply by voice from your watch. Instead of wondering whether a long job finished, you glance at a device list that shows pending counts across all your machines. Instead of waiting to see what an agent produced, the screenshots, files, videos, PDFs and dev-server previews arrive with the task. BotBus does not change how your agents work; it changes where you have to be while they work, so a commute, a meeting or an evening away does not mean downtime for your machine. Typical scenarios follow the way developers actually work. A test suite fails and the agent asks to run a command; you are away from your desk, so you approve it from your phone and the run continues. You think of a small fix while commuting, so you pick the project and agent, say one sentence, and the task starts on the computer at home. You run several machines and want a single view of pending and running work, sorted by agent and project. You want to see the landing page an agent built before you get back, so you preview the dev server on your phone. You are traveling and need to take control of your Mac's screen directly. Or you are in a meeting, an approval arrives, and one tap on your watch, or a spoken reply, keeps the agent moving. BotBus runs a desktop app on macOS, Linux and Windows and a mobile app for iOS and Android. The Mac app requires macOS 26 or later and is universal for Apple Silicon (arm64) and Intel (x86_64); the current download is BotBus for Mac 1.0.6 (build 33), 24.3 MB, released 2026-10-08, with a published SHA-256 for verification. Linux is a command-line version for servers and dev machines, covering mainstream x86_64 and aarch64 distros with or without systemd and installing without sudo; you scan a QR code in the terminal to pair. Windows 10 and 11 is ready to install, runs in the background after you sign in with a tray icon, needs no administrator rights, and requires Windows 11 on ARM PCs. On mobile, the iPhone and Apple Watch app requires iOS 26 / watchOS 26 or later and comes bundled with the watch app; Android 8.0 or later is available on Google Play or as a direct APK download. Built-in agent support covers Codex, Claude Code, Hermes, Pi, OpenClaw and DeepSeek Harness, and other agents that implement ACP (Agent Client Protocol), such as OpenCode, can connect as well. BotBus turns the computer that runs your coding agents into something you can supervise from your pocket. By discovering local agents automatically, delivering approvals and questions to your phone or watch, and encrypting content end to end, it keeps the work moving while you are away from your desk.
tide is a simple, self-hostable video conference service that positions itself as an alternative to Jitsi, Zoom and Google Meet. Rather than renting conferencing from a hosted provider, an organisation can run tide on its own infrastructure and host meetings at an address such as meet.custom.domain. The product's own tagline describes it as "A Jitsi alternative that does a few things really well," and the site lists the core capabilities as link sharing, screen sharing and server-side recording. It is for anyone who wants to own the video meeting stack rather than depend on someone else's servers, and the site offers both a live demo and deployment documentation as starting points. Most video conferencing today happens on someone else's infrastructure. Zoom and Google Meet are hosted services: the meeting runs on the vendor's servers, under the vendor's terms, and the media travels through networks the customer does not control. Jitsi offers a self-hostable route, and tide explicitly frames itself as an alternative to it, naming Zoom and Google Meet alongside. The problem tide addresses is therefore one of ownership: whose server carries the audio and video, who holds the recordings, and who decides the sign-in rules. The website states its answer in two headline bullets — "Media stays on your server" and "Server-side recording" — arguing that a conferencing service can stay simple while still keeping the media and the resulting files inside the operator's own environment. For teams with data-residency expectations, internal security policies or a preference for self-reliance, that distinction weighs more heavily than a long feature list. Deployment is presented as one of tide's defining traits. The site lists "One Go binary" as its first bullet and calls tide a simple, self-hostable video conference service. Two links carry the practical next steps: a demo instance at demo.tide.convex.works and a Deploy link pointing to tide.convex.works/docs. The single-binary pitch means the whole service can be distributed and run as one artifact rather than as a suite of separate components the operator has to assemble and keep in sync. Go is the one technology named directly on the page, and the claim of one binary follows from that. For anyone evaluating self-hosted video, the effect is a smaller surface to install, fewer moving parts to update, and a documented entry point at the docs URL. On the meeting side, tide covers the core workflow of getting people into a call. Link sharing is named among the core features, and the interface shown on the site includes a "New room" form with fields for a Name, a Link, and a calendar shortcut. The illustrated example is a "Weekly sync" with the link meet.example.com/m/chw-pnih-sxi, and the form includes an "Add to calendar" action plus a Date block with Starts and Ends times — 10/05/2026, 07:30 PM to 08:00 PM in the example. Two actions are offered once the room is configured: "Create" and "Create & join," so an organiser can either prepare a room or start it immediately. Screen sharing is listed explicitly as a core feature, and recording is handled server-side rather than on a participant's machine — the site states "Server-side recording" both as a headline bullet and in the Product Hunt description alongside link sharing and screen sharing. Sign-in is delegated to OIDC, the fourth headline point. Using OIDC means authentication can be tied to an identity provider the organisation already operates, instead of tide maintaining its own account system, which fits the self-hosted positioning: the operator keeps control over who is allowed in. The meeting view shown on the site displays named participants — Daniel, Maya, Marcus and Nikos, marked as "You" — with a participant count of four, illustrating a small call. The overall approach tide takes is stated in its own tagline: "A Jitsi alternative that does a few things really well." Rather than competing on breadth, the product concentrates on a short, explicit list — one Go binary, media that stays on your server, server-side recording and OIDC sign-in — and repeats that framing in the Product Hunt description: "A few things, done well." The same description notes that tide lets you host your own "meet.custom.domain" for "a simple video conferencing environment with all core features you expect." The methodology, in other words, is to be a focused self-hosted service: install one binary, point a domain at it, and run meetings with link sharing, screen sharing and server-side recording under your own roof. The benefits that follow from the page's stated facts are straightforward. Because media stays on your server, meeting traffic terminates in infrastructure the operator controls. Because recording happens server-side, call recordings are produced by the service itself rather than depending on a participant capturing their own local stream. Because sign-in uses OIDC, access control can follow whatever identity system the organisation already runs instead of a separate set of credentials. Because the service is a single Go binary, deployment and maintenance are framed as simple rather than as an ongoing platform project. And because the scope is deliberately small — a few things done well — the operator does not have to weigh a long list of optional modules to get a working conferencing environment. Concrete scenarios appear on the page. The "New room" example is a recurring team meeting — a "Weekly sync" scheduled for a specific date and time with a fixed start and end — and the presence of an "Add to calendar" action indicates the intended flow of setting up a meeting and adding the appointment to a calendar. The generated link, meet.example.com/m/chw-pnih-sxi, shows the pattern of a short meeting URL that can be shared with attendees, which matches the link-sharing feature. The "Create" and "Create & join" buttons serve both the organiser who wants to prepare a room ahead of time and the one who wants to start straight away. The demo at demo.tide.convex.works provides a way to experience a call before committing to a deployment, and the site's framing of "meet.custom.domain" points to organisations that want their meetings hosted on a domain of their own. Server-side recording suits meetings that need to be captured for people who cannot attend, and OIDC sign-in suits invitations that must be restricted to members of an existing directory. The intended audience can be read from the page's own vocabulary: the three alternatives invoked — Jitsi, Zoom and Google Meet — describe both the self-hosting tradition tide belongs to and the mainstream services it is offered against. Anyone who wants to run their own "meet.custom.domain" is the stated target. In terms of stack, the site names exactly one technology, Go, in the bullet "One Go binary," and describes OIDC for sign-in. Deployment documentation is linked at tide.convex.works/docs. The page itself does not state a price, plan or licensing model, and it does not describe native mobile or desktop applications; it presents a self-hosted service with a room creation form and a shareable meeting link. Taken together, tide makes a single, deliberate claim: video conferencing that you host yourself, built around a few things done really well. One Go binary to deploy, media that stays on your server, server-side recording and OIDC sign-in, wrapped around the familiar flow of creating a room, sharing a link, sharing your screen and joining the call. For teams that want their meetings — and the recordings they produce — to remain on infrastructure they control, tide offers a focused alternative to Jitsi, Zoom and Google Meet.
Liquid Inference is an LLM router that runs an instant auction for every AI request. You send an ordinary chat request, and providers compete to answer it at the lowest price that meets the rules you set. Instead of committing to one vendor's rate card, you describe what the request needs — model, region, speed and minimum quality — and the cheapest provider that satisfies those requirements answers. The product is built for developers and teams already working with large language models through coding agents, SDKs or direct API calls, and who want access to hundreds of open- and closed-weight models without managing a separate account, key and billing relationship for each one. Choosing a model provider has usually meant accepting a published, fixed rate and paying it whether or not cheaper capacity exists somewhere else at that exact moment. Inference capacity fluctuates with supply and demand, so providers often hold spare capacity they would be willing to sell at a lower price, but buyers have had no practical way to discover and capture that price request by request. Liquid Inference turns every prompt into a small auction to close that gap. Providers publish a price per token for each model and can change it at any time, lowering it when they have spare capacity. The result is that a buyer pays the lowest marginal cost available for that request while still getting the model, region, speed and quality constraints they specified. The auction runs in three steps. First, providers set their prices: each provider sets a price per token for each model and may change it whenever they like, so the offers on the book move with supply and demand. Second, the cheapest match answers: you set the rules — model, region, speed and minimum quality — and the cheapest provider that meets them answers your request. Third, you pay for what you use: before the model starts, you know the most a request can cost, and you are billed only for the tokens it produces. Because the cap is fixed before the first token is generated, the price of a request is known up front rather than discovered later on the invoice. Control over routing is explicit. A price limit is placed on every request before the first token, so you know the maximum a request can cost and pay only for the tokens produced. Routing rules let you choose the model, region, speed and minimum quality, and only providers that meet those requirements compete for the work. To support trust in the marketplace, Liquid Inference tests every provider regularly with standard benchmarks and publishes the results, so the speed and measured quality of providers are visible and the same rules apply to everyone. Billing is itemized, showing what every request cost line by line, and public price history lets you download live and past prices for every model so you can send work when prices are low. Liquid Inference covers hundreds of open- and closed-weight models, spanning families such as GPT, Qwen, Gemini, GLM, Deepseek, Gemma, Kimi, Grok, Claude, Mistral, O, Nemotron, Ernie, Mimo, Llama, Phi, Nova, Command, Hermes, Granite, Sonar and many more. Model counts per family are listed on the site alongside the lowest current offer in USD per million output tokens, which ranged from $0.01 for Nemotron to $4.62 for O at the time of capture. Compatibility is deliberately simple: one key covers both OpenAI Chat Completions and Anthropic Messages on a single base URL, so existing code works unchanged, and getting started requires changing one URL. The product also supports full multi-modal requests. The overall approach is to treat inference as a live market rather than a static catalogue. Providers compete dynamically on price for every single prompt, offering the lowest marginal cost at the moment the request is made. You can create routing rule presets or use the Auto routing algorithms to decide how requests are matched, and the rules you set determine which offers are allowed to compete. Because providers can raise or lower prices at will and stop quoting when they are full, the offers on the book reflect current capacity. The buyer's side of the market is equally concrete: a single base URL, one API key, and code that already speaks the OpenAI or Anthropic API continues to work. Practically, this means a lower cost per request for equivalent work, because you are matched to the cheapest provider that meets your stated requirements rather than paying a fixed published rate. It means more predictable spend, since a price limit is fixed before the first token and you are billed only for produced tokens, with itemized billing showing what each request cost. It gives you leverage over supplier choice — model, region, speed and quality are yours to specify — while independent benchmark results keep providers comparable. And because prices move with supply and demand, public price history gives you the information needed to time workloads when prices are low. Concrete workflows follow from those capabilities. A developer using an agentic coding tool such as Claude Code, Codex, Cursor, OpenCode, Cline or Pi can point the tool at Liquid Inference by changing the base URL, keeping their existing client while gaining access to every listed model. A team planning spend can pick a model and a monthly output volume in the cost estimator and see the lowest offer now and the estimated cost per month. A workload that is price-sensitive rather than latency-sensitive can be scheduled using public price history when prices are low. A user who needs multi-modal support can send those requests through the same single key. And anyone already running inference on their own models can join as a provider, post a price and be paid for the tokens they serve. For buyers, sign-up is free with email and the first 500 users receive $20 of free inference; referring others earns 20% of referred fees as free inference, with 10% for second-level referrals. Access is through an API key and the base URL https://router.inference.ai.exchange/v1. The documented list of compatible clients and SDKs includes Claude Code, Codex, Pi, Oh My Pi, Cursor, OpenCode, Cline, Roo Code, Kilo Code, Goose, Open WebUI, Cherry Studio, n8n, the OpenAI SDK, the Anthropic SDK, the Claude Agent SDK, the OpenAI Agents SDK, the Vercel AI SDK, LiteLLM, LangChain and curl. On the supply side, anyone running models can create an account, register the deployment they want to serve, have an operator review and list it, then connect their agent and start quoting. Registration as a provider is free, and Liquid Inference charges its fee to the customer, not to the provider. In short, Liquid Inference replaces fixed inference pricing with a per-prompt auction in which providers compete to serve your request at the lowest price that still satisfies your rules. You keep the models and tools you already use, gain a price cap before the first token, itemized and predictable billing, benchmark-backed provider trust and public price history, while providers gain a live market for their spare capacity. The value proposition is straightforward: complete your AI requests and pay the lowest offer that meets your requirements.
Markdoc is a shared Markdown editor that places the raw source and an editable rendered preview side by side in the same document, live for everyone who has it open. You can type in either surface — the Markdown source or the rich preview — and the other follows instantly, cursors included. The Product Hunt listing describes it as "a shared Markdown editor for people and their agents," which captures its two audiences: people who write and review Markdown, and the AI agents they bring into the document. Its stated purpose is straightforward: write Markdown together in real time, review with comments and suggestions, keep every version, and publish straight to a gist or a repository file. Access is free while the product is in preview, and a GitHub account is required to get started. Markdown has become a common format for documentation, notes, READMEs and repository files, but the act of writing it has largely stayed a solitary, file-based job. Files typically live in gists and repositories, and review tends to happen after the writing is done, through commits and whatever commentary travels alongside them. Markdoc's framing — "Markdown, together" — positions the editor as the place where those activities converge instead of being scattered. Rather than writing in one tool, previewing in another, discussing changes in a third and publishing from a fourth, the product brings authoring, review, versioning and publishing into a single shared document on the web. The tagline "A shared Markdown editor for people and their agents" also signals a newer kind of collaborator: software agents can take part in the same document through MCP, so human and machine editing can happen against the same live text. The first capability Markdoc highlights is its dual-surface editing model: "Two surfaces, one document." A code editor and a rich preview sit side by side, and you can type into either one. Type in the source and the rendered page updates; type in the rendered page and the source follows. The update is described as instant and includes cursors, so both surfaces stay visually in step. Because both views are driven by the same document, there is no need to switch tools to check how your Markdown will render — you see it as you write it. Real-time collaboration is layered on top: presence, live carets and selections, and conflict-free merging on both surfaces. That means multiple people can be in the same document at once, each seeing where the others are working, with concurrent edits merged rather than clobbering each other. The editor also works offline and catches up when you reconnect, so a dropped connection or a flight does not stop the writing. Review in Markdoc happens inside the document. Comments are designed to stick: threads are anchored to text, and they follow the words as the document changes, so a comment stays attached to its subject even after paragraphs move or are rewritten. Threads can be replied to, resolved, and reopened, which supports a back-and-forth review that continues over time rather than a one-off note. Alongside comments, Suggesting mode lets a collaborator propose edits as tracked changes instead of editing the text directly. Owners — the people responsible for the document — can accept or reject each proposed change individually, or accept or reject all of them at once. Together these two features cover the familiar review loop: leave a note where something needs discussion, or make a concrete proposal that someone else decides on, without either side overwriting the other's work. Version history gives the document a memory. Markdoc takes automatic snapshots while you work, so recent states are captured without anyone having to remember to save a copy. When a particular state matters, you can create a named version. Comparing versions is done with word-level diffs, and restoring is a one-click action. For storage, Markdoc is GitHub-native: you can open any Markdown file from a gist or a repository, and publishing creates a real commit on the branch you choose. In other words, the document's home remains the place the file already lives — a gist or a repo — and publishing is not a copy-paste export but a commit. The Product Hunt description adds one more route in and out of the document: you can bring your own agent over MCP, letting an assistant work with the same Markdown file alongside the people in it. The distinctive approach is that everything happens in one place, on one document, in real time. Editing, previewing, discussing and versioning are not separate stages handed off between tools; they are concurrent activities on the same live text. The two-surface design makes the source and its rendered output equal, editable views of that text, and the collaboration layer — presence, carets, conflict-free merging and offline catch-up — keeps every participant, including ones who were disconnected, on the same state. Comments anchored to text and tracked suggestions keep feedback attached to the exact words it concerns. Version snapshots and named versions record how the document evolved, while GitHub-native storage and publishing tie the working copy back to a gist or a repository through real commits. Agents participate through MCP, so they are not a separate chat window but another participant in the document. The benefits follow from that consolidation. Because the preview is always beside the source and updates as you write, you can see how your Markdown renders without leaving the editor or opening a separate preview window. Because collaboration is real time with presence and conflict-free merging, several people can work on one file at once instead of taking turns or merging changes later by hand. Because comments anchor to text and suggestions are tracked, review feedback stays attached to what it refers to and nothing is silently overwritten. Because snapshots are automatic and restore is one click, experiments are less costly and earlier states are recoverable. And because publishing is a real commit to a gist or repository, the file you wrote stays in the place your team already looks for it. Concrete workflows the content describes include writing Markdown alongside other people in the same document, with everyone's cursors and selections visible as they work. A reviewer can comment on a specific passage and hold a discussion in the thread, resolving and reopening it as needed, or switch to suggesting mode and propose edits as tracked changes that the document owner accepts or rejects. Teams can start from an existing Markdown file by opening it from a gist or a repository, work on it together in Markdoc, then publish back — creating a real commit on a chosen branch — when the document is ready. Someone can draft offline and let the editor catch up on reconnection. And a team that uses an agent can bring it into the document over MCP so it works on the same Markdown file as the people. Markdoc is aimed at anyone who writes Markdown collaboratively — the Product Hunt topics list Productivity, Writing and Developer Tools, which matches a product that appeals both to writers who care about the rendered result and to developers who treat Markdown files as part of their repositories. The stated integrations are GitHub-specific: opening files from gists and repositories, publishing as commits to a branch, and the requirement of a GitHub account to get started. Agents integrate over MCP. Pricing is free while the product is in preview. No other technology stack details are stated in the provided content. Markdoc's core promise is simple to state: Markdown, together. It puts source and preview side by side in one live document, lets people edit either surface at the same time, anchors comments and tracked suggestions to the text they concern, keeps automatic and named versions with word-level diffs and one-click restore, and publishes to a gist or repository as a real commit on the branch you choose. Agents can join over MCP. Free while in preview and requiring only a GitHub account, it offers a single shared place for writing, reviewing, versioning and shipping Markdown.
OpenSwarm is a free AI desktop for Mac where many agents work at once. Rather than giving you one assistant in one chat window, it puts a desktop in front of you on which a swarm of agents runs in parallel, each agent with its own browser, apps and tools. The stated goal is straightforward: anything you do on your computer, a swarm can do for you. You tell OpenSwarm what you want, the agents work with you at the helm, and you can watch the whole swarm on one canvas, step in when you want, and pick up the finished work. Most AI tools still give you one agent in one chat. It works on a single task while you wait, and anything bigger than that ends up back on your plate. That limitation is the problem OpenSwarm sets out to remove. When a job involves dozens of small steps - searching many pages, checking several sources, drafting a message for every name on a list - a single conversational agent cannot keep up, so the human becomes the bottleneck and the coordination work lands back on them. OpenSwarm reframes the work as orchestration instead of execution: you describe the outcome, and a swarm of agents carries out the parallel steps while you stay in control of the direction. One of the clearest demonstrations of the swarm model is parallel browsing. A single ask - the site's own example is "Best food in Berkeley" - opens six browsers at once, and each agent reads its own set of pages. Instead of one agent walking through search results one after another while you wait, six lines of research run simultaneously and their findings come back together. Agents also use your browser, your apps and connected tools, which means they can carry a task through to the end rather than stopping at advice. The site frames this as unlimited capability: whatever you would normally do on your computer, the swarm can do it for you, and it finishes the whole task instead of telling you how to do it. OpenSwarm also builds software on request. In the example shown on the site, you type "Make me an app for my daily brief" and an agent builds the tool for you; it then sits in your launcher next to the rest of your apps. That behaviour matters because it removes the gap between having an idea for a small utility and actually having it. You do not need to know how the app is put together or where it lives - you describe the tool you want in plain language, and it appears as a finished app in the same place as everything else you use. This is the sense in which the product describes apps creating themselves: the desktop grows to fit the work you ask for. On top of the desktop itself, OpenSwarm offers an agent marketplace - a set of apps that your agents use inside OpenSwarm to find leads, validate problems and more. Lead Finder is described as an app for finding your next customers with five agents. Problem Validator takes a description of a problem and sends agents to search Reddit, X, Hacker News and review sites for real people who have it, using six agents. Post Harvester asks you to paste a profile, after which three agents harvest the posts and turn them into a knowledge base you can talk to. Social Footprint Finder takes a name or a handle, and six agents find public profiles across the web. More apps are listed as coming soon: Text Agents, Call Agents and Verbal Hotkeys. The pattern behind all of these apps is the same: a big job is split so that every source or every unit of work gets its own agent. Problem Validator is the clearest illustration - it gives every source its own agent so that Reddit, X and Hacker News are searched at the same time rather than one after another. You then supervise the swarm on a single canvas, watch what each agent is doing, intervene where your judgement is needed, and collect the results when the work is finished. OpenSwarm describes itself as an AI-first operating system where agents run the whole machine - apps create themselves, browsers control themselves, and swarms of agents work together - turning your operating system into an infinite canvas and your work from doing one task at a time into orchestrating dozens in parallel. The benefits follow directly from that structure. Work that used to be serial becomes parallel, so waiting time shrinks and more of a task can be handed over instead of just the easy part. Because the agents use your browser, apps and connected tools, they can finish the whole job rather than leaving you to complete it. At the same time, you are never out of the loop: the swarm is visible on one canvas, you can step in when you want, and you pick up the finished work when it is ready. OpenSwarm summarises the outcome as being at the helm - you are no longer the person doing one task at a time, but the person orchestrating dozens. The site positions OpenSwarm as one desktop for every team and lists sales and outreach, operations, recruiting and research as the areas it is built for. The sales example is spelled out in detail: a user can ask OpenSwarm to find 50 Series A fintech startups in New York and draft a first email to each founder. The swarm finds the right people, learns what they care about, and has a first email ready for each one, with progress shown against a running total of leads. Research workflows appear in the same way - the Berkeley food question, or validating a problem across many sources at once - while recruiting and operations teams are named as the other functions that can hand repetitive, multi-step work to a swarm. OpenSwarm is a free AI desktop for Mac. The site describes it as a 100% free AI desktop, and access is being handled through a waitlist: at the time of writing the page showed 10,672 people on the waitlist, and joining requires only an email address, with early-access updates sent by email and unsubscribe available at any time. The workflows shown reference LinkedIn, Crunchbase, HubSpot and Gmail as the tools involved in the outreach example, alongside the apps agents use inside OpenSwarm. The page carries a "Backed by" link to joinef.com. Beyond the Mac desktop itself, the marketplace apps - Lead Finder, Problem Validator, Post Harvester and Social Footprint Finder - each come with a stated number of agents, and Text Agents, Call Agents and Verbal Hotkeys are marked as coming soon. OpenSwarm's proposition is easy to state and hard to do: instead of an assistant that answers in a chat while the real work stays with you, it offers a desktop where a swarm of agents works at once, each with its own browser and tools, all visible on one canvas. You keep the helm; the swarm keeps the pace. Whether you are researching a market, validating an idea, harvesting posts, finding leads or drafting outreach, the product turns a queue of small tasks into parallel work that can be finished and handed back to you - and it is free for Mac users who join the waitlist.
DevAlly is an AI-powered accessibility compliance platform built for product teams who ship quickly. Its purpose is to make a digital product accessibility conformant fast, so that teams can build products for everyone rather than treating accessibility as a one-off audit. The platform covers the accessibility lifecycle end to end — scan, identify, remediate, prove and scale — and combines automated auditing with AI that generates exact code-level fixes. DevAlly AI Agent, the product's launch on Product Hunt, extends this by letting a user describe a user journey in plain English; the agent then navigates the application and records that journey, saving hours of engineering work. DevAlly then audits each stage of the recorded journey against the WCAG criterion and suggests fixes for every issue it finds. The company positions the product for teams that need accessibility compliance without slowing down their roadmap. The context behind DevAlly is a regulatory and legal landscape that is tightening. According to figures presented on the website, a large share of websites fail basic accessibility requirements, and thousands of ADA lawsuits are filed in the United States annually. The site notes that ADA Title III exposes private businesses to civil lawsuits, with demand letters, class actions and settlements rising every year, and that settlements often exceed $50,000. At the same time, the US, the EU and the UK have each set their own accessibility requirements, and the direction is described as mandatory, enforceable and increasingly expected by the enterprise customers teams are selling to. For US federal procurement, VPATs are required, and they are increasingly expected by enterprise buyers more broadly. Because products change constantly, accessibility requires consistent monitoring rather than a single audit — which is exactly the gap the DevAlly Agent is designed to close. DevAlly organises accessibility work into five stages. The first is Scan: you sign up and run your first automated audit in under ten minutes, with no configuration required. The website states that no credit card and no accessibility expertise are needed to begin, so a team can enter its product URL and get started straight away. The second stage is Identify, where issues found by an audit are prioritised by severity and by compliance standard. The point of that prioritisation is to surface the necessary fixes first rather than the nice-to-haves, so a team working through a long list of findings knows which items actually block conformance and which can wait. Together, Scan and Identify turn an open-ended question — is our product accessible? — into a ranked, standard-based list of things to fix. The third stage, Remediate, is where DevAlly's AI generates exact code-level fixes rather than generic advice. Those fixes are integrated directly into GitHub and into a CI/CD pipeline, which means accessibility issues can be caught before they ship instead of being discovered after release. This matters because it moves accessibility into the same workflow engineering already uses for other quality checks: remediation happens where the code lives, and the pipeline becomes a gate rather than a report. The website also notes that the DevAlly MCP brings accessibility compliance into your editor, so you can ask what is failing WCAG and get the fix without leaving your workflow. The company describes this combination as accessibility that stays built in, not bolted on. The fourth stage is Prove. When procurement, legal or a customer asks about accessibility, DevAlly is designed to have the documentation ready: VPATs, compliance dashboards and accessibility statements on demand. Because VPATs are required for US federal procurement and are increasingly expected by enterprise buyers, being able to produce them quickly is a commercial concern as well as a compliance one. The fifth stage is Scale: as a product grows, DevAlly grows with it, and continuous monitoring catches regressions before users do. Continuous monitoring is the direct answer to the problem of constant change — a product that passed an audit last quarter may fail today's WCAG criteria after a release, and DevAlly's approach is to keep checking rather than to re-audit from scratch. Taken together, the platform's methodology is an end-to-end, AI-driven loop rather than a point-in-time audit. A team enters its product URL or signs up, runs an automated audit, and receives findings prioritised by severity and compliance standard. For each issue, AI generates code-level fixes that flow into GitHub and the CI/CD pipeline. Documentation for compliance and procurement is produced from the same system, and monitoring continues so that regressions are caught as the product evolves. The DevAlly AI Agent adds a natural-language layer on top of this: instead of scripting a test path, you describe a user journey in plain English, the agent navigates the app and records the journey, and the platform audits each stage of that journey against the WCAG criterion and suggests fixes for every issue it finds. The website frames the overall promise simply — DevAlly handles the auditing, the prioritisation and the documentation, and the team handles the building. The intended outcomes are that teams become accessibility conformant quickly, without needing in-house accessibility expertise and without slowing down the roadmap. Practically, that means less engineering time spent recording and replaying user journeys by hand, a short path from sign-up to first audit, and a prioritised list of fixes instead of an undifferentiated backlog of violations. It also means documentation that is ready when it is requested by procurement, legal or customers, and monitoring that keeps a product conformant as it changes. The website summarises the goal as building products for everyone, not just running audits. Concrete scenarios described in the content include a product team that wants to run a first automated audit with no configuration simply by entering its product URL; engineering teams that need AI-generated, code-level fixes wired into GitHub and their CI/CD pipeline so issues are caught before they ship; teams asked for a VPAT or an accessibility statement by procurement or a customer, who need compliance dashboards and documentation on demand; and growing products that need continuous monitoring to catch regressions introduced by new releases. The DevAlly AI Agent supports the case where a team wants to verify a full user journey — described in plain English — and have each stage of it audited against WCAG automatically. DevAlly is aimed at product teams who ship fast, and specifically at teams selling into markets where accessibility is mandatory or expected — the US, the EU and the UK — as well as organisations for which federal procurement and enterprise buyers require VPATs. The site emphasises that no accessibility expertise is needed, which suggests it is intended to be usable by teams without a dedicated accessibility specialist. Mentioned integrations and touchpoints include GitHub, CI/CD pipelines, an MCP integration for the editor, and a Chrome extension called Wendy described in the company's blog. On pricing, the website offers a free way to get started, with no credit card required, alongside a Request a Demo path for teams that want a walkthrough. The product is described as being live on Product Hunt as DevAlly AI Agent. The core value proposition is straightforward: DevAlly makes accessibility compliance something a fast-moving product team can actually keep up with. By combining automated scanning, severity-based prioritisation, AI-generated code-level fixes, on-demand compliance documentation and continuous monitoring into one end-to-end platform — and by letting a user journey be captured in natural language — it turns accessibility from a periodic, expensive audit into an ongoing part of shipping software.
Rool is a full private cloud machine that brings your files, software and AI into a single workspace. Instead of being only a chat window, Rool gives you a complete machine in the cloud that holds your documents, runs software, and keeps the work and memory produced between tasks. The machine is hosted in the EU, and the AI models that run on it are self-hosted by Rool in the EU as well. Rool is built for privacy-conscious individuals, teams and creators who want to work with AI without giving up control of their content. Your workspace stays private to you and to the people you choose to invite, and you can start on a free machine without a credit card. Most mainstream AI tools ask you to trade your data for convenience. Content you upload may be used to train models, advertising may be part of the deal, and your data may sit in jurisdictions far from where you or your customers are. Rool takes a different position. The company states that it sells Rool, not your data: there are no ads, no data sales, and your files and conversations are never used to train AI models. Your data is stored in Finland, under EU law, and your Rool Machine is hosted in the EU. For individuals and teams who care about where their information lives and who can reach it, that difference is the whole point rather than a footnote. Chat is just the surface in Rool. Behind every conversation sits a full machine that holds your files, runs software and keeps your work and memory between tasks. That means a chat is not a dead end: you can start with a conversation and then build from there. The machine keeps the results of what you do and the context around them, so the next task does not begin from zero. Files, software and memory are the three pillars Rool highlights. Writing a document, working with your files, or running software all happen on the same machine, and the outputs stay there, ready for whatever you do next, rather than being scattered across separate tools that forget what happened before. Rool runs AI models on infrastructure it manages in the EU. Those self-hosted models are what you use to work on the documents, files and tasks inside your Rool Machine. Frontier AI models are included in every plan, so the free Standard tier is not limited to a cut-down model. Usage is measured in AI credits: Standard includes 240 AI credits per day, Plus includes 1,200 per day, and Pro includes 4,800 per day, with the balance refilling hourly up to a plan-specific ceiling of 1,000, 2,000 or 5,000. Keeping the models in the EU, on infrastructure Rool manages, means your workspace and the AI infrastructure that serves it sit closer together rather than across jurisdictions. Your existing tools can be connected to your Rool Machine. Rool provides built-in connectors and support for custom MCP servers, which bring external services into the workspace so you do not have to abandon the tools you already use. Connectors and MCP are listed as features of the Plus and Pro plans, and they appear alongside the custom subdomain option. Practically, this means the machine is not a sealed box: it can reach out to the services around your work and pull their capabilities into the same place where your files and memory already live. Rool describes this as bringing the tools you already use into your Rool workspace, keeping one environment instead of many disconnected ones. Privacy is not a setting in Rool; it is the shape of the product. Your machine is private to you and the people you invite, and you choose who gets access. Your files, conversations and memory stay in your own workspace. Rool states plainly that there are no ads and no data sales, and that your files and conversations are never used to train AI models. The European hosting story reinforces the same point: your Rool Machine is hosted in the EU, and the models are self-hosted in the EU too. For anyone whose work involves sensitive material, such as client documents, internal notes or personal writing, having a workspace that is not mined for advertising or model training removes a recurring source of hesitation. The overall approach is to give one person or a team a single persistent machine rather than a collection of disconnected chat sessions. You start with a chat, and the chat is how you get going, but everything it touches lands on the machine: the documents you write, the files you work with, the software you run, and the memory that carries context forward. Rool calls the memory system Object Memory, and full Object Memory is included in the free Standard plan. Because the machine keeps working state between tasks, you do not have to re-establish context every time you come back. Because the models run on Rool's own EU infrastructure, the AI is part of the same environment as your files instead of a separate service consuming them. The benefit is continuity with control. Work you do in Rool does not evaporate when a conversation ends; the results and the context stay on your machine, ready for the next task. You keep your files, conversations and memory in your own workspace and decide who else can see them. There are no ads and no data sales to work around, and your content is not used to train AI models, so you can bring real work into the tool rather than sanitised versions of it. EU hosting and EU self-hosted models give you a clearer answer when someone asks where the data lives. And because every machine starts free, with no credit card and no trial clock, the cost of trying that approach is zero. Rool fits workflows where a person or a small team needs to work across files and tasks with AI in the loop. Writing a document, working with existing files, or running software are the activities Rool names directly, with the machine keeping the results and context ready for what comes next. Teams can invite the people they work with and control who has access to the workspace. Creators get a place to keep ideas, files and AI work together instead of spread across unrelated apps. Anyone who needs to connect external services can do so through connectors or a custom MCP server and then work with those tools from inside the same machine. The pattern in every case is the same: start a chat, do the work, and let the machine hold onto it. Rool is available on the web and as mobile apps for iOS and Android, with download badges for the App Store and Google Play. Pricing is freemium. Standard is free forever: 240 AI credits per day, 2 Rool Machines, 1 GB of storage per Machine, a balance that refills hourly up to 1,000, full Object Memory and frontier AI models included. Plus costs €9 per month and multiplies the daily credits five times to 1,200, with 2 GB of storage per Machine, a refill ceiling of 2,000, faster hourly refills, a custom subdomain, and connectors/MCP. Pro costs €25 per month, twenty times the Standard credits at 4,800 per day, 5 Rool Machines, 10 GB of storage per Machine, a refill ceiling of 5,000, priority support from the Rool team, plus everything in Plus. Rool's proposition is simple to state: a full private AI machine with files, software and persistent memory, hosted in the EU, running models that Rool self-hosts in the EU, under a policy of no ads, no data sales and no training on your content. It takes the convenience of chatting with AI and attaches it to something that lasts, a machine that keeps your work and its context between tasks. For privacy-conscious individuals, teams and creators who want AI they can trust with real work, Rool offers a workspace you control, on your terms, and free to start.