Category Focus/categories/customer-service
Customer Service AI Tools
Discover and compare the best customer service AI tools and software. Browse 35+ curated tools with reviews and rankings.
Projects tracked
35
Sort mode
RECENT
Page
1
Discover and compare the best customer service AI tools and software. Browse 35+ curated tools with reviews and rankings.
Projects tracked
35
Sort mode
RECENT
Page
1
Embage is a no-code platform for building AI chat and voice agents that talk to your customers. You choose whether the agent handles support, sales or feedback, shape its tone, and put it live on your website as a chat window, a browser-based voice agent, or both — and on Telegram for chat. The agent answers from your own documents, acts inside the tools you already use through sub-agents, and leaves your team a scored record of every conversation. It is built for teams that want customer conversations handled automatically without writing code or installing anything, and it can be live in three steps: build, connect and embed. Embage frames the underlying problem simply: most companies throw the conversation away. Visitors arrive, ask questions, and leave, and whatever they said is lost unless someone happens to be watching. Embage positions its agent as a way to answer 24/7 while your team sleeps, to save every chat as a lead, ticket or feedback record, and to end each conversation with a next step — a score and a follow-up — rather than a raw transcript nobody reads. That framing runs through the whole product: the conversation is treated as data worth keeping and acting on, not just a support cost. Chat and voice both run live on your site. You can add a chat window, a voice agent, or both, and chat agents can also answer on Telegram. Voice runs in the browser with nothing for visitors to install, and visitors can interrupt mid-sentence instead of waiting for the agent to finish. At any point the conversation can be handed off to your team. Because the voice agent acts mid-call, it can book meetings and save records while it is still talking, and when a human takes over their replies are spoken aloud to the visitor. The same documents, tools and scored record apply whether the conversation happens by chat or by voice. The knowledge base is what the agent answers from. You upload files or add web pages, and the agent searches them before it answers rather than improvising. Supported formats include PDF, Word, PowerPoint, Excel, CSV and Markdown. Articles can be edited in place so answers update to match, and questions the agent could not answer are surfaced as knowledge gaps — a direct signal of what your documentation is missing. This keeps replies grounded in your own material and gives the team a feedback loop for improving it over time. The datastore turns chats into records. While the agent talks, it saves tickets, leads and feedback, using templates for tickets, a sales CRM, feedback and events. It asks for missing fields before saving, so a half-complete ticket does not land in your queue, and every row can be filtered, edited and acted on afterwards. That means the outcome of a conversation is structured data your team can work with, rather than free text someone has to re-read and retype into another system. Sub-agents are how the agent does the work rather than only describing it. They are workflows written in plain English that call your tools mid-conversation, connected through 360+ apps with one-click sign-in — Zendesk, Shopify, HubSpot, Gmail, Salesforce, Google Calendar, Google Meet, Slack and Stripe among them. Every tool call is logged. The contrast Embage draws is between the old sequence — leave the chat, search the docs in another tab, do the task in Shopify — and running the sub-agent, where the knowledge base is checked, the workflow is done and the reply is ready, all inside the conversation. Embage lets you bring your own model key. You can pick from 200+ models, or plug in your own key so your agent's replies bill to your provider rather than to Embage credits. Connection is through OpenRouter or Vercel AI Gateway, and a different model can be assigned to each agent and each sub-agent. Keys are encrypted and never shown again after they are entered. Mixed model choice matters because different agents and sub-agents have different jobs, and the option to run on your own key changes the cost profile: on the Free plan, chat replies on your own API key use zero Embage credits. After the conversation ends, Embage evaluates it. Every chat receives a 0–100 score plus a sentiment reading and a summary, action items with a priority and an owner, and a note of what your docs are missing. A conversation record might show a score, a short description of what the customer asked, a next step marked high priority, and a knowledge gap such as international returns. This is the second half of the product's promise: the interaction is not finished when the visitor leaves, because the record of it continues to drive follow-up work. Getting an agent live follows three steps. First you build: pick support, sales or feedback, and shape its tone — no code involved. Second you connect: add your docs, your forms and the apps you use. Third you embed: paste one snippet on your site, or connect Telegram. From there the agent runs on the channels you connected, using the same knowledge base, the same sub-agents and the same scored record, whether a customer reaches it by chat window, browser voice or Telegram. The stated outcomes follow from those pieces. The agent answers while the team is unavailable, including 24/7, so visitors are not left waiting. Every conversation becomes a lead, ticket or feedback record instead of disappearing when the tab closes. Questions that the agent cannot answer become visible knowledge gaps instead of silent failures. And each conversation closes with a score, a summary and a prioritized next step, so follow-up starts from a structured record. Because the voice agent acts mid-call, booking and record-saving happen during the conversation rather than afterwards. In support, the agent handles questions such as changing a delivery address on an order, starting a return within the free 30-day window, or looking up a refund, while the outcome is logged as a ticket. In sales, it qualifies visitors and saves them into a sales CRM template, then books meetings through connected calendar tools. In feedback collection, responses land in the datastore as feedback records. With voice enabled, an agent can act as a receptionist that books a demo for a specific slot and confirms it out loud. Each of these sessions is then scored and summarised, and the lead quality or follow-up work is attached to the record. Embage is in early access and priced to match usage. The Free plan costs $0 forever and is enough for a website agent if you bring your own OpenRouter or Vercel AI Gateway key, with chat replies using 0 Embage credits; it includes 200 knowledgebase searches, 500 datastore writes and 250 integration calls per month plus the website chat embed. Starter is $19/month with 1,000 AI credits, 100 voice sessions, 1,000 knowledgebase searches, 1,000 datastore writes and 200 integration calls, aimed at small businesses adding support, leads and feedback to a site. Pro is $59/month with 3,800 AI credits, 500 voice sessions, 1,500 knowledgebase searches, 10,000 datastore writes and 300 integration calls, positioned for growing teams using Embage as a daily AI receptionist. Enterprise is custom, for teams needing custom limits, dedicated support and security and deployment review. Paid plans are free for 7 days, voice is priced per session, and no credit card is required to start. Taken together, Embage is a way to put a working agent on your website and Telegram that answers from your own material, performs tasks in your connected tools, keeps every conversation as structured data, and reports back on what happened. Its value proposition is that the conversation is captured, acted on and analysed rather than thrown away.
Vaani Voice is a voice AI harness for building, running, and improving AI phone agents. It is aimed at teams that want a voice agent which sounds and behaves human without writing a single line of code: you describe the call you want in plain language, and the platform assembles the prompt, voice, language mix, and tools. From there you connect your tools and knowledge base and go live on a real phone number. Vaani frames every call as something that should produce a useful outcome, and states that every call ends with clean, structured data. The platform describes itself as built on millions of calls and presents itself as one connected platform for building agents, running calls, and improving every conversation. Phone conversations are still how many businesses qualify leads, handle order questions, and onboard customers, but Vaani frames the hard part as the quality of the call itself. It lists what it says every other platform still cannot get right: metallic voices, dead air, and awkward pauses. Its answer is a set of call-experience capabilities, including agents that make small talk so there is no silence, agents that pause when turn taking is relevant, automatic switching to the caller's language and dialect, realistic voices with emotional tags, and low latency. The second stated problem is build friction: a nuanced agent is tough to build, agents break on questions nobody thought to ask, stitching voice, language, and tools together takes time, and a single prompt tweak can quietly break a live agent. Vaani's Teacher AI and prompt-diff review flow are presented as the response to those problems. The first capability group is the build experience driven by Teacher AI. Instead of prompt engineering or flowcharts, you tell Teacher AI who to call, what to say, and what counts as success, in plain language. Vaani states that one sentence is enough to start. Teacher AI then asks clarifying questions about what is missing, covering languages, objections, qualifying criteria, and handoffs, and each answer tightens the agent before it ever makes a call. The platform then builds live in seconds, assembling the prompt, voice, language mix, and tools together with a readiness score as it goes, so what you get is described as a deployment-ready agent rather than a draft to finish. The second capability group is change control and ongoing refinement. When a prompt change is proposed, Vaani shows the prompt diff before anything is saved, together with recommended settings for latency, voice, and turn-taking, and nothing is saved until you approve it. Refinement does not restart the build: you can ask Teacher AI by chat to change the tone, add a language, or handle a new objection on an existing agent, and it updates the same way with a diff to review. This is framed as protection against the common failure where one prompt tweak quietly breaks a live agent. The third capability group is the conversation quality layer. Zero dead air means agents make small talk, illustrated by a caller asking where their order is and the agent answering that it will check. Turn taking means agents pause when it is relevant, such as pausing to listen when a caller says "hmm" or asks to change a date. Effective communication means automatic switching to the caller's language and dialect, illustrated by a request to move a visit to tomorrow at 10 AM. Ultra realistic voice means realistic voices with emotional tags, illustrated by a warm response to a worried caller. Lowest latency is described as a best-in-class P-90 latency of roughly 450 milliseconds. The site also references a sub-500ms multilingual engine and response accuracy on noisy telephony audio. The fourth capability group covers memory and call handling. Memories keeps every past call with a caller retained and stored, and context can be shared by a different agent. A custom context filter lets you choose how many past calls to use and which ones, and the agent receives cumulated context containing only what that call needs, such as an order number, a refund approval, a language preference, and a channel preference. The stated outcome is that the agent picks up where the last call left off, so customers do not repeat themselves and are less frustrated. Call screening keeps screened calls connected: Vaani answers the screening prompt and stays on the line while the customer decides whether to pick up. When asked who is calling, Vaani shares the agent's name, your company, and the reason for reaching out, then introduces itself again and explains the purpose of the call once the customer answers. Vaani states that about 98% of screening calls are handled in under 15 seconds. Overall, Vaani organizes its platform around four verbs shown across the site: Build, Humanise, Connect, Run, and Improve, summarized on the page as build agents, run calls, and improve every conversation in one connected platform. An agent management view lists all AI agents with agent name, ID, deployment status, deployed-on status, and last edited time, alongside the ability to archive or create a new agent. The promise of the flow is: describe the call, hear the agent, then let it dial only inside the window, with a live call demo available to listen to before deploying. The stated benefits are concentrated on call quality and operational focus. Because agents avoid dead air and handle turn taking, and because they switch languages and carry emotional tone, Vaani positions the resulting conversations as realistic rather than metallic. Because memories carry context across calls and across agents, customers do not repeat themselves. Because qualifying and handling happens on the agent side, human teams continue from informed, qualified conversations with context instead of raw records. And because every call ends with clean, structured data, calls produce outcomes rather than transcripts. Concrete use cases are documented as case studies. IndiaFilings used Vaani for automated first contact, qualifying founders in need of compliance services and passing them to an expert callback, with founders hearing the offer in their language and choosing how to continue. Prateek Group used Vaani for automated broker outreach, introducing the partner program, checking broker interest, and earning permission for a callback before relationship managers follow up. Sat Kartar Life used Vaani for inbound sales, answering product questions and confirming buying intent before transferring ready-to-buy customers to closers, with a callback path for customers who need more time. Memories is illustrated with an order support scenario covering a delayed order, a UPI refund, Hindi preference, and WhatsApp updates. An example agent named KYC - Onboarding also appears in the agent list. The platform is accessed through the web, with a start-free signup, documentation, a contact page, and a live call demo. Vaani also offers enterprise-grade solutions for AI phone calls, where you work with a dedicated Vaani engineer to implement custom agents, analytics, and automation. Customers and companies shown on the site include Uber, Accenture, Randstad, SBI Life, Bajaj Finserv, Mphasis, Krafton, Hero FinCorp, InCred, IndiaFilings, Prateek Group, and Sat Kartar Life. Vaani states it is backed by Google AI Accelerator, VentureCatalysts, nasscom ai, INDIAai, and kotak BizLabs. In short, Vaani's value proposition is a single harness for voice AI: describe the agent you want, let Teacher AI build and refine it, ship it on a real phone number, and let calls end with clean, structured data and qualified next conversations.
Chatway is a live chat and AI customer support platform with an all-in-one inbox, automation, and MCP. It is built for customer support and sales teams that want to handle every customer conversation from one place while adding AI where it helps most. Chatway lets businesses bring their own AI agent — connecting ChatGPT, Claude, Gemini, Cursor, or any MCP-compatible assistant — to manage customer conversations, reply to messages, search contacts, and access a knowledge base. Alongside that, Chatway ships with a built-in AI Support Agent, a shared inbox, a help center, automation, and iOS and Android mobile apps. Over 50,000 businesses use Chatway to build better customer connections. Customer support today is scattered. Conversations arrive through a website chat widget, WhatsApp, Facebook Messenger, Instagram, and email, and agents are expected to answer quickly without losing context or repeating themselves. Support teams also face rising volumes and the expectation of 24/7 availability, which is difficult to staff around the clock. Chatway addresses this by centralising every customer conversation in one unified inbox and by offering automation and AI so that routine questions can be handled instantly. The optional MCP connection means teams that already rely on an AI assistant can put that assistant to work on support, rather than starting over with a new tool. Chatway's built-in AI Support Agent answers questions and supports customers 24/7 across a website, WhatsApp, Instagram, Messenger, and Email. It is trained on your website and knowledge base, so it delivers instant, accurate answers in multiple languages and seamlessly hands conversations over to your team when human support is needed. For teams that already use an AI agent, Chatway supports Bring Your Own AI Agent with MCP and Webhooks. You connect your own agent — including Claude Code, OpenAI Codex, GitHub Copilot, Gemini, Devin, Cursor and others — through MCP and choose what it can access, so it can tag, hand off and help your team. It works alongside Chatway's built-in AI Support Agent rather than replacing it. Every conversation can live in a single all-in-one inbox. Chatway integrates with WhatsApp, Facebook Messenger, Instagram, X, Email, and Phone so customers can reach out through the channel they prefer while your team works from one place. Team collaboration tools let agents share notes, assign tasks, and work on conversations together, which improves efficiency and effectiveness. Live Visitors Insights shows who is browsing your website in real time so you can instantly start a conversation at the right moment. Multilingual Support translates incoming messages into agents' preferred languages in real time, supporting more than 20 languages, and the chat widget can be customised for diverse audiences. Automations and Smart Workflows let you create custom rules that respond to chats, form submissions, page visits, and more — engaging visitors, qualifying leads, and simplifying repetitive tasks. Deep eCommerce integration connects Chatway with platforms such as Shopify and WooCommerce so your team and AI agents get real-time order and cart insights, access to store data, and the ability to answer questions with relevant, up-to-date product information. A self-service Help Center lets you publish FAQs, guides, and documentation, while FAQ and Canned Responses give agents a library of common answers they can send in seconds. Analytics reports on your support activity so you can better understand customer interactions, and Segmentation categorises and labels conversations using specific criteria for more personalised support. Notifications keep you updated on all incoming messages with email and push alerts, and Full Customisation lets you personalise the chat widget to match your business's style and branding. Chatway's unique approach is that it does not force a choice between a human team and an AI agent. Human agents can reply to customers from the Chatway web or mobile app, work alone or with a team, and bring in an AI agent whenever they want. Conversations can be handed between AI and humans without losing context. Two paths are available for developers: connecting an existing AI assistant through MCP and webhooks, or building your own agent against the REST API. With the API route, you receive a signed webhook event the moment a visitor writes, and you reply through the REST API — and the API is included on every plan. The outcomes are practical: faster first responses, round-the-clock coverage, and less repetition for agents. Because the AI agent is trained on your own website and knowledge base, answers stay accurate and relevant. Because conversations are centralised in one inbox, agents do not have to switch between tools. And because handoffs between AI and humans preserve context, customers do not have to start over. Chatway reports over 1,000 five-star reviews across the iOS and Android app stores, and over 50,000 businesses already use it to build better customer connections. Chatway is positioned for a wide range of industries. eCommerce teams use it to recover carts, answer questions, and boost sales. SaaS teams use it to convert trial users into customers with support. Customer support teams use it to resolve issues quickly and improve satisfaction. Finance teams use it for secure client questions, education teams for student support, travel businesses for guiding travellers and answering booking questions, and real estate teams for responding to inquiries and closing deals. Professional services use it to connect with clients quickly and offer personalised service, HR and recruitment teams use it to engage candidates and streamline hiring, and nonprofits use it to engage supporters and build relationships. Chatway is aimed at customer support and sales teams of all sizes, including developers who want to build their own agents. It integrates with WhatsApp, Facebook Messenger, Instagram, X, Email, and Phone, with eCommerce platforms like Shopify and WooCommerce, and with site platforms such as Shopify, Wix, and Duda. Supported AI agents include Claude Code, Claude Desktop, ChatGPT, Codex, Cursor, Muse, Gemini, Grok, VS Code, Cline, Devin, OpenCode, Goose, Manus, and any MCP client. Pricing is free to start with no credit card required, and the API is included on every plan. In short, Chatway is a live chat and AI customer support platform that unifies every conversation, automates the routine, and lets you bring whichever AI agent you already trust. It lets support and sales teams deliver faster, more consistent answers across web, mobile, and social channels.
AgentSDR is an open-source, self-hosted AI SDR workspace for outbound sales teams. It runs email sequences, LinkedIn campaigns and WhatsApp calls from one place, and pairs them with an AI CRM that reads every reply, classifies it and drafts the answer. The product is described as the open-source AI SDR that replaces Clay, Smartlead, HubSpot and many more, and it is designed to run on your own server with your own model key. Its stated promise is to reach, reply and close from a single workspace: sequences on each channel, AI triage on every reply, and measurement of replies, meetings and customers in one view. It is built for teams that want to own their outbound stack instead of renting a hosted service. Outbound today is spread across a long list of separate tools. The AgentSDR landing page shows logos for Smartlead, Clay, Instantly, HubSpot, HeyReach, Attio, lemlist, Salesforce, Apollo.io, Pipedrive, Expandi, Close, Outreach, Lusha, Salesloft, Hunter, Waalaxy and folk, making the fragmentation of the modern sales stack visible. AgentSDR's answer is to collapse that stack into one self-hosted workspace where email, LinkedIn and WhatsApp run side by side and every reply lands in a single AI CRM. Because it is self-hosted, your leads, conversations and call recordings live in your own Postgres database and your own storage bucket, and there is no hosted AgentSDR service in the middle. Provider keys are encrypted at rest with AES-256-GCM, and the data and sending reputation stay yours. Email is the first channel. AgentSDR sends multi-step sequences from your own Google Workspace mailboxes, connected through a service account with domain-wide delegation. Any CSV or XLSX column can be used as a merge field, and the system supports {A|B} spin text. Each mailbox has its own daily cap — 30 by default — plus its own sending window and signature, and campaigns can share the same pool of mailboxes, which are assigned round-robin. The list tools include one-click unsubscribe and automatic bounce suppression. The email analytics view shows emails sent, leads contacted, replies, reply rate, bounced and unsubscribed, and it is explicit that opens and clicks are not recorded, so reply rate is the engagement metric to watch. A campaign table breaks those numbers down per campaign, and mailbox health is shown with near-limit warnings and connected versus failing accounts. LinkedIn campaigns run across several accounts through Unipile. A sequence consists of an invite, an accept message and three follow-ups. Safe pacing keeps the accounts inside LinkedIn's limits: 30 invites a day on premium accounts and 5 on free accounts, a randomised 30–60 second gap between invites, and sending only inside each account's working hours; an account that hits LinkedIn's own limit pauses for the day. Search batches can bring up to 400 leads a day per account into campaigns, and every LinkedIn reply appears in one thread view with an AI draft ready. WhatsApp adds calling and messaging. A Chrome extension, the AgentSDR Call Recorder, dials inside WhatsApp Web when you call a lead from AgentSDR, records both sides to your Cloudflare R2 bucket, and your chosen model writes the transcript; it relies on WhatsApp Web's English interface. Unanswered leads can be retried after 1, 2 and 4 days, and messages sync with a 24-hour warm-up for new numbers and a limit of 25 new chats a day per number. At the centre is the AI CRM and inbox. Every reply is classified as Interested, Customer, Not interested or Other, using your own stages. Grounded drafts are written from your knowledge base — pricing, FAQs, case studies and objections — and held for approval rather than sent automatically; reply sequences also have every follow-up step drafted for review. The analytics show how many drafts were sent, how many replies the AI classified, and the override rate for labels a person changed. In the sample data, 71% of sent drafts went out unedited (151 of 214). The inbox is keyboard-first: J and K move, Enter opens, and ⌘K jumps anywhere. An Action required queue centralises conversations waiting on you, follow-ups that are due, and drafts to review, alongside warnings such as failing mailboxes or disconnected LinkedIn accounts. Under every channel is one database of people and companies. You import CSV or XLSX, add your own columns of text, number, date or select, and duplicates match on email or LinkedIn. Enrichment tables let a column call an API, run a formula, ask your model or pull from Apollo, and a table can then become a campaign. The AI layer is bring-your-own-model: every AI call runs on your OpenRouter key, pinned to the provider you chose with fallbacks turned off, so your data only goes where you decided. Classification, reply drafts, transcription and AI table columns all run this way. Optional lead enrichment integrations for emails, phones and company data include Hunter, Lusha, RocketReach, Snov, FullEnrich, LeadMagic, Findymail, ZeroBounce and Apollo, plus six more. The overall method is expressed in three words: Reach, Triage and Measure. Reach covers sequences on email, LinkedIn and WhatsApp inside each channel's limits. Triage means every reply is classified by AI with the answer already drafted. Measure means replies, meetings and customers are tracked by channel in one view. Deployment follows the same self-hosted logic: clone the repository, copy the example environment file and set the database, auth and encryption secrets, then run docker compose up; the app is ready at localhost and each channel is connected from inside the interface. Guardrails apply everywhere: daily caps, sending windows, warm-up for new numbers, and Do Not Contact honoured on every channel. The AI proposes and a person approves — a confident classification can move a lead forward in the pipeline, but a backward move, a low-confidence call and every new Customer are held for a person. The benefit is ownership and control. You send from your own accounts, so sending reputation and data stay yours; you pay for your server and your own AI usage rather than seats, tiers or per-contact fees. Analytics turn conversations into a clear view of meetings and customers by channel. In the sample workspace, 512 replies produced 104 positive replies (27% of people who replied), 37 meetings and 6 customers, with a median first response of 38 minutes; channel reply rates were 4.1% for email, 9% for LinkedIn and 18% for WhatsApp. Because drafts wait for approval, the human stays in charge of what goes out, while low-confidence classifications are held for review. Concrete workflows run through the workspace daily. A team imports a list, builds an enrichment table, and creates a campaign from it. Email sequences pace themselves across a pool of Google Workspace mailboxes, respecting caps and windows. LinkedIn accounts send invites and follow-ups within their limits, and replies arrive in a thread with a draft ready. WhatsApp calls are dialled from AgentSDR, recorded, transcribed and retried if unanswered. Reps then work the triage queue: approving or editing AI drafts, clearing follow-ups that are due, and moving leads through stages such as Information Requested, Demo Requested, Meeting Requested, Meeting Done and Trial User. Analytics closes the loop by showing which channel brought the replies, meetings and customers, and a single deployment can hold several organisations with separate leads, inboxes and connected accounts. AgentSDR is built for sales teams, founders and agencies that run outbound and want a self-hosted alternative to a stack of subscriptions; the product explicitly supports whole teams, with owners, admins and members, and multiple organisations in one deployment. What you connect is your own accounts: Google Workspace mailboxes for email sequences, Unipile for LinkedIn and WhatsApp, OpenRouter for every AI step, and Cloudflare R2 for call recordings, with optional enrichment providers for table data. The stack is a TypeScript Next.js 16 application using React 19, Postgres, Drizzle, Tailwind 4, Bun and Docker, and it needs a machine that runs Docker plus PostgreSQL 16 or newer. Pricing is free: the project is open source, with no seats or per-contact fees, so the only costs are your server, your connected accounts and your AI usage. AgentSDR's core proposition is simple: one open-source, self-hosted workspace where email sequences, LinkedIn campaigns and WhatsApp calls sit beside an AI CRM that triages every reply and prepares the answer, with your data, your model key and your sending reputation kept on your own infrastructure. Teams reach, reply and close from a single place, with guardrails on every channel and a human approving the drafts.
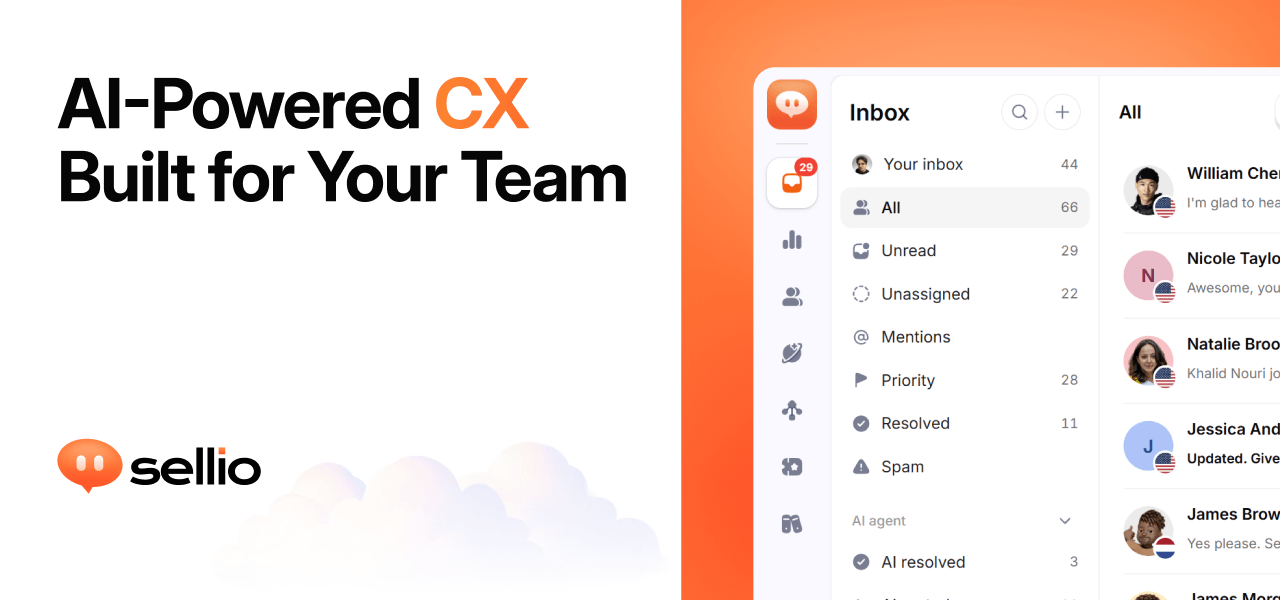
Sellio is an AI customer support platform that puts every customer conversation into one shared inbox. Website chat, WhatsApp, Instagram, Telegram, and email all land in the same place, so a support team works from a single thread rather than switching between tools. On top of the inbox, Sellio adds tickets for work that continues after a chat, an AI agent that can be switched on when a team is ready, and analytics that show how each conversation ended and how it felt. It is aimed at the kinds of teams that answer customers all day: stores and ecommerce businesses, hotels, SaaS companies, local businesses, help desk teams, and agencies. The website describes the product simply as AI customer support in one inbox, with one line added to your site to get started. Support conversations rarely stay in one place. A customer asks something through a website chat widget, follows up on Instagram, sends a complaint by email, and messages on WhatsApp, and each of those threads normally lives in a different tool with its own history. When a conversation is split like that, handoffs lose context, customers repeat themselves, and replies get missed. Sellio frames this as a problem that looks the same in every industry: missed replies look the same whether you run a store, a hotel, or a SaaS product. The shared inbox is the response, one place where every channel lands, every reply and note stays with the thread, and the next step is always clear to whoever picks it up. The core of Sellio is the shared inbox. It is built around clear threads with next steps: every reply, internal note, and handoff stays attached to the same conversation, so anyone on the team can see what was said and what should happen next. Teams work the inbox together rather than forwarding messages around, and because every channel is in one place, an agent does not have to remember which app a customer used. When a conversation turns into work that continues beyond the chat, Sellio lets the team raise a ticket from the thread, assign it, and keep the full history attached, so context survives the move from chat to task. The AI agent is optional and separate from the free chat and inbox. Sellio emphasises that you add it when you decide you are ready: you point the agent at your site, docs, and FAQs so its answers stay grounded in what you actually ship, rather than in whatever a general model happens to know. The agent's first job is the first reply on website chat, which is where many conversations begin. Where the AI cannot finish, it hands off to a person without losing context, so the human sees the same thread the AI saw. The website also highlights staying in control of cost as part of how the agent is positioned, and its FAQ addresses both how the AI learns about your product and whether a person can take over from the AI. Analytics in Sellio are meant to show what to fix next. The product follows every conversation through to how it ended and how it felt, and places automation, resolution, and CX rates beside each other in one funnel, so a team can see performance and customer experience together instead of in separate reports. Topics are drawn from real chats, which surfaces what customers actually ask about rather than what a team assumes they ask about. Sellio also presents response time that improves and CSAT that explains itself as part of the same picture, connecting speed, satisfaction, and outcomes in one view. Getting started is deliberately light. Sellio is installed by adding one line or one script tag to a site, which produces an on-brand chat widget; the site notes that website chat and the shared inbox are free, and that no credit card is required to start. AI is only switched on when a team chooses to switch it on, so a business can run a human support inbox first and layer automation on later. New conversations can be mirrored into Slack, Discord, and Microsoft Teams, so teammates who do not sit in the inbox still see what is happening. The overall approach is staged: inbox and chat first, other channels and AI as the team needs them. The stated benefit is fewer missed replies. Because every channel lands in one inbox and every thread keeps its history, handoffs happen without losing context and customers do not have to repeat themselves. Teams get a clear next step on each conversation, an AI agent that answers from their own documentation, and a funnel that shows how conversations ended and how customers felt. Cost stays controllable: the free plan covers web chat and the shared inbox with no trial clock and no credit card, and paid plans are only needed for more seats, channels, AI agents, and AI credits. Sellio lists the industries and situations it fits. Ecommerce teams can run live chat on Shopify in the same inbox as WhatsApp, Instagram, and email. Hospitality businesses such as hotels can put WhatsApp, Instagram, and website chat in one inbox for front desk and operations. SaaS companies can start with website chat and place every other channel beside it for the whole team. Local businesses can add a live chat bubble to their site along with the channels their neighbourhood already uses. Help desk teams can raise work from a conversation, assign it, and keep the full history, and agencies can run a shared inbox that several people assign, note, and resolve together. On channels and integrations, the website says website chat, WhatsApp, Instagram, Telegram, and email land in one inbox, while Slack, Discord, and Microsoft Teams can mirror new conversations for the team. Logos shown on the page include Stripe, ClickUp, Zoom, Salesforce, Discord, Telegram, Trello, GitLab, WhatsApp, Messenger, Jira, Linear, Shopify, Notion, Microsoft Teams, Zapier, Instagram, Asana, Slack, HubSpot, and GitHub, with the note that six integrations are available now and the rest are on the way. Pricing is straightforward: website chat and the shared inbox are free, while email and messaging channels start on Mini. The Free plan includes two seats, one channel, and one API key, with one AI agent and five AI conversations, and nothing expires; more seats, channels, AI agents, and AI credits come from the paid plans. Sellio's proposition is that support does not have to be scattered or complicated to set up. One inbox holds the conversations, one script tag puts chat on the site, tickets carry work forward, an optional AI agent answers from your own docs and hands off when a person is needed, and analytics show what happened and how it felt. Teams can start on the free plan without a credit card and stay there, adding channels, agents, and AI credits only when the workload grows.
Chat.sh is a help center that answers the question instead of handing back a list of titles. You type your question in your own words, and the AI search reads it, retrieves the relevant passages, writes the answer, and shows the pages it used. It is built for teams that need a public help center for their product and want it served on their own domain — either as a custom domain such as help.yoursite.com, or in a folder on the site they already run, such as yoursite.com/help. The product exists because its maker was a longtime Intercom customer until Intercom's help center search broke. The fix did not come fast enough, so he built his own. The frustration he describes is familiar to anyone who has run support documentation: most help centers give you a subdomain, a keyword search, and a monthly bill, and the old stack hands every team the same URLs, the same search, and the same page with a different logo on it. When a keyword index is handed the word "domain", it returns five titles that all contain that word rather than the one page that answers the question. Chat.sh is a deliberate response to that fixed format. The centrepiece is search that reads the question. A model retrieves the relevant passages from the knowledge base and writes an answer, then displays the pages it used, so the reader can verify where the answer came from. Answers come from published articles only, which keeps the output grounded in documentation the team has actually written and approved. The result is closer to a colleague answering than a search box listing: instead of a list of titles the reader must open one by one, they get the answer directly, with its sources attached. Underneath sits one knowledge base that feeds three ways of answering. Content goes in once as articles, web links, files, or TXT and markdown, and the help center, the messenger, and the markdown you hand to an AI assistant all come from that same source. The help center is a public site that answers rather than handing back a list of titles, reachable at yoursite.com/help, help.yoursite.com, or your-team.chat.sh. The chat messenger, shipping next, puts the same answers in a widget on your app so a stuck customer never has to leave the page they are stuck on; each AI reply in it uses one credit from the monthly allowance. The AI agent side lets you copy any page as markdown, view it as plain text, open it directly in ChatGPT or Claude to ask questions about it, or copy every published article at once for pasting into AI tools, and an agent can also start from llms.txt. Presentation is treated as part of the product. You can name a folder — /guide, /help, or whatever you call it — and the help center is served from there on the domain you already run, keeping the same domain and the same analytics with no subdomain to explain. If you prefer, you can point a domain you own at the help center instead. Article addresses are written for people: there is no numeric id wedged into the path, and the slug is the title and is yours to change. Each page draws its own preview card, so a link dropped in Slack arrives as the article rather than as your logo, and theming lets you pick the accent and the mark. Every page follows that choice and stays readable, because the colour is darkened until it is. Put together, the product's approach is to treat support content as a single source that is published to several surfaces rather than as a website bolted onto a subscription tool. You maintain one knowledge base; Chat.sh answers from it in a help center on your own domain or in a folder on your existing site, will answer from it inside an app widget, and exports it as markdown for assistants such as ChatGPT and Claude. Nothing is duplicated per channel, and the answer always cites the pages it drew on. The benefits follow from those choices. Readers get answers instead of search results, with the sources shown so they can check them. The help center lives on a domain the team already owns, so it inherits existing analytics and needs no new subdomain to explain to anyone. Documentation becomes usable inside AI tools through markdown export and llms.txt. And commercially, the product is bought once rather than rented: your own domain is $399 once, never a subscription, and the price rises by $100 each time a new capability ships, so buying early costs the least. Concrete uses follow the same shape. A team that wants docs at yoursite.com/guide names the folder and publishes there, keeping the help center alongside the rest of the site. A team that prefers a dedicated address points a custom domain at it. A support lead drops an article link into Slack and the preview card carries the article itself. A developer copies a page as markdown and opens it in ChatGPT or Claude to ask follow-up questions, or copies the whole help center into an AI tool. Live examples cited in the content are testimonial.to/guide and chat.sh/help. Chat.sh is free for 50 pages and 100 AI answers a month with no card required. Every price tier includes the help center, 1,000 pages and 1,000 AI credits a month per workspace; one credit is one answer, here or in the messenger, and when the month's credits are gone, 1,000 more cost $20 as a one-time purchase. Page counting is defined rather than vague: a link counts as one page for every 2,500 characters of its text, an article you write counts as one page, and a PDF counts as one page per page of the file. The lifetime deal adds your own domain, bigger ceilings, and your agents. The chat messenger is shipping next and the inbox is shipping after it; the inbox lets teammates take over a conversation, with three people per workspace and each person after that at $10 a month, and human replies do not use AI credits. Launch-day buyers get $200 off any lifetime deal with the code PHLAUNCH, taking $399 to $199 and $799 to $599, until October 2 at 12 AM PT. Chat.sh's value proposition is narrow and clear: a help center whose search answers the question and cites its sources, hosted on your own domain or in a folder on the site you already run, with the same knowledge base exported as markdown for AI assistants — and paid for once rather than every month.
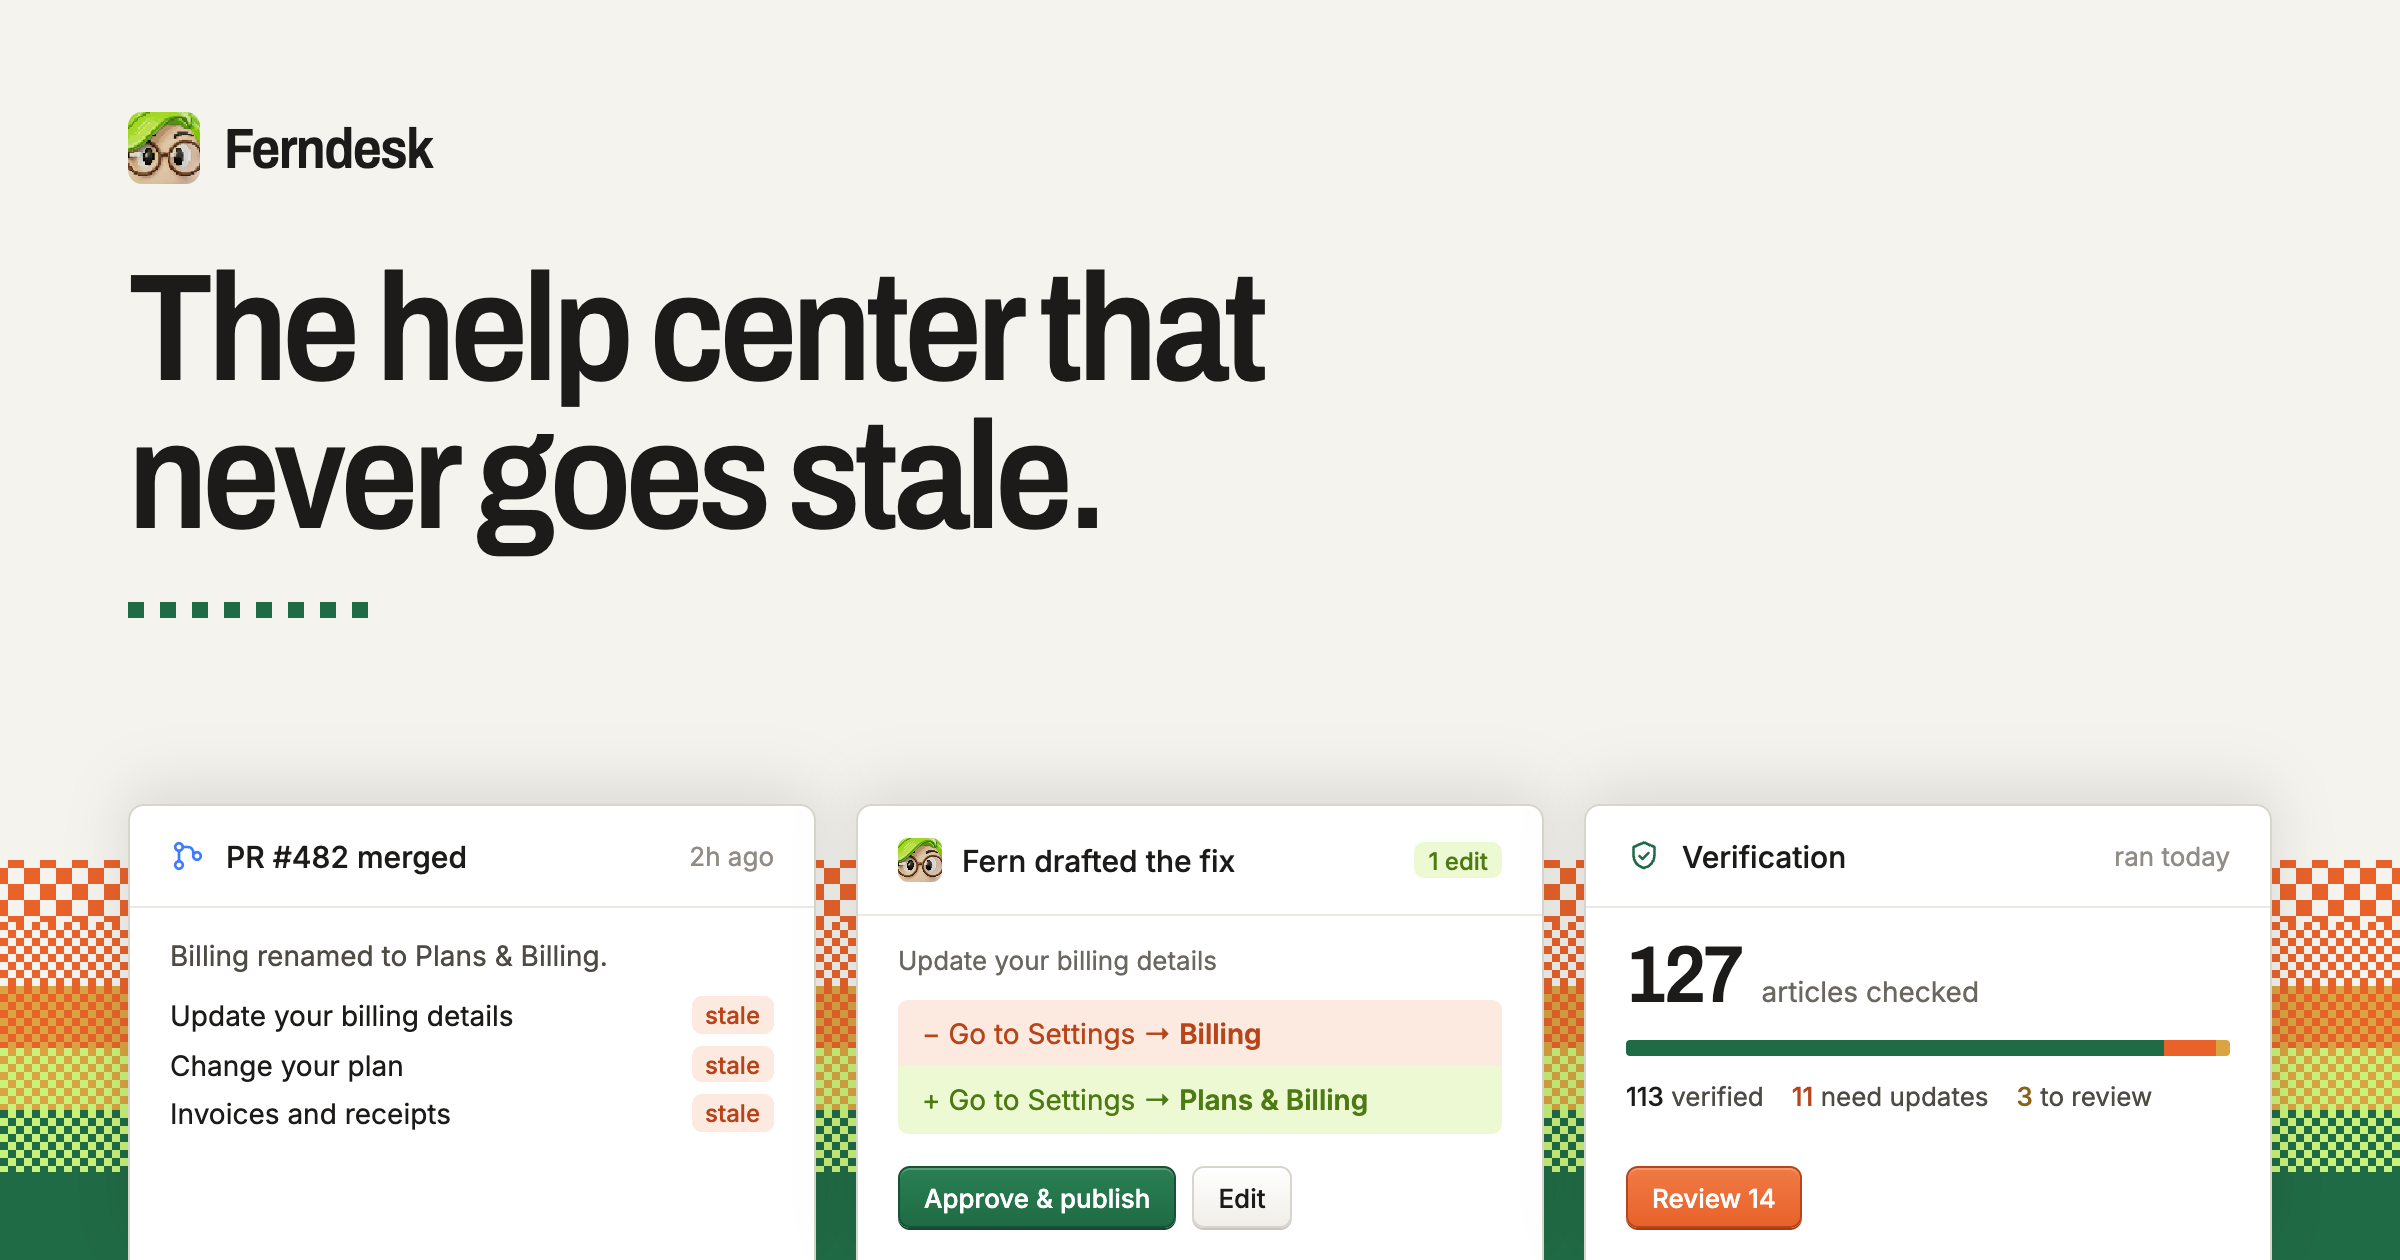
Ferndesk is a complete help center built around an agent named Fern that checks every article against your product, catches what changed, and drafts the fixes for you. It is a single place for a public help portal, AI answers, an in-app widget, API documentation, private docs, translations and analytics. The purpose stated on the site is to keep help content accurate while a team keeps shipping, and to give customers everything they need to help themselves so fewer of them need support. Docs can also be managed from Claude Code, Cursor or ChatGPT. Ferndesk exists because documentation goes stale the moment a team keeps shipping. The site describes the situation plainly: this month you changed a default, and yet your docs were last updated three months ago. It lists the everyday changes that quietly invalidate help content — renaming a plan, killing a feature, moving the export button, adding a plan, changing the pricing page, breaking a link, shipping a new flow, renaming a button, changing a setting — and points out that it is not the team's fault, because keeping docs true while shipping every week is tough. Customers echo the same pain: Brennan Dunn, Founder of RightMessage, says that before Ferndesk the process for updating documentation was basically hoping they would remember to do it, while Tristan Roth, Founder of ISMS Copilot, says his team ships features every week and that updating docs is hell. Fed, Founder of GummySearch, notes that he used to write articles once and they went stale right from day one, and Laura Elizabeth of Client Portal says writing documentation was something she never did and it showed in her help docs. Ferndesk's process is presented in three steps. The first is to connect your tools: your codebase, your live product and your support inbox. The site says this takes ten minutes, after which Fern can see what your customers see. Named integrations shown on the homepage include GitHub, Intercom, Linear, Zendesk, Slack, Help Scout and Discord, alongside an example live product such as app.acme.com. The second step is verification: Fern checks every article, and each claim is checked against the code and the product. Anything that is wrong comes back as a change you can approve, together with the reason it was flagged. The homepage illustrates this with a claim marked as no longer true — an article telling readers to update billing details at Settings → Billing when the product now uses Settings → Plans & Billing — presented as a proposed edit with Review and Approve & publish actions. The third step is that new releases document themselves. When a pull request merges, Fern writes the article before the release goes out. The example shown is PR #530, 'Add image editing to Fern', after which Fern drafted documentation for a new capability, 'Editing images in articles', marked NEW, plus an UPDATED article about automating screenshots in your docs. The four capabilities highlighted at the top of the site are verification, the help center itself, automatic updates and AI conversations. Beyond maintaining articles, Ferndesk is a full help center that a team can run, described as built to bring tickets down. The public help center can live on your own domain or at /help, is fast and searchable, and is indexed by Google and by AI search engines. AI conversations let customers ask in plain language and receive answers drawn from your verified docs rather than a guess. The in-app widget requires a single script tag and puts search, articles and AI chat inside your product, exactly where people get stuck. When the widget cannot answer a question, escalation hands the conversation off to Intercom, Zendesk or Help Scout, so customers still reach a human channel. The remaining help center capabilities cover technical and internal documentation. API documentation provides an OpenAPI reference with a try-it playground sitting next to your customer docs. Private docs can be protected with magic link, OIDC or JWT, and are intended for customers, partners or your own team — an internal knowledge base use case. Translations provide a multilingual help center with a glossary and language-prefixed routes; Metricool, for example, has seven languages live on Ferndesk. Analytics reports searches, missed searches, failed answers and feedback, so you can see what to write next. The site also describes a compounding benefit it calls smarter AI: the docs Fern keeps current are the same docs your support AI trains on, which is how Metricool uses Ferndesk to train its AI support agents. The unique approach is the combination of verification, drafting and human approval. Rather than asking a team to remember to update documentation, Ferndesk reads the codebase, the live product and the support inbox, checks every claim in every article, and returns a concrete change with the reason it is needed. Nothing publishes without you: you review and approve, and Ferndesk publishes from then on. The site frames the shift as moving from hoping your docs are right to knowing they are right, and describes the workflow as connecting your tools, letting Fern check every article against what your product actually does, fixing what is wrong, and writing the docs for what ships next. Migration is another explicit part of the product. The site argues that the migration teams keep putting off takes ten minutes, because moving help centers normally means broken links, lost rankings and a week of copy-paste. Ferndesk says it brings every article, image and URL over intact, with one click, every URL preserved and redirects created. Importantly, your support tool does not have to change: your inbox, chat and ticketing stay where they are, and Ferndesk keeps reading tickets from it. Imports are listed from Intercom, Zendesk, Crisp, Help Scout, HubSpot, GitBook, Document360 and every other help center. One customer, Juan, Founder of Duplika, describes migrating from Zendesk Guide as feeling like an upgrade — faster, with no paid add-ons, and the knowledge base living at a subfolder of their domain. The outcomes customers report are concrete. Founders say they save 20 hours a month on docs; Tristan Roth of ISMS Copilot says he does in five minutes what used to take an hour and that Ferndesk makes it easy to ship more and scale. Laura Elizabeth of Client Portal says her support requests have dropped significantly, and that simply being able to see what customers search for and cannot find answers to was huge on its own. SEO Gets reports a measurable drop in churn within three months of launch and even organic clicks to queries they did not expect to rank for. Metricool's Chief Customer Officer, Jose Julio, says they would be miles away from getting this into a working product, after having scoped a custom build on the Crisp API. The site summarises the impact for founders who used to dread updating docs: they now ship features every week while Fern keeps every help article accurate. Typical scenarios described on the site include a team shipping a weekly release and needing the help article to exist before the release goes out; a founder renaming a plan or changing a setting and needing every affected article corrected; a support team that wants customers to answer their own questions through search, articles and AI chat before opening a ticket; a company moving off an existing help center such as Zendesk Guide, Intercom or GitBook without losing URLs or rankings; a company serving customers in several languages from one knowledge base; and a product team publishing an OpenAPI reference and private or internal documentation alongside its public docs. In each case, the same verified article set serves the portal, the widget, the AI answers and the support AI. Ferndesk states that it is trusted by more than 100 software teams, and the customers named include Metricool, Zeffy, Andri, PixelFlow, SEO Gets, RightMessage, ISMS Copilot, GummySearch, Client Portal and Duplika — largely SaaS founders, customer success and support leaders, and documentation owners. The site also lists a set of pre-switch questions it answers, covering whether Fern can maintain docs where they already live (no — Ferndesk verifies and updates articles that live in Ferndesk, while your support tool stays where it is and Fern keeps reading tickets from it), what verified means, how often verification runs, what happens if Fern gets something wrong, whether URLs break on import, codebase safety, working without GitHub, custom domains, free trials and what happens if you leave. The signup flow offers a 7-day free trial with no card required. In short, Ferndesk pairs a complete, self-service help center with an agent that keeps it honest. Import your existing content, connect your codebase, product and support inbox, and from then on every article is checked, every fix is drafted, and nothing publishes without your approval — a help center that does not go stale, and support teams that answer fewer repetitive questions.
IntellAgents.io is a single AI agent platform for customer communication. It answers inbound calls, places outbound calls, and handles conversations across WhatsApp, Instagram, Facebook, Telegram, and a website widget — all live 24/7, in over 36 languages, drawing from one knowledge base that a business sets up once. The system is built for companies that want every customer request answered promptly without staffing a round-the-clock support desk, and it covers both AI agents and human operators in the same system. The product is positioned around a specific, common failure: missed calls and slow replies. As the site puts it, most businesses juggle a different tool for every channel — one for phone support, another for WhatsApp, another for the website chatbot. That fragmentation means leads wait, messages sit unanswered overnight, and context is scattered across tools. IntellAgents replaces all of it with one AI agent that covers the phone line, the social inboxes, and the website at the same time, so a customer writing in French at 1:30 AM gets the same quality of answer as someone calling during business hours. The stated goal is simple: stop losing customers to missed calls and slow replies. Call handling is the core of the platform. The Inbound Call Handling capability means the AI answers every customer call instantly, 24/7 — no queue and no missed calls. Phone numbers and SIP support make it a complete voice agent for your line: it answers every inbound call and can place outbound ones too. A 24/7 hour availability promise means agents handle every inquiry around the clock, across every time zone, without fatigue. Language coverage spans over 36 languages, so the AI communicates fluently with customers without needing a translator; the platform's plans offer three languages on Starter, up to five on Pro, and unlimited languages on Business. Beyond voice, IntellAgents connects the messaging channels where customers already are. Facebook Messenger conversations are handled without anyone watching the inbox. Instagram DMs are answered the moment they arrive, day or night. Telegram is supported through your own Telegram bot, connected in a couple of clicks. WhatsApp Business gets two-way conversations answered automatically. On the website, a single snippet drops in a widget where visitors can either type to the agent or start a live voice call with it without leaving the page. Connecting a channel takes a couple of clicks — no developer and no separate bot to train for each one. A unified knowledge base sits behind all of it. All conversations — calls, DMs, comments — feed into a single unified source, and updating once reflects everywhere. Chat Summaries are generated instantly after every interaction, giving a clear and concise record so your team always knows exactly what happened. Escalation Workflows detect when a human touch is needed and route the conversation to the right person instantly with full context. Every escalation, follow-up, complaint, or callback can be logged as a ticket mid-call on a Requests board, where tickets move across New, Triage, In Progress, and Resolved and are tagged with the channel they arrived on. It works the same whether the request came in on phone, chat, or email, so nothing falls through the cracks. The platform's defining approach is unification. IntellAgents unifies AI agents, human operators, customer history, and escalation workflows into one system. AI resolves requests instantly, and when a human is needed, the conversation hands off with full context so the team never starts from zero. Rather than deploying a separate bot per channel, businesses configure the agent once against a single knowledge base and let it operate everywhere their customers are — from the first phone call to the last DM. The stated outcome is straightforward: cut support costs and never miss a lead. One AI system handles calls, messages, and follow-ups across every channel automatically, reducing support costs, responding instantly, and freeing the team to focus on what matters most. The AI agent service can answer common questions, qualify leads, book appointments, and support customers 24/7, and it can transfer the customer to a real person when needed. Plan descriptions frame the value in terms of headcount: Starter handles up to 60% of repetitive calls automatically, Pro is positioned as replacing one to two support agents on repeat queries across all channels, and Business as replacing three to five support agents with full call and chat automation at scale. The site lists industry starting points that suggest where the product is applied: Restaurant, Dental Clinic, Orders & E-commerce, Salon & Spa, Auto Service, Call Center, Bank, IT Company, and Telecom, plus a Custom Board option. A typical scenario is an overnight social inbox: a customer asks in Spanish at 11:42 PM whether the business is open tomorrow and gets an answer; a question in Russian at 4:07 AM about consultation pricing is answered too; an Instagram DM at 2:15 AM about north-side delivery is handled; a Facebook question in French at 1:30 AM about weekend delivery is answered. During a call, an agent can log an escalation, follow-up, complaint, or callback as a ticket without leaving the conversation. Pricing is published in monthly and annual terms, with annual saving 20%. A social-channels-only option is listed at $20/mo with approximately 3,000 AI replies included per month. The Starter plan is $45/mo with 200 minutes per month, $0.12/min after that, and 7,500 AI replies per month, including inbound calls 24/7, basic FAQ responses, call summaries, one knowledge base, three languages, and basic human handoff. Pro is $149/mo with 700 minutes, 25,000 AI replies, inbound and outbound calls, Instagram, Facebook, WhatsApp and Telegram, a unified knowledge base, human handoff and escalation, up to five languages, and follow-up workflows. Business is $449/mo with 2,000 minutes, 75,000 AI replies, task creation and CRM sync, advanced call routing, unlimited languages, priority support, and advanced analytics. Enterprise offers a custom setup with unlimited minutes, multi-agent setup, custom workflows, branded voice, CRM/API integrations, advanced routing, and dedicated support. Extra minutes are billed at $0.12/min on all plans, and no credit card is required to start. In short, IntellAgents.io brings the phone line, the social inboxes, and the website widget under one AI agent driven by a single knowledge base. By answering every call and every message 24/7 in the customer's own language, escalating to people only when it matters, and logging every request on one board, it lets a business respond instantly across every channel without adding headcount.
Sierra's multimodal agents are AI agents built for customer conversations that bring voice, text, and visuals into the same interaction. Instead of forcing a customer to choose a single medium, the agent automatically shifts between modes as the conversation requires. Voice is used when a customer wants to explain what they need, a visual when it helps to compare options side by side, and text when someone wants to reference something later. Sierra frames the result as an interface that morphs with the conversation, so customers get the best of each medium without having to pick just one. The agents are intended for companies that handle customer interactions and want those interactions to feel continuous rather than fragmented. The problem these agents address is familiar to anyone who has tried to complete a purchase or a change over the phone. Sierra uses the example of upgrading a mobile plan: a representative talks through models, colors, storage sizes, and monthly rates, and the customer is left comparing all of it in their head and picking a phone they cannot picture. The call is genuinely good for parts of the task, because it is easier to say what you actually need and to ask questions than it is over text. But the customer cannot see the thing they are about to buy, and that gap makes the decision harder and slower than it needs to be. Sierra's multimodal agents are described as closing that gap by bringing voice, text, and visuals into the same conversation. Connecting multiple channels is not, in Sierra's framing, the difficult part. The real trick is knowing which modality to use when: voice to explain what you need, a visual to compare options side by side, or text when you want to reference something later. Agents built on Sierra anticipate what is needed for each conversation and automatically shift between modes. Crucially, that switching happens without making the customer start over or repeat themselves, which is what usually happens when an interaction moves between a phone call, a chat window, and a self-service screen. The interface is meant to follow the conversation rather than the other way around, so the customer never has to re-explain context that the agent already has. Concrete examples show how that plays out in practice. If a flight is disrupted and a customer calls the airline to get a new flight, instead of a representative reading alternate options off one by one, the options appear laid out with departure times, layovers, and pricing right in the conversation. The customer picks one, and the agent keeps going from there. Choosing a seat works the same way: the customer sees the seat map and taps the seat they want. And for times when it is easier to talk than to type, the customer can switch to voice and explain exactly what they need, with the agent capturing those details instead of asking the person to type a paragraph into a text box. Multimodal agents also follow Sierra's approach of one agent for every surface. You can build your agent once and deploy it across all channels, and the same is true of multimodal components: once you build a visual component, your agent can use it everywhere it lives. That approach extends to Sierra's MCP UI integration, which lets you bring interactive components such as product cards, comparison tables, calendars, and forms directly into the conversation. Your team designs and hosts those components, so you decide how they look, what they show, and when they change. When you make an update, it is automatically reflected everywhere without needing to redeploy or maintain different versions for each platform. When something needs more room, a component can expand to full screen to show calendars, long comparison tables, multi-step forms, and more. This matters because the interface can scale with the complexity of a task without the customer ever leaving the conversation. The underlying idea is that the conversation is the interface: the customer says what they need and the agent figures out the rest, using whichever mode of communication fits the moment. Multimodality is the mechanism that lets that principle hold true across tasks that involve talking, reading, comparing, and tapping to confirm. For customers, the outcome is that they do not have to choose. On a single call, a customer can talk through what they need, glance at a screen to compare their options, and tap to confirm, without ever pausing the conversation to switch tools. That continuity removes the repetition and dead ends that usually come with moving between a phone call and a screen. For the businesses deploying these agents, the stated benefit is that multimodal experiences are as easy to build and deploy as they are for customers to use, thanks to the build-once, deploy-everywhere model and components that are owned and updated centrally. Use cases described in the content include telecommunications journeys such as upgrading a mobile plan, where the customer talks through models, colors, storage sizes, and monthly rates while seeing the options rather than holding them in their head. Travel is another: rebooking a disrupted flight while alternate options with departure times, layovers, and pricing appear in the conversation, and selecting a seat by tapping a seat map. Forms, calendars, product cards, and comparison tables can all be embedded where a conversation needs them, including multi-step forms that can expand to full screen. The agents are aimed at organizations that run customer interactions and want to design the experience themselves. Sierra emphasizes that your team designs and hosts the components used in the conversation, which gives you control over how they look, what they show, and when they change. Deployment is described as building the agent once and running it across all channels, with updates flowing everywhere without redeployment or platform-specific versions. The MCP UI integration is the specific integration named in the content for bringing interactive components such as product cards, comparison tables, calendars, and forms directly into the conversation. The takeaway is that Sierra's multimodal agents treat the conversation itself as the interface and let the medium change as the moment demands. Voice handles explanation, visuals handle comparison, and text handles referencing, all within one continuous interaction that customers never have to restart. Built once and deployable everywhere, with components your team owns and updates centrally, the agents aim to make multimodal customer experiences as straightforward to build as they are to use.
The Frigade Assist API adds product expertise to an AI agent you have already built. In one tool call — importing frigade from '@frigade/ai' and running frigade.assist({ query }) — your existing agent can answer product questions and guide users through any workflow, right inside the agent you already built. It is made for product and engineering teams who own an in-app agent and want it to show users where to click instead of replying with a wall of text, and for support and CX teams who need those answers to be accurate and controllable without engineering work. The problem it addresses is simple: most in-app AI agents cannot see the screen. When a user asks 'how do I do this?', the agent answers with a wall of text. Your agent has read your docs, but it has never used your product. That matters because written documentation is accurate exactly once — the day it is written. Docs go stale the day you ship, and an agent that links a help article from two releases ago sends users down paths that no longer exist. Frigade instead gives your agent the same product your user is looking at, so it can walk them through the workflow rather than pointing at a document. At the center of the product is a living model of your product that Frigade builds by using it. Frigade deploys agents that take a seat like any user — you invite Frigade the way you would invite a person, with nothing to document or configure first. Those agents work through your real workflows, clicking the same paths your users click and mapping how your features actually connect. Frigade also takes in your existing knowledge base. Then, because your product changes, it re-learns on every release: you ship, the map updates itself, and your agent is never a version behind. Ship a new feature and it is picked up; move a button and the guidance follows. Answers are grounded in the product rather than the documentation. Every answer comes from how your product behaves right now, so it holds up even when the help center is two releases behind. Your team stays in control of that content: anyone can rate any answer and write the behavior they want instead — no code — and that guidance holds from the next conversation on. Every reply your agent gives through Frigade is logged, and you can see every conversation in the dashboard, in Slack, or over the API. This is deliberately not only work for engineers: support, CS, and CX own the answers, rating replies and stating what they wanted instead, with no ticket to engineering. Beyond answers, Frigade provides guidance: the real steps, rendered inside your own UI. When a user needs to manage SSO, for example, the agent can show a step-by-step card such as 'Step 1 / 3 — Open Security to manage SSO. Follow the highlight.' Insights then show where users get stuck, where the agent helps, and where it hands off. When Frigade cannot help, it knows its limits and hands off cleanly, saying so right away and passing the conversation to your team. Steering lets your team tune the system over time — the more your team puts in, the better it gets. And alongside answering and guiding in the moment, Frigade can proactively surface the right feature to a user right when they would benefit from it, using the same idea as Frigade's Suggestions product to help drive feature adoption and expansion revenue. Underneath the single tool call sits an entire engine that relearns your product, plus a platform for your team to manage with no code. Frigade is a lightweight SDK and two primitives: register it as a tool your agent can call, in a few lines, and your agent can now run a live product tour or return a grounded product answer. Your agent stays in control — it decides when to call Frigade and what to do with the result — and keeps its own reasoning and voice. Frigade adds product expertise to your agent; it never takes over the conversation. Every call returns fast with a clear answer, and when Frigade cannot help it says so immediately so your agent never stalls or burns latency waiting. The four layers are a product model built by using your product and rebuilt every release, grounded answers written from your actual product, guidance rendered inside your own UI, and steering that improves with your team's input. The outcome is an agent that answers about the version that shipped rather than the version someone last documented. Because Frigade relearns automatically, nobody on your team has to retrain the agent or rewrite prompts when you ship. Support and CX can fix a bad answer themselves instead of filing engineering work. Teams also see measurable deflection: one customer reported that Frigade solved over 400 queries a month that would otherwise have gone to support, equivalent to two hires they did not have to make, and said it paid for itself within the first two months. Retell AI, which builds agents for a living, gave Frigade access to its product and reported that it learned the product on its own, allowing the agent to take someone through a workflow without manual documentation. Concrete workflows include answering plan and permission questions — for example, whether the Growth plan includes SSO, where the agent can answer yes, note that it is turned on under Settings and Security, and mention that SAML is Enterprise-only. It guides setup tasks such as adding a webhook, showing the user where to paste an endpoint URL and confirming the test event. It resolves billing questions, walks users through connecting integrations like Slack, and handles access questions. When a request is beyond it — deleting a workspace and all data, for example — it hands the conversation to a human. It also proactively surfaces the right feature at the right time to drive adoption and expansion revenue. Frigade Assist API is built for product and engineering teams that already run an in-app agent, and for the support, CS, and CX teams that own the answers. It is framework-agnostic: it integrates cleanly with the Vercel AI SDK today, and any agent that can call a tool can call Frigade, regardless of how the agent was built or which models it runs. On security, Frigade is SOC 2 Type II certified and fully GDPR compliant, encrypts data in transit with TLS 1.2+ and at rest with AES-256, offers EU data residency, a zero-retention LLM policy, and automatic PII scrubbing, and runs guidance with the user's own permissions. Teams needing full data control can self-host Frigade with their own LLM keys. Pricing starts at $1,000 per month with usage-based scaling, and enterprise plans with custom pricing are available. If you have not built an agent yet, Frigade ships a full in-product assistant that learns your product and guides users in real time, no code required. Frigade Assist API's primary promise is that your agent stops pointing at documentation and starts showing users exactly where to click. By adding one tool call to the agent you already built, you give it a product model that learns by using your product, re-learns on every release, and is tuned by your own team — with grounded answers, in-app guidance, clean handoffs, and full visibility into every conversation.