Category Focus/categories/analytics
Analytics AI Tools
Discover and compare the best analytics AI tools and software. Browse 128+ curated tools with reviews and rankings.
Projects tracked
128
Sort mode
RECENT
Page
1
Discover and compare the best analytics AI tools and software. Browse 128+ curated tools with reviews and rankings.
Projects tracked
128
Sort mode
RECENT
Page
1
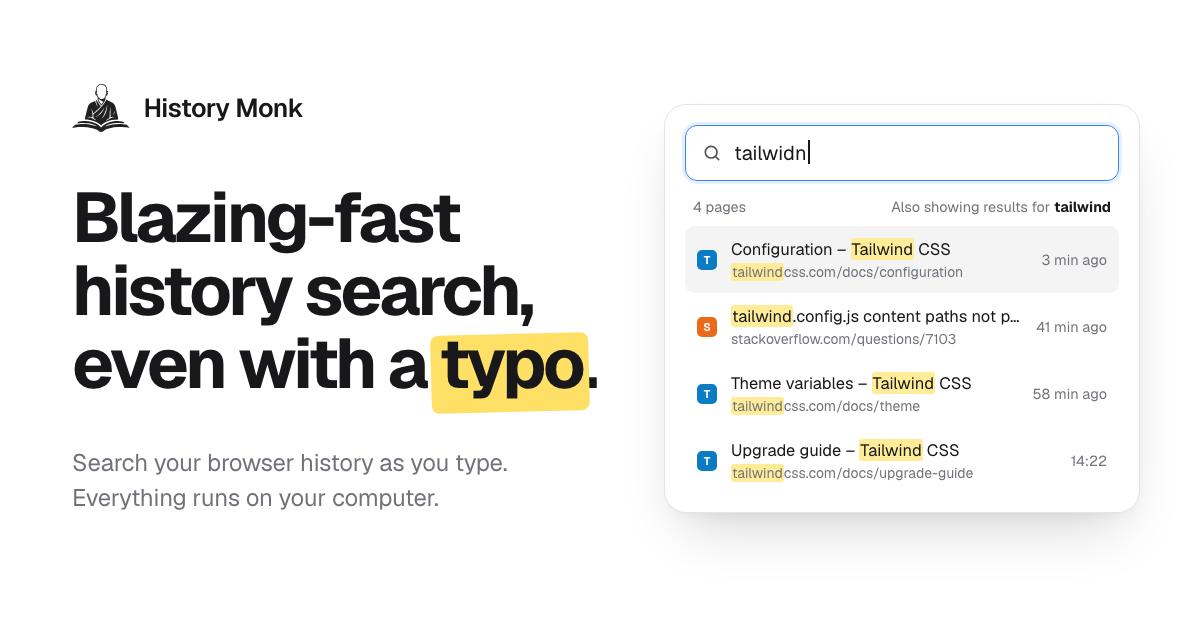
History Monk is a browser extension that replaces your browser's built-in history page with a fully searchable one. Instead of scrolling through days of visits, you type a few letters and the page you want shows up as you type — even with a typo. It works in Chrome, Edge and Opera, where it takes over the built-in history page so the History menu and its shortcut open History Monk, and in Firefox 140 and later, where you open your browsing history from the toolbar button or with Alt+Shift+H. It is made for anyone who spends the day in a browser and needs to find, reopen, export or clear out pages they have visited, and the whole thing runs on your own computer. Browser history pages were designed to record visits, not to help you find them again. They show a long chronological list with a single search box that only matches exact strings, so a half-remembered title or a misspelled word returns nothing useful. At the same time, the history fills up with search result pages, sign-in screens, duplicate URLs and links you clicked once and never needed again. History Monk addresses both sides of that problem: fast, forgiving search across everything you have visited, and a set of cleanup tools that sort the junk into groups you can review and remove. Because everything happens locally, tidying up your history does not mean handing your browsing data to a third party. Search is the centre of the product. History Monk is ready to search 80 milliseconds after it opens, and results update with every letter you press — no Enter key, no waiting for a page to load. It is built to stay fast on large archives, with the page citing 100,000 pages searched with no lag. Typo correction works against the words in your own browsing history, so typing “plannig” still finds the planning doc. When a word is not enough, 11+ power filters let you narrow things down: require two words in any order (“tailwind config”), match an exact phrase in quotes (“release notes”), restrict to one site with site:github.com, exclude one with -site:youtube.com, match the page title with title:invoice or the address with url:/pull/, and combine several of them in a single query. Date and time filters such as after:yesterday, a specific date like 2026-08-01 and before:17:30 limit results to a window, visits:>10 finds pages you opened more than ten times, a regular expression such as /issues\/\d+/ can be mixed with anything above, and sort:new orders results by best match, newest or most visited. A selected: filter can show only the rows you have ticked. Recently closed keeps every tab and window you close, newest first, so the last tab you closed sits on top and can be reopened with one click. The same list is searchable: type a word and only matching closed tabs stay. In Chrome, the Devices view lists the tabs open on your other signed-in computers and phones, grouped by device with the time each tab was last used, and you can search across all of them and open a page on the machine you are using. It uses the Chrome sync account you already have, with no extra account, and the product notes that Firefox does not share other devices' tabs with extensions. A third view, By group, keeps a search together with the pages you opened from it, one card per search — Google, Bing, DuckDuckGo, YouTube and dozens more are recognised with no setup. From a card you can reopen every page in a new tab group or delete the search and its pages in two clicks, while pages you also visited at other times stay. Sites turns cleanup into a bulk operation. You tick the sites you want gone — shift-click to select a range, Ctrl+A to tick every site — and delete every page from them, including older visits that are not visible on screen. You can also right-click any page or link and choose “Delete all history of this site”. Deleting a site always asks first, and sites on your protected list can never be removed. Export takes what you filtered and writes it out: search or filter first, then export just those results or a whole Cleanup group as CSV for Excel and Google Sheets, JSON ready for your own scripts, or an HTML page you can search and sort offline. Every file uses the same five columns — title, URL, site, last visited and visit count — and is created in your browser and saved to Downloads, with nothing uploaded. Cleanup itself sorts your history into 24 groups of likely junk, covering search result pages, duplicate pages that differ only by tracking parameters or a fragment, sign-in and OAuth callback pages, shortened links, links with tracking parameters, pages visited once and never again, untitled or failed pages, social feeds and video, AI chat conversations, meeting and call links, preview and staging sites, cart and checkout pages and more. You see every page in a group before anything is deleted, every delete waits for a second click to confirm, protected sites are never touched, and there are one-click deletes for the last hour, day or week. Timeline lays your browsing history out one day at a time, newest first, with a new session starting after 30 minutes of quiet and the gap showing how long you were away. Analytics shows how you really browse: a weekday-by-hour heatmap of your history, a focus score, streaks, rising and fading sites, and the terms you search for most — and clicking any cell opens those pages. The weekly digest condenses the last seven days into one card with pages, top sites, your busiest hour and late-night share, which you can copy as an image or text. Keyboard users can open History Monk from any tab with Alt+Shift+H, jump to search with /, move with the arrow keys, open with Enter and open in the background with Ctrl+Enter. The interface can be made your own with 28 themes taken from official palettes — Nord, Dracula, Catppuccin, Solarized, Rosé Pine and 23 more — plus 8 languages (English, Español, Français, Deutsch, Português, 日本語, 简体中文 and हिन्दी), a 12- or 24-hour clock, date order, row density and text size. Under the hood, History Monk reads your browsing history through the browser's history API and searches it inside the extension page, so search, Analytics and Cleanup all run locally. There is no account to sign up for and no third-party trackers or analytics. In Chrome and Edge, site icons come from the browser's icon cache, so showing results makes no web requests, and the only network requests the extension makes are to verify a license key and to look up the current price. It has no content scripts, so it never runs inside the pages you visit and only does work while its history page is open. Two settings-like features give you control over what appears: hidden sites stay out of search, Sites, Analytics and Cleanup without the underlying history being touched, while protected sites stay in your browsing history and cannot be deleted from any view. The practical payoff is time. A page you half-remember turns into a few keystrokes instead of a scroll through days of visits, and a typo no longer costs you a second attempt. Closing a tab by mistake becomes one click rather than a hunt. Research that started on a phone can be picked up on a laptop through the Devices view. Instead of manually picking through thousands of entries, you review a cleanup group, confirm, and remove hundreds of junk pages at once — and you can still export exactly the pages you filtered before you clear anything. Because everything stays on your machine, tidying up does not trade privacy for convenience. Typical workflows come straight from the product's own examples. You remember the Lisbon flight you looked at yesterday, type a few letters and it appears. You searched for cheap flights to Lisbon and opened three results; the By group card lets you open those pages again in a new tab group or delete the search and its pages together. You are shopping for a surprise and want a single site's history gone, so you tick it in Sites or right-click and choose to delete all history of that site. You have been researching Tailwind grid gap and want to see where the time went, so you open Timeline or the Analytics heatmap and click a cell to reopen those pages. You want a record of the GitHub pull requests you read this week, so you filter with site:github.com and export CSV, JSON or HTML. Or you simply want the junk gone: you open Cleanup, look through the search result, duplicate and sign-in groups, and clear them out. History Monk is aimed at people who treat the browser as their workspace: developers and designers moving between documentation, repositories and design files, researchers running many searches in a sitting, and anyone who wants a private, searchable record of where they have been. It is available for Chrome, Edge and Opera — where it replaces the built-in history page — and for Firefox 140 and later, and in Chrome it can also show tabs from other devices signed in to the same sync account. It is free for 7 days with no account; when the trial ends it keeps working for 3 opens a day, and a license removes that limit and enables deleting from Cleanup. The extension's only outbound requests are to verify a license key and to look up the current price. History Monk takes the browser's weakest tool — the history page — and rebuilds it around search you can trust, filters that narrow fast, one-click recovery of closed tabs, bulk deletion by site, exports in three formats, and a cleanup system that never deletes without showing you what is going. All of it runs on your computer, which is the point: the wise search once, and History Monk remembers the rest.
Proofsource is an AI intelligence platform that shows whether ChatGPT, Perplexity, Claude and Google AI Overviews name your brand when buyers ask category questions, who those engines name instead, which sources they cite, and what to fix. It is built for the teams that own the shortlist: growth and brand leaders, writers and search teams, agencies running many brands, and founders or small businesses. Its stated purpose is simple and direct — be the brand AI recommends. Rather than measuring blue links or ranking positions on a search results page, Proofsource measures the answer itself: whether your brand appears inside it, where it appears, and which other brands appear alongside it. Buyers now ask AI for a shortlist. An answer engine names three to five brands and moves on. If your brand is not one of them, there is no second page to rank on and no click to measure, so the loss is invisible in conventional reporting. Proofsource says most brands never see this shortlist. Its own measurement illustrates how contested the space is: across 947 citations, four engines and a scan dated 4 October 2026, 43.5% of the sources AI cited for category questions were comparison pages — listicles, alternatives and versus pages. In the same research, 387 different websites were cited across just 80 answers, meaning a brand's own site is one voice among hundreds. A separate finding reported on the site states that only 1 of 4 engines described a brand-new company correctly, with the other three answering from what they already believed. New research highlighted on the homepage notes that 0.8% of AI citations point to the brand's own website. The first feature group is visibility measurement. Proofsource asks each engine the questions your buyers ask and records whether you are named, in what position, and next to whom. It reports mention rate, share of voice and average position per engine, and every number carries a 95% confidence range, described in the product as a 95% Wilson interval, so a bad day never looks like a trend. Answers are kept in full, both as text and as a screenshot, so the evidence behind a number can be revisited. In the Tesla example shown on the site, 53 of 100 answers named Tesla overall, split as 16 of 25 on ChatGPT, 16 of 25 on Google AI Overviews, 11 of 25 on Claude and 10 of 25 on Perplexity. Second, Proofsource shows who AI names instead of you. Every brand the engines name for your questions lands on one leaderboard, ranked by answers per engine, including brands you never thought of as competitors. You can add any of them to tracking with one click, and the platform highlights the questions where each competitor beats you. The Tesla example lists Rivian at 13 answers, SunPower at 13, Ford at 10 and Enphase Energy at 9, alongside Tesla at 53. This matters because a shortlist loss is usually a competitive loss, and the leaderboard makes the set of rivals that answer engines actually consider — not the set you assume — explicit and trackable. Third, Proofsource shows the pages AI trusts in your category. Because answers are built from sources, the platform lists every page the engines cite for your questions, which of those pages mention you, and which are open to a pitch, a listing or a correction. It surfaces cited domains alongside the exact pages, the listicles that leave you out, and the pages on your own site that engines read versus the ones they skip. In the Tesla example, youtube.com was cited in 29 answers, en.wikipedia.org in 24, reddit.com in 20 and tesla.com in 17, with the platform noting whether each source names the brand, partly names it, or is the brand's own site. Fourth, Proofsource catches what AI gets wrong about you. Engines answer from what they already believe, so the platform asks about your brand by name, reads the answers, and flags wrong prices, old features and mixed-up identities, along with the source behind each claim. It reports wrong claims together with the page that caused them, runs profile checks on the sites engines lean on, and checks crawler access — whether GPTBot, ClaudeBot and PerplexityBot can read you at all. One illustrative claim check on the site shows an engine stating that plans start at a price the brand retired last year and that the free tier includes unlimited seats, flagging it as wrong on both counts, pointing to a 2024 review page as the likely source, and suggesting an update to the pricing page plus a request for the reviewer to refresh. Fifth, and central to the product, Proofsource does not stop at a score. It keeps going through a loop it describes as Know, Act, Prove, Repeat: what the engines say, why they say it, what to change, and whether the change worked. It ranks the gaps behind each lost answer by likely lift against effort, names the page or source to change, and drafts the fix from your own content for you to approve. After approval, its agents publish the change, verify that the answers have changed, and learn from every change. The workflow starts from your website and reaches first answers in minutes. You tell Proofsource your site; it reads it, works out your category and your competitors, and drafts the buyer questions worth tracking, with you approving every one. It then asks 25 questions on ChatGPT, Perplexity, Claude and Google AI Overviews, and keeps every answer with its sources and a screenshot. You receive the shortlist and the fixes: where you are named, who is named instead, which sources decided it, and the gaps worth closing first. On paid plans answers are checked every day, because AI answers shift from day to day and a weekly snapshot can miss the day a competitor enters your shortlist. The free trial runs two scans, today and tomorrow. The site links to a published methodology page describing how it measures AI answers. Proofsource is positioned for every team that owns the shortlist. Growth and brand leaders get one number for AI visibility they can defend in a board meeting, with the questions, engines and confidence range behind it. Writers and search teams get the questions they lose, the pages the engines cite instead, and drafts grounded in their own site — the site frames the shift as "search taught you to rank; this shows you how to be quoted." Agencies running many brands get unlimited brands on one account, a weekly report per client, and a roll-up of who is winning and losing across their book. Founders and small businesses use the free trial to see in minutes whether ChatGPT recommends them and then fix the one page that matters most. Engines tracked on every plan are ChatGPT, Perplexity, Claude and Google AI Overviews; the site also displays Google AI Mode, Gemini, Microsoft Copilot, Grok, DeepSeek and Meta AI logos, and the FAQ states that Grok and DeepSeek are available as add-ons on Custom plans. Pricing is free to start: 200 answers, 25 questions on every engine, top AI engines, two days, no card. After that, you choose how many questions each brand tracks, and custom plans start at $64 per brand per month, with the final price discussed on a demo call. Proofsource also publishes side-by-side comparison pages against Profound, Otterly.AI, Peec AI, Semrush, Ahrefs, Scrunch, SE Ranking, Rankscale and AthenaHQ, covering engines covered, sampling cadence, statistics, fixes and price, with sources for every claim about another product. The FAQ clarifies that Proofsource is not ProveSource, the social-proof popup tool, and explains how it differs from SEO rank tracking: rank trackers measure blue links, while answer engines write one answer and name a few brands. The takeaway Proofsource reinforces throughout its site is that the shortlist is being written right now — answer engines are deciding, question by question, which brands get named. By measuring those answers across the major engines, showing who is named instead and which sources decided it, and then drafting, publishing and verifying the fixes, Proofsource turns AI visibility from an invisible loss into a measurable, actionable loop.
Pheebs is an open-source AI telemetry tool created by Eversynced that measures how engineers and teams actually work with AI coding agents. It sits quietly inside Claude Code, Cursor, and Codex via hooks, capturing lightweight interaction signals: the shape of the session, not its contents. The people it is built for are the ones who need an honest proficiency read rather than a guess — engineering leaders, platform teams, and the developers themselves. Its purpose is measurement: turning the ordinary activity of agent sessions into signals about model choice, verification habits, context management, orchestration, and the dollars that model choices are costing. The problem Pheebs addresses is a visibility gap that opens up precisely when a team starts moving fast. AI coding agents arrive, adoption climbs, and nobody can say what changed. Six observations illustrate the questions the tool was built to answer: model spend that buys nothing, such as a bigger model than the work needed; where AI code ships unchallenged; whether AI output gets verified at all; rework hiding inside the speedup, where follow-up prompts are fixing something the AI broke; and whether the enablement investment landed — for example, a review skill used weekly by 78% of engineers while a migration skill never caught on. The final observation frames the stakes: nobody on the team runs tests inside the agent loop, which is a missing harness rather than a skills gap. Distinguishing a structural gap from a coaching gap is the core problem Pheebs exists to solve. Pheebs captures data by hooking into the agents themselves. It works with three coding agents — Claude Code, Cursor, and Codex — and records seventeen event types that run from session_started through to artifact_found. Hooks fire on session starts and ends, prompt submissions, skill and slash-command expansions, sub-agent spawns, tool calls and failures, compaction, and background tasks. Typical recorded fields are deliberately small: a session_started event carries a codebase such as acme/checkout and a model such as opus; a prompt_submitted event carries a character count and, when the prompt intent classifier is enabled, an intent label such as task or debug; a tool_use_completed event carries the tool name and its duration, with recognized commands summarized as a tool_intent such as test_run. Claude Code and Codex additionally export native OpenTelemetry metrics and logs through the Pheebs proxy, while Cursor is covered by hooks alone. The design constraint behind all of this is that Pheebs captures interaction patterns, not content. It never records source code or file contents. It never records file paths or directory structures — a repo is reduced to org/repo from the git remote. It never records prompt text; a prompt becomes a character count. It never records raw command strings, since a command like npm test is read in process and recorded as tool_intent: test_run. It never stores your name or your email: the developer is the id behind your Pheebs token, stamped by the backend, or a truncated hash of your git email when no token is set, and your GitHub handle is never looked up. The only route in the backend contract that receives raw text at all is POST /classify-prompt, which takes one prompt in and returns one label out. The backend contract also includes POST /ingest for one event envelope per request, POST /validate-token to resolve a token to an identity and its consent flags, POST /otel/v1/{signal} as an OTLP passthrough so no observability credential ever ships in the client, and an optional GET /insights for what one developer can see about their own work. On top of those signals sits a documented proficiency model. It assesses six competencies: Models, covering model choice, effort settings, plan mode, and autonomy modes; Artifacts, the reusable configuration that shapes the agent, such as skills, sub-agents, slash commands, and context files; MCP, live connections to external systems like tickets, databases, browsers, and documentation; Evals, verification wired into the agent loop through tests, typecheck, lint, build, and review passes; Context management, deliberate use of the context window including compaction and the save, resume, clear lifecycle; and Orchestration, running more than one agent at a time via sub-agents, parallel work, worktrees, hooks, and plugins. Each practice is classified as Unobserved, Adopted, or Recurring — Recurring meaning it showed up in at least 3 of the last 4 active weeks — and the coverage index summarizes, per engineer, the share of applicable practices at Recurring. Five judgement signals sit alongside the competency model. On the output side, verification coverage measures the share of AI edits followed by a verification action such as a test run, typecheck, lint, build, or a check against a spec; pushback rate measures how often the engineer challenges AI output instead of accepting it; the refinement-to-repair ratio separates follow-up prompts that refine intent from those that repair breakage; and wholesale-accept rate captures sessions with no pushback, no repair, and no verification, weighted by lines changed — described as the composite red flag of polished output with no questions asked. On the input side, model-fit rate measures the share of sessions whose model class matched the size of the work. Pheebs follows three stated principles here: tasks are sized, so every task prompt gets a scope from a one-file change to open-ended design and a session is judged on its hardest prompt; misses count both ways, because an over-provisioned session burns budget silently while an under-powered one shows up as repair prompts; and Pheebs is an audit, not a router — it never intercepts a prompt or switches a model on anyone's behalf, it reads the gap and prices it, and the decision stays yours. The overall pipeline has five steps. A hook fires. Lightweight fields are extracted — event type, durations, counts, models, trigger types — with prompt text reduced to a character count and an optional intent label. Identity and repo are resolved from the Pheebs token or a truncated git email hash, and from org/repo on the git remote. Every event is logged locally in a JSONL log, and with a token set it is also sent to the backend. OpenTelemetry rides along for Claude Code and Codex. Sending requires both settings to be present: pheebs config set base-url and pheebs config set token. Both need to be set or nothing is posted, and unsetting either one stops sending — the local JSONL stays the durable copy either way. Pheebs also states there are four routes to any backend: self-hosted, or managed by Eversynced. Two deployment shapes are described. In the self-hosted model you run the backend and hold the data: telemetry goes from developers' machines to your infrastructure and Eversynced never sees it. That option includes the full client for all three agents under Apache-2.0, a documented contract and a reference backend in the repo, raw JSONL you can query with whatever you already use, and no account, no key, and no requests. In the managed model, the same open-source client points at a backend Eversynced operates, with the proficiency model rendered as reports and dashboards — the AI Enablement Assessment, a 30-day telemetry sprint ending in an executive debrief and a plan for the gaps. The benefits the content states are visibility rather than surveillance: knowing which models are in play, whether AI output gets verified, whether enablement investments landed, and what the model-fit gap costs. The reporting built on top includes a practice adoption funnel, with one bar per competency split by how many engineers have not acted on it, acted on it once, or acted on it week after week; a practice heatmap putting every engineer against every competency, where a cold column means the team is missing the setup and practice for it and a cold row calls for coaching; a per-engineer view showing how much of each competency has become habit; and a signals table showing the five judgement signals per engineer against a team median. The dollar view prices the gap: in the illustrative example, a savings opportunity of $9,960 against $32,400 of list-price spend, described as 31% and an API list-price equivalent estimated upper bound, with models used and work as sized split across Frontier, Large, Medium, and Small classes. Decisions and figures come from complete sessions only, with coverage reported as complete, incomplete, no telemetry, and unpriced. The quickstart is three commands: npm install -g pheebs, pheebs init for interactive setup across all three agents, and pheebs doctor to check the wiring. Eversynced states that every Eversynced engineer is instrumented with Pheebs; it powers the measurement layer of their AI delivery framework, and the reporting built on top of it ships with the AI Enablement Assessment run for client teams. The product is therefore aimed at teams adopting AI coding agents who want evidence about how those agents are actually being used in their codebase. In short, Pheebs turns the day-to-day shape of AI coding sessions — model choices, prompts reduced to counts, tool calls, verification, compaction, and orchestration — into an honest, legible read on proficiency, adoption, and cost, while keeping the code, the prompts, and the identity of the developer out of the dataset.
AUDR (Agent Usage Detail Record) is an open standard for recording who initiated your agent runs and how much each cost, across every system a run passes through. It defines a common JSON schema that any harness, router, or billing system can emit and ingest. The goal is to help businesses make sense of the economics at the run level, giving every team building or monetizing agents a reliable record of what an agent run consumed and who or what it was associated with. It was drafted at Chargebee and is being improved with collaboration across the ecosystem, stewarded by Chargebee under the Apache 2.0 license. The problem AUDR addresses is that a run can be fully observable at every individual layer and still leave you without a single end-to-end record of who ran it and what it cost. A single agent run touches multiple systems: the application knows the customer and the feature, the router knows the tokens and the cost, and the tools know what they executed. Without a shared way to join these, usage data is orphaned from the business context that gives it meaning. The telecom industry solved a similar problem with the Call Detail Record, an open standard carriers converged on so a call's attributes could be captured and exchanged in a common format, independent of any single carrier's systems. AUDR is built on the same principle: a common record for agent runs that any harness, router, or billing system can emit and ingest. AUDR adds three core rules that let reports from different layers come together into one record. The first is a shared run ID, minted by the harness, passed to the router in request metadata, and echoed back, so every system that touches the run carries the same ID. The second is clear authority per field: the harness owns attribution such as customer, environment, and initiator, while the router owns usage such as tokens and provider. Each fact has exactly one source. This ensures that a record can carry raw counts that drive cost—tokens, tool calls, seconds of compute—alongside the business context that says whose cost it is. The record structure includes a run block with run ID and span ID, an attribution block sourced from the harness, a usage block sourced from the router, and an emitter block that identifies the component that produced the record. The third rule is strict merge rules. The sink assembles records sharing a run and span ID, and no component rewrites another's block. Conflicts are rejected, and a correction is a new record, never a mutation. This makes the record durable and reliable, and ensures that retries remain idempotent. The example in the spec shows a run with a run ID minted by the harness, attribution sourced from the harness, usage sourced from the router, and the emitter identified as the router. Because each field has exactly one authoritative source, the merged record is consistent and auditable, and any correction is preserved as a new record rather than silently overwriting history. AUDR provides adapters for runtimes you already use, so you can register an adapter and get a usage record for every model and tool call, including the customer it belongs to. Available adapters include NVIDIA NeMo Relay, LiteLLM, Merge Gateway, Vercel AI SDK, and Mastra. The core SDK builds, validates, and delivers records straight from your own code, with Python and TypeScript packages. Sinks deliver records to destinations you already use: Chargebee and Lago for usage-based billing. Adapters read identifiers, usage, and timings, never prompts or outputs. Every package is Apache 2.0 and published to PyPI or npm. The architecture is runtime → adapter → core client → sink → destination. Support for OpenRouter is in development. You can write records to a local file to start, with no account, hosted backend, or pricing configuration needed. AUDR is designed to sit on top of OpenTelemetry, not compete with it. OTel's GenAI semantic conventions provide the foundation for describing model calls and usage, and AUDR reuses them. An AUDR record can be emitted as an OTel span, and the OTel collector is a first-class sink. What OTel does not define is the set of rules needed when usage becomes a durable record: which attributes are required, how attribution is handled when it's missing, how retries remain idempotent, or how corrections are made. Observability can tolerate a dropped span, but a usage record cannot. AUDR adds those requirements and delivery semantics on top of OTel. It also complements standards like FOCUS, which standardizes billing data received from providers; AUDR standardizes the usage emitted when an agent run happens, before that usage is priced. The benefits are practical. With AUDR, you can answer questions like: How much does this agentic feature cost? What does this customer's agent usage look like, and how much does it cost? What are the unit economics and margins per customer for my agentic features? Which workflows or models are driving our costs? Which power users are driving our costs? Because records are emitted asynchronously and out of band, recording usage adds no synchronous work to inference in the normal request path. The only exception is optional pre-flight budget gating, which makes a single check before a run starts. You can store records locally, send them to a warehouse, feed them into an observability system, or use them for internal cost analysis or future projections. Use cases include usage-based billing, where records are delivered to a Chargebee site's usage-ingest batch endpoint or Lago's batch event endpoint. Teams can also use AUDR for internal cost analysis, to understand unit economics and margins, to identify which workflows or models drive costs, and to track power users. It supports cost governance by providing a common record that any system can emit and ingest. You can write records to a local file to start, with no account, hosted backend, or pricing configuration needed. For observability, the OTel collector acts as a first-class sink, and records can be used for future projections. AUDR is aimed at teams building or monetizing agents, developers, platform engineers, and billing teams. It does not assume what you do with the data after it is emitted; a billing system is just one possible consumer. It carries no prices or rating logic, and the SDK has no concept of plans, invoices, or how a customer should be charged. It records what happened and who it happened for. You can point the records at Chargebee, a competing rating engine, your own, or a warehouse for analytics. The spec is Apache 2.0, stewarded by Chargebee, and the goal is to move cost governance to an independent foundation as adoption grows. Contact is audr@chargebee.com. The three core rules are stable and will not change without a major version, while the field set will continue to grow as providers introduce new things to measure. In summary, AUDR is an open standard that provides a common language for recording agent run usage and cost across every system a run passes through. By combining a shared run ID, clear field ownership, and strict merge rules, it turns orphaned usage data into a durable, end-to-end record that supports cost analysis, usage-based billing, and agent unit economics. It is open, neutral, and community-owned, with packages published under Apache 2.0.
DailyHelm is an agentic AI business reviewer that monitors your analytics, ads, SEO, and store data overnight and then tells you what to fix today, ranked by revenue impact. Its promise is simple: your business, reviewed by AI, every morning. Rather than leaving you to interpret charts or open dashboard after dashboard, DailyHelm produces a daily brief that works as a prioritized punch list of the issues and opportunities worth acting on. It is built for founders, operators, and growth teams who run the whole business themselves — people who wear the marketing hat, the engineering hat, and the finance hat — and who need a clear answer to the question of what to do next. The problem DailyHelm addresses is the gap between data and action. Traditional dashboards show you charts and leave you to interpret them, which means hours of tab-switching and a lingering sense that you are still guessing. Real problems hide in that gap: conversion tracking silently breaks, ad spend keeps optimizing against zero conversion data, a top product disappears from the sitemap, a lead form stops firing, or failed payments quietly churn subscribers. DailyHelm was built to catch those issues and turn them into a ranked, evidence-backed list of things to fix, so days of wasted spend and lost orders do not go unnoticed. The review is produced by six specialists led by Aria. Each agent owns a domain. Iris covers analytics and growth — funnels, pipeline health, and churn signals. Pitch covers ads — spend, keywords, search terms, and CPA. Echo covers SEO — rankings, indexation, and on-page signals. Ada covers code, investigating your repository when business data smells off. Penny covers cost — cloud spend by SKU, cost forecasts, and egress leaks. Sage covers site UX — crawl-driven performance and conversion blockers. Aria correlates their findings, ranks them by expected impact, and writes the morning brief. Together they handle AI for business operations, monitoring ads, SEO, analytics, and code while you sleep. Each finding is delivered with the detail needed to act on it. Every finding cites its evidence and a recommended next step, along with an impact score, a confidence level, and an effort rating. In the product's example, Iris flags a conversion tracking blackout with 96% confidence, showing that GA4 recorded zero conversions while Stripe recorded 47 purchases in the same window, and pointing to the commit that removed the tracking include. The finding carries a recommended action, and you can accept it, snooze it, dismiss it, or chat with Aria to dig deeper into what broke and how to fix it. That structure means the digest does not just surface a symptom — it explains the cause and proposes the fix. Setup is designed to be fast and non-technical. DailyHelm handles the OAuth; you click approve. First you tell the system about your business — what you sell, who buys it, and what success looks like — which anchors every recommendation. Then you connect your platforms one click at a time: GA4, Google Ads, Search Console, Shopify, GitHub, GCP billing, and your site. DailyHelm opens the approval page and you confirm. From there you get a daily AI business review, a prioritized punch list every morning, with the option to chat with Aria any time. The company states average setup time is under five minutes and that findings start arriving within the hour, with first findings reachable within 24 hours. DailyHelm's overall approach is overnight monitoring plus correlation, delivered as a morning brief. It pulls a daily snapshot from each connected platform and stores nothing it does not need. The agents work in parallel across their domains, and Aria cross-references their individual findings to produce one ranked list. Because the system is built to be read-only on every connector, it never writes back to your accounts. OAuth scopes are read-only across GA4, Search Console, Ads, GitHub, and your store, so DailyHelm cannot write, post, or modify anything. Integrations use each platform's own consent screen rather than API keys, and onboarding happens through those approval flows. Users describe the outcome in terms of time saved and money recovered. One founder reported that Aria caught a $340 per day wasted-spend issue on day one, with a Shopping campaign running against 47 zero-conversion search terms for nine days; negatives were added before lunch and the bleed stopped the same morning. Another reported that a Friday deploy broke the GA4 purchase event, leading to $2,200 spent over a weekend with no conversion data to optimize against, and said that kind of thing will not happen again after setting up DailyHelm. A solo founder described replacing 90 minutes every morning across five dashboards with an eight-minute brief and one clear priority. DailyHelm reports early user ratings of 4.9 out of 5 and describes itself as a part-time COO that reads every dashboard so you do not have to, answering questions about your business in plain English. The product documents concrete categories of findings for different business types. For DTC and e-commerce, Pitch surfaces wasted ad spend — specific keywords or search terms burning budget with zero conversions — plus negative-keyword and bid recommendations to cap the bleed. For SaaS and app businesses, Iris and Ada detect a conversion tracking blackout where Stripe charges fire but GA4 shows zero, identifying the deploy that broke the tag and the line of code to restore. For local and service businesses, Echo surfaces a local-search ranking collapse in which "near me" and city-name queries fall out of the local pack. For dropshippers, Echo and Ada catch a top product disappearing from the sitemap or returning a 404 after a deploy. For B2B and lead gen, Iris, Ada, and Sage cross-reference a lead form that silently regressed after a deploy broke validation or the success-event fire. For subscription businesses, Penny flags a failed payment surge, including the dunning gap and recoverable MRR. DailyHelm is aimed at operators who run the whole business: DTC and Shopify founders, dropshippers, B2B SaaS operators, solo founders, agencies, and anyone short on time. It connects to Google Analytics 4, Google Ads, Google Search Console, Shopify, GitHub, Stripe, a Site Crawler, and Meta Ads, with GCP billing referenced during setup. The company offers a seven-day free trial, requires no credit card, and says setup takes about five minutes. On security, it states that all traffic to DailyHelm is TLS 1.2+ encrypted, data is encrypted at rest, and OAuth refresh tokens and webhook secrets are encrypted at the field level. It states that AI never trains on your data, that processing happens through providers contractually prohibited from training on it, and that the service is GDPR and CCPA compliant with rights to access, correct, export, and delete data. One click deletes your account, revoking every connected token and purging findings within 30 days. DailyHelm's value proposition is straightforward: stop opening eight dashboards every morning, get the punch list, pick the top three, and move on with your day — with every recommendation anchored to evidence from your own connected tools. It turns overnight data into a prioritized set of revenue-oriented fixes so founders and growth teams always know what to fix today.
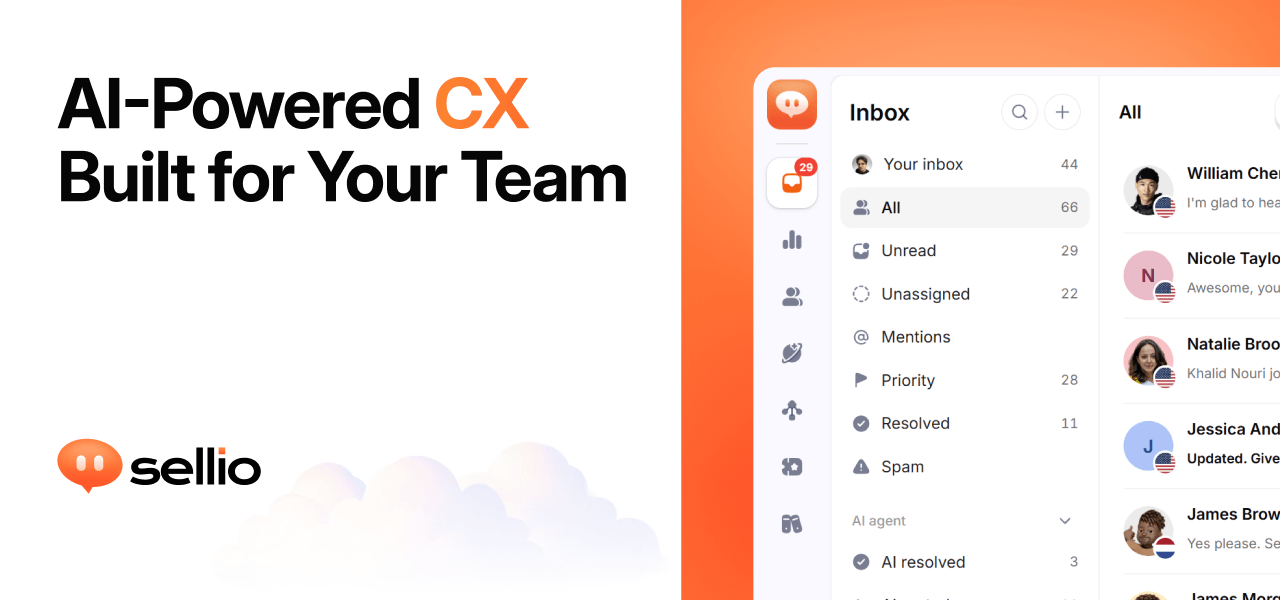
Sellio is an AI customer support platform that puts every customer conversation into one shared inbox. Website chat, WhatsApp, Instagram, Telegram, and email all land in the same place, so a support team works from a single thread rather than switching between tools. On top of the inbox, Sellio adds tickets for work that continues after a chat, an AI agent that can be switched on when a team is ready, and analytics that show how each conversation ended and how it felt. It is aimed at the kinds of teams that answer customers all day: stores and ecommerce businesses, hotels, SaaS companies, local businesses, help desk teams, and agencies. The website describes the product simply as AI customer support in one inbox, with one line added to your site to get started. Support conversations rarely stay in one place. A customer asks something through a website chat widget, follows up on Instagram, sends a complaint by email, and messages on WhatsApp, and each of those threads normally lives in a different tool with its own history. When a conversation is split like that, handoffs lose context, customers repeat themselves, and replies get missed. Sellio frames this as a problem that looks the same in every industry: missed replies look the same whether you run a store, a hotel, or a SaaS product. The shared inbox is the response, one place where every channel lands, every reply and note stays with the thread, and the next step is always clear to whoever picks it up. The core of Sellio is the shared inbox. It is built around clear threads with next steps: every reply, internal note, and handoff stays attached to the same conversation, so anyone on the team can see what was said and what should happen next. Teams work the inbox together rather than forwarding messages around, and because every channel is in one place, an agent does not have to remember which app a customer used. When a conversation turns into work that continues beyond the chat, Sellio lets the team raise a ticket from the thread, assign it, and keep the full history attached, so context survives the move from chat to task. The AI agent is optional and separate from the free chat and inbox. Sellio emphasises that you add it when you decide you are ready: you point the agent at your site, docs, and FAQs so its answers stay grounded in what you actually ship, rather than in whatever a general model happens to know. The agent's first job is the first reply on website chat, which is where many conversations begin. Where the AI cannot finish, it hands off to a person without losing context, so the human sees the same thread the AI saw. The website also highlights staying in control of cost as part of how the agent is positioned, and its FAQ addresses both how the AI learns about your product and whether a person can take over from the AI. Analytics in Sellio are meant to show what to fix next. The product follows every conversation through to how it ended and how it felt, and places automation, resolution, and CX rates beside each other in one funnel, so a team can see performance and customer experience together instead of in separate reports. Topics are drawn from real chats, which surfaces what customers actually ask about rather than what a team assumes they ask about. Sellio also presents response time that improves and CSAT that explains itself as part of the same picture, connecting speed, satisfaction, and outcomes in one view. Getting started is deliberately light. Sellio is installed by adding one line or one script tag to a site, which produces an on-brand chat widget; the site notes that website chat and the shared inbox are free, and that no credit card is required to start. AI is only switched on when a team chooses to switch it on, so a business can run a human support inbox first and layer automation on later. New conversations can be mirrored into Slack, Discord, and Microsoft Teams, so teammates who do not sit in the inbox still see what is happening. The overall approach is staged: inbox and chat first, other channels and AI as the team needs them. The stated benefit is fewer missed replies. Because every channel lands in one inbox and every thread keeps its history, handoffs happen without losing context and customers do not have to repeat themselves. Teams get a clear next step on each conversation, an AI agent that answers from their own documentation, and a funnel that shows how conversations ended and how customers felt. Cost stays controllable: the free plan covers web chat and the shared inbox with no trial clock and no credit card, and paid plans are only needed for more seats, channels, AI agents, and AI credits. Sellio lists the industries and situations it fits. Ecommerce teams can run live chat on Shopify in the same inbox as WhatsApp, Instagram, and email. Hospitality businesses such as hotels can put WhatsApp, Instagram, and website chat in one inbox for front desk and operations. SaaS companies can start with website chat and place every other channel beside it for the whole team. Local businesses can add a live chat bubble to their site along with the channels their neighbourhood already uses. Help desk teams can raise work from a conversation, assign it, and keep the full history, and agencies can run a shared inbox that several people assign, note, and resolve together. On channels and integrations, the website says website chat, WhatsApp, Instagram, Telegram, and email land in one inbox, while Slack, Discord, and Microsoft Teams can mirror new conversations for the team. Logos shown on the page include Stripe, ClickUp, Zoom, Salesforce, Discord, Telegram, Trello, GitLab, WhatsApp, Messenger, Jira, Linear, Shopify, Notion, Microsoft Teams, Zapier, Instagram, Asana, Slack, HubSpot, and GitHub, with the note that six integrations are available now and the rest are on the way. Pricing is straightforward: website chat and the shared inbox are free, while email and messaging channels start on Mini. The Free plan includes two seats, one channel, and one API key, with one AI agent and five AI conversations, and nothing expires; more seats, channels, AI agents, and AI credits come from the paid plans. Sellio's proposition is that support does not have to be scattered or complicated to set up. One inbox holds the conversations, one script tag puts chat on the site, tickets carry work forward, an optional AI agent answers from your own docs and hands off when a person is needed, and analytics show what happened and how it felt. Teams can start on the free plan without a credit card and stay there, adding channels, agents, and AI credits only when the workload grows.
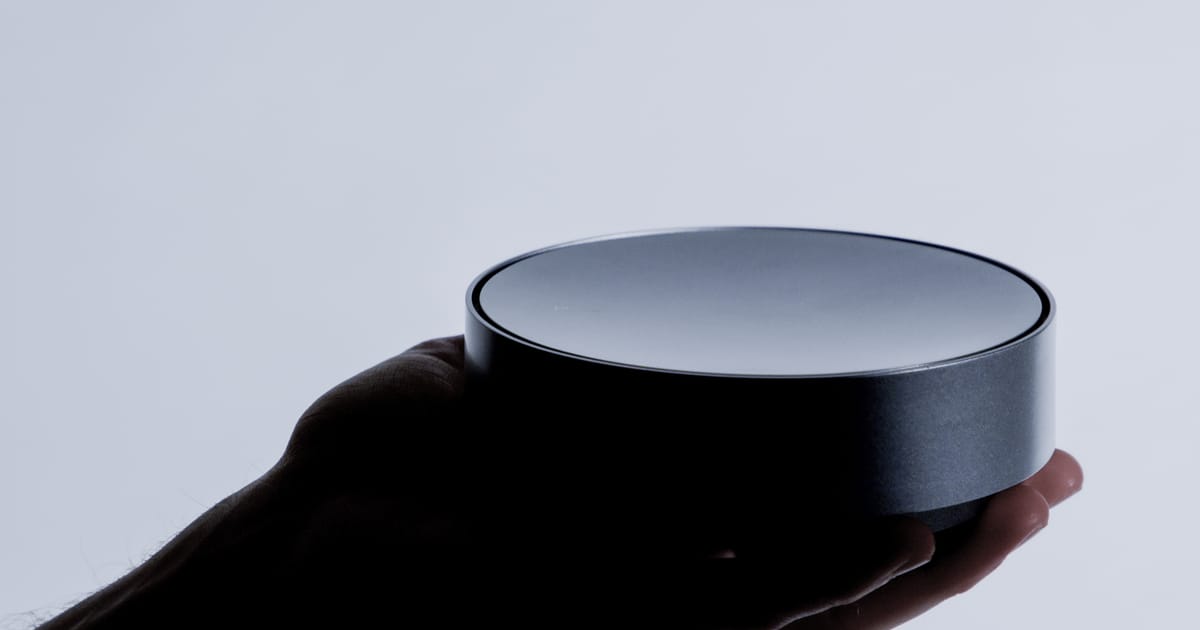
Phare C1® is a smart smoke alarm built by Phare Labs to detect fire and carbon monoxide early and accurately. Rather than simply reacting once smoke reaches a threshold, it pairs research-grade sensors with advanced AI, described by the company as "AI-powered early fire and CO detection, backed by our peace and quiet guarantee." It installs in place of an existing smoke alarm, so the hardware swap is a familiar one even though the behaviour is not. The product is aimed at homeowners who want dependable protection without the constant interruption of nuisance alarms, and it keeps much-loved features from the discontinued Nest Protect — such as early warnings, a night light and in-app alerts — while adding new ones including air quality monitoring and intruder detection. Phare C1 is live in the UK, US pre-orders are open, and pricing starts from $149. The product is framed around three everyday failures of conventional alarms. First, false alarms: Phare states that up to 89% of the time, smoke alarms go off for something other than a fire. Second, missed fires: according to data from the NFPA cited on the site, smoke alarms miss 28% of fatal fires. Third, the beeps: the site asks whether you actually know what the different sounds mean, adding that "we don't speak morse code either." These problems matter because an alarm that cries wolf, misses real emergencies, or communicates in unclear signals is one people learn to ignore, silence or disconnect. Phare C1 is positioned as the answer to all three, with the blunt framing that "it's time to fire your smoke alarm." The core capability is detection. Phare's AI algorithm is designed to detect more fires, earlier, while reducing false alarms, so the device alarms for fires and nothing else. A multi-sensor array spots fire and carbon monoxide early and accurately, and the product description notes that detection algorithms learn and improve to make your home even safer over time. Carbon monoxide is handled with particular precision: Phare measures CO with 0.1 ppm precision and sends exposure alerts before other devices do, so occupants can catch carbon monoxide sooner. Because both fire and CO are covered by the same unit, the alarm replaces a narrow single-purpose sensor with a broader safety net that is meant to stay responsive to genuine events rather than to cooking, steam or dust. Beyond sounding an alarm, Phare C1 is designed to inform. The site promises that Phare tells you what's going on and what you can do about it, removing the mystery beeps that leave people guessing. This early-warning approach means you can respond before it gets loud — reacting before an alarm actually sounds in order to keep the home safe and quiet. Phare C1 and C1 Pro also sense motion in the dark and softly light your path, so you are not fumbling for switches on the way to the bathroom or down a hallway. That pathlight behaviour is one of the features Phare deliberately carried over from the Nest Protect, alongside early warnings and in-app alerts. The C1 line extends into areas a traditional smoke alarm never touches. Phare C1 and C1 Pro monitor air quality, which the company frames as helping protect your health and longevity. Phare C1 Pro adds a radar array that spots intruders and sounds the alarm to drive them away, turning the same ceiling device into a basic home security layer. Maintenance is intentionally minimal: Phare tests itself and never needs batteries, so once it is set up the system handles the rest. Alerts and information are delivered through the companion app — customers who came from Nest Predict describe the devices as producing lots of useful home data, and the app is where CO exposure alerts and other notifications surface. Overall the approach is to analyse a large volume of environmental data continuously rather than to wait for a single threshold to be crossed. Phare states that it analyses thousands of data points every minute to keep you safe, doing all of the worrying so that you don't have to. Combined with detection algorithms that learn and improve, that continuous analysis is what underpins both the earlier detection of real fires and the reduction of false alarms. Installation follows the familiar pattern of an existing alarm — Phare installs in place of your old smoke alarm, though as the site puts it, that's where the similarity ends — and setup is described as plug and play peace of mind, with a companion app for review and alerts. The promised outcome is quieter, better-informed safety. Users get early fire and carbon monoxide warnings rather than a device that only reacts at the last moment, fewer nuisance alarms interrupting cooking and daily life, and clear explanations instead of confusing tone patterns. The pathlight adds practical night-time usefulness, and the air quality monitoring adds a health dimension that a standard alarm does not provide. Customers quoted on the site describe the units as problem free in their basic alarm function, simple to install and use, and producing far more detail than their previous Nest alarms ever did. Phare backs the experience with a Peace & Quiet Guarantee: no false alarms in the first 30 nights, or a full refund. Concrete scenarios follow directly from those capabilities. Households replacing expired mains-powered Nest Protect devices use Phare C1 as a drop-in successor while gaining additional data and features. At night, the pathlight illuminates hallways and rooms when motion is sensed in the dark, and the unit continues to test itself and requires no battery swaps. In the kitchen, the AI-driven detection is intended to distinguish real events from everyday cooking so that dinner does not set off the alarm. Where carbon monoxide is a concern, the 0.1 ppm precision and exposure alerts aim to surface risk earlier than other alarms. Users who want a security element can add Phare C1 Pro's radar-based intruder detection, and anyone interested in indoor environment quality can follow air quality readings alongside their safety status. Phare C1 is sold to homeowners in the UK and the US, with UK availability live and US pre-orders open at the time of publication. Pricing starts from $149, with a promotional code offering $35 off any order of two Phares or more, and orders billed in USD or GBP. The company provides free returns from anywhere in the US and UK, an extended warranty of up to five years with Phare+ Pro, and the Peace & Quiet Guarantee covering the first 30 nights. US orders are noted as shipping once UL certification is complete, estimated for summer 2027, and pre-orders can be cancelled at any time for a full refund. A web login at app.pharelabs.com and published API documentation indicate app and API access alongside the physical device. Phare C1's value proposition is straightforward: a smoke alarm that treats false alarms, missed fires and unclear beeps as problems worth solving. By combining research-grade sensors, AI-based detection, carbon monoxide precision, night-time pathlighting, air quality monitoring and app alerts in one ceiling-mounted unit, it aims to make a home both safer and calmer — the smoke alarm, minus the drama.
CrawlRaven MCP is a remote Model Context Protocol server that plugs into Claude, ChatGPT, Cursor, Claude Code or any OAuth-capable MCP client and lets you run your whole SEO operation from the chat. It exposes the data CrawlRaven already holds — Search Console, linked GA4, ranked opportunities, your target keyword plan and your site timeline — as thirteen typed tools, so your agent reads the actual rows and tells you what to fix, refresh and write next. It is built for anyone who decides what gets written, refreshed or fixed next and would rather ask than export: SEO agencies, in-house SEO and content teams, and founders or solo marketers. Connection is one URL and an OAuth sign-in, and twelve of the thirteen tools are read-only by default. The problem CrawlRaven MCP addresses is the gap between the questions you actually have and the way Search Console answers them. Search Console answers one filtered question at a time: the Performance report caps every table at 1,000 rows, so the long, specific queries that AI search sends fall off the end, and every other angle means another filter and another export. Matching queries to pages, then pages to GA4, is manual work, so it happens once a quarter — by which time the decaying page has already lost its clicks. And when a raw CSV is pasted into a chat, the model cannot tell whether a drop lines up with a Google update or which page should own a query, so it fills the gap with a plausible story. CrawlRaven MCP replaces export, filter, match, repeat with one question and a ranked list. Four of the thirteen tools read Google Search Console. The agent can search queries by text instead of scrolling a table, narrow any report to one exact page in a single call, and pick any window from 1 to 365 days. Overview, series, queries and pages are all exposed, so the model works on the site's real performance data rather than a screenshot of a report. Because the tools return typed rows with the period and any truncation stated, answers can name the tool and the date range they used — and long, specific queries that fall off the end of a 1,000-row Performance report stay reachable. Two more tools join GA4 outcomes, returning sessions, engagement and key events for the linked property so Search Console and linked GA4 answer in the same conversation. One tool ranks what to fix next: opportunities arrive ranked with the evidence attached and an action to take, covering striking distance rankings, CTR gaps and content decay. Another checks your keyword plan, telling the model which page is meant to rank for a query and surfacing target keywords with no page ranking yet or query conflicts where no page owns the term. A further tool explains drops using your timeline, which shows verified Google updates next to your own notes. Finally, three tools write notes you approve — including one that plans a timeline note and waits for your approval in the app. Scopes and defaults shape what a connection can do. Each tool belongs to a scope you approve in the browser, and a connection only sees the tools you granted. Twelve tools only read; the single tool that plans a timeline note waits for your approval in the app. There are no API keys and no manual tokens to paste. This means a connected client cannot quietly change anything in your account, while the agent still has enough context — sites, rankings, analytics outcomes, opportunities, keyword plan and timeline — to give an answer you can act on. The server sits between your CrawlRaven data and the AI client you already use. The client picks a tool, CrawlRaven checks the scope, and typed rows come back with the period and any truncation stated. Setup is one-time and takes about two minutes: connect Search Console in CrawlRaven, and link GA4 as well if you want the analytics tools; paste mcp.crawlraven.com/mcp into your client using the remote HTTP transport; sign in and approve the scopes in a browser; then ask your first question, starting with which sites you have in CrawlRaven. The connector discovers CrawlRaven's auth metadata and prompts you to sign in before sending tool requests, and advanced OAuth metadata URLs are published for clients that inspect OAuth discovery directly. The documented workflow runs end to end without an export or a screenshot: the agent lists pages that lost the most clicks over 90 days, reads the annotations timeline, lines the drop up against a Google update, and separates a site problem from a Google one. Outcomes reported by customers include a daily and Monday content refresh routine where Claude and CrawlRaven update around five to seven pages every Monday, taking a daily SEO routine from two hours to five minutes and generative AI overview impressions from roughly 2,500 to about 9,000 a day. Another customer cut identifying the next set of keywords from three hours to thirty minutes and now describes in plain English what data it needs and gets all of it in seconds. A third moved fixing low-hanging fruit from quarterly to weekly and checks every new post against what the site already ranks for, so pages do not cannibalise each other. Underneath these numbers is a simpler benefit: follow-ups become one message rather than another afternoon of exporting. Concrete workflows where the server is used include weekly content refresh at scale, next-set keyword discovery, pre-publish cannibalisation checks, and decay triage that starts with a question such as which pages lost clicks this month or did traffic fall gradually or overnight. Users also ask which queries containing a term get impressions but no clicks, find pages sitting between position 8 and 20, group every query for a URL by intent, ask which landing pages drove key events over the last 28 days, turn the top five opportunities into a checklist for a writer, and plan a note for a launch that waits for approval. Weekly and monthly reporting can be written from live data, and answers cite their source so they hold up on a client call. Supported clients are Claude and Claude Desktop, Claude Code, ChatGPT, Codex, Cursor and any OAuth-capable MCP client, connected over the remote HTTP transport at https://mcp.crawlraven.com/mcp. Pricing starts with a free preview at $0 for eligible free accounts: seven read-only tools, one pinned website, a fixed 28-day window, up to 50 rows per call and 20 tool calls per account per day. Full access is included with every lifetime license as a one-time payment with no MCP add-on, and unlocks all thirteen tools by the scopes you approve, every website on your plan, custom ranges from 1 to 365 days, and the linked GA4 and timeline tools. In short, CrawlRaven MCP turns Search Console, GA4, your keyword plan, your ranked opportunities and your timeline into tools your AI agent can call, so you ask what to ship this week instead of exporting what shipped last quarter.
Would you pay? is a free web tool where indie makers put their startup in front of real people who swipe right if they'd pay for it and left if they wouldn't. Instead of chasing likes, upvotes or polite encouragement, makers get one blunt signal: the share of strangers who say they would actually pay. The deck currently holds 102 indie startups and has collected 6,499 swipes. Anyone can start swiping without creating an account, and makers can add their own startup to the deck for free. The product is built for indie founders, side-project builders and small teams who want to know whether their pitch earns a yes before they spend more months building. It targets the earliest stage of a product, when the pitch, the idea and the positioning are still cheap to change. Most side projects fail quietly: months of building, then nobody pays. The signals usually available to makers — likes, upvotes, encouraging comments — are cheap to give and say very little about whether anyone would open their wallet. A like costs the giver nothing; a buying decision costs money. Would you pay? was built around that gap. It replaces soft engagement with a harder question asked directly to a stranger who looks at a card for a few seconds: would you pay for this? The site is explicit that the answer is intent rather than a sale, but it is a harder yes than a like, and first impressions decide whether someone clicks through at all. That makes the deck a fast way to see whether a pitch works before more code gets written. The core experience is a swipe deck of indie startup cards. Each card shows a screenshot of the product plus its name and a short pitch line — for example theslot.today, described as "One ad slot a day. The price drops until someone claims it.", or Sweep, "See what you actually cleaned." Visitors open the deck and their first card appears in about a second. No signup and no account are needed to swipe. The rule is stated in three steps: swipe right if you'd pay, left if you wouldn't, and makers see who'd actually pay. Swiping right is not a purchase and nothing is charged; it records first-impression intent. Because the deck is made of indie startups rather than polished enterprise products, cards are judged on their pitch and their screenshot, the same way a visitor to a landing page would judge them. Makers get a results view that goes beyond a single number. They see the share of people who'd pay, whether those people are developers, founders or marketers, and how many clicked through to their site. To keep the signal honest, the percentage only appears after 10 swipes, so one or two early votes cannot skew the figure. The full breakdown is private and shown only to the maker. Because the deck asks a paying question rather than a liking question, the audience breakdown matters: a founder who learns that developers say they'd pay while marketers do not has learned something concrete about who the product is really for. Click-through data adds a second layer, showing how many people were interested enough to leave the deck and visit the site after seeing the card. Adding a startup is free and the card goes into the deck right away. For makers who want answers faster, there is an optional $19 Boost. Boost puts a card at the front of the deck for 24 hours so that nearly every new swiper sees it first. Up to five cards can be boosted at the same time, and those cards share the front position in random order. A guarantee is attached: if a card does not reach 100 swipes within 24 hours, the platform keeps boosting it for free until it does. Crucially, swipes stay honest — people still swipe right only if they'd pay. As the site puts it, Boost gets you answers faster, it does not buy yes votes. Access is deliberately low-friction on both sides. Swipers never register; they open the deck and start judging. Makers log in with a one-time email link and no password, which reduces the account step to a single click from an inbox. Results are private to the maker, but each startup also has a public share page showing the headline percentage once it passes 10 swipes, so the result is ready to post on X. That split between the private full breakdown and the public headline number is the product's overall approach: the maker sees the detail — the share who'd pay, who those people are, and the click-throughs — while the public sees a clean, shareable figure. Underneath it all is one methodology: ask strangers the paying question instead of the liking question, and only report the number once enough opinions have accumulated for it to mean something. The benefit is a decision signal that arrives in hours instead of months. A maker learns whether the pitch earns a yes, which kinds of people say yes, and how many were moved enough to click through to the site. Together those three things tell a founder whether to keep building, change the positioning, or aim at a different audience — all before further engineering time is spent. Because the question is asked in a swipe deck, the audience is not the maker's friends or followers who are inclined to be nice; it is people with no relationship to the maker and nothing to gain from a polite answer. And because the site states plainly that "I'd pay" is intent, not a sale, the number is positioned as evidence about the pitch rather than as revenue. It is a first filter, not a forecast. Concrete workflows follow from that. A maker submits a startup, the card enters the deck immediately, and the results page begins filling in once 10 swipes are reached: the share who'd pay, the breakdown by developers, founders and marketers, and the number of click-throughs to the site. If they need answers quickly, they can pay $19 for a Boost, putting the card at the front of the deck for 24 hours and holding the platform to 100 swipes. Once the headline percentage is live, the maker can post the public share page on X. On the other side, a visitor with no account can open the deck, see a card such as theslot.today or Sweep within about a second, and swipe right or left based on whether they would pay. Would you pay? is aimed at indie makers: the deck is made of indie startups, and the maker-side product serves founders, side-project builders and small teams who want demand evidence before building more. Product Hunt lists it under Marketing, SaaS and Startup Lessons, which matches its use as a pre-launch validation tool rather than a finished product. The people answering the questions are described in the maker results as developers, founders and marketers, since respondents are broken down into those categories. Pricing is straightforward: swiping is free and account-free; adding a startup and seeing results is free, with the card going into the deck right away; and the only paid option mentioned is the $19 Boost, which buys faster responses for 24 hours rather than different answers. In short, Would you pay? turns startup validation into a swipe. Right if you'd pay, left if you wouldn't, and the maker gets a percentage, an audience breakdown and click-throughs instead of likes — free, fast, and based on a harder yes than any social signal can offer.
ZenABM's LinkedIn Ads AI Analyst is a set of AI-powered tools for creating, launching, understanding, optimizing and reporting on LinkedIn Ads. It works in two ways: through Zena, ZenABM's native AI agent, and through the ZenABM MCP server, which lets you build, manage and optimize LinkedIn ads and campaigns directly from Claude, ChatGPT, Perplexity, Gemini or any other AI tool. Zena, the MCP server and the API are all powered by the same company-level ABM data, so campaign building, analysis and reporting draw on LinkedIn Ads, ABM, CRM and revenue data together. The product is aimed at people who run LinkedIn Ads and ABM campaigns and want to do that work inside the AI tools they already use. ZenABM frames the core problem simply: running LinkedIn Ads today often means copy-pasting between your tools and LinkedIn Campaign Manager. Campaigns, ad sets, ads, copy and settings all have to be moved by hand, and reporting tends to arrive as a raw data dump rather than a set of insights and next actions. The result is slow campaign launches, fragmented performance data, and reporting that takes time to turn into decisions. ZenABM's approach is to remove that manual middle layer - generation, management, optimization and reporting happen through AI, with the user reviewing and approving the outcome rather than doing the assembly work. Rather than replacing Campaign Manager, ZenABM hands you a link to review and approve there, so nothing launches until you approve it. Zena, ZenABM's AI agent, builds and manages LinkedIn campaigns directly. You describe the campaign you want and Zena builds it end to end: the campaign, ad sets, targeting and the ads themselves - copy written for you and creatives pulled from your media library. Before committing, you can check the audience size, and you can reuse your saved audiences and lead forms or duplicate what already works. Nothing goes live until you confirm it, which keeps a human in the loop at the approval step while the assembly is automated. Through the MCP server, the same capability is available wherever you already work. You ask Claude, ChatGPT, Perplexity or Gemini for the ads you need; the ZenABM MCP generates them, pushes them into a new ad set with the objective, budget and bidding you asked for, and returns a link to review and approve in Campaign Manager. The site describes the MCP server as offering 15 expert skills built in and 96 read and write tools across your LinkedIn ads and ABM data, extending the agent's reach beyond ad creation into the data around your campaigns. Those expert skills are 15 ready-made ABM skills you run as slash commands, covering tasks such as audits, monthly reports, strategy planning, ad decay checks and sales handoff lists, all graded against ZenABM benchmarks. Underneath them sit the 96 read and write tools spanning LinkedIn Ads, ABM, CRM and revenue data. The point of combining skills with tools is that the AI is not only answering questions about your ads - it has defined, benchmark-aware routines it can execute against your own account data. Reporting is automated rather than assembled by hand. Zena produces weekly, monthly and quarterly reports written for you and sent straight to your inbox, with insights and action items Zena can carry out on your approval, rather than a raw data dump. You can also request a report on the spot: performance is cross-referenced with your pipeline, top and low performers are surfaced, and the result is shareable in seconds. Optimization follows the same pattern. Zena finds and fixes underperforming LinkedIn Ads and campaigns without leaving the chat. It surfaces your lowest and best performing assets, then lets you act on them: pause inefficient ad sets and campaigns, change bids and budgets, and build retargeting audiences from ad engagement and CRM events. Every change waits for your approval, so the AI proposes and the user decides. Alongside execution, ZenABM positions Zena as an advisor. Zena is trained on knowledge from 30+ ABM and LinkedIn ads experts, including Tim Davidson, Ali Yildirim and Max Herzeg, drawn from their own posts. When you ask about list building or ABM strategy, the answer comes back tied to your own data and to benchmarks from other accounts, so the comparison is real rather than generic. The site also advertises expert LinkedIn Ads advice available 24/7. The third surface is the API, which lets you connect your LinkedIn Ads data anywhere and build your own dashboards. It pulls LinkedIn ads engagement, campaign performance and intent stages into whatever system you need. ZenABM notes that whether you use Zena, plug ZenABM into your AI client, or build on the API, it is all powered by the same company-level ABM data - so the agent, the MCP server and the API are three ways into one data foundation rather than three separate products. The benefits follow from that setup. Campaigns that previously required manual rebuilding in Campaign Manager can be generated from a description or a prompt in an AI client. Reporting that previously required pulling data and writing commentary arrives weekly, monthly or quarterly with insights and action items attached. Optimization that previously depended on someone spotting a poor performer moves into the same chat where the performance surfaced, with pause, bid and budget changes queued for approval. And because answers are tied to your own data and benchmarks from other accounts, advice is comparative rather than abstract. Concrete scenarios appear throughout the site. In one illustrated workflow, Claude generates four document ads for a ZenABM workshop in London, with draft ads named for the event, including single-image ads tied to a London Event ad set. Another scenario is ongoing program management: asking Zena to analyze LinkedIn ads performance, find top engaged companies, and surface and pause underperforming ads. Reporting scenarios include a scheduled monthly report cross-referenced with pipeline, and an ad-hoc report requested on the spot. Audits, ad decay checks and sales handoff lists are listed as skill-driven tasks, while retargeting audiences built from ad engagement and CRM events support follow-up campaigns. On targeting and access, ZenABM addresses the product both to people running LinkedIn Ads and to those running ABM programs, including users who want to work inside Claude, ChatGPT, Perplexity, Gemini or Cursor. The site includes FAQ entries asking whether you need to be technical, which AI clients the MCP server works with, whether ZenABM AI can take actions or only read data, whether data is secure, which ZenABM plans include the AI features, and whether you can try ZenABM AI before paying - indicating both a free way to start and tiered plans. Calls to action invite you to start for free or book a demo, and a three-minute walkthrough video is offered. In summary, ZenABM's LinkedIn Ads AI Analyst takes the manual work out of LinkedIn Ads - building campaigns, creating ads, understanding performance, optimizing spend and reporting results - and delivers it through an AI agent, an MCP server for your preferred AI client, and an API, all on the same company-level ABM data.